Dokku
With over 32,000 GitHub stars and a decade of production use since 2013, Dokku is the original self-hosted Heroku alternative — a Docker-powered PaaS that turns any single Ubuntu server into a full application platform with a simple git push. Deploy applications written in Node.js, Python, Ruby, Go, Java, PHP, Scala, and Clojure using Heroku-compatible buildpacks, Cloud Native Buildpacks via pack-cli, standard Dockerfiles, or pre-built Docker images, with automatic language and framework detection handling the rest. Every deployment runs through zero-downtime checks that health-test new containers before routing traffic via the built-in Nginx reverse proxy, which handles virtual host configuration, WebSocket proxying, and HTTP/2 support automatically. The official plugin ecosystem provides managed datastores including PostgreSQL, MySQL, MariaDB, MongoDB, Redis, RabbitMQ, and Elasticsearch, each provisioned with a single CLI command and linked to apps via environment variables. Automated TLS certificates arrive through the Let's Encrypt plugin with auto-renewal, while persistent storage volumes, cron job scheduling, user ACL management, and process scaling round out the platform capabilities. The entire system is CLI-driven — no web dashboard — keeping resource overhead minimal enough to run multiple applications on a $5/month VPS. Dokku also supports Lambda function builds, custom builder plugins, and app.json-based healthcheck configuration for advanced deployment workflows. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Hasura
A PostgreSQL database becomes a production-grade GraphQL API the moment Hasura GraphQL Engine points at it: track tables and relationships - existing schemas included - and full query, mutation, and subscription types appear with where, order_by, limit, offset, and on_conflict arguments, no resolvers or boilerplate written. Its Haskell core compiles GraphQL to efficient SQL, and any query becomes a real-time live query with a single keyword, powering dashboards and collaborative UIs over standard GraphQL subscriptions. Authorization is where Hasura earns its enterprise reputation: role-based access control with row- and column-level permission policies driven by session variables from JWTs, auth webhooks, or headers - each role effectively sees its own GraphQL schema containing only what it may touch, integrating cleanly with Auth0, Firebase, or homegrown auth. Event triggers fire webhooks on inserts, updates, and deletes for asynchronous business logic; Actions extend the schema with custom REST handlers; remote schema stitching merges external GraphQL services into one endpoint; and auto-generated REST endpoints serve clients that skip GraphQL. A browser console handles data modeling and API exploration, the CLI manages migrations and metadata as code, and deployment is a single stateless Docker container beside Postgres.
SigNoz
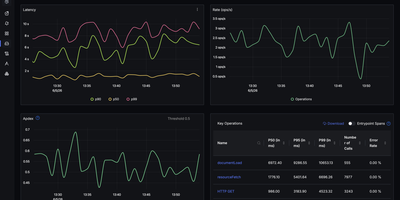
With over 31,000 GitHub stars and native OpenTelemetry support that eliminates vendor lock-in from day one, SigNoz delivers full-stack observability covering metrics, traces, and logs in a single pane of glass without the per-host pricing model of commercial APM platforms. The platform ingests telemetry data through the OpenTelemetry Collector, supporting auto-instrumentation for Java, Python, Node.js, Go, Ruby, PHP, and .NET applications with zero code changes required for basic tracing. ClickHouse serves as the columnar storage backend, providing fast aggregation queries over billions of spans and log lines with configurable retention policies and tiered storage. The distributed tracing view renders flame graphs and Gantt charts showing request flow across microservices with latency breakdowns, error rates, and p99 percentile calculations. Custom dashboards support PromQL and ClickHouse SQL queries with time-series charts, bar graphs, tables, and value widgets. The log management pipeline supports structured and unstructured logs with full-text search, log pipelines for parsing and enrichment, and correlation with traces via trace IDs. Alert rules can be configured on any metric or log query with notification channels including Slack, PagerDuty, OpsGenie, webhooks, and email. The exceptions monitoring module automatically groups and tracks application errors with stack traces, occurrence counts, and first-seen timestamps. Service maps visualize inter-service dependencies with real-time latency and error rate overlays. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed with an enterprise edition available.
Onyx
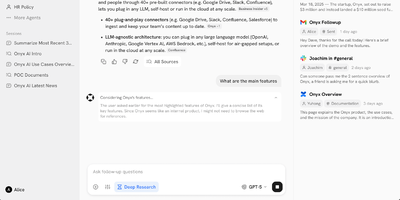
Formerly known as Danswer and now backed by over 31,000 GitHub stars with 253 releases, Onyx delivers a production-ready AI platform that turns any LLM into a context-aware enterprise assistant connected to your organization's actual knowledge. The agentic RAG pipeline combines BM-25 keyword search with prefix-aware embedding models in a hybrid index, then deploys AI agents to retrieve, verify, and synthesize answers with source citations from over 40 connected workplace tools including Google Drive, Confluence, Slack, Notion, Jira, SharePoint, GitHub, and Linear. Custom AI assistants with configurable prompts, backing knowledge sets, and document-level access control enable specialized agents for engineering, sales, support, and research workflows. The platform supports every major LLM provider — Anthropic Claude, OpenAI, Google Gemini, plus self-hosted options via Ollama, LiteLLM, and vLLM for fully air-gapped deployments. Beyond chat, Onyx provides web search with Serper, Google PSE, Brave, and SearXNG integration, an in-house web crawler, code execution, file creation, and multi-step deep research with report generation. Enterprise features include SSO via Google OAuth, OIDC, or SAML with SCIM provisioning, role-based access control, usage analytics by team and agent, query history auditing, PII removal through custom code hooks, and full whitelabeling. Deploy via Docker Compose on any infrastructure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed (Community Edition).
InfluxDB
With over 31,600 GitHub stars and thousands of production deployments, InfluxDB 3 Core is the open-source time series database rebuilt in Rust on the FDAP stack — Apache Flight for high-throughput data transfer, DataFusion for vectorized SQL query execution, Arrow for columnar in-memory representation, and Parquet for compressed columnar storage. The engine delivers sub-10ms query response times on recent data and handles millions of writes per second through line protocol ingestion over HTTP, with unlimited tag cardinality eliminating the high-cardinality limitations that plagued earlier InfluxDB versions. The diskless architecture persists data as compressed Parquet files to S3-compatible object storage, Azure Blob, Google Cloud Storage, or local disk with configurable partitioning strategies, while the write-ahead log and in-memory buffer serve real-time queries against recent data before compaction. Native SQL support through DataFusion includes window functions, CTEs, subqueries, and joins, while InfluxQL maintains backward compatibility with existing InfluxDB 1.x and 2.x applications through the same query API. The embedded Python VM enables processing engine plugins and triggers that execute custom logic on write events, perform cross-database queries, and transform data in real time without external tooling. Flight SQL clients provide high-performance query access from Python, Go, Java, and Rust, and the HTTP API supports writes in line protocol format compatible with Telegraf's 300+ input plugins. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT/Apache 2.0 dual-licensed.
DragonflyDB
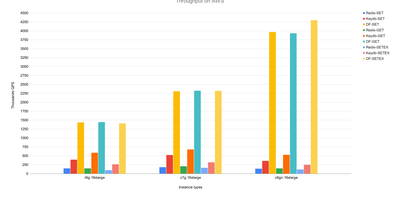
With over 30,000 GitHub stars and benchmarks showing 25x the throughput of single-threaded Redis, DragonflyDB is a modern in-memory data store that eliminates the need for complex Redis Cluster deployments by fully utilizing every CPU core on a single machine. Its shared-nothing, thread-per-core architecture written in C++ supports over 200 Redis commands and 13 Memcached commands, making it a true drop-in replacement that requires zero application code changes. A single DragonflyDB instance scales vertically from 8GB to 768GB of RAM across up to 64 cores, replacing entire Redis Cluster topologies with one process while maintaining full compatibility with Strings, Hashes, Lists, Sets, Sorted Sets, Streams, JSON, and Bloom Filters. The novel dashtable data structure and cache eviction algorithm achieve higher hit rates than LRU and LFU with zero memory overhead per entry. Forkless point-in-time snapshotting eliminates the memory spikes associated with Redis BGSAVE, while automatic backup scheduling via cron syntax supports both local disk and AWS S3 cloud storage. Primary-replica replication follows the Redis replication protocol up to version 6.2, and Prometheus-compatible metrics at the default port enable Grafana monitoring dashboards out of the box. DragonflyDB also exposes an HTTP admin interface on its main TCP port for operational monitoring. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSL 1.1 licensed.
NanoClaw
NanoClaw delivers a radically simple alternative to OpenClaw — a single Node.js process and a handful of files that provide the same core functionality with true container-level security isolation. Agents execute inside Docker containers on Linux or Apple Containers on macOS, where even root access inside the sandbox cannot reach the host filesystem. The platform natively runs Claude Code via Anthropic's official Claude Agent SDK, with drop-in alternatives including OpenAI Codex, OpenRouter via OpenCode, Google, DeepSeek, and local open-weight models via Ollama — configurable per agent group. Multi-channel messaging connects WhatsApp, Telegram, Discord, Slack, Microsoft Teams, iMessage, Matrix, Google Chat, Webex, Linear, GitHub, WeChat, and email via Resend, installed on demand through skill commands. Each agent group receives its own CLAUDE.md memory file, isolated filesystem, container sandbox, and session state — a prompt injection in one group cannot exfiltrate data from another. The OneCLI Agent Vault handles credentials so agents never hold raw API keys, while approval-gated self-modification allows agents to request new packages or MCP servers that administrators must authorize. Scheduled tasks run recurring jobs inside containers with message delivery back to users. The setup script handles dependencies, authentication, and container configuration through Claude Code conversation. Deploy on any Docker-capable Linux server. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Cognee
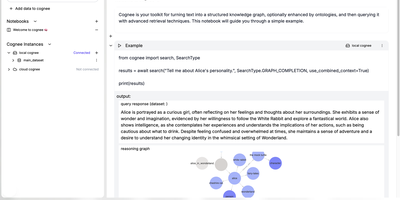
Cognee gives AI agents persistent long-term memory that survives across sessions, replacing the traditional stack of separate graph, vector, and session databases with a unified engine running on a single PostgreSQL instance. The memory-native API exposes four verbs (remember, recall, forget, and improve) enabling agents to persist context, retrieve cited answers, prune outdated knowledge, and self-improve from feedback. Under the hood, Cognee combines pgvector embeddings with a PostgreSQL-native graph store and cognitive-science-grounded ontology generation, delivering hybrid retrieval that fuses semantic similarity, structural graph traversal, and lexical search in a single query. Integrations span Claude Code, Cursor, LangGraph, OpenAI Agents, and any MCP-compatible client through a dedicated MCP server on port 8001, while the Python and TypeScript SDKs provide direct programmatic access. The platform supports swappable backends including Neo4j, FalkorDB, Qdrant, ChromaDB, Weaviate, Milvus, and LanceDB for teams with existing infrastructure. Built-in OpenTelemetry tracing, an experimental dashboard with knowledge graph visualization, multi-tenant user isolation, and audit trails ensure production readiness. Deploy via Docker Compose with optional profiles for PostgreSQL, Neo4j, Redis, and the web frontend. Reached v1.0 in April 2026 with 30,000+ stars. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Gods Eye View
God's Eye View turns your browser into a real-time spatial intelligence command center, rendering thousands of live aircraft, ships, satellites, earthquakes, traffic flows, and public cameras on a photorealistic 3D Earth powered by CesiumJS and Google Photorealistic 3D Tiles. Click any aircraft to see its transponder telemetry from OpenSky and adsb.lol, including route history, altitude, speed, and callsign; track live vessel positions worldwide through AIS beacon data from AISStream; or follow roughly 840 satellites color-coded by class using orbital elements from CelesTrak. A hands-free voice agent powered by the OpenAI Realtime API lets you ask the planet questions in natural language, and the globe annotates your answer directly in 3D space. Toggle FLIR mode for a thermal camera aesthetic, layer in NASA FIRMS wildfire data, switch between Google 3D, Bing aerial, and OpenStreetMap base layers, or tune into a geolocated world radio dial. Public CCTV cameras are projected into 3D city geometry with viewshed cones and direct-manipulation calibration. The cockpit mode provides a pilot-style briefing surface with mission-specific overlays. Entity inspection panels show detailed metadata for every tracked object, and shareable links let you send any scene configuration to a colleague. Ten of the thirteen live data layers work with zero API keys, while the required Google Maps key offers 1,000 free 3D tile sessions per month. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
HashiCorp Consul
With nearly 30,000 GitHub stars and deployment across organizations including Criteo, Pandora, and Barclays, HashiCorp Consul is the industry-standard platform for service discovery, service mesh, and distributed configuration across dynamic multi-cloud and multi-datacenter infrastructure. Services register themselves and become discoverable via a built-in DNS interface on port 8600 or an HTTP API on port 8500, with health checks ensuring only healthy instances receive traffic through automatic catalog deregistration and service-level circuit breaking. The service mesh capabilities use Envoy sidecar proxies with Transparent Proxy mode to establish automatic mTLS encryption for all service-to-service communication, while identity-based intentions define fine-grained authorization rules controlling which services can communicate. The integrated API Gateway manages north-south traffic into the mesh with configurable routing rules, TLS termination, and header-based matching policies. Consul's distributed key-value store provides hierarchical configuration storage accessible via CLI, HTTP API, and the built-in web UI, with blocking queries enabling watch-based configuration updates without polling. Multi-datacenter federation connects Consul clusters across regions through WAN gossip and RPC forwarding, enabling cross-datacenter service discovery and failover with configurable prepared queries. The Raft consensus protocol provides strong consistency for the service catalog and KV store, with anti-entropy mechanisms ensuring agent state converges with the server catalog. Consul integrates natively with Kubernetes via Helm charts with automatic sidecar injection, Nomad for workload orchestration, Vault for secrets management, and Terraform for infrastructure provisioning. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BUSL 1.1 licensed.
PicoClaw
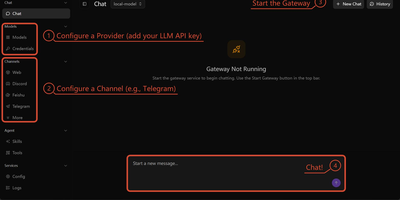
An 8MB Go binary that boots in under one second, uses less than 10MB of RAM, yet delivers full AI agent capabilities across 16+ chat platforms simultaneously. PicoClaw connects to Telegram, Discord, Matrix, IRC, Slack, WeCom, DingTalk, WeChat, LINE, and QQ while supporting LLM providers spanning OpenAI, Anthropic, Gemini, DeepSeek, AWS Bedrock, Azure, and local models via Ollama. Native Model Context Protocol support enables standardized tool integration, and the built-in smart routing engine directs simple queries to lightweight models to reduce API costs while sending complex tasks to capable models. Tool capabilities include secure shell execution, filesystem access, web search, cron scheduling for recurring tasks, and sub-agent spawning with status tracking. Gateway mode transforms PicoClaw into a full AI backend with REST API endpoints accessible from any client. The Skills system loads hierarchical behavior definitions from SKILL.md files, enabling customizable agent personalities and workflows. Compiles for x86_64, ARM64, ARMv7, RISC-V, MIPS, and LoongArch, making it deployable on hardware as cheap as a $10 Sipeed LicheeRV Nano. Achieved nearly 30,000 stars within six months of its February 2026 release. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Jitsi Meet
Backed by nearly 30,000 GitHub stars and powering millions of meetings through meet.jit.si, Jitsi Meet is the open-source video conferencing platform that runs entirely in the browser with no plugins or downloads required. The WebRTC-based architecture delivers HD audio and video through the Jitsi Videobridge selective forwarding unit, while Prosody handles XMPP signaling and Jicofo manages conference focus and orechestration. End-to-end encryption uses AES-GCM 128-bit keys exchanged via the Olm protocol, protecting audio, video, and screen sharing through the Insertable Streams API in Chromium-based browsers. Moderators can split participants into breakout rooms with individual password protection, enable lobby waiting rooms for admission control, set meeting passwords, and track speaker statistics with per-participant talk time metrics. Virtual backgrounds leverage TensorFlow.js body segmentation with WebGPU and WebGL acceleration, automatically adapting quality through device tier detection. Server-side recording and YouTube live streaming run through Jibri, while Jigasi provides a SIP gateway for PSTN dial-in and speech-to-text transcription. The platform includes in-meeting chat with private conversations, polls, raise-hand functionality, emoji reactions, and tile and speaker view layouts. Mobile applications for iOS and Android complement the web client, and both web and native SDKs enable embedding video conferences into custom applications. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
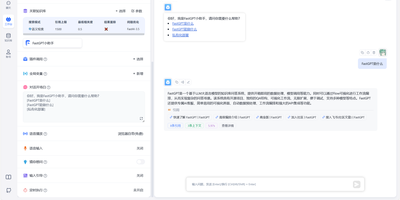
FastGPT
FastGPT lets you build production AI agents and knowledge base chatbots through a visual drag-and-drop workflow editor, connecting any LLM provider to your documents with retrieval-augmented generation that cites sources and reduces hallucination. The workflow canvas chains LLM calls, conditional branching, HTTP requests, code sandbox execution, and plugin nodes into complex conversation flows and agent skill pipelines without writing backend code. The knowledge base engine ingests documents in ten formats (TXT, Markdown, HTML, PDF, DOCX, PPTX, CSV, XLSX, URL scraping, and CSV batch import) then applies automatic chunking, hybrid vector retrieval with semantic reranking, and QA-pair splitting to deliver accurate, citation-backed answers. FastGPT connects to virtually any LLM provider through its AI Proxy aggregation layer: OpenAI GPT-4o, Anthropic Claude, Google Gemini, DeepSeek, Qwen, ERNIE Bot, and models hosted via Ollama all work through a unified OpenAI-compatible API. Bidirectional MCP support enables agents to call external tools and expose their own capabilities to other systems. Completed applications can be shared via login-free links, embedded as iframe widgets, or integrated with WeCom, Lark, DingTalk, and WeChat Official Accounts through the published REST API. Application operation logs, conversation annotation, and per-model usage analytics provide full lifecycle governance for compliance-sensitive deployments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. FastGPT Open Source License (Apache 2.0 based) licensed.
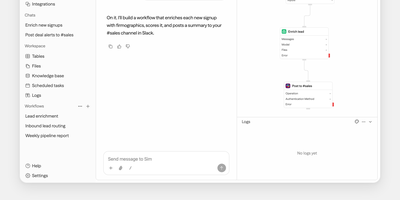
Sim Studio
Sim Studio lets teams build, deploy, and monitor AI agent workflows by dragging blocks onto a visual canvas and wiring them into executable pipelines, backed by over 1,000 integrations. The React Flow editor represents each step as a node: LLM calls, tool invocations, conditional branches, and data transformations form directed acyclic graphs that run as complete agent pipelines. Every major LLM provider works natively, including OpenAI, Anthropic, Google Gemini, Groq, and Cerebras, plus local models through Ollama and vLLM. Integrations span Gmail, Slack, Microsoft Teams, Telegram, WhatsApp, Notion, Google Workspace, Airtable, GitHub, Jira, Linear, Perplexity, Firecrawl, PostgreSQL, Supabase, Pinecone, and Qdrant. Built-in tables provide a database layer, a file store offers shared team storage, and knowledge bases powered by PostgreSQL with pgvector enable retrieval-augmented generation. Finished workflows deploy as REST API endpoints, scheduled jobs, or Slack bots, with block-by-block execution traces for full observability. Real-time collaborative editing via Socket.io supports simultaneous multi-user construction. Alternatively, describe agent behavior in natural language and Sim assembles the workflow automatically. Built on Next.js App Router, Bun runtime, Drizzle ORM, and Tailwind CSS. 29,400+ GitHub stars and 100,000+ builders. Apache-2.0 licensed.
GPT Researcher
A question goes in; a cited, long-form report comes out - GPT Researcher is an open-source autonomous research agent. A planner agent decomposes the query into sub-questions, execution agents crawl 20+ web sources in parallel with JavaScript-enabled scraping, and a publisher aggregates findings into a 2,000+ word report with inline citations, exportable to PDF, Word, and Markdown. The Deep Research mode extends this recursively: each result yields follow-up questions that are explored to configurable breadth and depth in a tree pattern, while accumulated learnings, citations, and visited URLs are shared across branches. It also researches local documents (PDF, CSV, Word) alongside the web. LLM and search providers are pluggable, including OpenAI, Anthropic, Google, DeepSeek, and Ollama for models, and Tavily, Google, Bing, DuckDuckGo, and SearXNG for retrieval. It ships as a Python package, a FastAPI server with web frontend, a Docker image, and an MCP server for use inside Claude or Cursor. MIT-licensed.
Harbor
The first container registry to reach CNCF graduated status with over 29,000 GitHub stars since VMware open-sourced it in 2016, Harbor transforms the basic Docker Distribution into a hardened enterprise registry with vulnerability scanning, supply chain signing, multi-datacenter replication, and project-level access control out of the box. Trivy scans every pushed image against the NVD, GitHub Advisory Database, and distribution-specific vulnerability feeds, with scan-on-push policies that block deployment of images exceeding configurable severity thresholds. Artifact signing through Cosign keyless signatures and Notation enforces content trust policies ensuring only cryptographically verified images reach production clusters. Policy-based replication synchronizes images and Helm charts between Harbor instances across multiple datacenters using repository, tag, and label filters with automatic retry and bandwidth throttling — enabling hybrid-cloud and disaster-recovery topologies. The RBAC model isolates projects with per-project quotas, robot accounts for CI/CD automation, webhook notifications, and audit logging that tracks every pull, push, delete, and configuration change. LDAP, Active Directory, and OIDC authentication integrate with existing identity providers, while the proxy cache transparently caches images from Docker Hub, Quay, and other upstream registries to reduce pull latency and rate-limit exposure. The RESTful API with embedded Swagger UI, tag retention policies, garbage collection scheduling, and immutable artifact rules complete the lifecycle management. Deploy via Docker Compose or Helm Chart on Kubernetes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
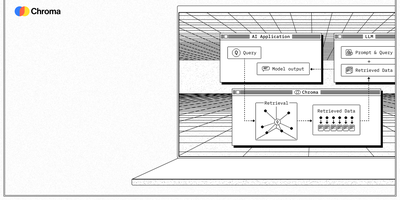
Chroma
With over 29,000 GitHub stars and deep integrations into LangChain, LlamaIndex, and CrewAI, Chroma has become the default vector database for developers building retrieval-augmented generation pipelines and AI agent memory systems. Its core API consists of just four functions — create, add, query, and delete — making it the fastest path from zero to semantic search, while the underlying Rust engine handles tokenization, embedding, HNSW indexing, and similarity scoring automatically. Chroma supports dense vector search via HNSW with configurable distance metrics including L2, cosine similarity, and inner product, sparse vector search using SPLADE, full-text BM25 keyword search, and regex matching, all combinable in hybrid queries through a single unified interface. Metadata filtering at query time uses MongoDB-style operators including $eq, $ne, $gt, $lt, $in, and logical combinators $and and $or, enabling precise result scoping without post-processing. The multimodal pipeline powered by OpenCLIP embeds text and images into a shared vector space, allowing cross-modal retrieval where text queries return relevant images and vice versa. Deployment options range from embedded mode via PersistentClient for notebooks and prototypes, to client-server mode with Docker for production, to Chroma Cloud for serverless scalability. Official Python and JavaScript SDKs provide identical APIs, and embedding function integrations support OpenAI, Cohere, Hugging Face, Google, Ollama, and custom models. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Infisical
API keys hardcoded in repos, database passwords pasted into CI variables, .env files emailed between developers - Infisical, the open-source platform for secrets, certificates, and privileged access management, is the answer to all three. Secrets live in versioned stores scoped by project, environment, and path, with fine-grained identity-aware access control and full audit logging on every read and change. Delivery covers every consumption pattern: CLI injection into local dev, SDKs for Go, Node.js, and Python, an HTTP API, agents, a Kubernetes Operator, and secret syncs that push to GitHub, GitLab, AWS Secrets Manager, and Vercel. Automatic rotation replaces credentials for PostgreSQL, MySQL, MSSQL, LDAP, AWS IAM, and Azure on a rolling schedule - new credentials issue while old ones stay temporarily valid, so nothing breaks mid-rotation. Dynamic secrets go further, generating ephemeral, time-bound database credentials on demand, and SSH access replaces static keys with short-lived CA-signed certificates that expire automatically. Secrets scanning catches hardcoded credentials in code and pipelines, certificate management automates X.509 issuance and renewal, and a built-in KMS handles encrypt/decrypt with central key control. Self-hosting keeps the keys to everything else on your own infrastructure.