linkding
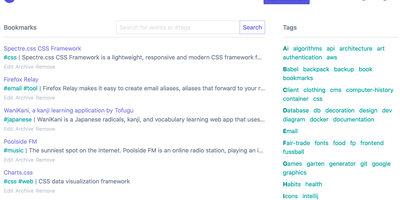
For people who found del.icio.us perfect and everything since bloated, linkding is the bookmark manager - a Django application whose entire design goal is saving and finding links with zero friction. Paste a URL and it fetches the title, description, favicon, and preview image automatically; organize with tags, search full-text across everything, mark bookmarks unread for read-it-later, attach Markdown notes, and bulk-edit whole selections at once. Its answer to link rot is archiving: bookmarked pages can be snapshotted automatically, either submitted to the Internet Archive or saved as local HTML files, and a documented SingleFile browser-extension integration uploads full self-contained page captures straight to your instance. Official Firefox and Chrome extensions (plus a bookmarklet) make saving a one-click habit, the UI installs as a Progressive Web App on mobile, and multi-user support with bookmark sharing - to users or logged-out guests - covers families and teams, with SSO via OIDC when needed. The REST API (create, search, filter by tag) has spawned a genuine ecosystem of community mobile apps and libraries. Operationally it is famously boring in the best way: one small container, SQLite by default, automated migrations, and a zero-breaking-changes policy. Import and export use standard Netscape HTML. MIT-licensed.
Shiori
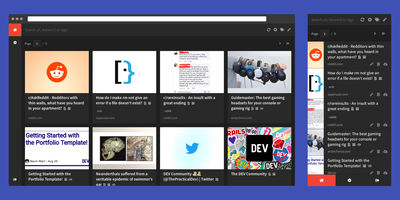
Most web links eventually break - the sobering statistic Shiori, a bookmark manager with archiving by default, is built on. Its answer is archiving by default - where possible, every bookmark you save gets a clean, readable offline copy parsed from the page, ads and navigation stripped, so the article survives even after the original URL dies. Conceived as a simple Pocket clone and written in Go, the entire server is a single binary using roughly 25-30 MB of RAM with SQLite out of the box (Postgres and MySQL supported) - genuinely the lightest archiving bookmark manager you can run. Saving is one click through the Firefox and Chrome extensions, and finding things again is where Shiori quietly outperforms its size: full-text search covers the archived page content, not just titles and tags, so you can find that article by a phrase you remember from paragraph six. Reader mode presents the cleaned text; archive mode shows the preserved page. It's dual-interface by design - a pretty web UI (installable as a PWA on mobile) and a complete CLI for terminal devotees - plus a REST API for scripting. Pocket imports work natively, and Netscape HTML handles browser imports and exports. Multi-user support included. MIT-licensed.
Siftly
Siftly transforms your Twitter/X bookmarks from a chaotic pile of saved tweets into a searchable, AI-categorized knowledge base with an interactive visual mindmap. With over 2,700 GitHub stars since March 2026, the platform runs a four-stage enrichment pipeline on each bookmark: entity extraction mines hashtags, URLs, @mentions, and 100+ known tool domains without API calls; vision analysis generates 30-40 visual tags per image using the Anthropic SDK; semantic tagging produces 25-35 searchable descriptors; and categorization assigns one to three categories with confidence scores. Search combines SQLite FTS5 full-text indexing with Claude-based semantic reranking, narrowing candidates through keyword matching, category-intent detection, and deduplication before sending a bounded set for LLM relevance scoring, letting you find bookmarks by meaning rather than exact keywords. The interactive mindmap built on @xyflow/react renders your entire collection as a force-directed graph organized by category with expandable nodes, color-coded legends, and direct links to original tweets. Import bookmarks through a built-in bookmarklet or console script without browser extensions, then browse in grid or list view with filters for category, media type, and date range. Export as CSV, JSON, or category-grouped ZIP archives. Prisma 7 manages the local SQLite database with FTS5 built in, requiring zero external database setup. A bundled CLI provides JSON-output commands for stats, search, and category management. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Hoarder
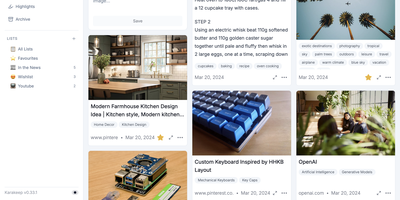
Hoarder (now Karakeep) is a bookmark manager that actually fights link rot: every page you save gets archived at capture time using Monolith, so the content survives even when the original URL dies. Beyond archival, an AI layer powered by OpenAI or local Ollama models auto-tags everything by analyzing page content. Prefer full privacy? Ollama keeps all inference on your server with zero external API calls. Full-text search through Meilisearch indexes the actual scraped content of every bookmark, not just titles and tags, so you find articles by what they say rather than labels you half-remember. Save links with automatic metadata extraction, plain text notes, uploaded images, and PDF documents, all organized into shareable lists with collaborative access. Browser extensions for Chrome and Firefox make saving a one-click operation from any page. Migrating is painless with importers for Chrome, Pocket, Linkwarden, Omnivore, and Tab Session Manager. LLM summarization condenses saved pages into brief overviews for quick scanning. The AI layer is entirely optional: Hoarder works perfectly as a manual bookmark manager, with intelligence adding convenience rather than imposing a requirement. SSO integration and responsive dark mode round out the package.
Wallabag
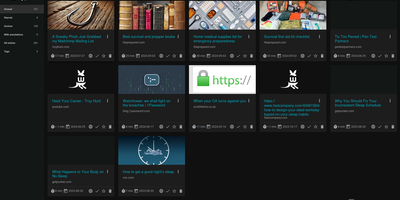
With 12,800+ GitHub stars and over a decade of active development since 2013, wallabag is the most established open-source read-it-later application — built for readers who want complete ownership of their article archive without depending on services that shut down (RIP Pocket). The Symfony-based PHP application extracts clean article content using Graby and php-readability, stripping advertisements, pop-ups, and tracking scripts to deliver a distraction-free reading experience optimized for both desktop and mobile screens. Save articles via Chrome, Firefox, or Safari browser extensions, Android and iOS native apps, REST API, or the built-in bookmarklet — all syncing to your self-hosted instance. Organize your library with tags, automated tagging rules that classify articles by content patterns, starred favorites, and archived collections. The annotation system enables highlighting extracts and attaching notes directly within articles for research and reference workflows. Import your existing reading lists from Pocket, Omnivore, Instapaper, Pinboard, Readability, and browser bookmarks. Export articles in PDF, ePUB, MOBI, JSON, CSV, TXT, or HTML for offline reading on Kindle, Kobo, and other e-readers. Full-text search with filters by reading time, domain, language, and creation date makes retrieval instant across thousands of saved articles. RSS feed output integrates with feed readers and automation services. Docker deployment with SQLite, MySQL, or PostgreSQL persistence backends takes under five minutes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
TrailBase
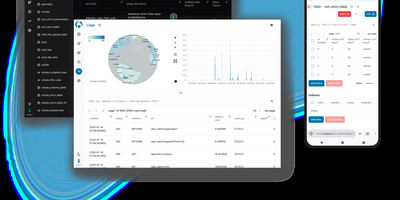
With 5,400+ GitHub stars and sub-millisecond response times that eliminate the need for dedicated caches entirely, TrailBase consolidates your database, API server, auth service, realtime subscriptions, and admin interface into a single Rust binary weighing under 40MB. The platform generates type-safe CRUD APIs automatically from your SQLite schema with configurable access control rules using SQL expressions, while realtime subscriptions push data changes to connected clients via Server-Sent Events. The embedded Wasmtime runtime executes custom server-side logic as WebAssembly components compiled from Rust, JavaScript, Python, or any language targeting WASI, enabling complex business logic without external services. First-class geospatial support through the in-house LiteGIS GEOS extension provides GeoJSON integration, spatial indexing via R-Trees, and query operators including @within, @intersects, and @contains for location-based applications. Client SDKs span JavaScript/TypeScript, Dart/Flutter, Rust, C#/.NET, Swift, Kotlin, Go, and Python — covering mobile, web, desktop, and IoT platforms. The admin dashboard offers visual schema editing, a data browser, Record API configuration, OAuth provider setup, user management, SQL query editor, ERD visualization, and server logs. Experimental PostgreSQL support (v0.28+) allows connecting to existing Postgres instances via connection string. Deploy via a single binary, Docker container, or the one-line install script across Linux, macOS, and Windows. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. OSL-3.0 licensed.
PodFetch
Podcast enthusiasts and homelab archivers automate digital episode preservation and stream personal audio feeds using PodFetch, an open-source self-hosted podcast manager that combines scheduled RSS downloads, Podcasting 2.0 transcript indexing, and browser playback into a modern listening platform. Listeners can subscribe to international podcast channels through direct feed URLs, Apple Podcasts directory searches, or bulk OPML subscription imports, configuring background polling timers to download new releases automatically upon publication. The integrated audio player supports variable speed playback, episode bookmarks, listening histories, and fullscreen visualization modes directly inside responsive desktop and mobile browser sessions. Advanced search capabilities leverage Podcasting 2.0 synchronized transcripts and automated speech-to-text generation via OpenAI-compatible Whisper APIs, allowing collectors to run full-text keyword searches across every spoken phrase in their audio archive. Built-in GPodder API synchronization maintains subscription lists and playback positions across popular smartphone apps like AntennaPod and native companion clients without relying on commercial cloud accounts. Server operators can assign multi-user accounts with private favorites lists, export customized RSS aggregation streams, and route storage paths between fast solid-state drives and large secondary mechanical hard disks. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
MinusPod
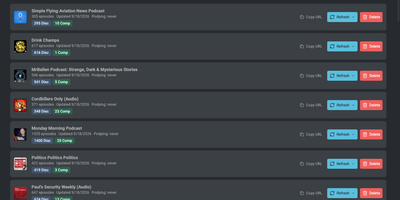
Eliminating repetitive sponsor reads and dynamic mid-roll commercials before an episode even reaches your headphones, MinusPod operates as a self-hosted podcast ad-removal server and RSS feed manager. You subscribe to shows inside the web dashboard using PodcastIndex search or OPML import, and the server generates clean replacement RSS feeds compatible with Pocket Casts, Overcast, Apple Podcasts, and Audiobookshelf. When a new episode drops via scheduled polling or instant Podping notifications, the pipeline transcribes the audio locally with faster-whisper or Parakeet, or routes it through a remote transcription API. Your choice of LLM provider, including Ollama, Anthropic Claude, OpenRouter, or any OpenAI-compatible endpoint, scans overlapping transcript windows to pinpoint sponsor reads, cross-promotions, and intros. Programmatic audio analysis reinforces AI detection by measuring EBU R128 loudness jumps, Chromaprint acoustic fingerprints, show jingles, and dynamically inserted ad transitions before FFmpeg splices the audio or marks segments as skippable Podcasting 2.0 chapters. A browser-based Ad Editor lets you audition pre-cut and post-cut audio, nudge start and end timestamps, and confirm detections that train global, network, and show-specific sponsor patterns. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Karakeep
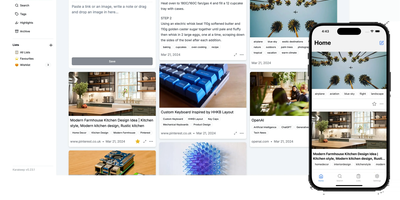
Previously known as Hoarder and now holding 28,000+ GitHub stars, Karakeep is the most popular open-source bookmark-everything application — combining AI-powered automatic tagging with full-text search, page archival, and cross-platform access for digital content hoarders who refuse to let valuable links disappear. The Next.js frontend with tRPC communication delivers a responsive interface for saving links, notes, images, and PDFs, while Puppeteer crawls bookmarked pages to fetch titles, descriptions, and images automatically. LLM-based auto-tagging supports OpenAI, Anthropic, or local models via Ollama for privacy-first deployments that never send data to external services. Meilisearch powers full-text and semantic search across all stored content including OCR-extracted text from images. A rule-based automation engine triggers custom actions based on bookmark properties — automatically sorting, tagging, or archiving content matching defined conditions. Full page archival via Monolith preserves complete page snapshots against link rot, while yt-dlp integration archives videos from YouTube and other platforms. RSS feed ingestion automatically captures new articles from subscribed sources. Collaborative lists enable teams to build shared bookmark collections, with per-list permissions and real-time sync. Native iOS and Android apps, Chrome and Firefox extensions, and browser bookmark sync via Floccus ensure capture from any device. Importers migrate data from Chrome, Pocket, Linkwarden, Omnivore, and Tab Session Manager. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Whisper Money
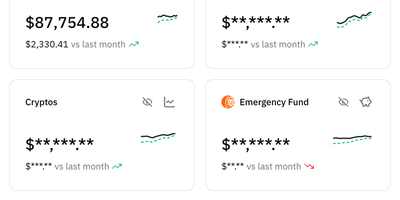
Ditch the spreadsheet for good: Whisper Money is a privacy-first personal finance app you host yourself to see exactly where your money goes, without your data being sold or profiled for ads. Connect multiple bank accounts in one place, fill them by hand or CSV import, and watch transactions categorize themselves automatically. Automation rules handle the repetitive sorting: rent, subscriptions, and transfers land in the right buckets every time. Brokers and exchanges including Indexa Capital, Coinbase, Binance, Bitpanda, Wise, and Interactive Brokers connect with your own API keys, so investments sit beside everyday spending. Optional open banking through EnableBanking can pull a year of movements and keep them current, and it stays switched off until you configure it. AI features suggest categories and rules and summarize your stats reports, and you choose the provider: Gemini by default, or OpenAI, Anthropic, Groq, DeepSeek, Mistral, any OpenAI-compatible endpoint, or a local Ollama server so nothing leaves your infrastructure. Spending pattern insights turn raw transactions into an honest picture of your habits, month after month. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. CC BY-NC 4.0 licensed.
Actual Budget
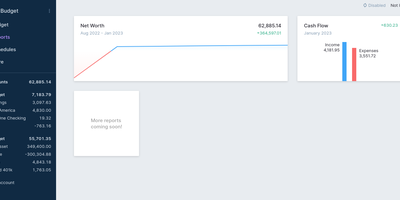
Every unit of income gets a job in Actual Budget - a local-first personal finance app built on envelope (zero-sum) budgeting, where you can only budget cash you actually have, which keeps the plan honest by construction. The data model is a SQLite file that lives on your device and works fully offline; the self-hosted Node.js sync server adds background multi-device synchronization using CRDT-based distributed-systems machinery, browser and mobile access as an installable web app, and automated backups. Optional end-to-end encryption makes the synced data unreadable even to the server hosting it. Transactions enter three ways: manual entry, file import (CSV, QIF, OFX, QFX, CAMT.053), or automatic bank syncing through GoCardless for EU/UK banks and SimpleFIN for US/Canada. Built-in YNAB4 and nYNAB importers migrate complete budget histories, and reports, schedules for recurring transactions, and rule-based transaction cleanup handle the day-to-day. A fully featured local API lets developers script custom importers and automation against their own data. 100% free, open source, and 26k stars strong.
LinkWarden
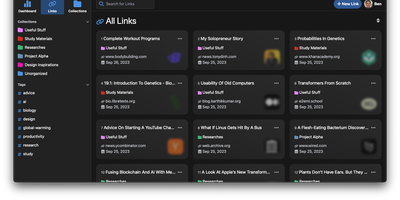
Links rot - the hard truth Linkwarden is built around, as a collaborative bookmark manager that preserves what it saves. Every page you save is fully preserved - a screenshot, a PDF, a self-contained single-file HTML archive (generated by the Monolith Rust binary), and a clean reader view - so the content survives even after the original site disappears. Think of it as a private Wayback Machine you own, with an optional one-click snapshot to archive.org on top. The reading experience matches the archival rigor: a distraction- free reader view supports text highlighting and annotation, and full-text search across everything you have saved is powered by Meilisearch. Optional AI tagging analyzes page content and auto-assigns tags - generate new ones, pick from your existing set, or constrain to predefined tags - with providers ranging from local Ollama models (fully private) to OpenAI, Anthropic, and OpenRouter. Organization is collections, sub-collections, and multiple tags per link; teams collaborate on shared collections with per-member permissions, and public collections share curated link sets (with preserved copies) to anyone. The stack is Next.js/React on TypeScript with PostgreSQL via Prisma, NextAuth supporting credentials, OAuth2, and SAML SSO, and a Playwright-driven headless Chromium worker doing the capture. Native iOS and Android apps and browser extensions feed it from anywhere.
LinkAce
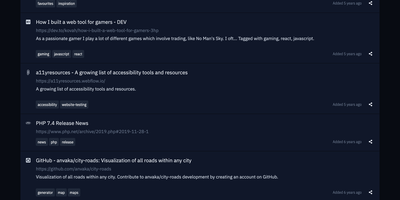
Preventing silent link rot across research libraries, LinkAce captures, indexes, and permanently archives web discoveries into searchable multi-user collections with automated Wayback Machine snapshots. Curators bookmark articles, documentation, tools, and media using custom browser bookmarklets or quick-add input fields that automatically scrape page titles and metadata descriptions. The built-in link monitor continuously checks saved endpoints for HTTP status anomalies, alerting curators whenever destinations move, throw server errors, or vanish from the live internet. For long-term preservation, the system dispatches automated backup requests to the Internet Archive Wayback Machine to capture historical copies of critical research material. Curators organize their library using nested lists and granular tag hierarchies, switching seamlessly between compact tables, detailed reading feeds, and visual card layouts. Teams and households can create separate user accounts to collaborate on shared collections, delegating read-only or editing privileges per list. The platform also generates individualized RSS feeds for public or private bookmark streams, synchronizes external data through a tokenized REST API, and dispatches automated database dumps to AWS S3 storage buckets. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Ties
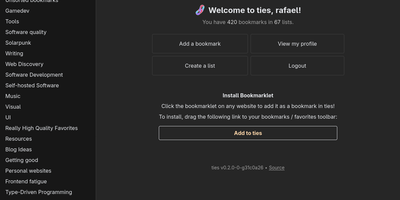
A federated bookmark manager written in Rust: Ties (formerly linkblocks) is your own small corner of the web for saving, organizing, and sharing good pages, connected to the fediverse over ActivityPub. Instead of rigid folders, bookmarks live in arbitrarily nested lists that link together into a knowledge graph. Saved pages are fetched, converted to a readable archived version, and stored in the database, so full-text search covers titles, URLs, and the actual page text - and the content survives if the original disappears. The federation model is deliberately anti-viral: there is no global timeline and no algorithmic feed. You publish public lists for anyone, follow users whose taste you trust, and mark trusted users whose bookmarks become part of your search range - extendable to trusted-users-of-trusted-users for a wider net. Public bookmarks post to Mastodon timelines, and WebFinger lookup makes your handle discoverable across fediverse platforms. Operationally it is about as light as web software gets: a single binary with all assets baked in, integrated TLS so it can run without a reverse proxy, PostgreSQL as the only dependency, OIDC single sign-on, and a bookmarklet for one-click saves. Note the project is alpha: single-user instances only, and all data should be considered public. AGPL-3.0 licensed, built with Rust and htmx.
YAFFA
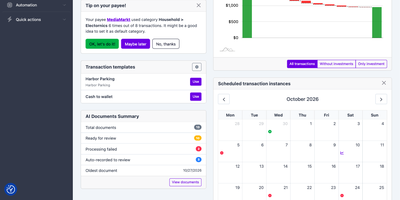
If your money is split across a bank app, a brokerage portal, and a half-abandoned spreadsheet, YAFFA, a self-hosted personal finance application, gathers it into one ledger with budgets, scheduled transactions, and forecasts. Record withdrawals, deposits, and transfers across unlimited accounts, and split a single supermarket receipt across categories so it lands in both Food and Household. Suggestions surface your most-used accounts and payees, and each payee's default category fills in automatically. Define rent, salary, or a loan payment once as a scheduled transaction; it appears on the dashboard calendar, enters with one action or records itself, and feeds the forecast. Import bank history from CSV or QIF files with rules for country- and bank-specific formats, and review every row before it is recorded. Optional AI document processing turns a receipt, invoice, or forwarded email into a draft transaction with payee, date, amount, and line items, using your own OpenAI or Gemini key and self-hosted Tesseract OCR for images. Accounts in different currencies roll up into your default currency using daily rates from the free Frankfurter service. Investments track gain and loss, with optional daily prices from Alpha Vantage. The dashboard summarizes accounts and upcoming schedules, the cash flow report can look ahead with a forecast, and Find Transactions filters history by payee, category, tag, or date. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
ArchiveBox
Backed by 27,700+ GitHub stars and actively developed with the v0.9.x architectural overhaul introducing an event-driven plugin ecosystem, ArchiveBox delivers the open-source self-hosted web archiving platform that preserves websites, bookmarks, social posts, media, source code, and research material in durable formats before link rot, platform shutdowns, and censorship erase them permanently. Feed it URLs one at a time or schedule automated imports from browser history, RSS feeds, Pocket, Pinboard, Instapaper, Wallabag, Shaarli, JSON, CSV, HTML bookmark exports, and browser extension captures. Each snapshot stores redundant copies as original HTML, rendered single-file HTML via SingleFile, full-page PDF, screenshot PNG, WARC archive, article text via Readability, favicons, HTTP headers, media files via yt-dlp, git repository clones, and structured metadata in SQLite. The Docker Compose deployment bundles Chrome, wget, curl, yt-dlp, SingleFile, and Readability parsers with automatic dependency management and isolation. Interact through the self-hosted web UI with search, tagging, and admin controls, the comprehensive CLI for batch operations, the REST API for programmatic access, or the Python API for custom integrations. The new abx-plugins system enables community extractors with per-plugin configuration, while the append-only-log architecture provides resumable crawls and audit trails. S3, B2, and Google Cloud storage backends sync archives to remote storage via rclone. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
PinePods
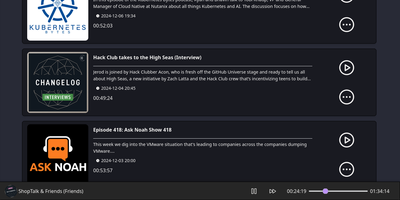
PinePods delivers a centralized, self-hosted podcast ecosystem that liberates personal listening histories, audio files, and show subscriptions from commercial streaming walled gardens. Users can discover new shows through built-in search connectors across Podcast Index, iTunes, and YouTube, streaming audio and video episodes with variable playback speed, chapter markers, and synchronized transcripts. A persistent queue and custom playlist builder keep media sequences orderly across web browsers, desktop installations, and mobile clients with native CarPlay and Android Auto support. Built-in gPodder server synchronization enables seamless cross-device progress tracking with third-party podcast apps like AntennaPod. Automatic episode downloader engines monitor subscribed feeds, archiving new releases to local server storage according to customizable retention rules and storage quotas. Multi-user authentication secures household access through OIDC single sign-on and two-factor TOTP verification, while an integrated terminal client lets command-line enthusiasts manage queues directly over SSH. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
ExpenseOwl
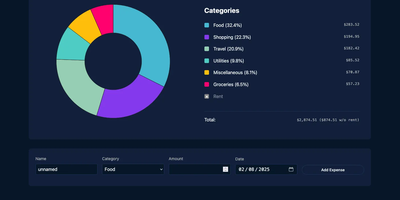
Log a date, amount, and category; get a clean monthly pie chart and a cashflow strip showing income, expenses, and net balance - ExpenseOwl is expense tracking stripped to what actually matters. The MIT-licensed Go application deliberately is not a budgeting system - no envelopes, no accounts, no double-entry, no bank sync - because its author found tools like Firefly III and Actual too heavy for the simple question "where did this month's money go?" The dashboard makes that question fast: click a pie slice to exclude fixed costs like rent and see discretionary spending clearly, then drill into a chronological table view to inspect or delete individual transactions. Recurring transactions handle salaries and subscriptions automatically, optional tags add a second classification axis, and settings cover custom categories, currency symbol, and a configurable month start date for non-calendar pay cycles. CSV import migrates data from virtually any other tool, and CSV export keeps your data portable. It ships as a self-contained binary and multi-architecture Docker image with zero internet interaction, stores data in flat JSON files by default (PostgreSQL optional), and installs as a PWA on phones. Single-user by design; pair it with an authenticating reverse proxy if exposed publicly.