Chroma
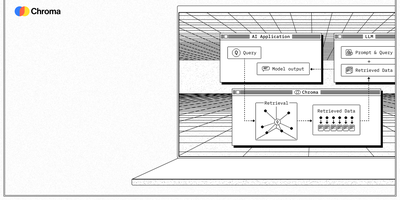
With over 29,000 GitHub stars and deep integrations into LangChain, LlamaIndex, and CrewAI, Chroma has become the default vector database for developers building retrieval-augmented generation pipelines and AI agent memory systems. Its core API consists of just four functions — create, add, query, and delete — making it the fastest path from zero to semantic search, while the underlying Rust engine handles tokenization, embedding, HNSW indexing, and similarity scoring automatically. Chroma supports dense vector search via HNSW with configurable distance metrics including L2, cosine similarity, and inner product, sparse vector search using SPLADE, full-text BM25 keyword search, and regex matching, all combinable in hybrid queries through a single unified interface. Metadata filtering at query time uses MongoDB-style operators including $eq, $ne, $gt, $lt, $in, and logical combinators $and and $or, enabling precise result scoping without post-processing. The multimodal pipeline powered by OpenCLIP embeds text and images into a shared vector space, allowing cross-modal retrieval where text queries return relevant images and vice versa. Deployment options range from embedded mode via PersistentClient for notebooks and prototypes, to client-server mode with Docker for production, to Chroma Cloud for serverless scalability. Official Python and JavaScript SDKs provide identical APIs, and embedding function integrations support OpenAI, Cohere, Hugging Face, Google, Ollama, and custom models. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Paperless-AI
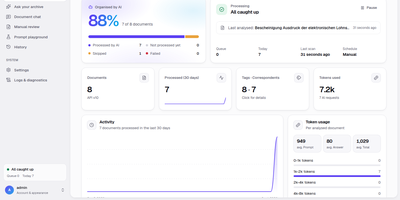
Paperless-AI reads every new scan that lands in your Paperless-ngx archive and fills in the title, tags, correspondent, document type, date, and custom fields so you stop doing it by hand. A dashboard tracks the processing queue, coverage, activity, and token usage. Ask your archive questions like "when did I sign my rental agreement" and get streamed answers with numbered citations that link back to the documents. Hybrid keyword and semantic search finds passages across thousands of pages, and follow-up questions keep their context. Manual Review shows the AI's suggestions beside the current values so you decide what to save. A prompt playground tests wording on real documents, and a history page with undo restores the original values in Paperless. Choose OpenAI, Claude, Ollama, Azure, or any OpenAI-compatible endpoint, and a workflow webhook processes documents the moment they arrive. A command menu jumps between pages, and light and dark themes come with five accent colours. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
RAGFlow
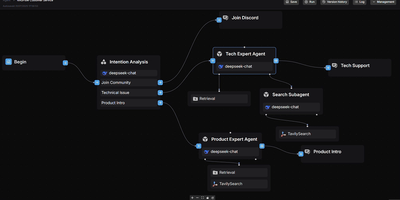
RAGFlow has established itself as one of the most widely adopted open-source RAG engines available, powering production AI systems that demand traceable, hallucination-free answers from complex enterprise data. The platform processes PDF, DOCX, Excel, and PPT files through vision-based deep document understanding with layout analysis and OCR, extracting structured knowledge from tables, charts, and images that simpler parsers miss entirely. RAGFlow's hybrid retrieval pipeline combines vector search with BM25 keyword matching and multi-stage reranking across configurable document stores including Elasticsearch, InfiniFlow's Infinity engine, OpenSearch, and OceanBase. Developers connect any combination of LLM providers — OpenAI, DeepSeek, Anthropic Claude, Google Gemini, and locally-hosted models via Ollama — through a unified configuration layer. The visual agent workflow system enables multi-step reasoning chains with persistent memory, tool calling, and pre-built templates for common enterprise scenarios. RAGFlow synchronizes data from Confluence, S3, Notion, and Google Drive, and delivers answers through chat integrations with Feishu, Discord, Telegram, and Line. The Python SDK and RESTful API on port 9380 provide programmatic access to knowledge base management, document parsing, and conversational retrieval. The full stack deploys via Docker Compose with MySQL for metadata, Redis for task orchestration, and MinIO for object storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Resume Matcher
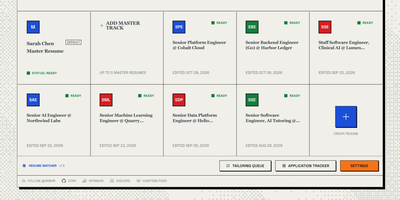
Stop rewriting the same resume forty times for forty job posts. Resume Matcher keeps one master resume, then tailors a fresh version for each job description you paste in, with prompts that forbid inventing skills, employers, or metrics you never had. Upload a PDF or DOCX, review the suggested edits, drag sections into a new order, and pick a template: single column, two column, modern, LaTeX, clean, vivid, or Deedy styles that export as text-based PDFs in A4 or US Letter. A JD Match tab highlights shared keywords and calculates an ATS score from keyword match, skills coverage, title match, section completeness, and date consistency, and an ATS Check tab reads your exported PDF back like an applicant tracking system would. Cover letters, cold outreach messages, and interview preparation are generated from the same resume and job description. The Tailoring Queue processes several pasted job descriptions in the background, and the Application Tracker follows each tailored resume through your pipeline. Choose OpenAI, Anthropic, Gemini, DeepSeek, OpenRouter, or Groq, or run Ollama so your resume never leaves the server, and switch the interface between seven languages. An MCP server lets Claude Code or Cursor write the tailoring, and Resume Matcher stores and renders it. Run it as one Docker container on port 3000 with a SQLite file for data. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Elasticsearch
With over 70,000 GitHub stars and billions of documents indexed across enterprises like Uber, Netflix, and Wikipedia, Elasticsearch is the world's most deployed search engine, powering everything from application search to security analytics and AI-driven retrieval. Built on Apache Lucene, its inverted index architecture delivers sub-second full-text search across terabytes of data with BM25 relevance scoring, configurable analyzers for 30+ languages, and fuzzy matching for typo tolerance. The kNN vector search API uses the HNSW algorithm for approximate nearest neighbor queries on dense and sparse embeddings up to 4,096 dimensions, while reciprocal rank fusion enables hybrid search that combines lexical and semantic signals in a single query. Elasticsearch's aggregation framework supports metric, bucket, and pipeline aggregations for real-time analytics directly on indexed data without separate OLAP infrastructure. The cluster distributes data across shards with automatic rebalancing, replica allocation, and cross-cluster search for multi-datacenter deployments. Kibana provides the visualization layer with dashboards, Lens visual editor, Canvas for pixel-perfect reports, and Discover for ad-hoc log exploration. Ingest pipelines with processors like grok, dissect, GeoIP enrichment, and inference handle data transformation at index time, and ES|QL brings pipe-based query syntax with joins and columnar processing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL v3 licensed.
Hindsight
Memory that survives the session: Hindsight extracts facts, entities, and timestamps from everything an AI agent retains, then lets the agent search or reason over it later. Adding it to an existing LLM client takes a two-line wrapper, and more than 60 integrations cover Claude Code, Cursor, LangGraph, CrewAI, and n8n. Every bank also exposes its own MCP endpoint. Retain sends text, images, or files through an LLM that extracts facts, timestamps, entities, and relationships. Recall runs semantic, keyword, graph, and temporal searches in parallel, merges them with reciprocal rank fusion, reranks with a cross-encoder, and trims to a token budget. Reflect reasons across memories for questions that need synthesis, shaped by per-bank skepticism, literalism, and empathy traits. In the background, related facts consolidate into observations that keep exact quotes and proof counts and are refined, never silently overwritten. Mental models and wiki-style knowledge pages hold standing answers that rewrite themselves as the bank learns. Each user, agent, or project gets an isolated bank with no cross-bank leakage, and Memory Defense redacts or blocks secrets and PII against 45 patterns. The Control Plane adds a Recall Analyzer with traces, a memory constellation graph, and a knowledge page editor. Extraction and reasoning can run on 25+ LLM providers, including local Ollama and llama.cpp. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
SearXNG
Up to 280 search services - Google, Bing, DuckDuckGo, Brave, Qwant, Startpage - aggregated without tracking or profiling: SearXNG is a privacy-respecting metasearch engine (AGPL-3.0, successor to Searx). Your instance queries the upstream engines on your behalf: your IP address, cookies, and search history never reach them, tracker parameters are stripped from result URLs, and an optional image proxy fetches thumbnails server-side so result pages leak nothing. It can even route outbound queries through Tor for full anonymity. Search is organized into categories - general, images, videos, news, maps, music, IT, science, files - with bang shortcuts for targeting specific engines, and every source can be enabled, disabled, or weighted per category in settings.yml. A plugin system adds calculators, hash tools, tracker removal, and unit conversions inline, and preferences (themes, safe search, languages, engine selection) persist in cookies rather than server-side accounts. The real argument for running your own instance rather than trusting a public one is control: you decide the logging policy (none), the engine mix, rate limiting, and who gets access - making it the default search backend for browsers, families, and teams that want Google-quality results without the profile.
Scira
Scira is an AI search engine that breaks complex research questions into sub-tasks, retrieves grounded answers from live sources, and cites every claim with clickable links to the original evidence. Formerly known as MiniPerplx and now backed by nearly 12,000 GitHub stars, the platform implements agentic research planning where language models decompose queries, select appropriate tools, retrieve information in parallel, and synthesize responses with inline citations. Seventeen distinct search modes cover Web, Academic, Extreme, X (Twitter), Reddit, GitHub, Stocks, Crypto, YouTube, and Prediction markets, each activating a curated subset of the 28 built-in tools. The Extreme mode deploys a deep research agent with multi-step planning, parallel source retrieval, code execution in sandboxed Daytona environments, and R2 artifact storage for generated charts. Model routing spans 50+ AI providers through a unified configuration layer supporting OpenAI, Anthropic, Google, xAI Grok, and custom models, with per-mode model assignment based on task requirements. The web search tool supports Exa, Tavily, and Firecrawl as interchangeable providers via a Strategy pattern. Lookouts schedule recurring research agents on cron schedules that monitor topics, track changes, and email summaries using Upstash QStash for reliable execution. PostgreSQL stores chat history, user preferences, and custom instructions while Redis handles caching and rate limiting. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Hoarder
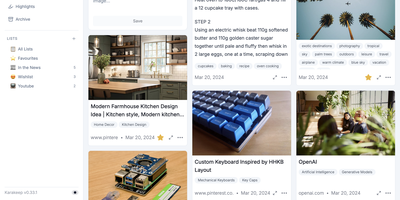
Hoarder (now Karakeep) is a bookmark manager that actually fights link rot: every page you save gets archived at capture time using Monolith, so the content survives even when the original URL dies. Beyond archival, an AI layer powered by OpenAI or local Ollama models auto-tags everything by analyzing page content. Prefer full privacy? Ollama keeps all inference on your server with zero external API calls. Full-text search through Meilisearch indexes the actual scraped content of every bookmark, not just titles and tags, so you find articles by what they say rather than labels you half-remember. Save links with automatic metadata extraction, plain text notes, uploaded images, and PDF documents, all organized into shareable lists with collaborative access. Browser extensions for Chrome and Firefox make saving a one-click operation from any page. Migrating is painless with importers for Chrome, Pocket, Linkwarden, Omnivore, and Tab Session Manager. LLM summarization condenses saved pages into brief overviews for quick scanning. The AI layer is entirely optional: Hoarder works perfectly as a manual bookmark manager, with intelligence adding convenience rather than imposing a requirement. SSO integration and responsive dark mode round out the package.
Dgraph
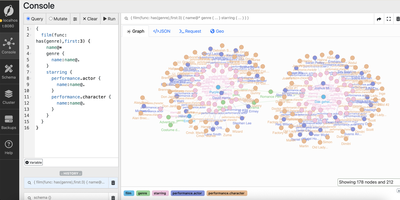
Dgraph is a distributed graph database that answers connected-data questions, such as who follows whom or which parts depend on which suppliers, in a single query instead of a pile of joins. Describe your data in a GraphQL schema and Dgraph generates a GraphQL API with its graph backend, or write DQL, the native query language, for deeper traversals. Indexes handle full-text search, regular expressions, and geo queries, and vector indexes add similarity search over embeddings. Transactions stay ACID across the cluster, replication is consistent, and data shards rebalance themselves as the dataset grows. Ratel, the companion web IDE, runs queries and mutations, draws results as a graph, edits the schema, lists cluster nodes, and manages backups. Bulk Loader fills a new cluster with large datasets, while Live Loader adds or upserts records into a running one. Access control lists and namespaces keep tenants apart within one cluster. It suits data spread across more than ten tables linked by foreign keys, sparse records that fit poorly in SQL, and schemas that must stay simple to read and change. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Omni
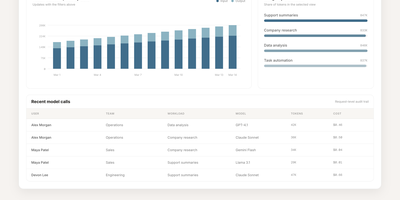
Omni is an open-source workplace AI agent and enterprise search platform that unites your company's scattered tools into a single context-aware workspace where team members can find answers and automate cross-application workflows. Employees can query connected knowledge sources including Google Drive, Gmail, Slack, Jira, GitHub, Confluence, and HubSpot to locate project specifications, customer records, and operational documents without jumping across tabs. The integrated AI assistant answers complex multi-step inquiries, summarizes lengthy email threads, and cites exact source passages so workers can verify factual accuracy before making business decisions. Granular permission inheritance mirrors existing access controls across every connected service, guaranteeing that sensitive personnel files, financial statements, and confidential repositories remain hidden from unauthorized staff. Engineers can construct bespoke data connectors and define automated agent skills through the extensible Python and TypeScript software development kits, triggering multi-service actions directly from interactive chat dialogues. Administrators can monitor background synchronization jobs, inspect audit trails, manage single sign-on access, and configure custom extraction pipelines using centralized operational dashboards. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Onyx
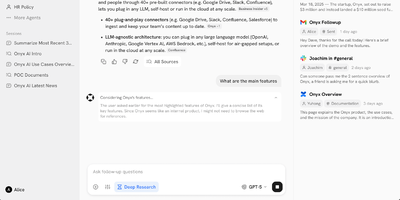
Formerly known as Danswer and now backed by over 31,000 GitHub stars with 253 releases, Onyx delivers a production-ready AI platform that turns any LLM into a context-aware enterprise assistant connected to your organization's actual knowledge. The agentic RAG pipeline combines BM-25 keyword search with prefix-aware embedding models in a hybrid index, then deploys AI agents to retrieve, verify, and synthesize answers with source citations from over 40 connected workplace tools including Google Drive, Confluence, Slack, Notion, Jira, SharePoint, GitHub, and Linear. Custom AI assistants with configurable prompts, backing knowledge sets, and document-level access control enable specialized agents for engineering, sales, support, and research workflows. The platform supports every major LLM provider — Anthropic Claude, OpenAI, Google Gemini, plus self-hosted options via Ollama, LiteLLM, and vLLM for fully air-gapped deployments. Beyond chat, Onyx provides web search with Serper, Google PSE, Brave, and SearXNG integration, an in-house web crawler, code execution, file creation, and multi-step deep research with report generation. Enterprise features include SSO via Google OAuth, OIDC, or SAML with SCIM provisioning, role-based access control, usage analytics by team and agent, query history auditing, PII removal through custom code hooks, and full whitelabeling. Deploy via Docker Compose on any infrastructure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed (Community Edition).
GeoLook
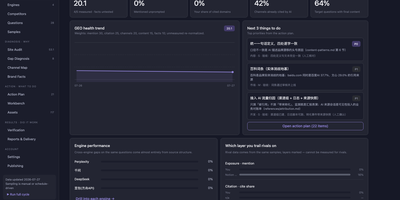
GeoLook shows you what AI search engines actually say about your brand, then turns that uncomfortable answer into a fix list you can work through and verify. You sample real answers across a wide matrix of AI engines and watch mention rate, ranking, and citation share appear per engine, with raw answer replay when a number looks suspicious. Competitor tables reveal which rival each engine prefers and which citation sources they rely on that you do not. A structured question bank sorts buyer, education, and probing questions, flagging the ones where you are absent, outranked, or described negatively. The site audit checks whether crawlers can reach, understand, and quote your pages, in the order those failures actually block visibility. Findings become tickets with an owner, effort estimate, risk grade, and acceptance check, and later sampling rounds confirm whether a fix worked or reopen the ticket when results slip. A content workbench ranks the topics most worth writing, checks drafts for citability, and prepares assets such as llms.txt and structured data snippets for publishing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Vane
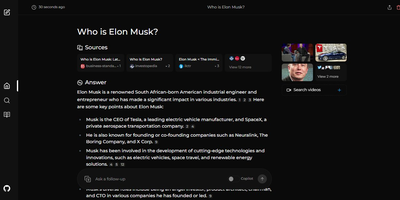
Perplexity's search experience without Perplexity: Vane deploys Perplexica, an open-source AI answer engine built as the self-hosted alternative. Instead of returning a page of links, it reads your question, searches the live web through the SearxNG metasearch engine, and composes a direct answer with cited sources. Retrieval quality comes from embeddings and similarity search: fetched pages are re-ranked against the query so the model answers from the most relevant passages rather than whatever ranked first. Two query modes cover different needs - Normal mode runs a straightforward web search, while Copilot mode generates multiple reformulated queries and actively pulls content from top matches for harder questions. Focus modes specialize retrieval for academic papers, YouTube, Reddit discussions, Wolfram Alpha calculations, or the general web. The answering model is your choice: OpenAI-compatible APIs or fully local LLMs such as Llama 3 and Mixtral through Ollama, which keeps queries entirely on your infrastructure. Because SearxNG pulls live results, answers reflect current information, and no search history is tracked.
OpenSERP
Search the web from your own server, with no API key and no per-query bill: OpenSERP is a self-hosted search API that returns structured results from Google, Bing, Yandex, Baidu, DuckDuckGo, and Ecosia through one interface. Every answer arrives as ranked JSON with titles, URLs, snippets, source engines, and timing, ready for an agent, a RAG pipeline, or an SEO tracker to consume. A mega search aggregates and deduplicates across engines in a single call, image search does the same for pictures, and an extract mode reads linked pages back as clean Markdown for models to cite. AI agents connect over MCP with tools for search, mega search, fast search, image search, and batch extraction, and it is a built-in web search provider in Open WebUI. Developers get Python and TypeScript SDKs, an n8n node, a full OpenAPI reference, and a CLI that runs the same searches from a terminal. Engines load in a real browser session, proxy support routes traffic through HTTP or SOCKS5, and one Docker command serves everything on port 7000. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Supernote
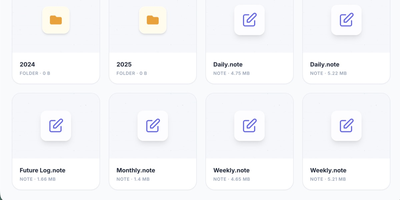
Your Supernote tablet fills with handwritten journals, meeting notes, and sketches, and this server gives that handwriting a private home: Supernote is a self-hosted sync cloud for Ratta Supernote tablets that stores notebooks on your own hardware and can transcribe, summarize, and search them with AI. Point the tablet at your server under its Private Cloud sync setting and notebooks upload automatically, ready to browse in the web interface alongside your task lists and AI insights. Turn on the intelligence layer and each synced page is transcribed by a vision model, either Google Gemini or a local model served by Ollama or another OpenAI-compatible endpoint, so notes never leave your network. Analyzers then read your journals to surface tasks, themes, and Daily, Weekly, and Monthly summaries. Every word is indexed for semantic search, which understands concepts: searching for budget also finds pages about expenses or money, even when that exact word never appears. Tasks discovered in your handwriting export as calendar feeds that drop into Home Assistant, Apple Calendar, Google Calendar, and Outlook. An MCP server lets assistants such as Claude, Gemini, and ChatGPT answer questions against your notebooks, and notebooks convert to PDF, PNG, SVG, or plain text for use anywhere else. The hub idles at about 160 MB of memory, or roughly 135 MB in bare sync mode. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Valkey
With 26,600 GitHub stars, 50 contributing companies including AWS, Google Cloud, Oracle, and Ericsson, and governance under the Linux Foundation ensuring the BSD 3-Clause license can never be revoked by a single entity, Valkey delivers a truly open-source Redis-compatible key-value datastore that reached 1.19 million requests per second in version 8.0 through redesigned asynchronous I/O threading across CPU cores while maintaining single-threaded data structure operations for predictability. Native data structures include strings, hashes, lists, sets, sorted sets, bitmaps, HyperLogLogs, streams, and geo-spatial indices with JSON support through modules. Valkey 9.0 shipped full-text search and aggregation via Valkey Search, enabling tag queries, numeric filtering, and text matching directly within the datastore without external search engines. Cluster mode provides horizontal scaling with automatic sharding, replication for high availability, and per-slot metrics for granular monitoring. Lua scripting enables complex atomic operations, while the module plugin system extends the server with custom commands and data types including probabilistic Bloom filters. Client libraries for Python, Java, Go, Node.js, and PHP maintain full Redis OSS protocol compatibility — existing Redis applications work without code changes. Deploy as a standalone daemon or in clustered mode with Docker, supporting persistent and ephemeral workloads on any Linux host. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSD 3-Clause licensed.
Khoj
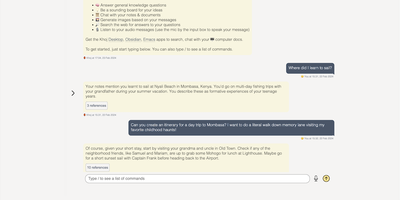
A self-hosted "second brain": Khoj indexes your own files and answers questions from them, parsing Markdown (whole Obsidian vaults included), org-mode, PDF, Word, plain text, Notion pages, GitHub repositories, and images described by a vision model, then embedding everything with sentence-transformers into a vector index for semantic search and RAG with cited sources. Any LLM backend works: local models like Llama, Qwen, or Mistral via Ollama, or cloud models like GPT, Claude, and Gemini. You can build custom agents, each with its own persona, scoped knowledge base, chat model, and tools such as web search and code execution. Scheduled automations run recurring research and deliver newsletters or notifications to your inbox, and research mode performs multi-hop web searches with inline citations. Access it from a browser, the Obsidian plugin, Emacs, desktop, or WhatsApp - all clients connect to the same self-hosted instance, making Khoj one of the few AI assistants Emacs users can point at decades of org files. Semantic search means recall works without exact keywords: "that paper about forecasting with transformers" surfaces the right PDF even when you cannot remember its title. Switching LLM backends never requires re-indexing your documents, and with a local model via Ollama, even inference stays on hardware you control - journals, research, and private notes are never sent anywhere. Python/FastAPI stack, AGPL-licensed, with PostgreSQL storage.