ParadeDB
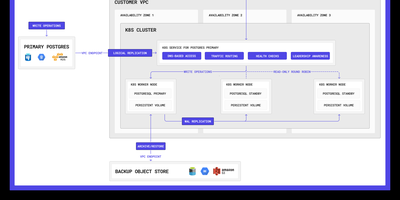
ParadeDB turns the Postgres you already run into a full search and analytics engine, so your application data, full-text search, vector retrieval, and aggregations all live in one database. Create one ParadeDB index over a table and you can run relevance-ranked BM25 queries with tokenizers, phrase matching, highlighting, and Top-K retrieval using plain SQL. The same index stores pgvector embeddings, so similarity search composes with text predicates and filters, and hybrid queries fuse both rankings when a question needs keywords and meaning at once. Aggregations push into the index too: ordinary GROUP BY queries accelerate, and Elasticsearch-style JSON aggregations return facets, histograms, percentiles, and cardinality for filterable search interfaces. Because the index updates in the same transaction as your writes, search results are never stale and there is no ETL pipeline, sync job, or second system to babysit. JOINs against the rest of your schema keep working, since search is just another index inside your system of record. Teams typically retire a separate search cluster while keeping sub-second relevance search, semantic retrieval for AI features, and faceted analytics on the data they already store. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Apache Solr
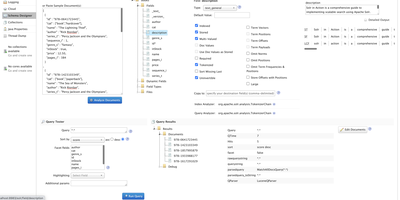
Product catalogs, help centers, and document archives all fail the same way: visitors type a few words, get the wrong results, and leave. Apache Solr is the search platform behind fast, relevant answers, returning ranked matches with faceted filters, highlighted snippets, spell suggestions, and geospatial distance in a single query. Index documents through HTTP updates or data import handlers, shape fields in the schema, and watch changes appear through near-real-time indexing without rebuilding the corpus. SolrCloud turns one index into a distributed collection: shards split large corpora across nodes, replicas copy each shard for failover and query load, and ZooKeeper coordinates configuration so every node serves the same schema. Dense vector fields store embeddings beside your text, and the KNN parser retrieves nearest neighbors through HNSW graphs, so semantic search runs in the same engine as keyword search instead of a second system. A combined query handler merges keyword and vector rankings with reciprocal rank fusion, and an enrichment processor can call language models at index time to tag or summarize documents as they arrive. Streaming expressions add analytics over results, from rollups and percentiles to joins across collections, while JWT authentication and authorization rules protect the admin console and APIs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
YaCy
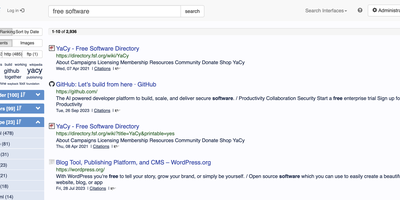
Search engines normally rent you answers from an index you cannot inspect; YaCy installs the entire machine on your server: the crawler, the index, the ranking, and the search page itself. Run it as a public web search portal with faceted results, topic clouds, and image search, or point the crawler at your intranet where a network scanner discovers HTTP, FTP, and file servers for a private enterprise search. Expert crawl jobs take start URLs, sitemaps, or link lists with depth limits, per-domain caps, and freshness rules, and the scheduler keeps re-crawling so results stay current. Peers exchange index data over a built-in peer-to-peer protocol, so a fresh installation can answer from the shared network index before its own crawl has seen much of the web. Private modes cut that connection for local-only answers computed on your hardware alone. The index browser walks stored hosts and draws link graphs of what the crawler found. Every page in the interface has an XML or JSON twin for automation, and the portal design tools restyle the result page for embedding in your own site. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-2.0 licensed.
Fess
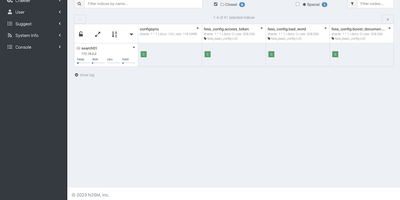
Eliminate indexing blind spots across fragmented company networks with Fess, a distributed enterprise search engine that crawls internal document repositories, corporate intranets, and cloud services to provide employees with instant, permission-aware file discovery. Organizations can schedule automated crawlers across web pages, network shares, databases, and third-party storage platforms to extract text and generate visual thumbnails from PDFs, spreadsheets, presentations, and compressed archives. Users can search indexed records using natural language queries, filtering results by file metadata, creation dates, categories, and geographic coordinates while viewing contextual snippets with highlighted keyword matches. Granular role-based permissions mirror directory security structures from Active Directory and LDAP so staff only see search results for documents they have explicit authorization to inspect. The browser-based administrative console lets operations teams define path mapping rules, manage virtual hosts, monitor active crawl jobs, inspect error logs, and configure scheduled re-indexing workflows without modifying server configuration files. Security teams can establish single sign-on across the organization using SAML or OpenID Connect authentication providers to secure administrative workflows and search portals. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Elasticsearch
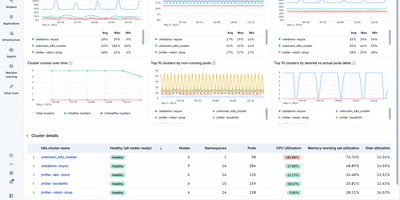
With over 70,000 GitHub stars and billions of documents indexed across enterprises like Uber, Netflix, and Wikipedia, Elasticsearch is the world's most deployed search engine, powering everything from application search to security analytics and AI-driven retrieval. Built on Apache Lucene, its inverted index architecture delivers sub-second full-text search across terabytes of data with BM25 relevance scoring, configurable analyzers for 30+ languages, and fuzzy matching for typo tolerance. The kNN vector search API uses the HNSW algorithm for approximate nearest neighbor queries on dense and sparse embeddings up to 4,096 dimensions, while reciprocal rank fusion enables hybrid search that combines lexical and semantic signals in a single query. Elasticsearch's aggregation framework supports metric, bucket, and pipeline aggregations for real-time analytics directly on indexed data without separate OLAP infrastructure. The cluster distributes data across shards with automatic rebalancing, replica allocation, and cross-cluster search for multi-datacenter deployments. Kibana provides the visualization layer with dashboards, Lens visual editor, Canvas for pixel-perfect reports, and Discover for ad-hoc log exploration. Ingest pipelines with processors like grok, dissect, GeoIP enrichment, and inference handle data transformation at index time, and ES|QL brings pipe-based query syntax with joins and columnar processing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL v3 licensed.
Gorse
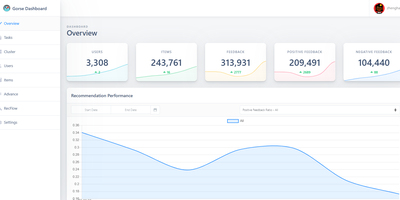
Gorse generates personalized recommendations from your application's user interaction data through automatically trained models, requiring no machine learning expertise to deploy or operate. Over 10,000 GitHub stars and production deployments processing millions of interactions validate a multi-source architecture that merges candidates from latest-item, user-to-user, item-to-item, and collaborative filtering recommenders, then ranks them using factorization machines or LLM-based rerankers with configurable query and document templates. Multimodal content support processes text, images, and video metadata via embedding vectors stored in BF16 format, with optional Qdrant, Weaviate, or Milvus integration for distributed similarity search. The visual RecFlow editor provides a drag-and-drop interface for designing recommendation pipelines, connecting data sources to recommenders and rankers without writing configuration files. A distributed cluster separates concerns across master nodes for model training and dashboard hosting, worker nodes for offline recommendation generation, and server nodes for real-time API endpoints, all scaling horizontally behind load balancers. Online evaluation analyzes recommendation quality from recent user feedback with configurable cache sizes and expiration intervals. RESTful APIs expose CRUD endpoints for users, items, and feedback alongside recommendation retrieval with category filters and API key authentication. Stores data in MySQL, PostgreSQL, MongoDB, or ClickHouse with Redis caching. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Manticore Search
With nearly 12,000 GitHub stars and a lineage tracing back to Sphinx Search, Manticore Search is the C++ search database that delivers the full-text, vector, and hybrid search capabilities of Elasticsearch at a fraction of the resource cost — starting in under a second and consuming just 40MB RAM for an empty instance. The SQL-first interface speaks the MySQL wire protocol, meaning mysql client, MySQL Workbench, and any MySQL-compatible driver connects natively without adapters, while the HTTP JSON API provides RESTful access for modern applications. Over 20 full-text operators handle proximity search, quorum matching, field-start and field-end constraints, MAYBE operators, and regex patterns, backed by stemming, lemmatization, stopwords, synonyms, wordforms, and advanced morphology in 70+ languages. Vector search with HNSW indexing enables semantic similarity queries, and hybrid mode combines keyword relevance with vector distance in a single ranked result set using a cost-based query optimizer. Real-time indexing delivers sub-second document availability after insert, sharded tables distribute data across nodes, and Galera-based synchronous replication ensures high availability. Conversational search via CREATE CHAT MODEL and CALL CHAT integrates LLM-backed responses with KNN retrieval and conversation history directly inside the database. Client libraries ship for PHP, Python, JavaScript, TypeScript, Java, Go, Rust, and Elixir. Columnar storage via the Manticore Columnar Library handles analytical workloads on large datasets. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPLv3 licensed.
Onyx
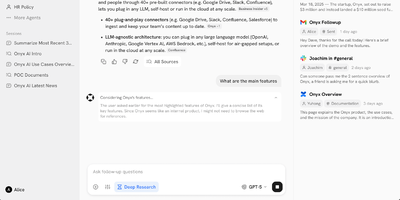
Formerly known as Danswer and now backed by over 31,000 GitHub stars with 253 releases, Onyx delivers a production-ready AI platform that turns any LLM into a context-aware enterprise assistant connected to your organization's actual knowledge. The agentic RAG pipeline combines BM-25 keyword search with prefix-aware embedding models in a hybrid index, then deploys AI agents to retrieve, verify, and synthesize answers with source citations from over 40 connected workplace tools including Google Drive, Confluence, Slack, Notion, Jira, SharePoint, GitHub, and Linear. Custom AI assistants with configurable prompts, backing knowledge sets, and document-level access control enable specialized agents for engineering, sales, support, and research workflows. The platform supports every major LLM provider — Anthropic Claude, OpenAI, Google Gemini, plus self-hosted options via Ollama, LiteLLM, and vLLM for fully air-gapped deployments. Beyond chat, Onyx provides web search with Serper, Google PSE, Brave, and SearXNG integration, an in-house web crawler, code execution, file creation, and multi-step deep research with report generation. Enterprise features include SSO via Google OAuth, OIDC, or SAML with SCIM provisioning, role-based access control, usage analytics by team and agent, query history auditing, PII removal through custom code hooks, and full whitelabeling. Deploy via Docker Compose on any infrastructure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed (Community Edition).
ZincSearch
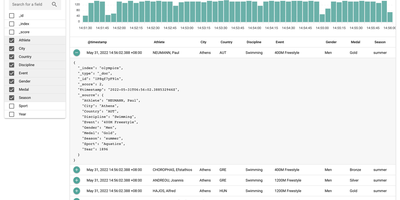
ZincSearch runs full-text search as a single Go binary that consumes a fraction of the memory and CPU that Elasticsearch demands while staying API-compatible, earning 17,800+ GitHub stars as a lightweight alternative. The bluge-powered indexing library processes documents through analyzers, tokenizers, and token filters while maintaining Elasticsearch-compatible ingestion APIs for single-record and bulk operations, letting existing pipelines connect with minimal configuration changes. Schema-less document ingestion accepts JSON payloads without predefined mappings, allowing different documents within the same index to carry different field structures while the engine automatically detects and indexes field types. An embedded Vue.js web console provides a browser-based interface for creating indexes, querying with full-text syntax, browsing results with hit highlighting, managing users, and monitoring system status. A dual API architecture exposes native ZincSearch endpoints under /api alongside Elasticsearch-compatible endpoints under /es, supporting boolean operators, wildcards, phrase matching, fuzzy search, date ranges, and aggregation pipelines including terms, histogram, date histogram, and range aggregations. Multi-tenancy with user-level access control isolates data across teams. Official SDKs for Go, Python, and Node.js provide typed client libraries for programmatic integration. Deploys via Docker or direct binary download with no external dependencies beyond disk storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.