Lenpaste
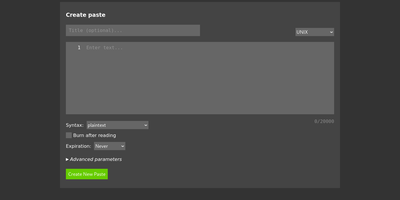
Share code snippets, logs, configs, and notes without registration, tracking, or ads: Lenpaste is a minimal, self-hosted, anonymous alternative to pastebin.com. It is deliberately spartan in the right ways: no accounts, no JavaScript required (the entire site works in text browsers and hardened setups), and cookies used solely to store display preferences. Pastes support syntax highlighting across a long list of languages (from ApacheConf and Arduino to mainstream stacks), configurable expiration from minutes to unlimited, one-use "burn after reading" pastes that self-delete on first view, optional author attribution, and iframe embedding for dropping pastes into other pages. The form-encoded HTTP API covers everything the UI does - create pastes with title, syntax, expiration, and line-ending normalization, fetch them by ID, and query server capabilities - making it trivial to pipe command output to your paste server from shell scripts. Server operators control maximum title and body lengths, maximum paste lifetime, rate limits for viewing and creation, search-engine indexing policy, and can lock private instances behind HTTP Basic authentication. It deploys as a single lightweight Docker container, giving your team a snippet-sharing endpoint where the content never touches a third-party service.
EMQX
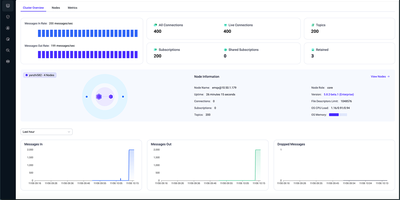
With over 16,500 GitHub stars and a track record powering connected vehicle fleets, smart city sensor networks, and industrial IoT deployments, EMQX is the MQTT messaging platform engineered to handle 100 million concurrent device connections in a single cluster while processing millions of messages per second with sub-millisecond latency. The protocol stack supports MQTT 5.0, 3.1.1, and 3.1 with full QoS 0/1/2 support, shared subscriptions, retained messages, and will messages, plus MQTT over QUIC for faster connection setup, reduced head-of-line blocking, and seamless connection migration on mobile networks. The gateway framework extends connectivity to MQTT-SN, CoAP, LwM2M, STOMP, and ExProto for bridging legacy industrial protocols. The SQL-based rule engine processes and transforms messages in real time with over 50 pre-built integrations including Kafka, PostgreSQL, MySQL, MongoDB, InfluxDB, TimescaleDB, ClickHouse, Redis, AWS Kinesis, GCP Pub/Sub, and Azure Event Hubs. The visual Flow Designer creates data processing pipelines without code. Built on Erlang/OTP with a masterless distributed architecture using Mria for state replication, the cluster separates Core nodes for data consistency and Replicant nodes for client-handling workloads. Authentication supports username/password, JWT, PSK, X.509 certificates, and LDAP with configurable ACL rules. The built-in dashboard provides real-time monitoring of connections, subscriptions, topics, message rates, and cluster health. Deployment runs via Docker, Kubernetes with the EMQX Operator, or native packages. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSL 1.1 licensed.
TriliumNext
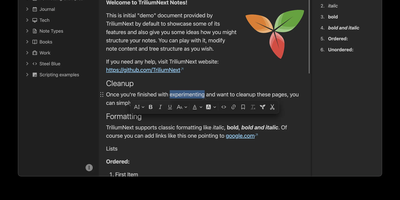
TriliumNext organizes notes in an infinitely deep tree where any single note can be cloned into multiple branches without duplication, building personal knowledge bases that mirror how ideas actually connect rather than forcing a single rigid folder hierarchy. Carrying forward the original Trilium project under active community stewardship with nearly 37,000 GitHub stars, the application is built on TypeScript with a CKEditor 5 WYSIWYG editor supporting rich text, tables, images, KaTeX math expressions, Mermaid diagrams, Excalidraw canvases, mind maps, spreadsheets with XLSX and CSV import/export, and code blocks with full syntax highlighting. A built-in JavaScript scripting engine runs on both frontend and backend, enabling custom widgets, automated workflows, scheduled tasks, and direct interaction with external REST services through a typed Script API. Full-text and fuzzy search with attribute-based queries locates any note instantly across databases tested at over 100,000 notes without performance degradation. The v0.104 release introduced importers for OneNote, Notion, Google Keep, Anytype, and Obsidian alongside 16 dedicated security fixes. Per-note AES encryption, OpenID Connect authentication, and TOTP two-factor protection safeguard sensitive content. The sync server keeps desktop clients, the progressive web app, and mobile devices in lockstep with zero third-party cloud dependency. Web Clipper captures content directly from browsers. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Trilium Notes
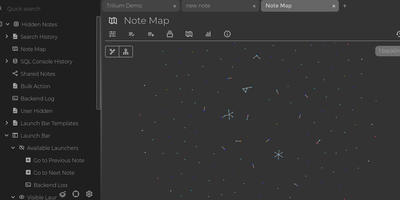
For people whose notes number in the tens of thousands, Trilium Notes is the hierarchical note-taking application built specifically for large personal knowledge bases - actively maintained as TriliumNext. Notes arrange into arbitrarily deep trees where every note is both content and container, and cloning lets a single note live in multiple places at once - bash notes belong under both Linux and Scripting, and Trilium refuses to make you choose. A WYSIWYG editor handles rich text, tables, math, and syntax-highlighted code blocks with Markdown-style shortcuts, while dedicated note types cover Excalidraw sketches, mind maps, geo maps with GPX tracks, relation maps that visualize connections between notes, and tables with typed columns. The attribute system is the power layer: labels attach queryable metadata (#year=1999, #author), relations create named links between notes, and both inherit down the tree - feeding full-text search, saved queries, and scripting. Scripting is Trilium's deepest differentiator: JavaScript code notes run on events like note changes or hourly schedules, build custom widgets, and add server-side logic, turning the knowledge base into a programmable platform. Protected notes encrypt sensitive content, note hoisting focuses on subtrees, and the self-hosted server syncs desktop clients across devices.
Formbricks
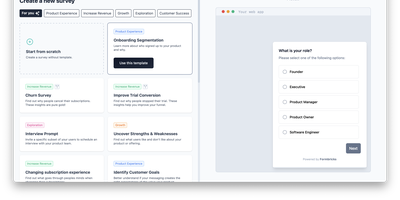
In-app, website, link, and email surveys feed one open-source experience management platform: Formbricks. Its distinguishing strength is targeted in-app research: a JavaScript SDK triggers surveys on user events and attributes, with segmentation rules like "power users who have not seen a survey in 10 days," so questions reach the right cohort at the right moment instead of a mass email blast. The no-code editor offers 20+ question types including NPS, CSAT, CES, matrix, ranking, and file upload, with skip logic, conditional branching, best-practice templates, and full brand theming. Responses feed built-in analytics with summaries and CSV/JSON export, and integrations push data to Slack, Notion, Google Sheets, Airtable, Zapier, and n8n, with webhooks and an open API on every tier. Because self-hosted surveys load from your own domain rather than a blacklisted third-party script host, ad blockers do not suppress them - in-app surveys reach users that Hotjar-style tools silently miss, which measurably raises response rates. Self-hosting also removes the third-party sub-processor from your privacy policy entirely: survey responses often contain PII, and keeping them on your own server matters for GDPR-sensitive and regulated industries. The Community Edition has no response caps or tier-gated features, so core functionality and your data stay accessible regardless of any subscription. Next.js on PostgreSQL, AGPLv3.
Prefect
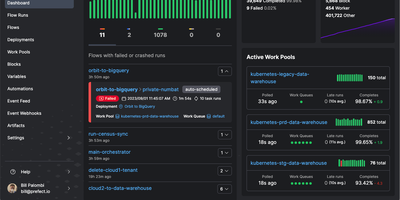
With 23,600 GitHub stars, 13 million monthly PyPI downloads, and 425+ contributors automating over 200 million data tasks monthly for Fortune 50 companies like Progressive Insurance and disruptors like Cash App, Prefect is the most widely deployed open-source workflow orchestration framework for Python — turning any script into a resilient production pipeline with a single @flow decorator while eliminating rigid DAG structures entirely. The durable execution engine persists task results and automatically resumes from failures without replaying expensive upstream work, guaranteeing exactly-once execution for any Python function. Event-driven automation triggers workflows from webhooks, cloud events, or state changes through a real-time event bus that detects what happens or fails to happen across your entire data platform. Work pools decouple workflow code from infrastructure, enabling seamless switching between Docker, Kubernetes, AWS ECS, Azure Container Instances, GCP Cloud Run, and serverless environments without modifying pipeline logic. Native Ray and Dask task runners extend execution across clusters for compute-intensive workloads. The self-hosted server provides a monitoring dashboard with flow run timelines, task state visualization, scheduling, and automation configuration. The third-generation engine reduces overhead by over 90 percent compared to Prefect 2, supporting batch, event-driven, interactive, and background task workflows. Deploy via Docker Compose with PostgreSQL, Redis, server, background services, and worker containers, or use official Helm charts for production Kubernetes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Chroma
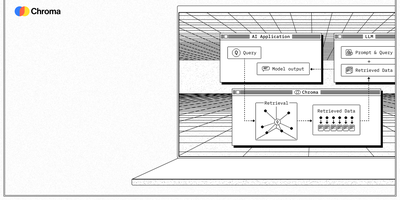
With over 29,000 GitHub stars and deep integrations into LangChain, LlamaIndex, and CrewAI, Chroma has become the default vector database for developers building retrieval-augmented generation pipelines and AI agent memory systems. Its core API consists of just four functions — create, add, query, and delete — making it the fastest path from zero to semantic search, while the underlying Rust engine handles tokenization, embedding, HNSW indexing, and similarity scoring automatically. Chroma supports dense vector search via HNSW with configurable distance metrics including L2, cosine similarity, and inner product, sparse vector search using SPLADE, full-text BM25 keyword search, and regex matching, all combinable in hybrid queries through a single unified interface. Metadata filtering at query time uses MongoDB-style operators including $eq, $ne, $gt, $lt, $in, and logical combinators $and and $or, enabling precise result scoping without post-processing. The multimodal pipeline powered by OpenCLIP embeds text and images into a shared vector space, allowing cross-modal retrieval where text queries return relevant images and vice versa. Deployment options range from embedded mode via PersistentClient for notebooks and prototypes, to client-server mode with Docker for production, to Chroma Cloud for serverless scalability. Official Python and JavaScript SDKs provide identical APIs, and embedding function integrations support OpenAI, Cohere, Hugging Face, Google, Ollama, and custom models. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
TencentDB Agent Memory
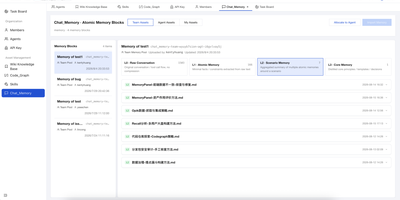
TencentDB Agent Memory provides a team-level memory hub that transforms AI agent conversations, documents, and codebases into four governed, shareable memory assets: Chat Memory for conversation history, Skills extracted from completed tasks, LLM-Wiki built from document ingestion, and Code-Graph generated from codebase analysis. The four-tier semantic pyramid structures long-term memory from L0 raw conversation capture through L1 episodic extraction and L2 scenario aggregation to L3 persona synthesis, enabling hierarchical drill-down via node and result references instead of flat vector recall. The Node.js Gateway sidecar handles capture, extraction, storage, recall, and pipeline scheduling through RESTful HTTP v2 endpoints on port 8420, while the Memory Proxy intercepts Anthropic-format API calls to inject team memory context into Claude Code, CodeBuddy, and other coding agents transparently. Local SQLite with the sqlite-vec extension provides the default storage backend with hybrid BM25 keyword plus vector embedding plus reciprocal rank fusion retrieval requiring zero external API dependencies. Teams manage ownership, versions, status, visibility, usage counts, and agent bindings through the Memory Hub dashboard with role-based access control separating System Admin and team-level Admin and Member permissions. Official TypeScript and Python SDKs provide programmatic access for custom framework integration beyond the built-in OpenClaw plugin and Hermes Agent adapter. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
SigNoz
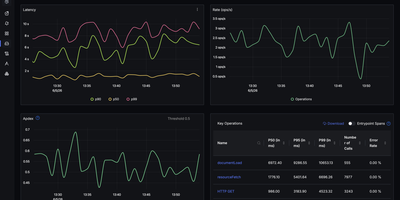
With over 31,000 GitHub stars and native OpenTelemetry support that eliminates vendor lock-in from day one, SigNoz delivers full-stack observability covering metrics, traces, and logs in a single pane of glass without the per-host pricing model of commercial APM platforms. The platform ingests telemetry data through the OpenTelemetry Collector, supporting auto-instrumentation for Java, Python, Node.js, Go, Ruby, PHP, and .NET applications with zero code changes required for basic tracing. ClickHouse serves as the columnar storage backend, providing fast aggregation queries over billions of spans and log lines with configurable retention policies and tiered storage. The distributed tracing view renders flame graphs and Gantt charts showing request flow across microservices with latency breakdowns, error rates, and p99 percentile calculations. Custom dashboards support PromQL and ClickHouse SQL queries with time-series charts, bar graphs, tables, and value widgets. The log management pipeline supports structured and unstructured logs with full-text search, log pipelines for parsing and enrichment, and correlation with traces via trace IDs. Alert rules can be configured on any metric or log query with notification channels including Slack, PagerDuty, OpsGenie, webhooks, and email. The exceptions monitoring module automatically groups and tracks application errors with stack traces, occurrence counts, and first-seen timestamps. Service maps visualize inter-service dependencies with real-time latency and error rate overlays. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed with an enterprise edition available.
Wazuh
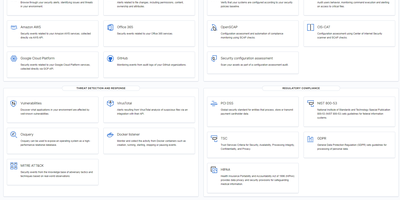
Protecting over 10,000 organizations worldwide with 16,000+ GitHub stars, Wazuh delivers enterprise-grade security operations through a fully open-source platform with zero feature gating. The unified XDR and SIEM solution deploys lightweight agents across Linux, Windows, macOS, Solaris, AIX, and HP-UX endpoints that stream security telemetry to a centralized cluster built on OpenSearch for indexing and the Wazuh Dashboard for visualization and management. Core capabilities include real-time file integrity monitoring with inotify-based detection and who-data attribution, automated vulnerability assessment that correlates software inventories against continuously updated CVE databases, Security Configuration Assessment against CIS benchmarks, rootkit detection, and log data analysis with a rules engine supporting over 3,000 built-in detection rules mapped to MITRE ATT&CK tactics and techniques. Wazuh monitors cloud infrastructure at the API level with native modules for AWS, Azure, and Google Cloud, detects container anomalies through Docker engine integration, and ingests third-party telemetry via syslog and REST APIs from sources like VirusTotal, TheHive, YARA, Suricata, and PagerDuty. Pre-built compliance dashboards and reports cover PCI DSS, HIPAA, NIST 800-53, GDPR, and TSC frameworks. Active response capabilities automatically trigger countermeasures including firewall rule updates, account lockouts, and endpoint isolation when threats are detected. The platform scales horizontally with multi-node clustering for high availability. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-2.0 licensed.
Khoj
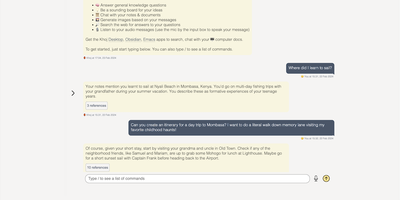
A self-hosted "second brain": Khoj indexes your own files and answers questions from them, parsing Markdown (whole Obsidian vaults included), org-mode, PDF, Word, plain text, Notion pages, GitHub repositories, and images described by a vision model, then embedding everything with sentence-transformers into a vector index for semantic search and RAG with cited sources. Any LLM backend works: local models like Llama, Qwen, or Mistral via Ollama, or cloud models like GPT, Claude, and Gemini. You can build custom agents, each with its own persona, scoped knowledge base, chat model, and tools such as web search and code execution. Scheduled automations run recurring research and deliver newsletters or notifications to your inbox, and research mode performs multi-hop web searches with inline citations. Access it from a browser, the Obsidian plugin, Emacs, desktop, or WhatsApp - all clients connect to the same self-hosted instance, making Khoj one of the few AI assistants Emacs users can point at decades of org files. Semantic search means recall works without exact keywords: "that paper about forecasting with transformers" surfaces the right PDF even when you cannot remember its title. Switching LLM backends never requires re-indexing your documents, and with a local model via Ollama, even inference stays on hardware you control - journals, research, and private notes are never sent anywhere. Python/FastAPI stack, AGPL-licensed, with PostgreSQL storage.
Redmine
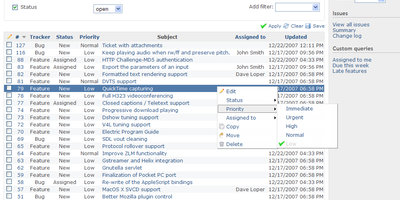
Nearly two decades running engineering organizations: Redmine is the veteran open-source project management and issue tracker, a Ruby on Rails application (GPLv2) still in active development. Its core strength is configurability: define your own trackers (bug, feature, task, or anything else), issue statuses, and role-based workflows that control exactly which transitions each role may perform, then extend records with custom fields of every type. Issues support subtasks, relations (blocks, precedes, duplicates), watchers, categories, and full journaled history, with saved custom queries and cross-project filtering for slicing the backlog any way you need. Around the tracker sit Gantt charts and calendars, a roadmap driven by versions, per-project wikis, forums, news, and document repositories, plus time tracking with estimated versus spent hours and activity-based reporting. Multi-project support runs deep - subprojects, per-project modules, and granular role-based permissions - and repository integration (Git, Subversion, Mercurial) links commits to issues automatically. Email notifications, inbound email-to-issue creation, LDAP authentication, a REST API, and a large plugin and theme ecosystem round it out. Recent 6.x releases brought substantial query and rendering optimizations. Self-hosting keeps your entire project history in your own database, free of per-seat licensing.
Bookstack
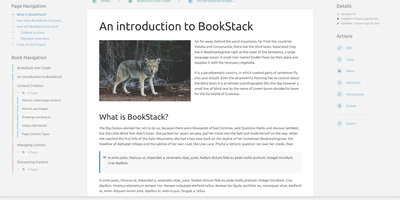
Most wikis die of flat page-and-tag sprawl; BookStack's defining decision is enforced structure - an MIT-licensed PHP/Laravel platform (over MySQL) where content lives in a hierarchy of shelves, books, chapters, and pages, the way a physical library works. A shelf maps to a department, a book to "Engineering Runbooks," a chapter to "Database Procedures," a page to the actual document. That opinionation removes the "where does this go?" friction and keeps knowledge bases tidy as they grow. Editing works both ways: a clean WYSIWYG editor for most users, a Markdown editor with live preview for those who prefer it - switchable per page. Full-text search spans all books or scopes to one, with direct links to individual paragraphs, and include tags let you embed one page's content inside another so shared blocks update everywhere at once. Every edit creates a diffable, revertible revision. Page templates standardize recurring formats, tags add cross-cutting categorization, and built-in diagrams.net integration draws architecture diagrams in place. Authentication covers email/password plus OIDC, SAML2, LDAP, and social login; a full role and permission system locks content down per shelf, book, or page. Pages and books export to PDF, HTML, plain text, and Markdown, a REST API automates content, and the whole thing runs happily on the cheapest VPS you can find.
EverShop
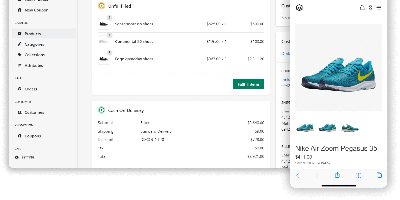
Magento's extensibility without PHP, Shopify's polish without the platform tax: EverShop is the TypeScript-first e-commerce platform built on that promise. Architected as a modular monolith on Node.js, it organizes every piece of business logic - catalog, checkout, customers, your custom extensions - into modules that plug in without touching core code, extended through a disciplined set of mechanisms: registry processors for transforming data across modules, hooks that wrap function calls, async event subscribers (product created, order placed), and route middleware. The storefront and the fully-featured admin panel are both React with server-side rendering and hydration, giving fast first paint and SEO-friendly pages, while a typed GraphQL API (plus REST endpoints) serves exactly the data each view needs - the same API that powers headless and PWA builds. Standard commerce is covered: product management with variants and attributes, category navigation, cart and checkout, order and customer management, coupons, and a theme system built on React components and Tailwind for deep storefront customization. PostgreSQL is the default database, deployment is Docker-friendly with near-zero configuration, and the GPL-3.0 license means the entire stack - types, resolvers, and checkout flow included - is yours to read and modify.
OpenMetadata
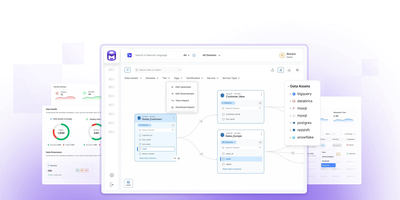
OpenMetadata builds a unified knowledge graph connecting schemas, tables, columns, dashboards, pipelines, ML models, and data products into one searchable catalog accessible at port 8585. The ingestion framework ships 130+ connectors covering Snowflake, BigQuery, Redshift, Databricks, PostgreSQL, MySQL, Kafka, Airflow, dbt, Tableau, Looker, Power BI, Metabase, and Superset, automatically extracting metadata on configurable schedules. Column-level lineage traces data flow across transformations, joins, and aggregations, while built-in data quality testing executes profiling and validation rules as data contracts with automated alerting on failures. Governance features include role-based access control, PII auto-detection, glossary term propagation, and domain-based ownership assignment. The native MCP server and AI SDK expose semantic search, lineage queries, and governance metadata as tools any LLM agent can call, enabling AI systems to discover and reason about enterprise data with full trust context. The architecture requires only PostgreSQL or MySQL plus Elasticsearch, no Kafka, no graph database, and deploys via a single Docker Compose file. Created by the founders of Apache Hadoop, Apache Atlas, and Uber's Databook, the platform has earned over 14,700 GitHub stars and adoption by 3,000+ organizations. Apache 2.0 licensed.
Morphic
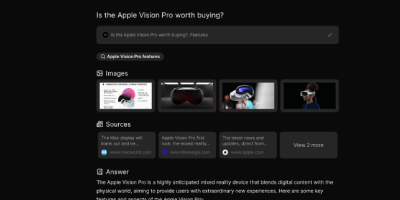
Perplexity's answer-engine experience, self-hostable and open-source: Morphic searches the web and writes cited answers. Instead of returning a list of links, it searches the web, reads the sources, and generates a complete answer with inline numbered citations. The generative UI streams rich components, source cards with thumbnails, image grids, syntax-highlighted code, and LaTeX math, rather than plain markdown. Quick mode answers fast; Adaptive mode runs deeper multi-step research. Search backends are pluggable: the Docker Compose bundle ships with a private SearXNG instance so no search API key is required, and Tavily, Brave, and Exa are supported alternatives. LLM providers include OpenAI, Anthropic, Google, Ollama, and any OpenAI-compatible endpoint, with per-mode model mapping - fast, cheap models for quick searches, stronger models for adaptive research, tuning the cost-quality trade-off per query type. An inspector panel exposes tool execution during multi-step research, and AI-suggested follow-up questions keep an investigation moving. Chat history persists in PostgreSQL, results are shareable by URL, file uploads feed context into queries, and optional Supabase authentication adds multi-user or guest access. Because the default search path is your private SearXNG instance, research topics never hit a commercial search API - and with local Ollama models the marginal cost of a query approaches zero. Built with Next.js, TypeScript, and the Vercel AI SDK under Apache 2.0.
Open SEO
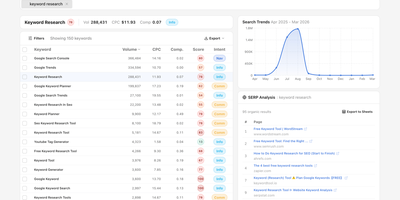
OpenSEO provides an alternative to the $100+/month SEO suite monopoly by connecting directly to DataForSEO APIs on a pay-as-you-go basis — you bring your own API key and pay only for the queries you actually make. The platform delivers focused workflows for keyword research with volume, difficulty, CPC, intent, and live SERP inspection; rank tracking with historical position monitoring; backlink analysis with referring domain quality scoring; technical site audits that crawl pages and surface issues; competitor insights comparing SERP positions across keyword sets; and AI visibility monitoring that tracks brand mentions, citations, and prompts across AI models. The integrated MCP server exposes all tools to AI coding agents including Claude Code, OpenClaw, Hermes, and Cursor, while Agent Skills provide reusable SKILL.md workflows that guide agents through complex SEO research tasks. Google Search Console integration reads first-party performance data including clicks, impressions, CTR, and position metrics with URL-level index status inspection. The Prompt Explorer compares how different AI models respond to SEO-relevant queries. Self-host via Docker for personal use or deploy to Cloudflare for team access with automatic database backups. The hosted version at openseo.so adds a 28% markup on DataForSEO requests. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
LiveKit
With over 20,000 GitHub stars and adoption by companies building everything from telehealth platforms to AI voice agents, LiveKit is the most widely deployed open-source real-time communication server available. The Go-based Selective Forwarding Unit handles hundreds of concurrent participants per node with adaptive bitrate streaming, simulcast layers, SVC codec support for VP9 and AV1, and end-to-end encryption. Client SDKs span JavaScript, Swift, Kotlin, Flutter, React Native, Rust, Python, Unity, and ESP32 embedded devices, while server-side APIs cover Node.js, Go, Ruby, Java, Python, Rust, PHP, and .NET. The Agents framework enables building AI-powered voice and video applications — real-time speech-to-text, LLM-driven conversations, and computer vision pipelines — running as server-side participants in any room. Egress records sessions to S3-compatible storage or streams to RTMP endpoints, while Ingress pulls external feeds from OBS via RTMP, WHIP, or SRT into LiveKit rooms. The SIP bridge connects traditional telephony to WebRTC rooms for hybrid conferencing. JWT-based authentication, webhook notifications, room-level moderation APIs, and selective subscription give operators granular control. Deploy as a single binary for development, Docker Compose for production single-node, or Kubernetes with the official Helm chart for distributed multi-region clusters using Redis for state coordination. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.