Statlite
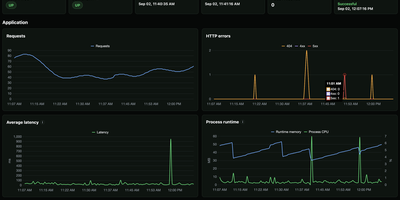
Small server, small monitoring. Statlite watches your applications and their host with a single binary that idles at about 15 MiB, so the observer never becomes the heaviest thing on the box. Point it at a Spring Boot Actuator endpoint and it polls health plus a fixed, curated set of Micrometer metrics: request traffic, latency, CPU, and runtime memory, all drawn as clean charts. Quarkus, Micronaut, and anything else that can answer a fixed JSON metrics profile can join the same dashboard. History lives in one local SQLite file, raw samples only, kept for 90 days by default, so yesterday's latency spike is still there when you go looking. The dashboard also watches the host itself: processor load, memory pressure, and filesystem capacity, including a warning before the metrics database fills its own disk. Restart detection tells you when an application bounced, and per-target Basic Auth support lets you poll protected Actuator endpoints safely. Configuration is one YAML file listing your targets and polling interval, friendly to systemd and Docker alike. Everything is deliberately scoped: no alert manager, no external service, no observability platform to operate. Just open the page and see whether your apps are healthy. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
LaraOwl
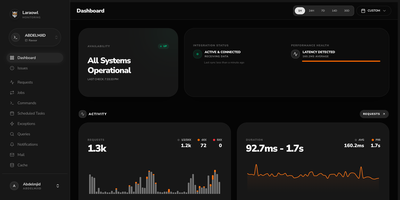
LaraOwl watches your Laravel applications from your own server, streaming every request, exception, slow query, and attack attempt into one live dashboard. Install one Composer package in each app, point it at your LaraOwl server, and requests arrive with method, path, status, duration, and middleware timing attached. Exceptions group themselves by fingerprint with stack traces, occurrence counts, and first and last seen times, so a resolved bug that comes back announces itself. Slow queries and N+1 patterns are flagged with execution times, jobs report failures and retries, and scheduled tasks check in like heartbeats that complain when they stop. A built-in security lens scores threats such as SQL injection, cross-site scripting, and path traversal, tracks hostile IPs, and can push a block into your Cloudflare firewall in one click. Uptime checks run every thirty seconds, alerts fan out to Slack, Discord, Telegram, email, or any webhook, and throttles keep a bad night from becoming a thousand messages. Teams organize multiple projects with their own tokens, thresholds, and retention policies, and daily pruning keeps last quarter's noise from filling the disk. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Pulse
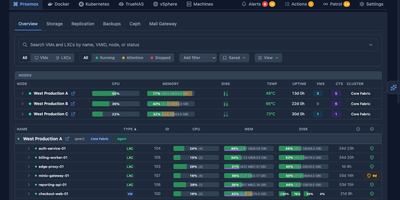
Pulse monitors your entire heterogeneous infrastructure from one screen: Proxmox VE, Proxmox Backup Server, Proxmox Mail Gateway, Docker, Podman, Docker Swarm, Kubernetes, TrueNAS SCALE/CORE, VMware vSphere, and standalone Linux/Windows/macOS machines. The Go binary embeds a SolidJS/TypeScript frontend, delivering WebSocket-driven dashboards with sub-second metric updates on port 7655. A unified agent auto-detects Docker, Podman, Kubernetes, and Proxmox on each host without manual configuration and self-updates silently, while Proxmox nodes need only API credentials with zero agent installation. Smart alerts use adaptive hysteresis-based thresholds to prevent notification floods, pushing to Discord, Slack, Telegram, Teams, email, ntfy.sh, Gotify, and generic webhooks with per-resource overrides. The standout feature is Pulse Patrol: scheduled AI health checks running every ten minutes to seven days using OpenAI, Anthropic, Gemini, or local Ollama models. Patrol catches silent backup failures, capacity creep, restart loops, unhealthy containers, and clock drift that dashboards miss when nobody is watching. Platform-specific views render Proxmox nodes, Ceph clusters, Docker Compose projects, Kubernetes workloads, TrueNAS pools, and vSphere VMs in familiar layouts. OIDC, SSO, and SAML authentication with credential encryption at rest secures access. 6,500+ stars and 441 releases since February 2025. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
HyperDX
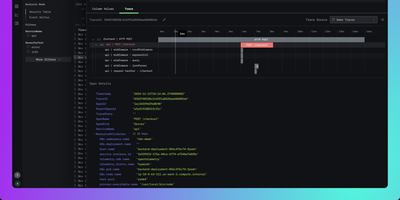
HyperDX correlates logs, metrics, traces, session replays, and errors in a single interface so engineers can resolve production incidents in minutes instead of hours. Nearly 10,000 GitHub stars reflect its role as the integrated UI layer for the ClickStack blueprint endorsed by ClickHouse. The platform connects to any ClickHouse cluster as its storage backend, working with existing table structures without requiring data migration or proprietary ingestion formats. An intuitive Lucene-like search syntax supports full-text queries and property filtering like level:err or service.name:api without needing SQL, while native JSON string querying and event delta analysis surface anomalies in high-cardinality datasets. One-click cross-signal correlation lets you jump from a log line to its distributed trace, from a slow span to associated logs, or from a frontend session replay to the backend errors it triggered. The OpenTelemetry Collector accepts telemetry via OTLP on gRPC port 4317 and HTTP port 4318, supporting automatic instrumentation for Node.js, Python, Java, Go, Ruby, and browser applications. APM tracks HTTP request latency, database query duration, and external service calls with trace waterfall visualizations. Configurable alerts trigger via webhook, Slack, PagerDuty, or email when thresholds are breached. Deploys via Docker Compose with ClickHouse, MongoDB, Redis, and the OpenTelemetry Collector. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Perses
Dashboards stop being screenshots of someone's browser and start being code your team reviews. Perses is an open-source dashboard platform for observability data, displaying Prometheus metrics, Tempo traces, Loki logs, and Pyroscope profiles in one interface, with more datasources arriving through plugins. Teams build dashboards in the visual editor, organising panels into groups with variables that retarget every chart at a new job, instance, or environment; the same dashboards can be written with Go or Cue SDKs, validated in CI, and applied through the CLI or API, so a hundred services keep a hundred consistent dashboards under version control. Projects organise ownership, role-based access controls who can edit what, and authentication connects to the identity provider you already run. Because the dashboard model is an open specification, definitions stay portable instead of locked in one vendor's JSON dialect, and the panel libraries can even be embedded inside your own product's interface. A Kubernetes operator mode stores dashboards as custom resources inside application namespaces, so the team that owns a service owns its dashboard next to its deployment. Time ranges, refresh controls, and explore views make it as useful during an incident as it is as long-lived documentation of how a system behaves. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
LogTide
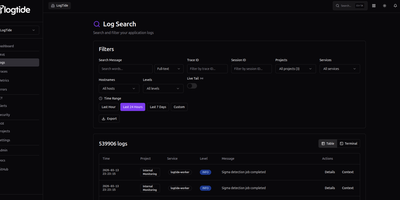
Every production incident starts the same way: someone asks "what do the logs say?" and the answer takes 45 minutes to find. LogTide collapses that search into seconds with a unified observability platform that indexes logs, traces, and metrics into a single queryable interface, backed by your choice of TimescaleDB, ClickHouse, or MongoDB. The log search interface supports full-text queries across millions of entries with filters for trace ID, session ID, project, service, hostname, and severity level, plus a live tail mode that streams new log lines as they arrive. Distributed traces render as waterfall timelines showing every span, its duration, and cross-service dependencies, while correlated logs for each trace are one click away. The metrics explorer visualizes OTLP gauge and counter data from your applications with system CPU, memory, disk, and network panels that update in near real-time. Where LogTide diverges from standard observability is its built-in SIEM engine: Sigma-compatible detection rules scan incoming logs for security threats like SQL injection, privilege escalation, lateral movement, and C2 communication, surfacing findings on a dedicated security dashboard with severity distribution, detection timelines, and affected service breakdowns. Alerting pushes notifications to Email, Slack, or Discord webhooks when thresholds trip or security rules fire. Native SDKs for Node.js, Python, Go, PHP, Kotlin, and Ruby ship logs with retry logic and circuit breakers, and the platform accepts OpenTelemetry data natively. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Sentry
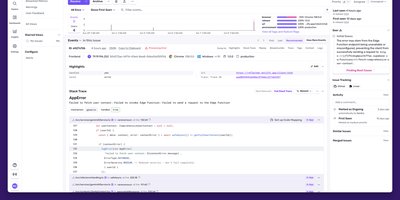
Backed by 44,000 GitHub stars and trusted by over four million developers, Sentry is the debugging platform that captures errors, traces, replays, profiles, and metrics from your applications and connects them all through distributed tracing. The error tracking engine captures full stack traces with source context, breadcrumbs, and automatic demangling for native crashes, while intelligent grouping consolidates duplicate events into actionable issues with regression detection and automatic assignment. Performance monitoring instruments your frameworks automatically, capturing every database query, API call, cache hit, and queue operation as spans within distributed traces that flow across frontend, backend, and mobile boundaries. Session Replay produces video-like recordings of real user sessions showing DOM interactions, network requests, console messages, and errors on a synchronized timeline, with AI-powered summaries that describe what happened without watching the full replay. Continuous profiling captures CPU execution data at the function and line level for Node.js, Python, iOS, and Android, linking slow spans directly to the exact code responsible. Cron monitoring tracks scheduled jobs for failures, missed runs, and duration anomalies. The alerting engine fires notifications through Slack, PagerDuty, Opsgenie, and webhooks on new issues, regressions, error spikes, or when latency and crash-free session rate thresholds are crossed. Self-hosted deployment runs as a Docker Compose stack with PostgreSQL, ClickHouse, Kafka, Redis, and Relay. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. FSL licensed.
Apache SkyWalking
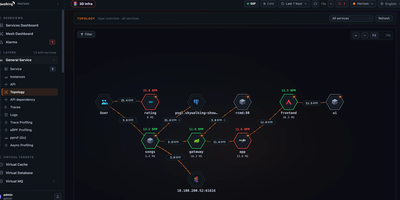
An open-source application performance monitoring platform for microservices, Kubernetes, and service meshes, Apache SkyWalking draws the live service map and ties slow requests to their traces, logs, and metrics. Agents cover Java, .NET Core, PHP, Node.js, Go, Lua, Rust, C++, browser JavaScript, and Python, and OpenTelemetry, Zipkin, Prometheus, Zabbix, and Telegraf data can be ingested too. Start at the service topology map, follow a request through the trace waterfall, then drill into the instance and its API dependencies. When the cause is inside the code, trace profiling, async-profiler, Go pprof, eBPF, and network profiling render flame graphs and process graphs in the same console. The Rover eBPF agent profiles Kubernetes workloads for CPU and network problems, and Istio and Envoy service meshes, including Istio Ambient, report into the same dashboards. Alarm rules target a service, deployment, or API, and alarms and telemetry can be forwarded to third-party systems. Metric and log analysis rules hot-update at runtime without a restart, and a live debugger shows what each rule stage receives and produces. An AI assistant answers plain-language questions with charts, topology, and traces from live data, using an OpenAI-compatible or Amazon Bedrock model you configure, and an MCP connection serves your own AI client. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
OpenObserve
With 20,500+ GitHub stars and over 6,000 organizations running it in production — including a Fortune 100 company ingesting more than 4 PB per day — OpenObserve is the open-source observability platform that replaces your entire Datadog, Splunk, or ELK stack with a single Rust binary deploying in under two minutes. Apache Parquet columnar storage with zstd compression on S3-compatible object storage delivers 140x lower storage costs than Elasticsearch while providing better query performance on a quarter of the hardware. Ingest logs, metrics, and distributed traces via native OpenTelemetry OTLP endpoints with no vendor lock-in. Query logs and traces with standard SQL, metrics with SQL or PromQL — no proprietary query language to learn. The built-in dashboard builder offers 19 chart types including time-series graphs, heatmaps, gauges, tables, and top-K lists with drag-and-drop layout combining data from all signal types. Data pipelines process, enrich, redact, or normalize ingestion streams using Vector Remap Language for real-time transformations including PII redaction and logs-to-metrics conversion. Real User Monitoring captures frontend performance with session replay. The Service Catalog provides topology-based trace analysis with side-panel drill-downs into database queries and error details. Alerting supports real-time and scheduled rules with SQL and PromQL conditions. Native multi-tenancy isolates organizations and streams with complete data separation. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Karma
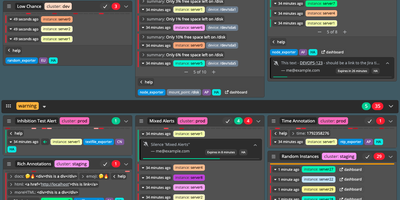
When an alert fires on any of your Prometheus Alertmanagers, Karma shows it once, on one filterable dashboard, and lets you acknowledge or silence it from there. Identical alerts from different servers merge into one entry tagged with every server that saw it, HA pairs included. Groups follow the group_by settings of your Alertmanager routes, and shared labels and annotations collapse into a footer. Multi-grid mode gives each value of a label, or each Alertmanager, cluster, or receiver, its own grid, keeping production and staging apart. Configurable label colors make hosts and severities easy to spot. Optional history draws 24 hourly blocks per group from the Prometheus servers that fired it, and an inhibited alert's muted button lists whatever is suppressing it. One click acknowledges an alert with a short-lived silence, and the separate kthxbye daemon can keep extending it until the alert resolves. The silence modal creates, edits, and expires silences, and ticket IDs in comments can become links. A Dead Man's Switch check raises a visible error when the alerting pipeline goes quiet. Basic auth or a proxy's header identifies each user, silence ACLs stop one team from silencing another's alerts, and read-only mode disables silence management. Default filters open the view your team triages first, and light and dark themes follow the browser. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Coroot
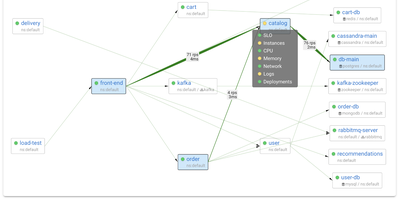
Coroot uses eBPF to capture metrics, distributed traces, logs, and continuous CPU profiles directly from the Linux kernel, delivering full observability without any application code changes, SDKs, or sidecars. From the first minute of deployment, an automatically generated service map covers every microservice, database, message queue, and external dependency with request rate, error rate, and latency measurements. When a service breaches its SLO, AI-powered inspections analyze telemetry across all dimensions to pinpoint the root cause and send a single consolidated alert with findings, replacing the flood of fragmented notifications typical of traditional monitoring. Deployment tracking automatically discovers Kubernetes rollouts and compares each release against the previous one to detect performance regressions, resource spikes, and cost impacts without CI/CD pipeline integration. Continuous profiling captures CPU flame graphs down to the line of code with negligible overhead. Integrated cost monitoring tracks cloud spending across AWS, GCP, and Azure, attributing expenses to individual services and deployments. Coroot supports Prometheus, OpenTelemetry, and ClickHouse as data sources and works identically on Kubernetes clusters, virtual machines, and bare-metal hosts. 7,700+ GitHub stars. Apache-2.0 licensed.
Zabbix
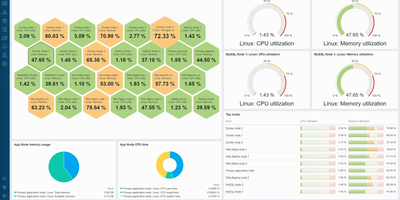
Monitoring everything from network switches to Kubernetes clusters since 2001 with over 6,200 GitHub stars and deployments exceeding 100,000 devices per installation, Zabbix has established itself as one of the most mature and feature-rich open-source monitoring platforms available, trusted by organizations including Dell, Salesforce, ICANN, and T-Mobile. The platform collects metrics from virtually any source using Zabbix Agent written in C, Zabbix Agent 2 written in Go with native plugin support, SNMP v1/v2c/v3 polling and trapping, IPMI for hardware health, JMX for Java applications, SSH and Telnet checks, HTTP/HTTPS polling, and ODBC database queries. Version 7.0 LTS introduced synthetic browser monitoring that executes user-defined JavaScript via WebDriver to simulate multi-step user interactions on websites, proxy load balancing with automatic host redistribution across proxy groups for high availability, in-memory proxy data buffering delivering up to 100x performance improvement, native multi-factor authentication with TOTP and Duo support, and just-in-time user provisioning from SAML and LDAP. Low-level discovery automatically detects file systems, network interfaces, SNMP OIDs, VMware resources, and Kubernetes pods, creating monitoring items and triggers dynamically. The alerting engine correlates events with configurable escalation chains, sending notifications through Slack, Microsoft Teams, PagerDuty, Jira, email, and SMS with customizable message templates. Over 1,000 official templates provide instant monitoring for Linux, Windows, VMware, AWS, Azure, Docker, PostgreSQL, MySQL, Apache, Nginx, and hundreds more. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
ContainerFlow
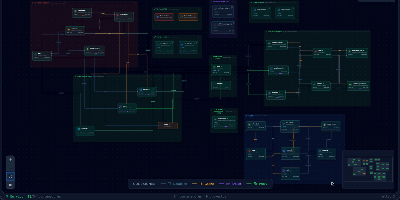
Your database container is probably not at 98 percent memory, whatever docker stats claims, because most of that figure is reclaimable page cache; ContainerFlow subtracts the full cache and shows the memory your containers actually hold. Point it at a Docker socket and it draws the whole estate as a living map: every Compose project discovered automatically, services grouped and colour coded, and the connections between them inferred, app to database, proxy to app, worker to broker. CPU and memory refresh every three seconds, the graph flashes when a container starts, stops, or restarts, and seven days of metric history wait in a local store when you need to know what happened overnight. Click any node and a detail panel opens with live logs you can filter by stream, an inline terminal that runs commands inside the container, and buttons to start, stop, restart, rebuild, recreate, or remove it. The same panel teaches as it works, flagging containers that run with no memory limit, no CPU limit, or no restart policy, while Discord webhooks fire when a container you care about crosses a threshold you set. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Traceway
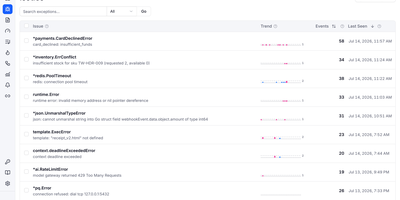
Production debugging slows to a crawl when logs, distributed traces, metrics, and session replays live in four disconnected dashboards, which is why Traceway consolidates every OpenTelemetry signal into a single self-hosted observability platform. Point any standard OTLP exporter directly at the ingestion endpoints without maintaining an intermediary collector or installing proprietary vendor SDKs. When an unhandled exception fires in production, automatic SHA-256 stack trace fingerprinting groups duplicates into prioritized issues complete with source-mapped frames and attached browser or Flutter session replays showing exact user clicks before the crash. Clicking any structured log entry jumps straight to its corresponding distributed span waterfall so engineers can trace slow database queries or failing downstream HTTP calls across microservices. Route performance bottlenecks surface immediately through per-endpoint P50, P95, and P99 latency percentiles ranked by Apdex and a five-factor impact score. Teams shipping AI features can also inspect LLM token consumption, model costs, tool calls, and multi-turn conversations grouped by customer identifier. Built-in on-call rotation schedules, escalation policies, and multi-channel alerts via Slack, Telegram, Pushover, email, and webhooks ensure incidents reach the right responder with one-click acknowledgment links. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Radar
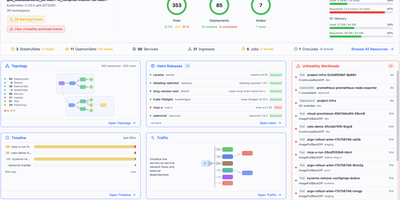
Radar is an open-source Kubernetes management dashboard and Model Context Protocol server that gives engineering teams complete cluster visibility, automated issue diagnosis, and GitOps controls through a unified web interface. Operators explore live interactive cluster topology maps rendered with automated layout engines, grouping workloads by namespace or custom application labels to trace network communication pathways. The unified event timeline retains Kubernetes activity and state change diffs well beyond default one-hour limits, allowing site reliability engineers to diagnose historical CrashLoopBackOff states and investigate failed deployment rollouts. Teams manage Helm releases by inspecting deployed values, comparing manifest revisions side by side, and initiating rollbacks or upgrades with a single click. The built-in GitOps workspace correlates ArgoCD and Flux applications, surfacing synchronization health, field-level configuration drifts, and automated remediation suggestions. Developers inspect container image filesystems directly from pod detail panels without pulling images locally or establishing interactive terminal sessions, browsing permissions and downloading specific files. Native Model Context Protocol endpoints expose cluster telemetry and operational tools to artificial intelligence coding assistants, enabling external agents to diagnose failing pods and inspect access controls securely. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
ClickStack
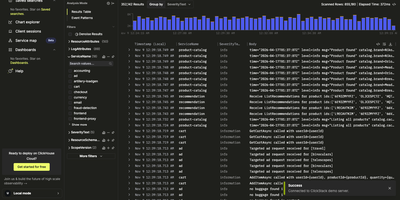
ClickStack is an open-source observability platform that unifies logs, metrics, traces, session replays, and errors in one searchable interface, so engineers can move from an alert to the exact request that broke in minutes. Search uses an intuitive full-text and property syntax (for example level:err), with SQL available when a question needs full analytical power. Live tail streams fresh logs and traces as they arrive, and event deltas surface anomalies by comparing current behavior against earlier windows. Dashboards chart high-cardinality events without a complex query language, and alerts can be created in a few clicks from any search or chart. Session replays connect a user's browser experience to the backend traces and database queries behind it, giving full-stack visibility from click to query. Native JSON string querying handles nested payloads, and the schema-agnostic design works on top of an existing ClickHouse schema instead of forcing a new one. OpenTelemetry is supported out of the box, with SDKs and collectors for Kubernetes, JavaScript, Python, Java, Go, Ruby, PHP, .NET, Elixir, and Rust. The all-in-one Docker image bundles the interface, ClickHouse, the OpenTelemetry Collector, and supporting services on port 8080, and a terminal CLI serves engineers who prefer the shell. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Overlook
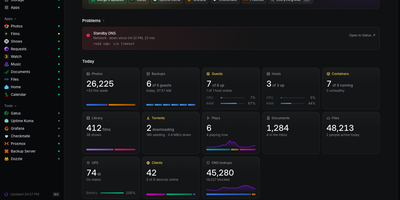
Overlook is a read-only status page that tells you at a glance whether your whole homelab is healthy, by pulling live answers from the monitoring, server, network, storage, and media tools you already run. The page leads with what is wrong, listing the checks your existing check engine is alerting on for as long as they fail, so the page and your alerts never disagree. Below that sit Servers, Network, Storage, and Apps, each marked up, degraded, or down with the last 30 results of its checks and its own detail page showing guests, DNS clients, or disk detail. A Today strip gives one figure from every source, such as guests running, DNS lookups, photos added, or the watts your UPS is drawing, while a weekly view lists each area's problems and events across the last seven days. Your apps appear as links with a dot that says whether each one answers, and chores due this week, waiting updates, batteries to change, and requests awaiting approval collect in one place you act on in the tool itself. A browser setup page appears before any config exists, tests each source you enter, and writes the config and secrets files for you. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Kula
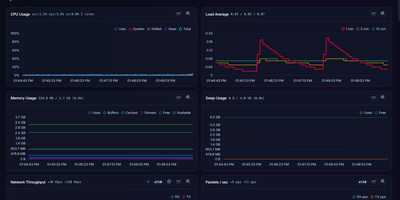
Kula watches a Linux server every second and turns CPU, memory, disks, network, containers, and applications into a live dashboard you can open before trouble becomes downtime. Follow total and per-core CPU, load averages, memory and swap pressure, disk I/O, filesystem space, temperatures, GPU load, and network throughput as charts update live in the browser. Drag to zoom into history, switch to focus or TV mode for a wall display, and check the System Info page when you need the hardware story behind a spike. Watch Docker, Podman, and cgroup containers beside host metrics, then add PostgreSQL, MySQL or MariaDB, nginx, and Apache monitoring or define custom metrics for the odd service only your team understands. Scrape the Prometheus endpoint into an existing observability stack, open the terminal UI over SSH for a quick live read, or ask the optional local Ollama assistant to discuss charts without sending data to a cloud service. Protect the dashboard with optional Argon2id logins and multiple users, schedule storage snapshots, and keep the whole tool working on closed networks with no external calls. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.