Grafana
The de facto dashboard of observability: Grafana is the open-source frontend that turns the data stores you already run into interactive graphs. It does not store metrics itself; it connects to the data stores you already run and turns their contents into interactive dashboards. Supported sources number over 150 via plugins: Prometheus, Loki, Tempo, InfluxDB, Elasticsearch, MySQL, PostgreSQL, Microsoft SQL Server, AWS CloudWatch, Azure Monitor, Google Cloud Monitoring, and many more. Dashboards are built from a large library of panel types (time series, heatmaps, tables, gauges, logs) with template variables for reusable, parameterized views. Unified alerting evaluates rules against any connected data source, not just Prometheus, and routes notifications to Slack, PagerDuty, email, and other channels with grouping and silencing - unlike Prometheus Alertmanager, a single rule can combine a Loki log pattern, a PostgreSQL query result, and a CloudWatch metric. Dashboards serialize to JSON and data sources configure via provisioning files, so the entire observability setup can live in Git and deploy repeatably across environments. Explore mode adds ad-hoc querying outside dashboards, with split view for correlating a metric spike against the matching log lines, and access control spans organizations, teams, folder permissions, and OAuth, LDAP, and SAML integration. Written in Go and TypeScript, AGPL-licensed. Self-hosting gives you unlimited users, dashboards, and queries at flat hosting cost, without Grafana Cloud's usage-based pricing.
Pulse
Pulse monitors your entire heterogeneous infrastructure from one screen: Proxmox VE, Proxmox Backup Server, Proxmox Mail Gateway, Docker, Podman, Docker Swarm, Kubernetes, TrueNAS SCALE/CORE, VMware vSphere, and standalone Linux/Windows/macOS machines. The Go binary embeds a SolidJS/TypeScript frontend, delivering WebSocket-driven dashboards with sub-second metric updates on port 7655. A unified agent auto-detects Docker, Podman, Kubernetes, and Proxmox on each host without manual configuration and self-updates silently, while Proxmox nodes need only API credentials with zero agent installation. Smart alerts use adaptive hysteresis-based thresholds to prevent notification floods, pushing to Discord, Slack, Telegram, Teams, email, ntfy.sh, Gotify, and generic webhooks with per-resource overrides. The standout feature is Pulse Patrol: scheduled AI health checks running every ten minutes to seven days using OpenAI, Anthropic, Gemini, or local Ollama models. Patrol catches silent backup failures, capacity creep, restart loops, unhealthy containers, and clock drift that dashboards miss when nobody is watching. Platform-specific views render Proxmox nodes, Ceph clusters, Docker Compose projects, Kubernetes workloads, TrueNAS pools, and vSphere VMs in familiar layouts. OIDC, SSO, and SAML authentication with credential encryption at rest secures access. 6,500+ stars and 441 releases since February 2025. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
VictoriaMetrics
Trusted by thousands of organizations processing billions of time series data points and backed by 17,000+ GitHub stars, VictoriaMetrics delivers a monitoring and time series database that outperforms Prometheus by 16x on query speed while consuming 2.5x less disk space through its optimized compression and storage engine. The architecture supports both single-node deployments handling 10M+ active time series and a horizontally scalable cluster version with vminsert, vmstorage, and vmselect components providing multi-tenancy, replication, and independent namespace isolation. Data ingestion accepts both push protocols including InfluxDB line protocol, Graphite plaintext, OpenTSDB HTTP, CSV, and OpenTelemetry OTLP alongside pull-based Prometheus scraping and remote write, enabling drop-in replacement of existing monitoring stacks without reconfiguring exporters. MetricsQL extends standard PromQL with additional functions, subqueries, and implicit time range alignment while maintaining full backward compatibility with existing Prometheus alerts and Grafana dashboards. The vmalert component processes recording and alerting rules with Alertmanager integration, while vmbackup and vmrestore enable point-in-time snapshots to S3, GCS, and Azure Blob Storage. Stream aggregation operates as a StatsD alternative for pre-aggregating high-cardinality metrics before storage. NFS-compatible storage backends including Amazon EFS and Google Filestore allow shared persistent volumes across cluster nodes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Parca
A flight recorder for production code, Parca profiles CPU and memory continuously and keeps the history to query after something breaks. A slow memory leak or a momentary CPU spike is already on record by the time anyone looks. Point it at any service that exposes pprof endpoints, or deploy the eBPF-based Parca Agent to profile every process on a Linux host or Kubernetes node without touching application code. The agent covers C, C++, Rust, Go, and more. In the web UI, pick a profile type such as on-CPU, narrow it with Prometheus-style label selectors, sum or group by any label, and click a point on the time series to open its flame graph. Switch the same query to a table, add extra panels, or try the alpha Flame Chart and Sandwich views. After a deploy, open the Compare page, set two queries side by side by label or time range, and the functions that gained or lost CPU time stand out as a diff. Native binaries are symbolized from uploaded debuginfo or upstream debuginfod servers. Recent releases add support for OpenTelemetry eBPF profiler profiles and GPU profile types. Optional persistence keeps history across restarts, and a Prometheus-style scrape configuration with service discovery decides what gets profiled. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Nightingale
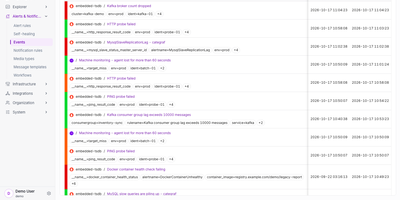
When a query crosses its threshold, Nightingale, a self-hosted alerting engine, decides who hears about it and how, without moving data out of the stores you already run. Rules use PromQL, log queries, or SQL against Prometheus, VictoriaMetrics, Elasticsearch, Loki, ClickHouse, MySQL, or PostgreSQL, graded S1, S2, or S3 with a for-duration that absorbs brief spikes. Existing Prometheus alert rules import from YAML. Business groups give each team its own rules and dashboards, and sign-in works through OIDC, OAuth2, LDAP, or CAS. Once a rule fires, mute rules silence the noise, subscriptions add recipients, and event pipelines rewrite labels or route conditionally. Delivery reaches Slack, PagerDuty, Discord, Telegram, Jira, email, DingTalk, Feishu, WeCom, SMS, and voice calls, plus HTTP webhooks and scripts for anything else. Evaluation records, active and historical events, and notification results show what happened at each step. If an alert misbehaves, the built-in AI agent explains why it fired or never arrived, and it drafts rules, dashboards, and mutes from plain-language requests. Claude Code, Cursor, and other MCP clients can query alerts and manage alerting through /mcp, read-only by default and bound by the caller's own permissions. At remote sites, n9e-edge keeps evaluating and notifying when the link to the center drops. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.

LobsterBoard
LobsterBoard lets you assemble custom monitoring dashboards from 50 pre-built widgets using a visual drag-and-drop editor, covering everything from CPU and memory gauges to AI subscription trackers, stock tickers, and camera feeds on your own server with zero cloud dependencies. The snap-grid editor handles layout composition with resize handles and a property panel, so you drag widgets onto a canvas, configure their data sources, and the dashboard is live. Real-time system statistics flow through Server-Sent Events, updating CPU load, memory pressure, disk usage, network throughput, and Docker container status without page refreshes. Five built-in themes range from a dark default to a retro CRT terminal aesthetic, a warm sepia paper look, and pastel options for different display environments. The template gallery lets you export complete dashboard layouts with auto-captured screenshot previews, share them with other users, and import configurations as a full replacement or selective merge. Custom pages extend beyond dashboards into notes, kanban boards, or any free-form layout you need. Built-in widgets connect to iCal feeds for calendar events, RSS sources for news aggregation, weather APIs for local conditions, and financial data providers for cryptocurrency and stock prices. The whole system runs from a single server.cjs file with zero cloud dependencies or external frameworks. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSL-1.1 licensed (free for non-commercial use; converts to MIT in 2030).
Rootprint
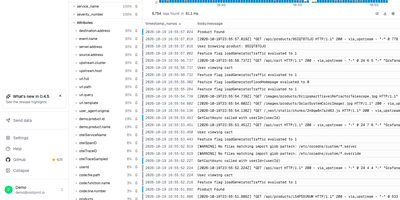
A year of searchable logs and traces no longer needs a metered logging service, because Rootprint keeps the whole index in a storage bucket you already own. A search matches any word on any line, since every log is indexed in full and no service name, stream, or label is needed first. A frequency histogram, one-click field filters, and saved views narrow the results, a fold mode collapses repeated lines, and exports arrive as NDJSON, CSV, or plain text, or as a share link. Open a trace from the log that emitted it, or paste a trace ID, and a waterfall shows per-span timing, attributes, events, and database calls grouped by query, with each span linking back to its logs. The trace explorer charts span volume, error rate, and p50, p95, and p99 latency, ranks the busiest operations, and filters spans by service, duration, and status. Every service gets its own page with request rate, error rate, operations, dependencies, and errors. Data arrives over OpenTelemetry from the Collector, Vector, or Fluent Bit, through a plain HTTP gateway, or by pulling from Kafka, Kinesis, or SQS, with guided setup for nine integrations. Indexes can live in S3, Google Cloud Storage, R2, MinIO, or Azure Blob. Teammates sign in with Google, GitHub, or any OpenID Connect provider, and scoped API keys serve scripts. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Karma
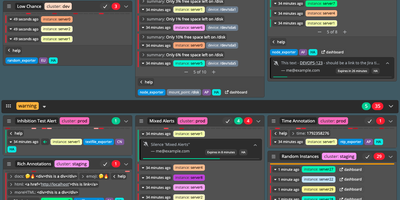
When an alert fires on any of your Prometheus Alertmanagers, Karma shows it once, on one filterable dashboard, and lets you acknowledge or silence it from there. Identical alerts from different servers merge into one entry tagged with every server that saw it, HA pairs included. Groups follow the group_by settings of your Alertmanager routes, and shared labels and annotations collapse into a footer. Multi-grid mode gives each value of a label, or each Alertmanager, cluster, or receiver, its own grid, keeping production and staging apart. Configurable label colors make hosts and severities easy to spot. Optional history draws 24 hourly blocks per group from the Prometheus servers that fired it, and an inhibited alert's muted button lists whatever is suppressing it. One click acknowledges an alert with a short-lived silence, and the separate kthxbye daemon can keep extending it until the alert resolves. The silence modal creates, edits, and expires silences, and ticket IDs in comments can become links. A Dead Man's Switch check raises a visible error when the alerting pipeline goes quiet. Basic auth or a proxy's header identifies each user, silence ACLs stop one team from silencing another's alerts, and read-only mode disables silence management. Default filters open the view your team triages first, and light and dark themes follow the browser. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Pyrra
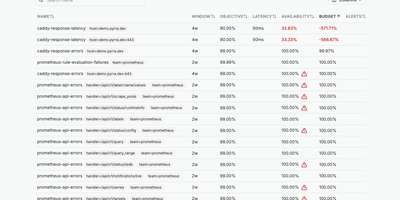
Define a service level objective in a few lines of YAML and Pyrra writes the Prometheus recording rules and multi-window burn rate alerts for it, then tracks the remaining error budget in a web interface. An objective can be an error ratio or a latency target, declared as a Kubernetes custom resource or as a plain file read from disk when running under Docker or as binaries. Grouping labels fan one definition out into an objective per route or handler. The objectives page lists each SLO with its window, target, availability, and remaining budget, sorted so the worst offenders sit on top; columns can be sorted or hidden, and a search box or a click on any label filters the list. Opening an objective highlights availability and error budget, plots the budget over time, and charts requests, errors, and duration with a time range picker and absolute or relative scales. Below the charts, a table shows the four generated alerts with their severities. Generated alerts carry a link back to the objective's page, and severities can be overridden in the spec. Queries go to Prometheus, Thanos, or Mimir, with basic auth, bearer tokens, or tenant IDs, and ready-made Grafana dashboards chart the same objectives. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Chartbrew
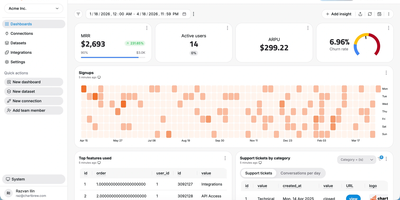
Chartbrew transforms raw database queries and API responses into polished, shareable dashboards without requiring a data engineering team. Connect to MySQL, PostgreSQL, MongoDB, Firestore, or any REST API, then build datasets using the visual query editor with syntax highlighting and auto-completion. Charts render through Chart.js with line, bar, pie, donut, radar, polar, KPI card, and table visualizations, each customizable with colors, legends, filters, and goal indicators. An AI assistant accelerates dashboard creation by generating queries and suggesting chart configurations from natural language descriptions of the metrics you want to track. Reusable datasets let teams prepare data transformations once and share them across multiple charts, while automatic scheduling through BullMQ and Redis refreshes data at intervals from every 10 minutes to monthly. The embed feature generates standalone chart URLs for insertion into external websites, internal tools, or customer portals, and the Reporting API enables programmatic dashboard management and automated report delivery. Team workspaces with role-based permissions control who can view, edit, or manage data connections. Nearly 4,000 GitHub stars reflect steady community adoption. The platform runs on Node.js with Express and Sequelize ORM, supporting MySQL or PostgreSQL as its application database. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. FSL-1.1-MIT licensed (converts to MIT two years after each release).