Promptfoo
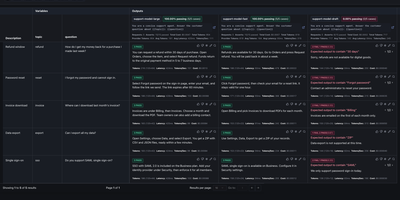
Promptfoo replaces vibes-based prompt tweaking with measurable tests, then attacks your AI app the way a hostile user would. An evaluation matrix lines up every prompt and model side by side, with pass or fail badges, assertion messages, latency, token counts, and cost in each cell. A red team wizard walks through the target, application details, plugins, and strategies, then probes for prompt injection, data exposure, broken access control, and harmful content. Preset bundles map plugins to the OWASP LLM Top 10, NIST AI RMF, MITRE ATLAS, GDPR, ISO 42001, and the EU AI Act. Meta Agent and Hydra Multi-Turn strategies adapt attacks across a whole conversation instead of firing one-shot prompts. Providers span OpenAI, Anthropic, Gemini, Bedrock, Azure, and local Ollama models, and any HTTP endpoint, Python script, or JavaScript function can be tested as a target. The history page lists every run with pass rates and raw scores, and prompt and dataset pages show which templates and test sets each run used. A provider allowlist file narrows the models offered in the web editor for cost control. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Apache Airflow
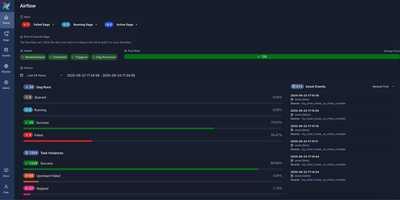
With over 46,000 GitHub stars and one of the largest communities in data engineering, Apache Airflow is the workflow orchestration platform that lets teams define, schedule, and monitor complex data pipelines as Python code through directed acyclic graphs. Airflow 3.x introduced a modernized architecture with a task execution API, the Language Task SDK for writing task implementations in Java and Go alongside Python, asset-based partitioning with FanOutMapper and FixedKeyMapper for data-driven scheduling, a first-class state store for tasks and assets, pluggable retry policies, and a redesigned React-based web UI built on FastAPI. The provider ecosystem ships 80+ packages covering AWS, Google Cloud, Azure, Snowflake, Databricks, Apache Spark, Apache Kafka, PostgreSQL, MySQL, MongoDB, Slack, HTTP, SSH, Docker, Kubernetes, and dozens more, enabling a single deployment to orchestrate jobs across multi-cloud and on-premises infrastructure. The scheduler supports cron expressions, timetable plugins, data-aware scheduling triggered by asset events, and dynamic task generation through Python loops and conditionals. Built-in operators include BashOperator, PythonOperator, DockerOperator, KubernetesPodOperator, and sensor operators that poll external systems. The web UI provides DAG visualization with Gantt charts, grid views, and graph views, task instance logs, SLA monitoring, connection and variable management, and role-based access control. Deployment options include standalone mode, Docker Compose with CeleryExecutor or KubernetesExecutor, Helm charts for Kubernetes, and managed cloud services. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache License 2.0 licensed.
RisingWave
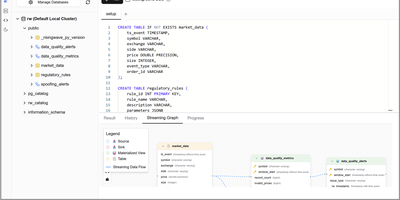
With over 9,100 GitHub stars and production deployments powering real-time analytics at companies like SHOPLINE where it reduced API latency by 76.7%, RisingWave is the PostgreSQL-compatible streaming database that collapses the traditional Debezium-plus-Kafka-plus-Flink-plus-serving-database stack into a single Rust-powered system. The platform continuously ingests data from PostgreSQL and MySQL via native CDC connectors that eliminate Debezium middleware, consumes Kafka, Redpanda, Pulsar, and Kinesis topics, accepts webhook events from SaaS applications, and batch-loads historical data from S3 and data warehouses. Standard SQL defines sources, materialized views, and sinks — no new DSL, no Java, and no custom API — while the PostgreSQL wire protocol means psql, DBeaver, pgAdmin, Grafana, Metabase, Superset, Tableau, and every PostgreSQL client library works without modification. Materialized views are incrementally maintained as events arrive, delivering point lookups in single-digit milliseconds without recomputing aggregates from scratch. For long-term retention, RisingWave writes to Apache Iceberg tables with a hosted REST catalog and automated table maintenance including compaction, small-file optimization, and snapshot cleanup, with data queryable by Spark, Trino, DuckDB, and DataFusion. The disaggregated compute-storage architecture uses S3-based state management for elastic scaling, instant failure recovery measured in seconds rather than the minutes-to-hours typical of RocksDB-based systems, and cost-efficient storage tiering. An MCP server enables AI agents to query and operate RisingWave directly. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Memory OS
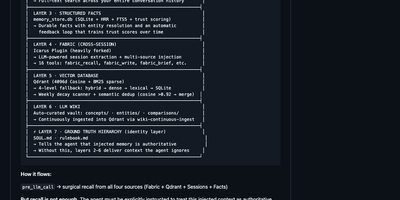
Memory OS gives Hermes Agent a permanent memory, so a new session opens with your projects, decisions, and working style already in context instead of introductions. Seven layers divide the job: workspace files carry your standing instructions into every turn, and a full-text index makes every past conversation searchable in place. Durable facts about your stack, your projects, and your patterns live in a structured store that resolves entities and scores how much each fact can be trusted, promoting what proves itself and demoting what does not. Cross-session recall pulls relevant moments from older threads, while a vector store with hybrid dense and keyword search finds the right memory even when the wording has changed. A self-curating wiki turns raw material into concept, entity, and comparison pages that are re-ingested automatically, and a Ground Truth hierarchy tells the agent to treat injected memories as authoritative instead of re-checking them. Scheduled jobs keep the system honest: hourly ingestion, weekly curation and decay scans, dead-letter reporting, and health heartbeats. It all runs beside the agent on your own machine with whichever provider you already use, from OpenRouter and Anthropic to a local Ollama. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Opik
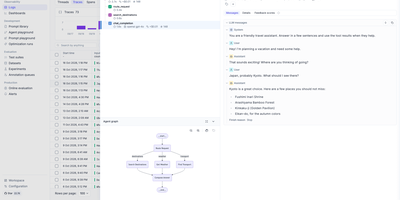
When an AI agent goes wrong at step seven of twelve, Opik, an open-source LLM observability platform, shows the exact trace, tool call, and prompt behind it, then scores your fix against test datasets. Full trace trees capture every LLM call, retrieval step, and tool execution, and you can annotate traces and spans with feedback scores in the UI or through the SDK. Native integrations for OpenAI, Anthropic, LangChain, LlamaIndex, CrewAI, Google ADK, and DSPy, plus OpenTelemetry for any language with an OpenTelemetry SDK, feed traces in, or add the @track decorator to your own functions. Datasets and experiments compare prompt and model versions, scored by LLM-as-a-judge metrics for hallucination, moderation, and RAG relevance, with a PyTest integration to run evaluations in CI. A Prompt Playground tests prompts across models, and the Agent Optimizer SDK helps improve prompts and agents. Production dashboards track feedback scores, trace counts, and token usage, online evaluation rules score live traces, and optional guardrails add safety checks. An MCP server lets Claude Code, Cursor, VS Code Copilot, Codex, or opencode read traces and run evaluations from chat. Run it yourself with the ./opik.sh script on Docker Compose, or a Helm chart on Kubernetes, so trace data stays in your infrastructure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Langfuse
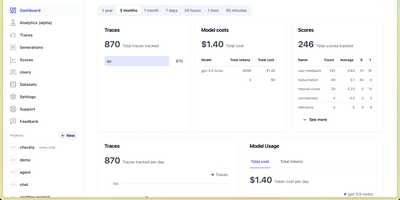
Backed by Y Combinator and trusted by over 2,300 companies processing billions of observations monthly, Langfuse is the most widely adopted open-source platform for building, monitoring, evaluating, and debugging LLM applications. The hierarchical tracing engine captures every LLM call, tool invocation, retrieval step, and agent action as nested spans based on OpenTelemetry, with automatic cost calculation, latency tracking, and token usage attribution across sessions and users. Prompt Management separates prompts from code with versioned artifacts, label-based deployments, one-click rollbacks, and runtime SDK fetching with server-side caching, while linking every generation back to its exact prompt version for attribution analytics. The evaluation system supports LLM-as-a-judge scoring, heuristic code evaluators, user feedback collection, and manual annotation workflows that run automatically on production traces or against curated datasets. The Playground enables interactive prompt testing on real production inputs with side-by-side model comparison across providers. Datasets and Experiments define test cases for systematic benchmarking with comparative result visualization. Native SDKs for Python and TypeScript provide decorator-based instrumentation, while 100+ integrations cover LangChain, LlamaIndex, OpenAI SDK, LiteLLM, Vercel AI SDK, and any OpenTelemetry-instrumented framework. The analytics dashboard surfaces cost breakdowns, quality scores, latency percentiles, and usage trends across models and prompt versions. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Agenta
Agenta delivers a comprehensive open-source LLMOps workspace that covers the full lifecycle of AI application development — from prompt engineering through production monitoring. The platform supports 15+ model providers including OpenAI, Anthropic, Google Gemini, Mistral, Groq, Together AI, Azure, AWS Bedrock, and self-hosted models via Ollama, enabling teams to switch between providers without code changes. The prompt playground allows side-by-side comparison of different configurations, while the evaluation system offers LLM-as-a-Judge assessment, 20+ pre-built evaluators covering semantic similarity, regex matching, and factual accuracy, plus custom Python evaluators for domain-specific requirements. Teams run evaluations through both the web UI for subject matter experts and the Evaluation SDK for programmatic CI/CD integration. The observability layer captures full trace visibility across complex agentic workflows, flagging quality issues like hallucinations and off-topic responses in real time. Human annotation workflows let domain experts review and annotate LLM outputs, feeding corrections back into the evaluation loop. The architecture supports Chain of Prompts, RAG pipelines, and multi-step agent workflows, integrating with frameworks like LangChain and LlamaIndex. Self-hosting deploys via Docker Compose with Traefik for routing, requiring only a clone, environment configuration, and a single docker compose command. On RepoCloud, deploy Agenta on a dedicated VPS with root SSH access, persistent storage for evaluation datasets and traces, and complete control over model provider credentials, all under the MIT license with no usage restrictions.
Dagster
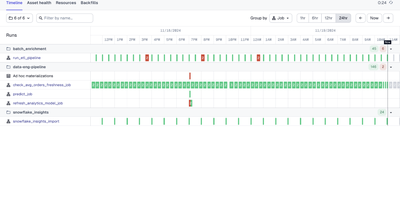
With nearly 16,000 GitHub stars, 5.7 million monthly PyPI downloads, and 400+ contributors, Dagster is the most widely adopted asset-centric data orchestration platform — replacing task-oriented schedulers like Apache Airflow with a declarative model where every pipeline is defined as Python functions producing data assets such as tables, datasets, machine learning models, and reports. The built-in asset graph provides automatic lineage tracking across your entire data platform, showing exactly how data flows from ingestion through transformation to downstream consumption in a single unified view. Declarative Automation goes beyond cron scheduling with event-driven conditions that intelligently trigger materializations based on upstream freshness, data quality signals, and dependency state. The integrated data catalog auto-generates documentation from asset metadata, ensuring it never drifts out of sync with production. Native first-class integrations connect dbt, Snowflake, BigQuery, Databricks, Fivetran, Airbyte, Spark, Great Expectations, Tableau, Power BI, AWS, GCP, and Azure without custom glue code. The web UI visualizes asset graphs, run history, schedules, sensors, and partitioned materializations with built-in alerting via Slack and PagerDuty. Dagster Pipes enables executing arbitrary code in external environments including Spark clusters, Kubernetes Jobs, and cloud functions. Deploy via Docker Compose on a single VM with separate containers for the webserver, daemon, and code locations, or use official Helm charts for production Kubernetes with K8sRunLauncher scaling each run as an independent Job. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Cube
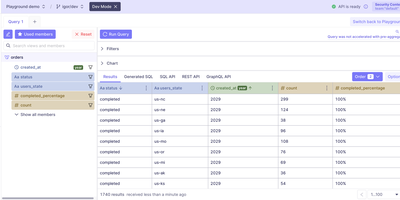
BI tools, customer-facing apps, and AI agents all receive the same governed answer from Cube Core, an open-source semantic layer where every metric is defined once, in code. Models are written in YAML or JavaScript. Cubes describe business entities with measures, dimensions, and joins. Views curate datasets for consumers. Git holds every version, with code review and CI like any other codebase. Queries arrive through a Postgres-compatible SQL API with a MEASURE function, through REST returning JSON, or through GraphQL, which means any tool that speaks Postgres connects without custom drivers. Sources include Snowflake, BigQuery, Databricks, Amazon Athena, Presto, and Postgres. Pre-aggregations declared in the model refresh in the background and live in Cube Store. An aggregate-aware planner routes matching queries to those rollups, and dashboards answer in milliseconds without rescanning the warehouse. Access policies set member-level visibility, row-level filters, and data masking from the security context. Multi-tenant SaaS analytics becomes practical: each customer sees only their own rows, whichever API asks. A development-mode Playground, meant for local use and never for public exposure, composes queries from measures and dimensions, shows the generated SQL, charts the results, and copies ready-made SQL, REST, and GraphQL calls. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Duckle
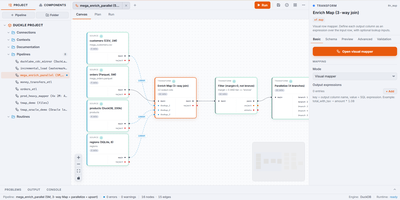
Duckle compiles visual data integration pipelines into vectorized analytical SQL executed on an embedded columnar engine, eliminating the overhead and cloud egress costs of traditional ETL infrastructure. Engineers can construct data pipelines on a drag-and-drop canvas, connecting hundreds of data sources spanning relational databases, cloud object storage, streaming event buses, vector databases, and SaaS application programming interfaces. An interactive mapping editor enables complex joins between primary data inputs and lookup streams with typed transform expressions and live sample inspections. Built-in transformation blocks execute change data capture, slowly changing dimensions, aggregation rollups, and integrated dbt models with zero row-based metering or cloud egress fees. Teams schedule headless production executions through a dedicated web console equipped with role-based access management, execution audit trails, and automated failure alerts dispatched to webhook endpoints. Embedded Model Context Protocol capabilities allow AI coding assistants to validate schema configurations, inspect execution logs, and trigger batch workflows directly through conversational commands. Workspaces store entire pipeline definitions as individual files in version control, ensuring reproducible deployments across staging and production environments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
OpenChoreo
OpenChoreo gives developers a complete open-source internal developer platform for Kubernetes: a self-service portal to build, deploy, and run applications without wrestling raw cluster YAML. In the portal you create a component from source code or a container image, expose it through endpoints, and promote it across environments with a few clicks. Platform engineers define the golden paths behind that simplicity: component types, traits, and workflows set the rules for how workloads are built, secured, and connected. The control plane translates each declaration into the Kubernetes resources it needs, then keeps the portal in sync with what is actually running. Built-in CI builds from source with Buildpacks and Argo Workflows, and GitOps delivery keeps every environment reconciled with the declared state. Metrics, logs, and traces surface in the same portal, organized by component and environment instead of pod names and namespaces. Role-based access control, project isolation, and traffic policies draw the boundaries between teams, and platform analytics show how the platform itself is being used. Existing Backstage portals can adopt OpenChoreo as plugins, and developers can also work through the CLI, GitOps files, or AI agents. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
CubeJS
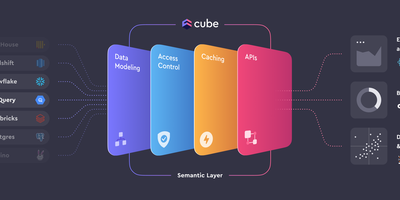
Between your databases and everything that consumes data - BI tools, embedded analytics, AI agents - sits Cube (formerly Cube.js), an open-source semantic layer. Metrics, dimensions, joins, and access rules are defined once as code in YAML, JavaScript, or Python, forming a governed data model that every downstream consumer shares, so "revenue" means the same thing in every dashboard. Caching is two-level: an in-memory cache absorbs bursts of identical queries, and declared pre-aggregations - rollup tables built in the warehouse or in Cube Store, Cube's distributed columnar engine, and refreshed in the background - deliver sub-second latency while cutting warehouse compute costs. The query planner routes each request to cache, rollup, or source automatically. Consumers connect through a Postgres-compatible SQL API (any tool that speaks Postgres works), plus REST, GraphQL, and a Meta API for model introspection. Row-level security and multi-tenancy are enforced in the layer itself, upstream of every client. Sources include Snowflake, BigQuery, Databricks, Postgres, MySQL, Presto, and Athena. Headless by design - bring your own UI.
PeerDB
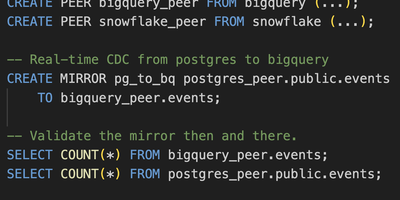
Replicate PostgreSQL to data warehouses 10x faster than conventional CDC tools, proven across 400+ companies including AutoNation and LC Waikiki collectively moving 200 TB monthly. The architecture pairs a Rust-based Nexus query layer implementing the PGWire protocol with Go-based Flow workers orchestrated by Temporal. Because Nexus speaks native Postgres wire protocol, any client tool (pgAdmin, psql, Grafana, Tableau, Flyway) can manage replication through standard SQL commands like CREATE MIRROR. Three streaming modes serve different needs: log-based CDC via logical replication slots, cursor-based streaming through timestamp or integer columns, and XMIN-based capture for tables lacking logical replication. Parallel initial load achieves consistent snapshots through transaction snapshotting and CTID range scans, reducing 100+ GB migrations from days to minutes. Native TOAST column handling processes large JSONB payloads and IoT data efficiently without row expansion penalties. Destinations include ClickHouse, Snowflake, BigQuery, Kafka, Azure Event Hubs, Google PubSub, S3, and PostgreSQL with in-flight SQL transformations. Schema change propagation, partitioned table support, and slot growth alerts ensure production reliability. Docker Compose bundles Temporal, catalog Postgres, Flow API, workers, and the Next.js monitoring UI. Deployable on RepoCloud with dedicated VPS resources under AGPL-3.0.
Flowctl
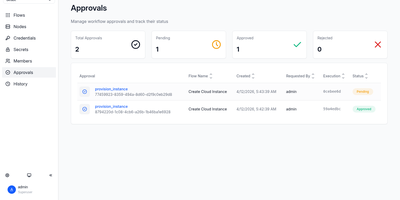
Flowctl turns repetitive ops work, such as granting SSH access, restarting a service, or provisioning a server, into self-service forms that anyone on the team can run without holding credentials. Each workflow is a YAML or HUML file with typed inputs, validation rules, and a list of actions. Actions run in order or as a dependency graph, so independent branches execute in parallel. Every action runs in a Docker container, as a shell script, or as another flow, and scripts can target remote servers over SSH, several at once. Sensitive steps pause until a reviewer approves or rejects them. Output from one action feeds the next, files pass along as artifacts, and failed actions can be retried. Cron schedules with time zones and labels run flows unattended, while logs stream live in the browser. Email, Slack, Mattermost, and webhook notifications announce success, failure, waiting, or cancellation. Teams get isolated namespaces with user, operator, reviewer, and admin roles, OIDC single sign-on, and encrypted storage for SSH keys and secrets. A built-in flow editor means nobody has to hand-write files, and custom executors can be added as Go plugins. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Freki
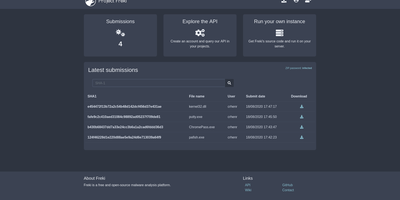
When a suspicious executable lands in your inbox, Freki gives your team a private place to pull it apart before it touches the network. Upload a sample through the web interface and Freki extracts its fingerprints at once: MD5, SHA-1, SHA-256, SHA-384, and SHA-512 hashes, plus CRC32 and SSDEEP fuzzy hashes for spotting near-duplicate variants. Static analysis then dissects Windows PE files without running them, reporting headers, sections, imported libraries, embedded strings, and capabilities identified in the code. A YARA engine sweeps every sample against your rule sets, so signatures your analysts write flag matching files the moment they arrive. Connect a VirusTotal API key and each report gains antivirus detection results from dozens of engines, placed next to your local findings. The same analysis runs through a REST API, so intake pipelines, mail gateways, and triage scripts can submit files and read verdicts automatically. Analysts discuss findings in community comments attached to each sample, building a shared memory of what a file is and why it matters. Accounts control who may submit samples and call the API, and every analyzed sample stays downloadable for re-examination or sharing with trusted peers. Docker Compose brings the whole platform up behind Nginx with its MariaDB database, keeping live malware samples on your own hardware instead of a public service. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Risuai
Characters, worlds, and long-running stories deserve a chat window built for them, and Risuai delivers one as a web application you host yourself. Each character card holds a description, a first message, and an author's note, and chats can run with a single character or a whole group. Lorebooks inject background facts only when their activation keys appear in the conversation, so a ship, a city, or a rival stays consistent without crowding every prompt. Provider choice is wide: OpenAI, Anthropic, Google, OpenRouter, Mistral, DeepSeek, Ollama, Kobold, and a Custom API slot for any OpenAI-compatible endpoint, with streaming and parameter sliders for temperature, top-p, and repetition penalty. The prompt editor can reorder blocks for character description, persona, lorebook, memory, and chat history, and conditions and variables shape the result. Regex scripts rewrite replies into custom interfaces, translators let you chat across languages, TTS reads replies aloud, and emotion images swap a character's portrait to match the mood. Plugins add providers or features, and HypaMemory and SupaMemory compress older turns to preserve context. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Airbyte
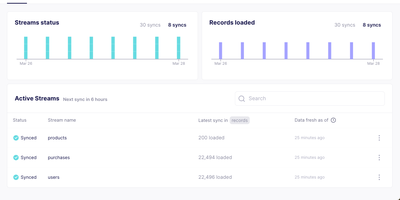
Backed by over 21,800 GitHub stars and more than 1,000 community contributors, Airbyte has become the standard open-source data movement platform, powering ELT pipelines for organizations ranging from startups to Fortune 500 enterprises. The platform provides 600+ pre-built connectors covering PostgreSQL, MySQL, MongoDB, Snowflake, BigQuery, Redshift, S3, Salesforce, HubSpot, Stripe, Shopify, Google Analytics, and hundreds of additional APIs, databases, and SaaS applications. The no-code Connector Builder lets practitioners create new source connectors in minutes by pointing at an API documentation URL, while the Python CDK enables custom connectors with full programmatic control for complex authentication flows and pagination strategies. Airbyte's AI agent capabilities include the MCP Gateway for Model Context Protocol integration, the open-source Agent SDK compatible with pydantic-ai, LangChain, OpenAI Agents, and FastMCP, and a Context Store that lets AI agents query business data across connected systems without runtime API stitching. Change Data Capture streams incremental updates from PostgreSQL, MySQL, and SQL Server using Debezium, while dbt integration handles post-load transformations within the pipeline. Self-hosted deployment uses Kubernetes via the abctl CLI tool, which bootstraps a local kind cluster with a single command, or Helm charts for production clusters with Keycloak OIDC authentication and secrets management through AWS Secrets Manager, Google Secrets Manager, or HashiCorp Vault. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. ELv2 licensed with MIT-licensed connectors.
Backstage
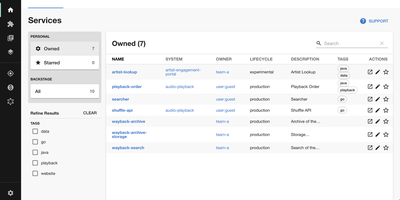
Adopted by over 3,400 companies and backed by 34,000 GitHub stars, Backstage is the open-source developer portal framework created by Spotify and now hosted by the Cloud Native Computing Foundation. The centralized Software Catalog registers every service, library, data pipeline, website, and ML model in your organization using YAML metadata files stored alongside code in GitHub, GitHub Enterprise, or GitLab, tracking ownership, lifecycle status, and dependency relationships across your entire ecosystem. Software Templates provide self-service infrastructure provisioning where developers fill out a form and Backstage automatically scaffolds new repositories, CI/CD pipelines, and cloud resources following your organization's standardized best practices. TechDocs renders Markdown documentation directly alongside the services it describes using a docs-like-code approach powered by MkDocs, with the TechDocs Addon Framework for extending the reading experience. The Search Platform indexes content across the catalog, TechDocs, Confluence, and Stack Overflow through configurable search backends. Kubernetes monitoring built specifically for service owners rather than cluster admins displays pod health, logs, and deployment status across any cloud provider or managed Kubernetes service. The plugin ecosystem includes over 230 open-source integrations covering CI/CD systems like GitHub Actions and GitLab Pipelines, monitoring platforms like Datadog and Grafana, cloud providers including AWS and Azure, plus specialized plugins for security scanning, cost management, API documentation, PagerDuty incident management, and Lighthouse website auditing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.