
Stars
Forks
Watchers
Developer links
Duckle
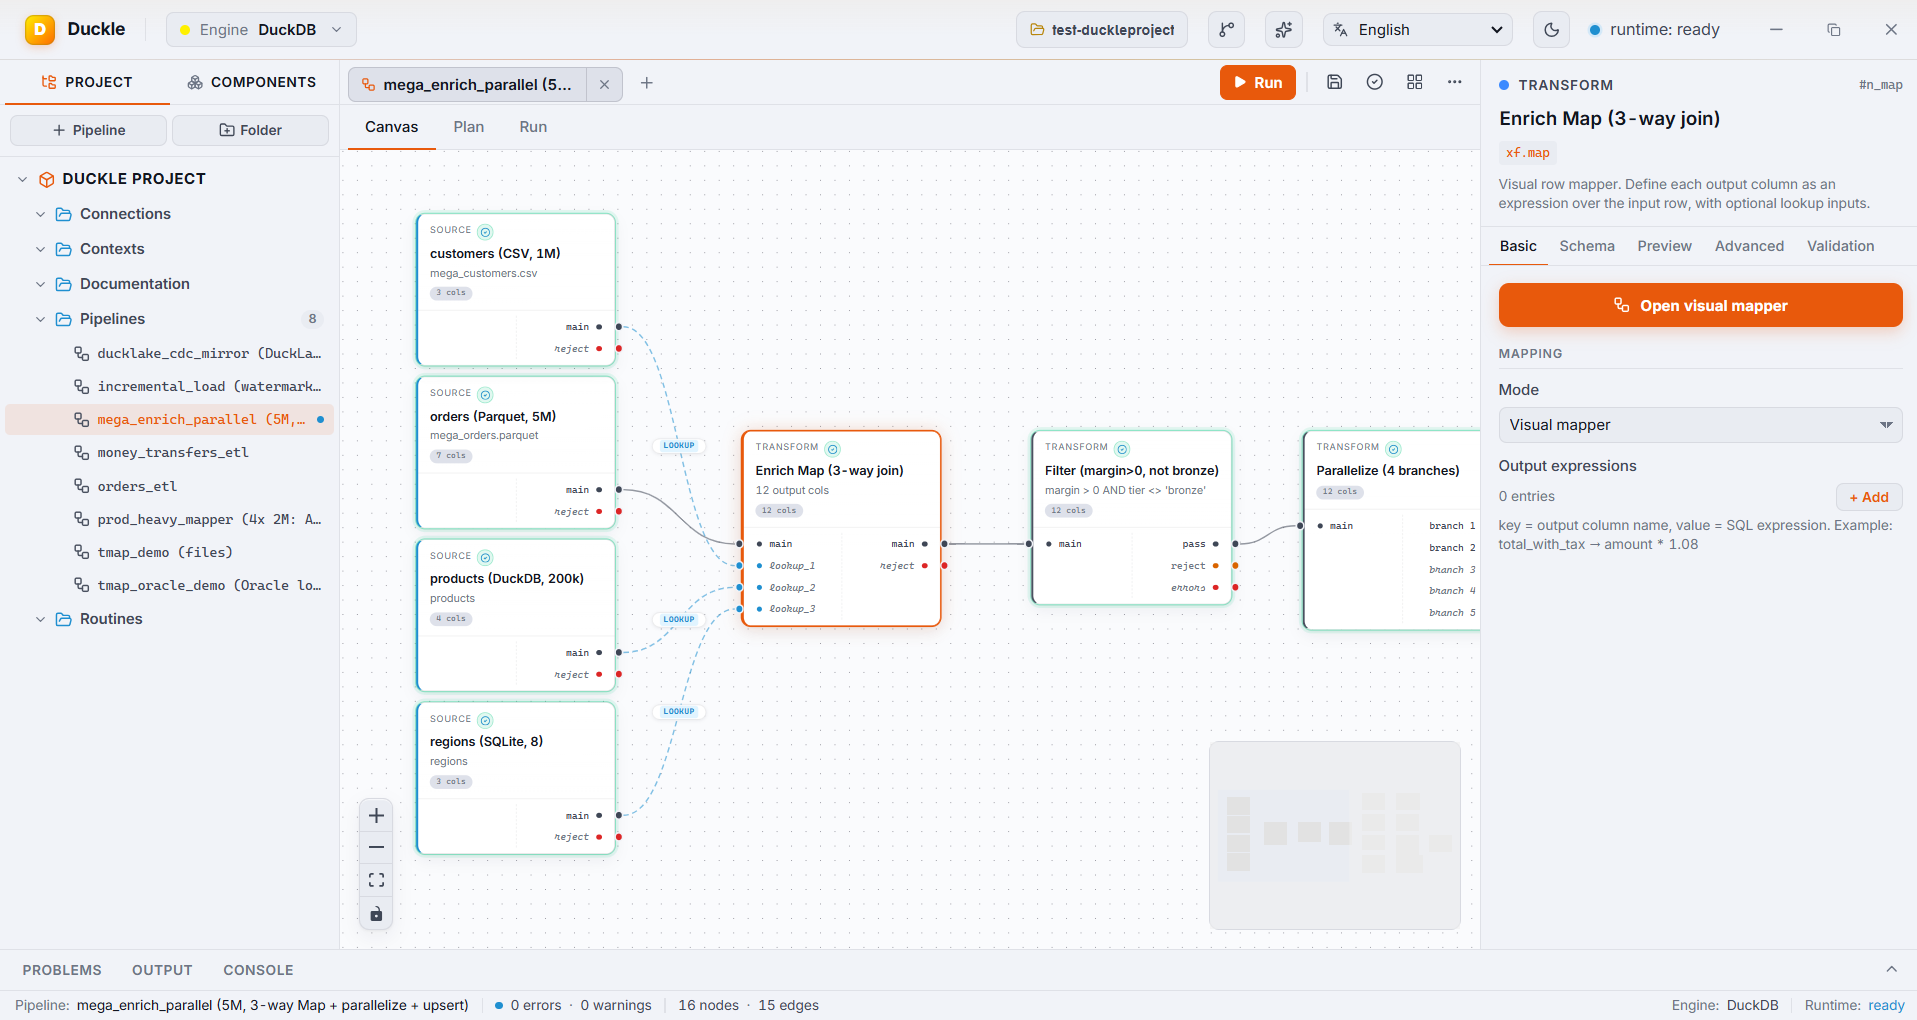
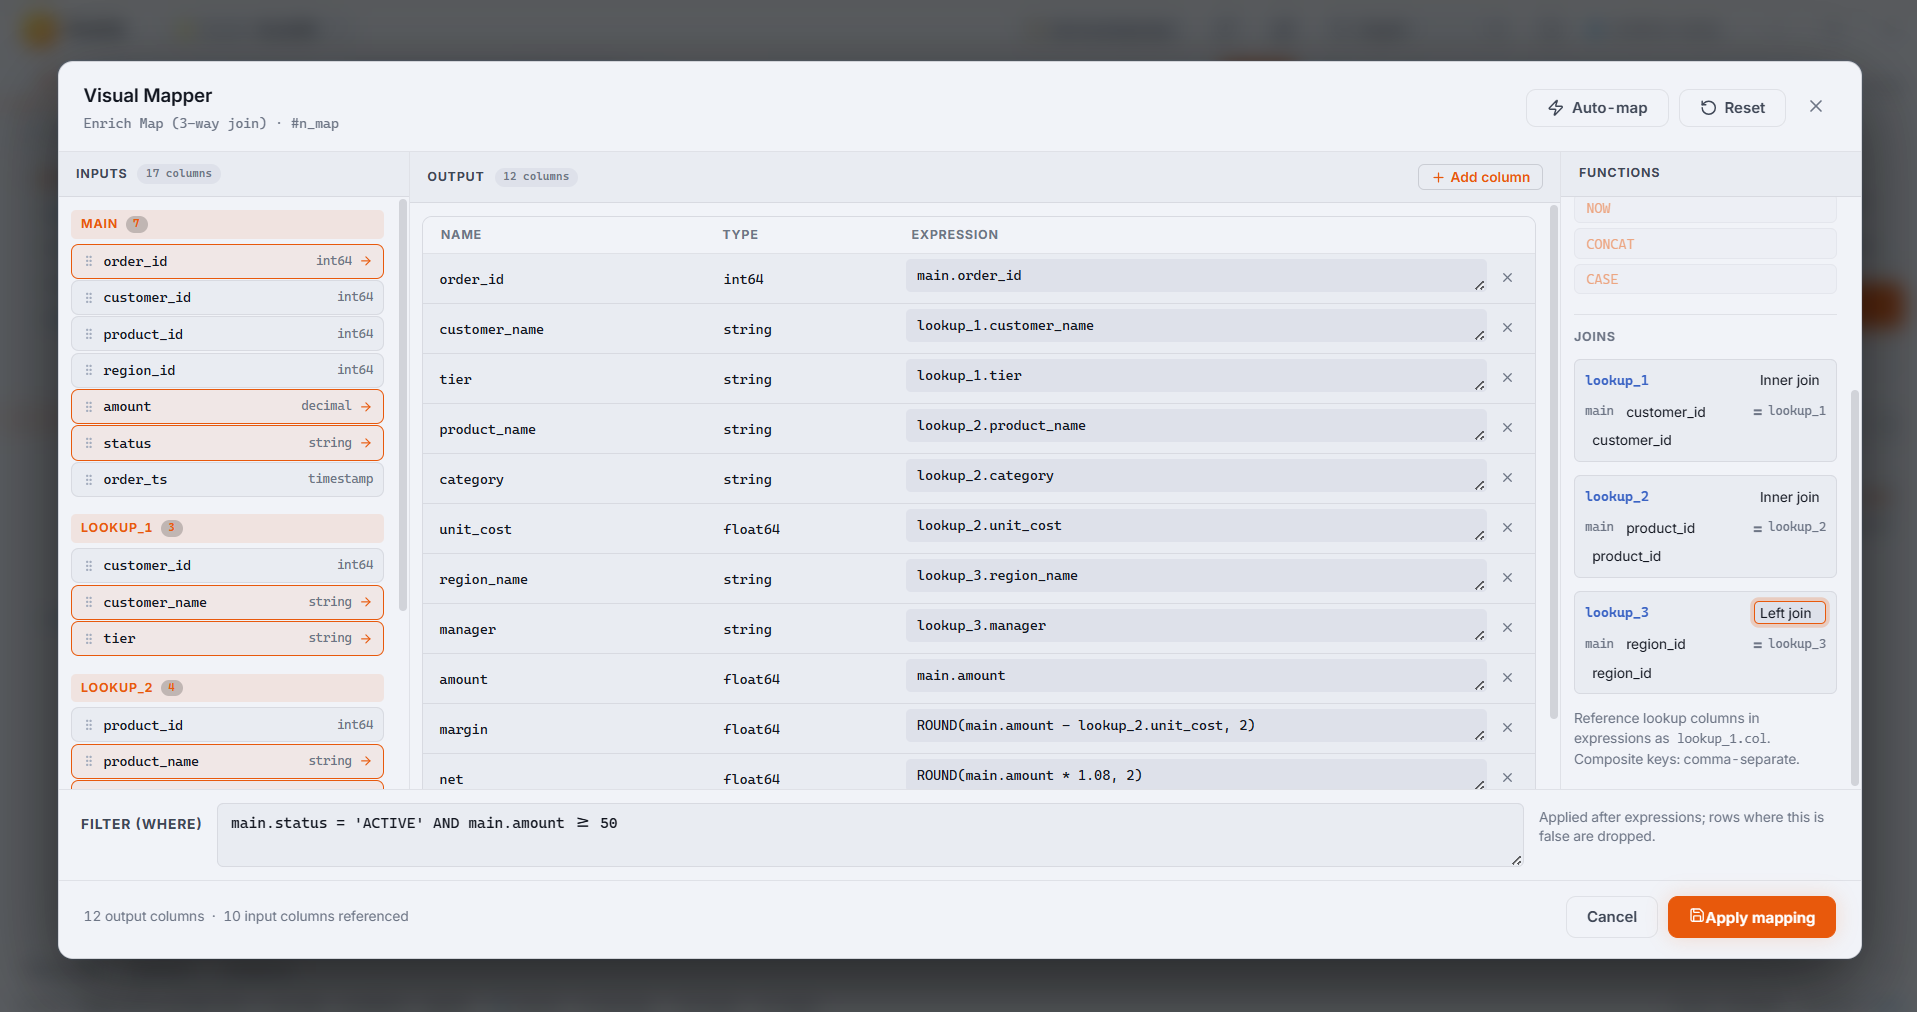
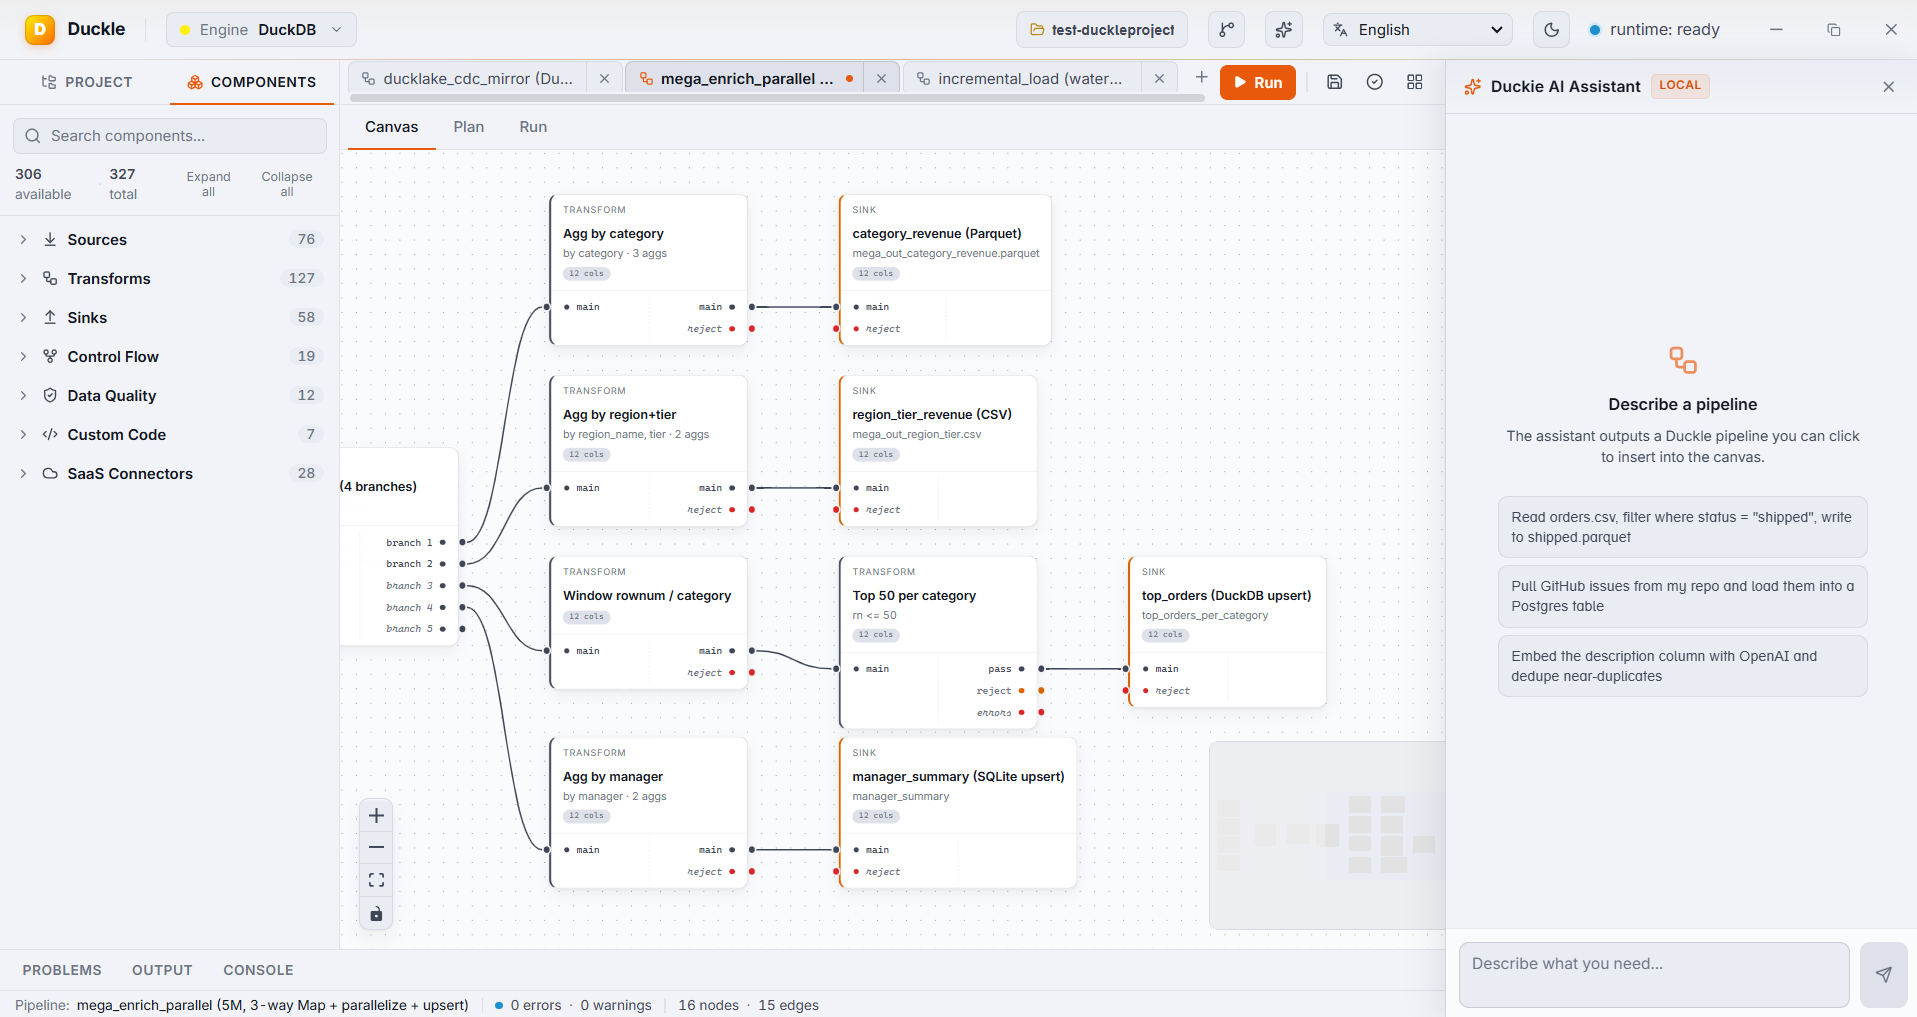
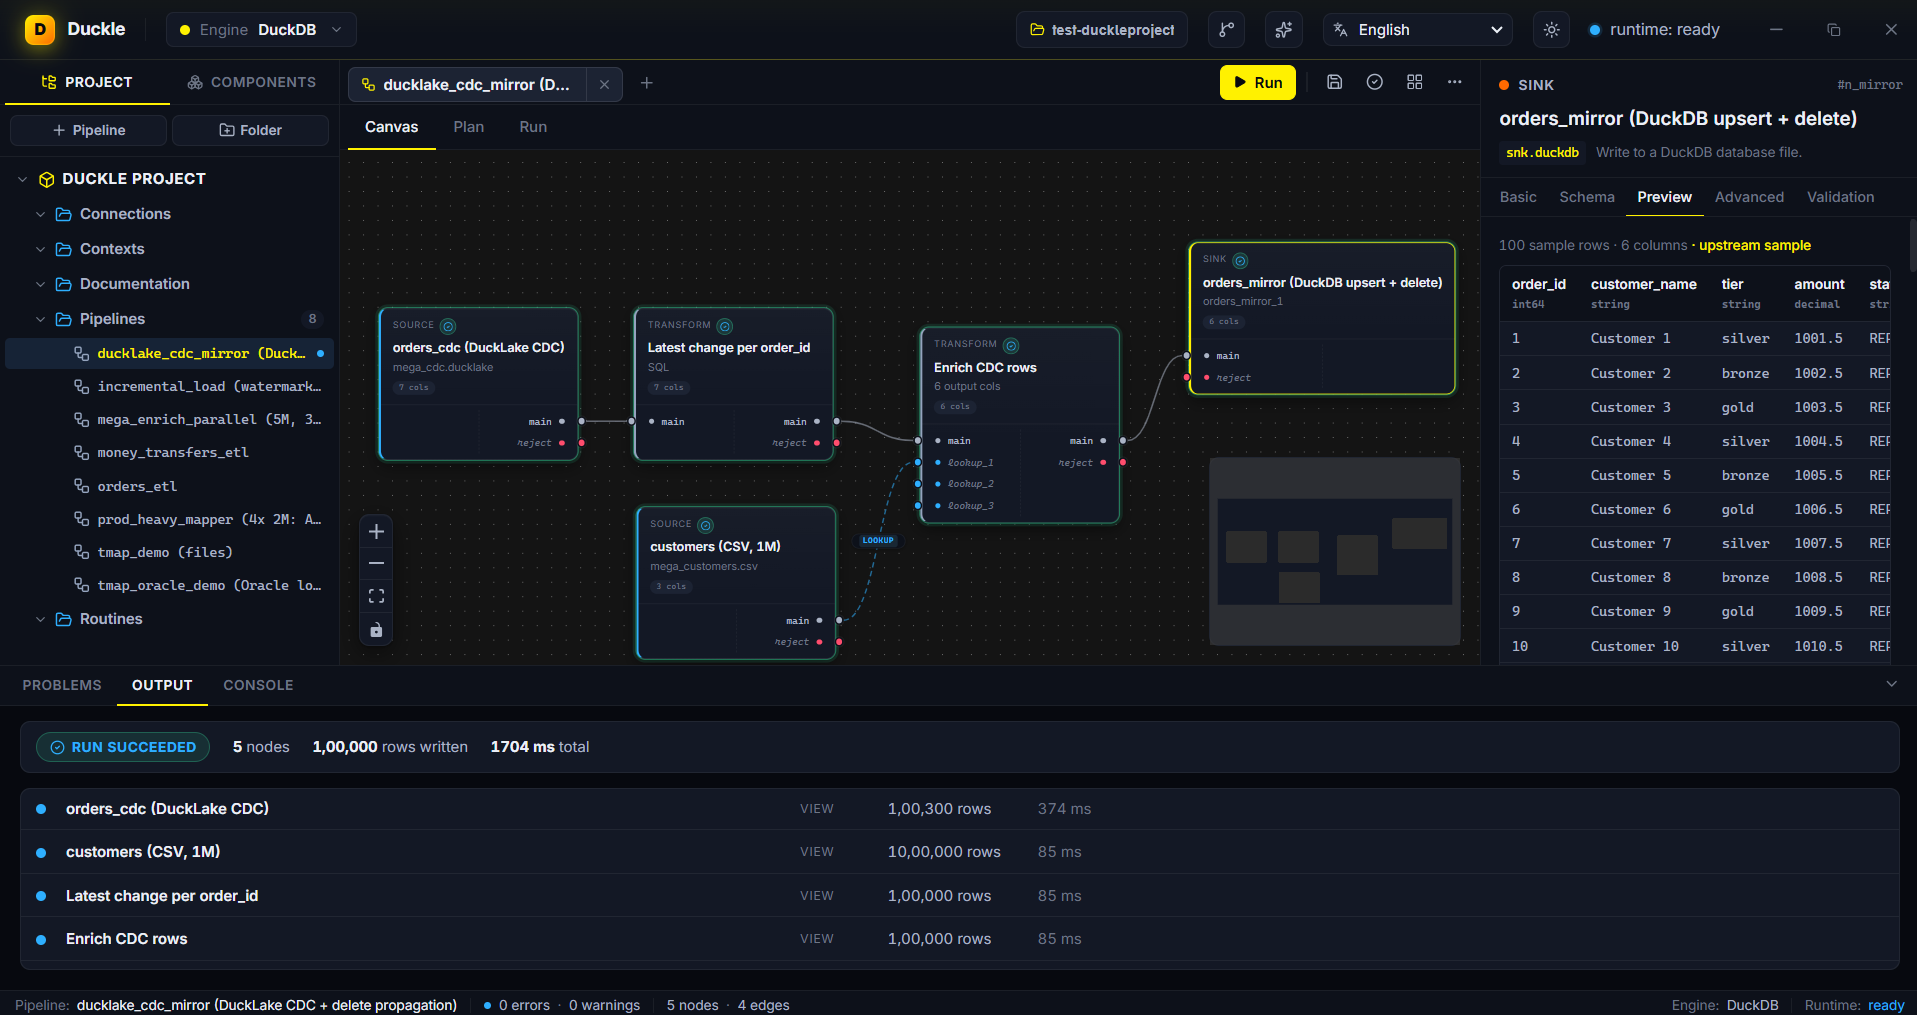
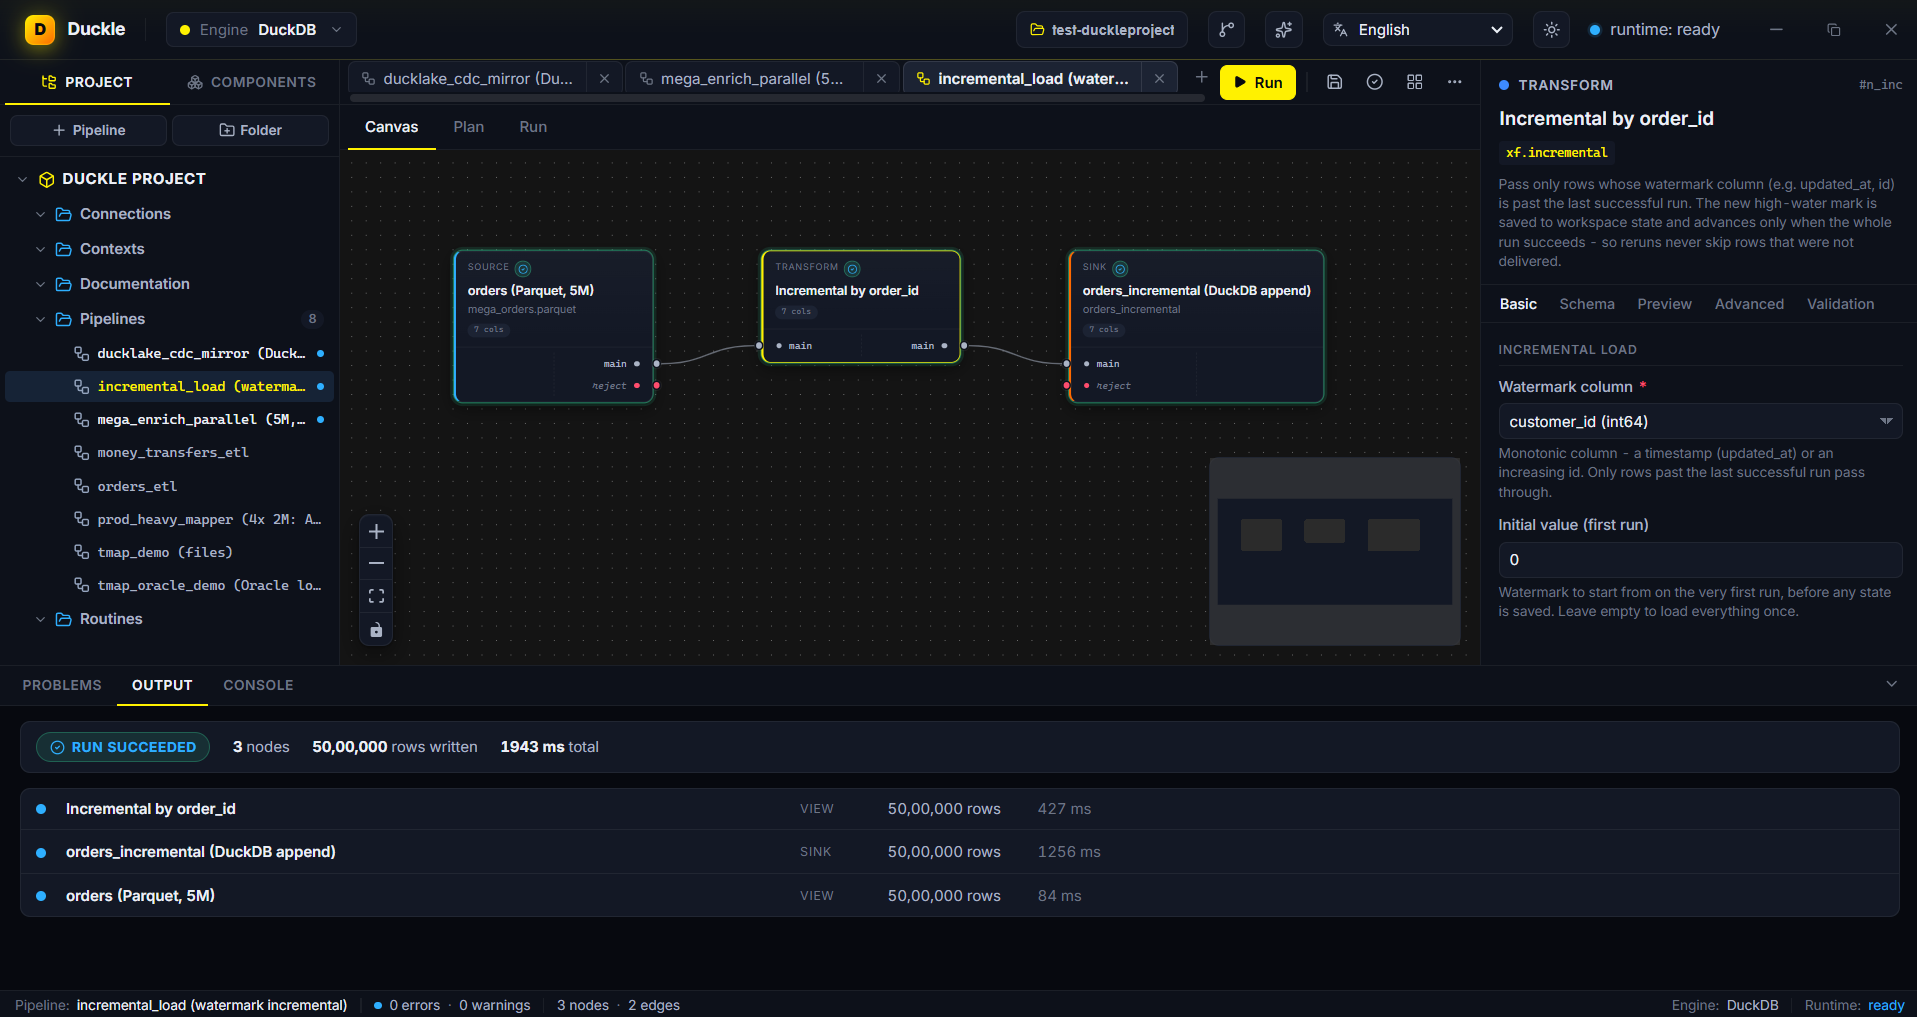
Duckle compiles visual data integration pipelines into vectorized analytical SQL executed on an embedded columnar engine, eliminating the overhead and cloud egress costs of traditional ETL infrastructure. Engineers can construct data pipelines on a drag-and-drop canvas, connecting hundreds of data sources spanning relational databases, cloud object storage, streaming event buses, vector databases, and SaaS application programming interfaces. An interactive mapping editor enables complex joins between primary data inputs and lookup streams with typed transform expressions and live sample inspections. Built-in transformation blocks execute change data capture, slowly changing dimensions, aggregation rollups, and integrated dbt models with zero row-based metering or cloud egress fees. Teams schedule headless production executions through a dedicated web console equipped with role-based access management, execution audit trails, and automated failure alerts dispatched to webhook endpoints. Embedded Model Context Protocol capabilities allow AI coding assistants to validate schema configurations, inspect execution logs, and trigger batch workflows directly through conversational commands. Workspaces store entire pipeline definitions as individual files in version control, ensuring reproducible deployments across staging and production environments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Benefits
- Zero Row-Based Egress Fees
- Process massive datasets locally on embedded columnar infrastructure without incurring per-row platform charges, managed service surcharges, or recurring cloud compute fees typical of proprietary commercial ingestion solutions.
- Unified Visual and Code Authoring
- Design data integration graphs on a visual node canvas or author complex transformation logic in standard SQL, compiling every node into inspectable queries with live preview tables.
- Pre-Built Multi-Protocol Connector Ecosystem
- Connect instantly to relational databases, cloud data lakes, vector indices, messaging queues, and SaaS endpoints with over three hundred verified sources and sinks operating out of the box.
- Git-Native Version-Controlled Workspaces
- Preserve every pipeline as an individual declarative file tracked in Git repositories, enabling standard pull request reviews, continuous integration validation, automated rollbacks, and reproducible deployments across server environments.
Features
- Vectorized Columnar Execution
- Compiles visual pipeline graphs into optimized DuckDB SQL queries that leverage multi-core CPU parallelization to transfer millions of records between endpoints per minute.
- Visual Join Mapping Canvas
- Combines primary input streams with multiple lookup tables using an interactive tMap-style editor featuring typed expression builders, conditional routing, and real-time schema validation.
- Native dbt Project Integration
- Runs dbt transformation models directly on local DuckDB storage within the pipeline execution lifecycle, streamlining complex SQL dependencies without external database engines.
- Change Data Capture Engine
- Tracks incremental database modifications and manages slowly changing dimensions using high-watermark state tracking and automated merge routines across target storage destinations.
- Headless Web Administration Console
- Serves an automated pipeline orchestrator featuring cron scheduling, role-based access controls, execution audit logs, webhook notifications, and embedded Model Context Protocol agent connectivity.