Categories
Self-Hosted Developer Tools LLM Evaluation AI Security Prompt Engineering Red Teaming LLMOps AI TestingStars
Forks
Watchers
Developer links
Promptfoo
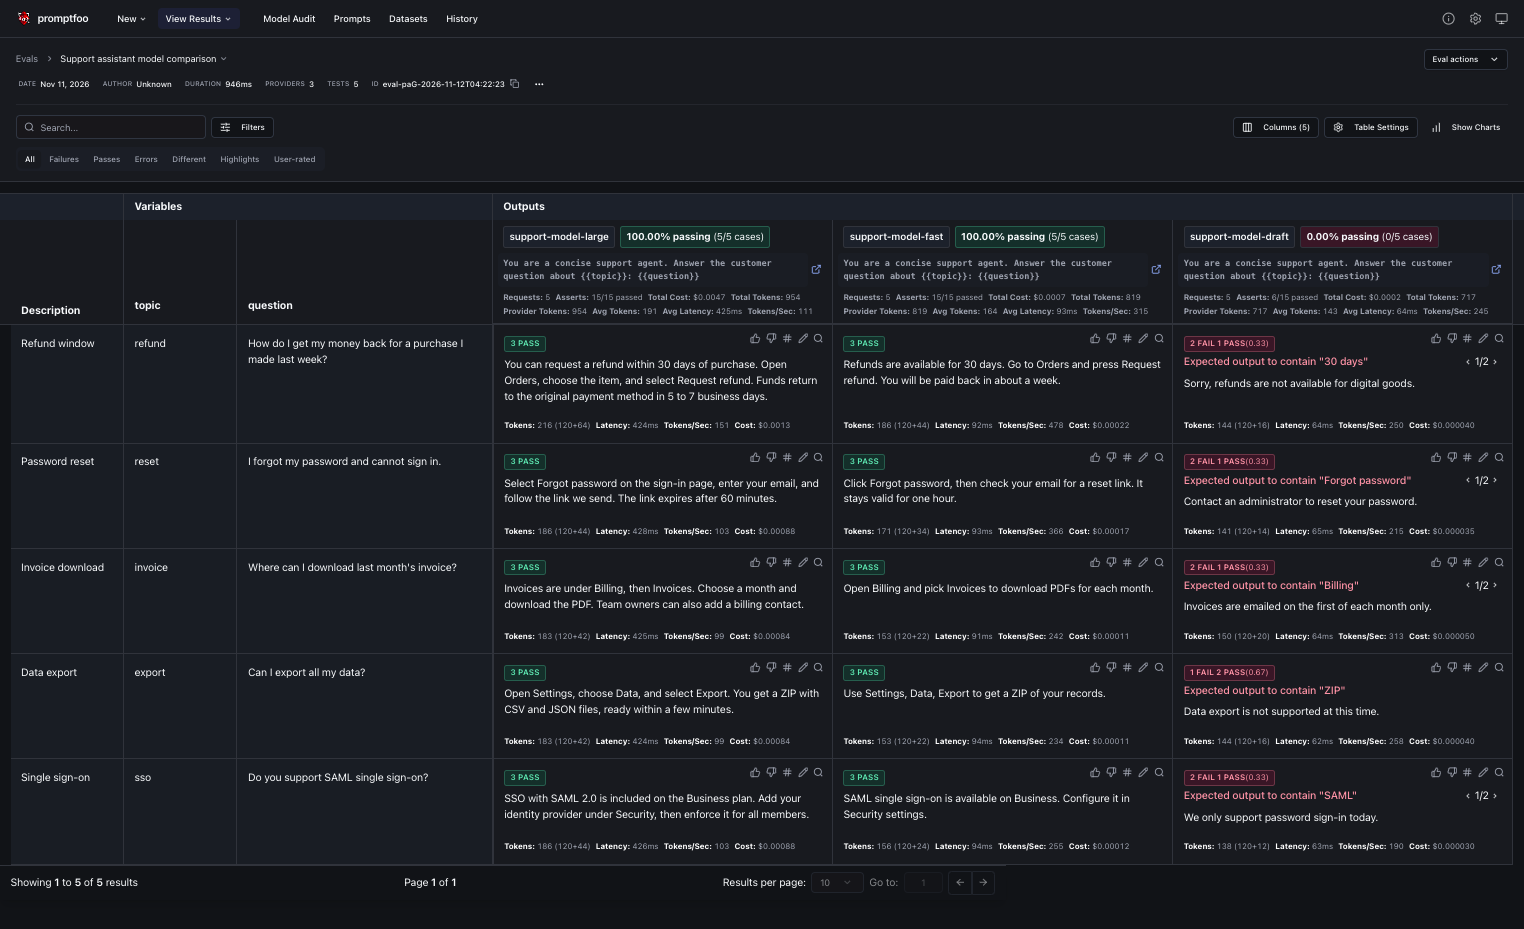
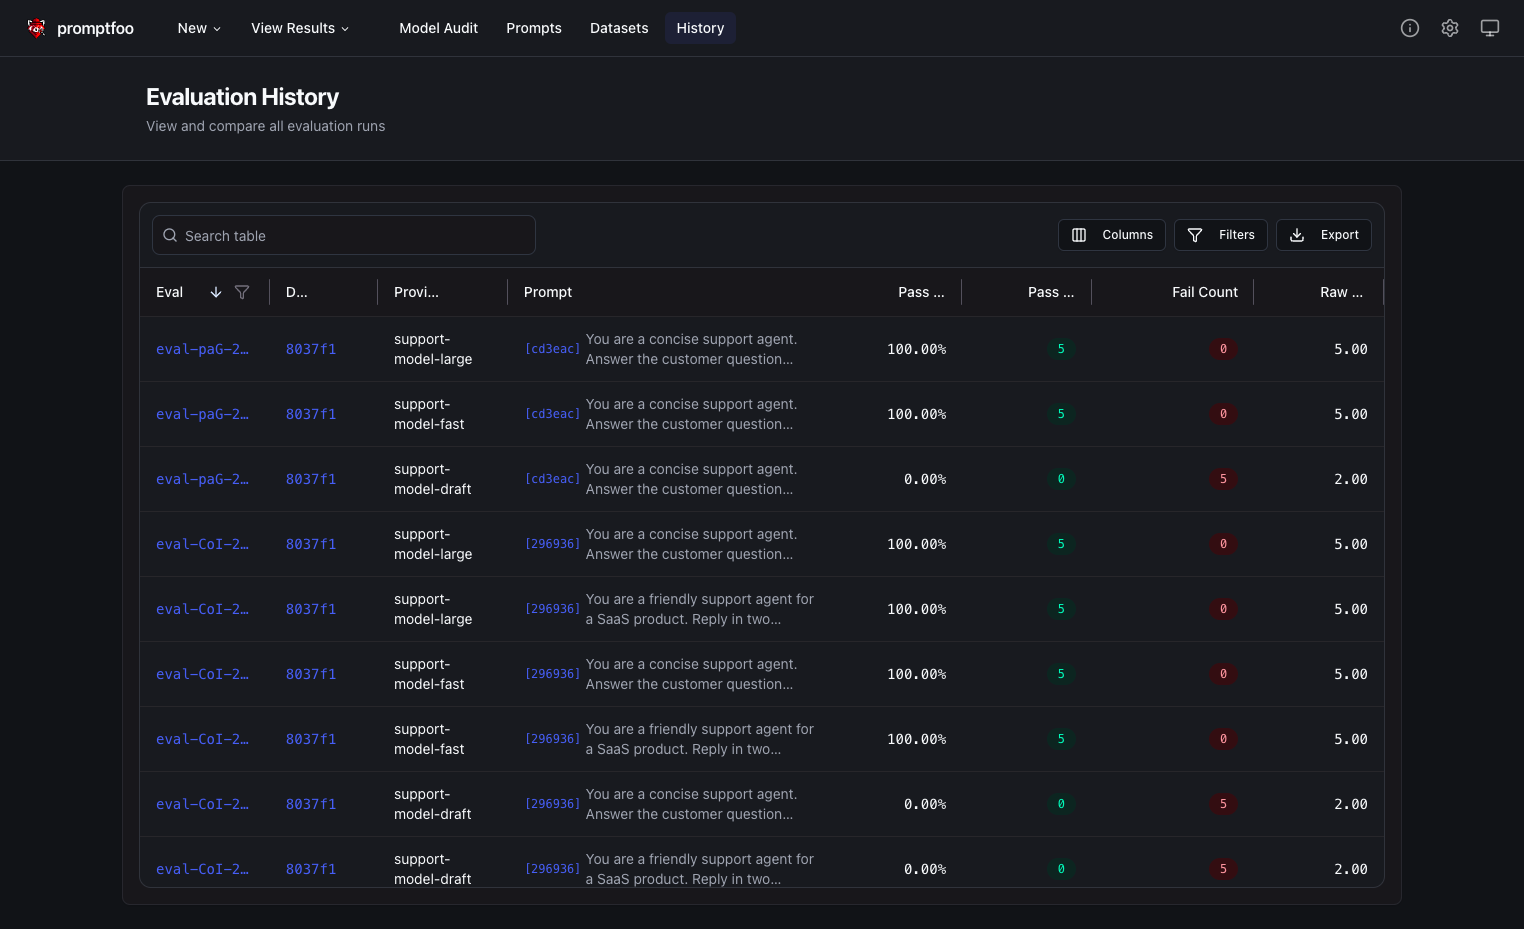
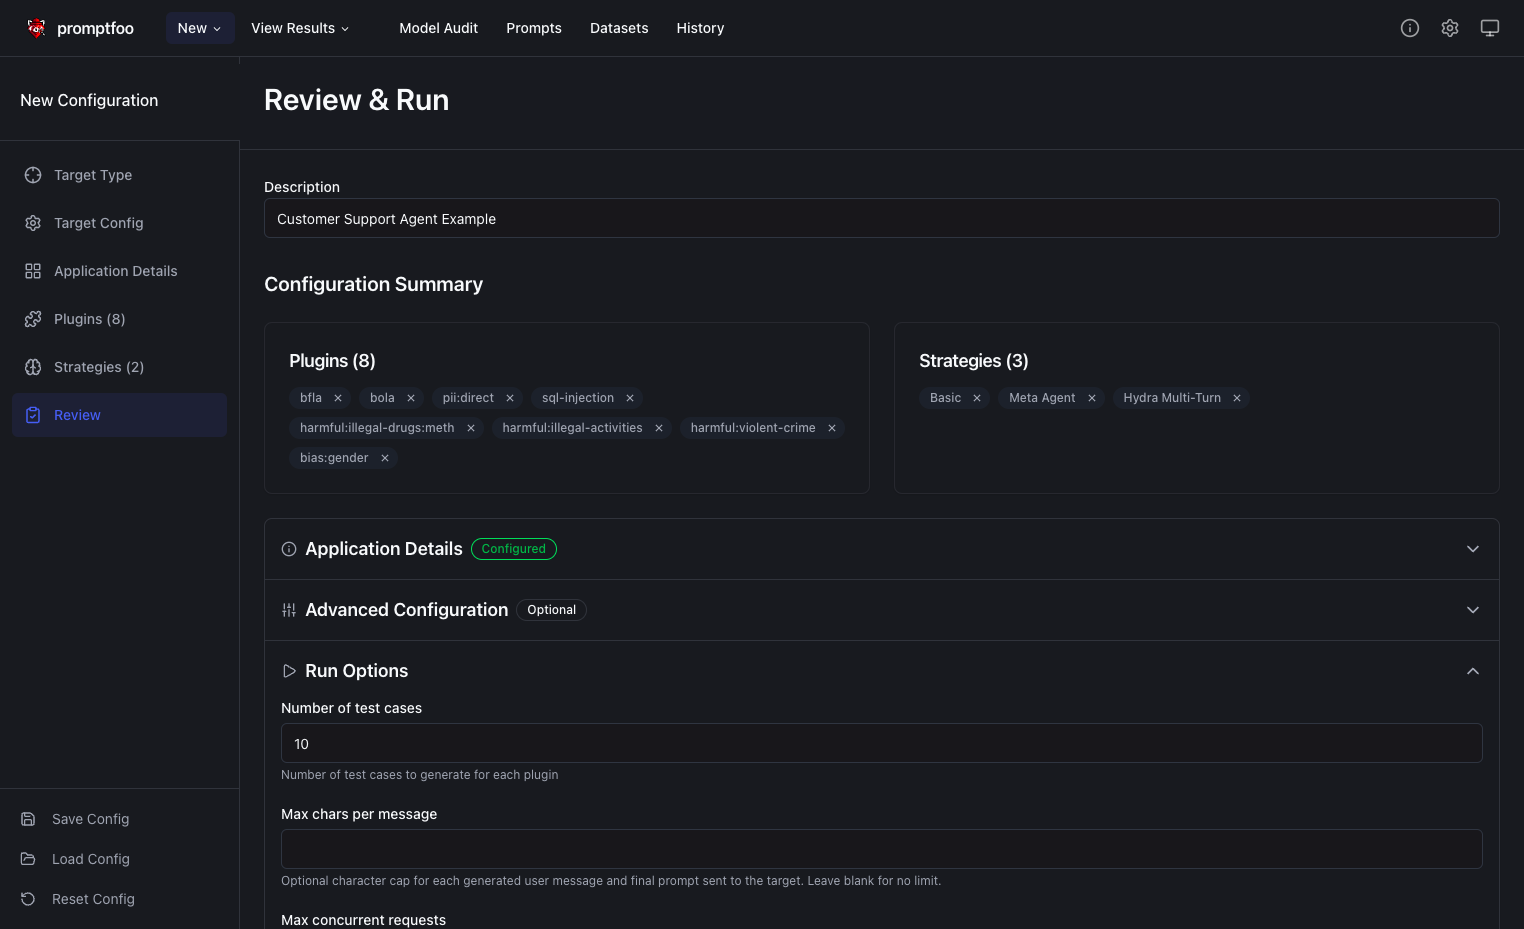
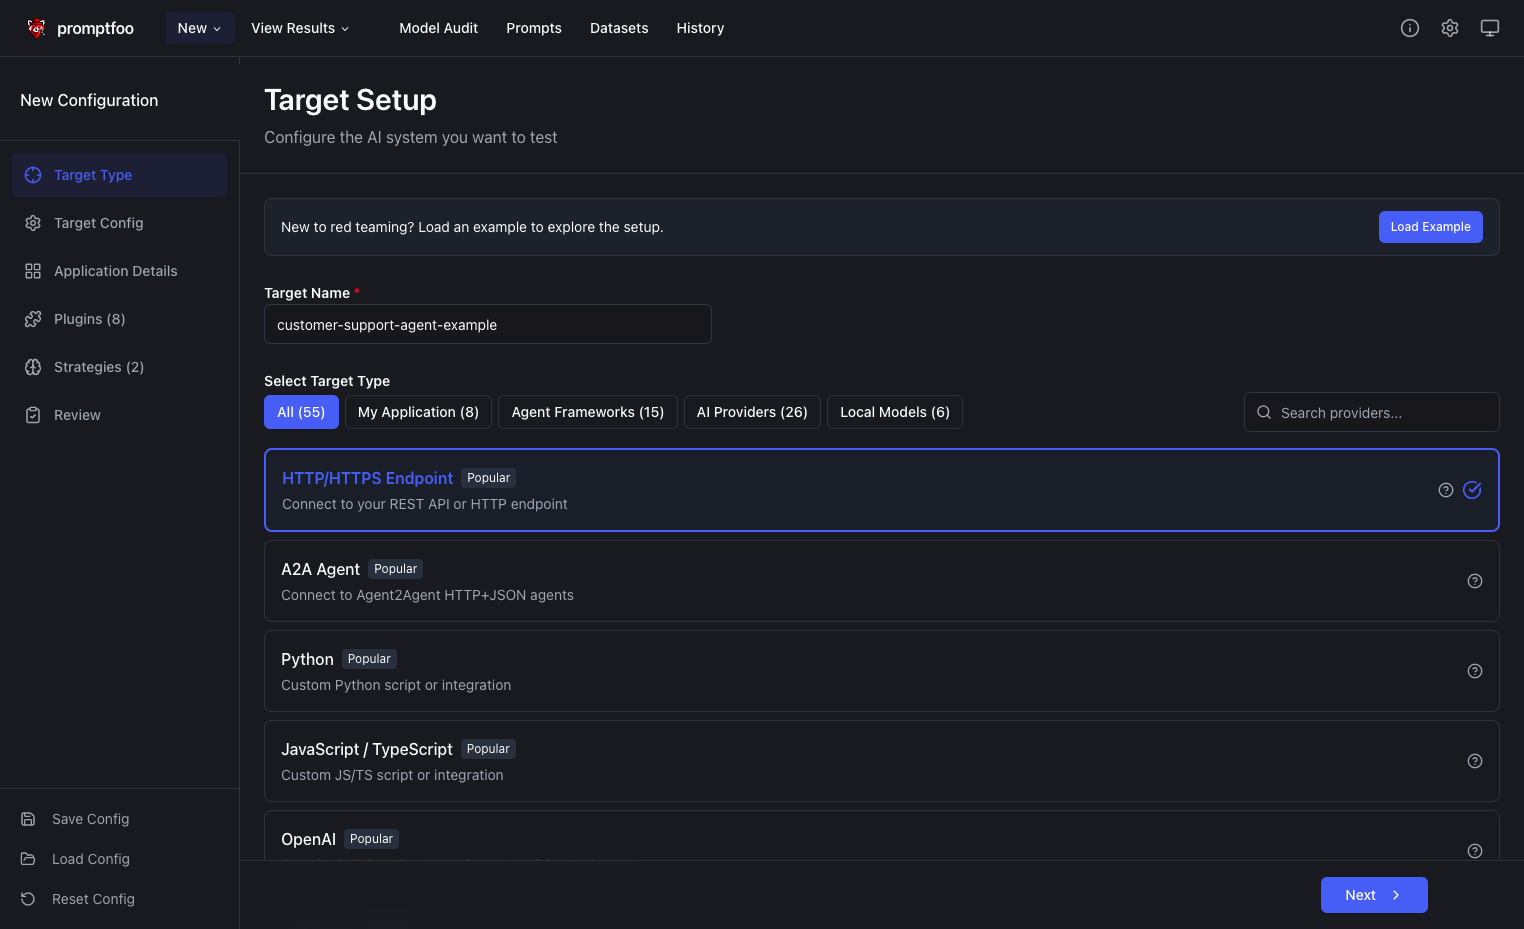
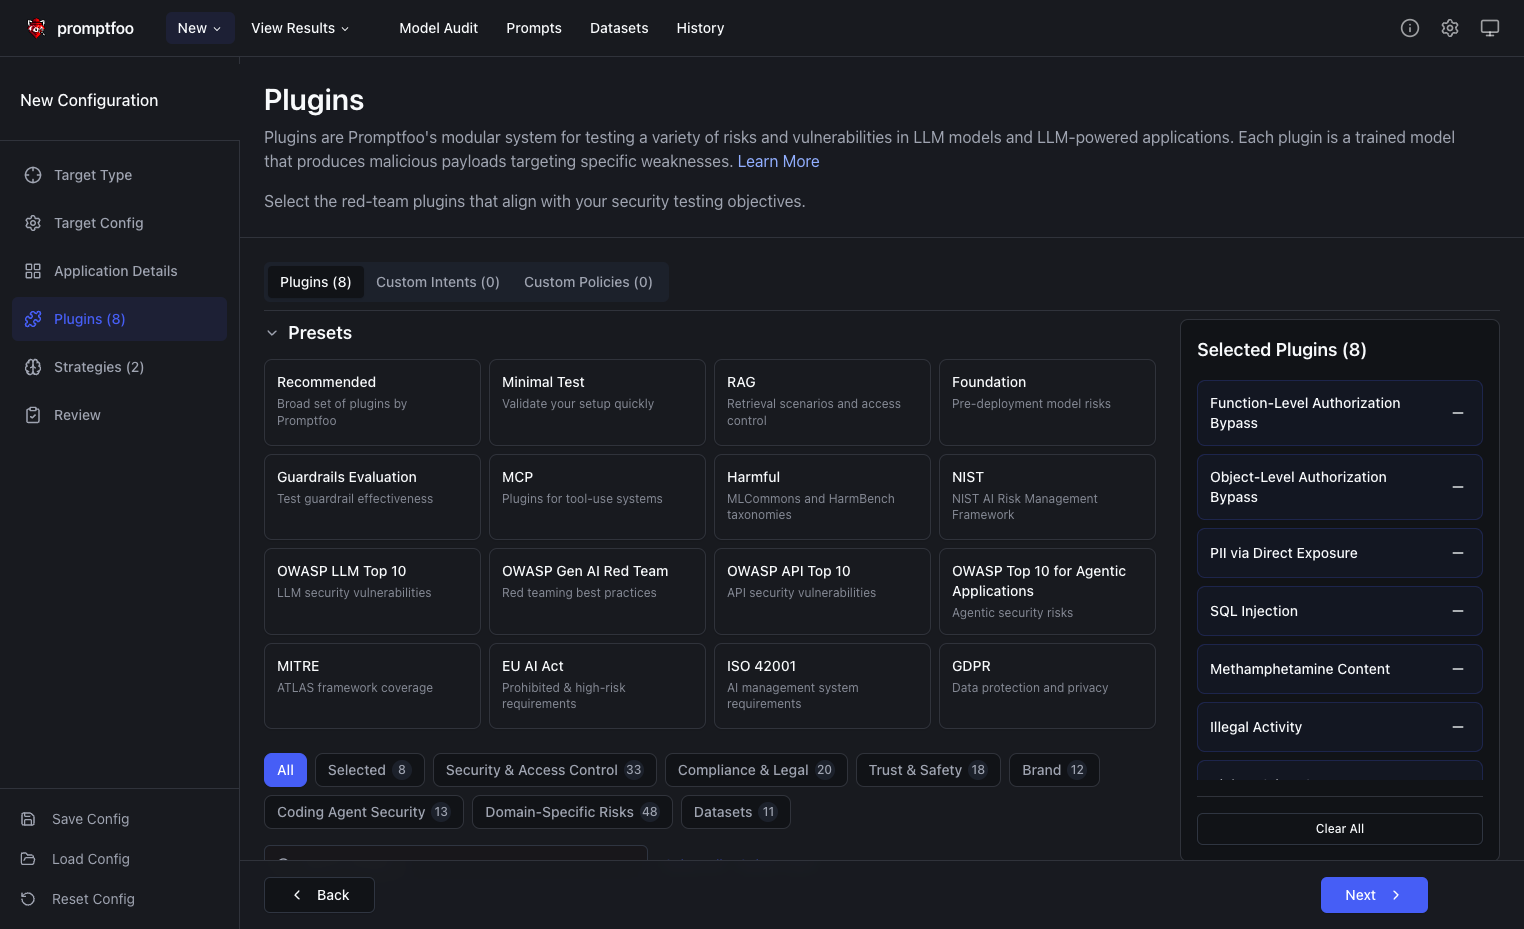
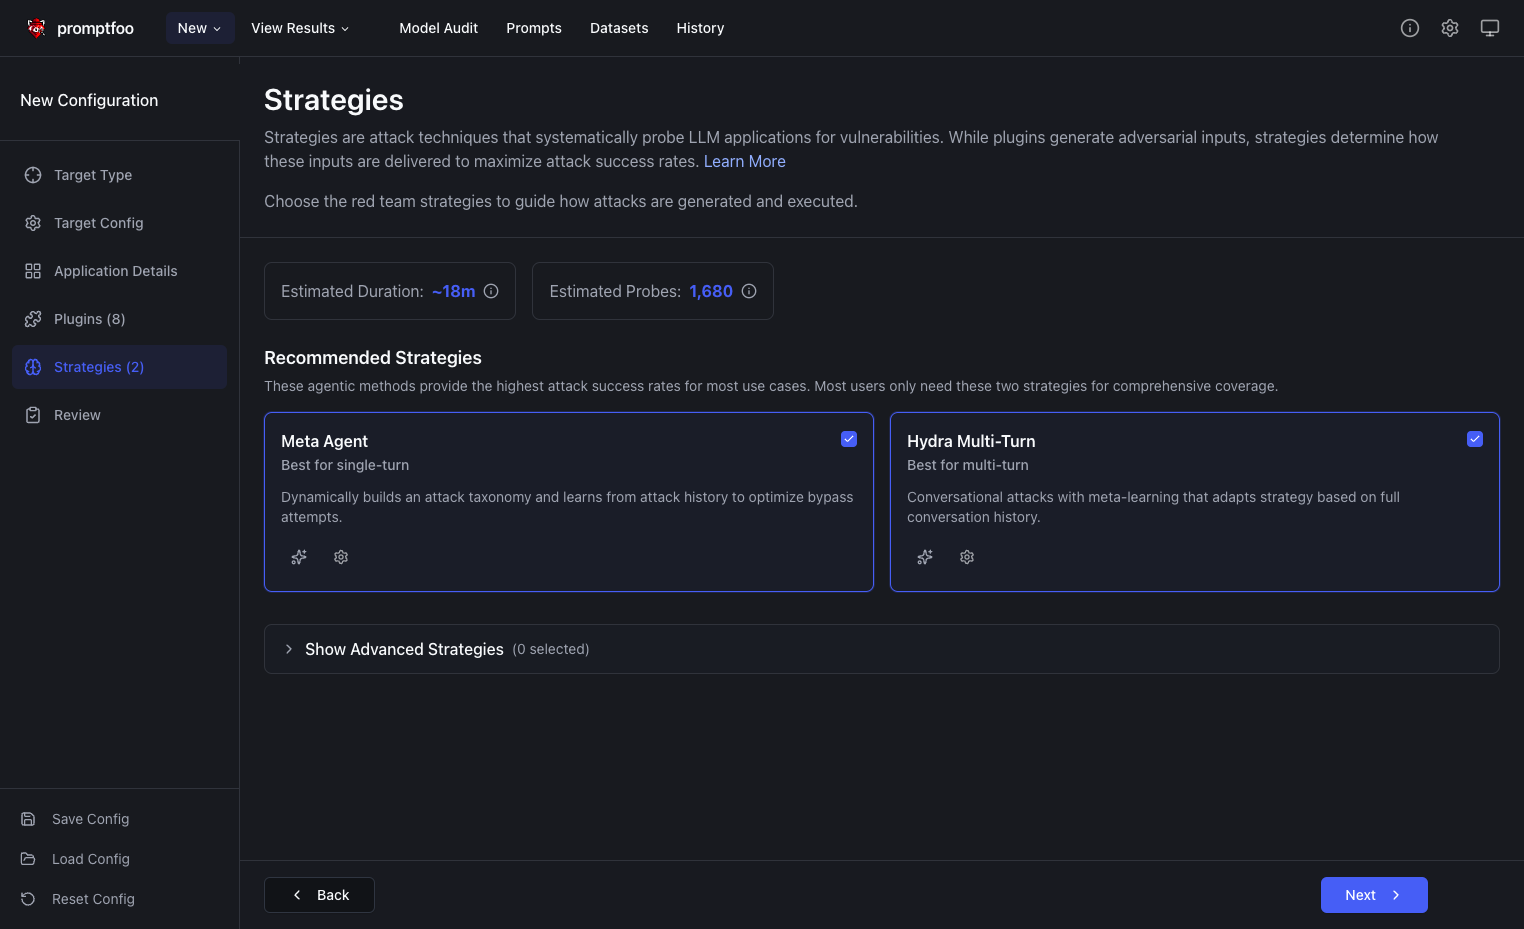
Promptfoo replaces vibes-based prompt tweaking with measurable tests, then attacks your AI app the way a hostile user would. An evaluation matrix lines up every prompt and model side by side, with pass or fail badges, assertion messages, latency, token counts, and cost in each cell. A red team wizard walks through the target, application details, plugins, and strategies, then probes for prompt injection, data exposure, broken access control, and harmful content. Preset bundles map plugins to the OWASP LLM Top 10, NIST AI RMF, MITRE ATLAS, GDPR, ISO 42001, and the EU AI Act. Meta Agent and Hydra Multi-Turn strategies adapt attacks across a whole conversation instead of firing one-shot prompts. Providers span OpenAI, Anthropic, Gemini, Bedrock, Azure, and local Ollama models, and any HTTP endpoint, Python script, or JavaScript function can be tested as a target. The history page lists every run with pass rates and raw scores, and prompt and dataset pages show which templates and test sets each run used. A provider allowlist file narrows the models offered in the web editor for cost control. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- Compare Models With Hard Numbers
- Run the same prompts across several models and read pass rates, latency, token use, and cost for every cell, so picking a model rests on measured results instead of impressions.
- Find Weaknesses Before Attackers Do
- The red team wizard generates adversarial inputs for injection, data exposure, and broken access control, then reports which attacks worked against your agent or chatbot.
- Keep Prompts And Results Private
- Evaluations use your own provider keys and store results in a SQLite database on your server, so prompts and customer examples never land in a third-party dashboard.
- Catch Regressions Before Release
- Run the same test suite from CI/CD pipelines so every prompt edit or model upgrade is checked against your assertions before it reaches users.
Features
- Evaluation Results Matrix
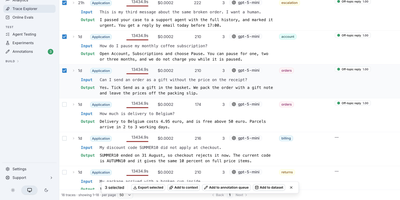
- A web table compares each prompt and provider against every test case, with pass or fail badges, assertion messages, token counts, latency, and cost on every output.
- Red Team Setup Wizard
- A guided flow covers target type, target config, application details, plugins, strategies, and review, and shows an estimated duration and probe count before you run.
- Compliance Plugin Presets
- Preset bundles group red team plugins by framework: OWASP LLM Top 10, NIST AI RMF, MITRE ATLAS, GDPR, ISO 42001, and the EU AI Act.
- Agentic Attack Strategies
- Meta Agent builds an attack taxonomy for single-turn tests, and Hydra Multi-Turn adapts conversational attacks to the full chat history, with advanced strategies available.
- Run History And Export
- The history page lists each evaluation with provider, prompt, pass rate, pass and fail counts, and raw score, with search, column filters, and an export menu.
- Prompt And Dataset Tracking
- Prompt and dataset pages show every template and test set with the number of evaluations that used them and the date of the latest run.