HyperDX
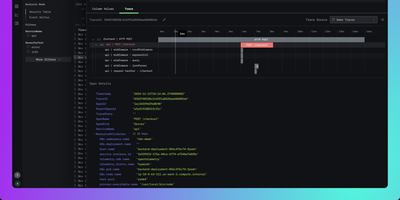
HyperDX correlates logs, metrics, traces, session replays, and errors in a single interface so engineers can resolve production incidents in minutes instead of hours. Nearly 10,000 GitHub stars reflect its role as the integrated UI layer for the ClickStack blueprint endorsed by ClickHouse. The platform connects to any ClickHouse cluster as its storage backend, working with existing table structures without requiring data migration or proprietary ingestion formats. An intuitive Lucene-like search syntax supports full-text queries and property filtering like level:err or service.name:api without needing SQL, while native JSON string querying and event delta analysis surface anomalies in high-cardinality datasets. One-click cross-signal correlation lets you jump from a log line to its distributed trace, from a slow span to associated logs, or from a frontend session replay to the backend errors it triggered. The OpenTelemetry Collector accepts telemetry via OTLP on gRPC port 4317 and HTTP port 4318, supporting automatic instrumentation for Node.js, Python, Java, Go, Ruby, and browser applications. APM tracks HTTP request latency, database query duration, and external service calls with trace waterfall visualizations. Configurable alerts trigger via webhook, Slack, PagerDuty, or email when thresholds are breached. Deploys via Docker Compose with ClickHouse, MongoDB, Redis, and the OpenTelemetry Collector. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
OpenSearch
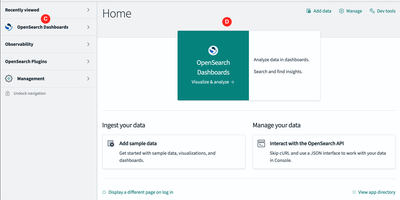
OpenSearch is a search and analytics platforms, powering full-text search, log analytics, observability, and AI-powered vector retrieval at petabyte scale. The distributed engine provides BM25 full-text search alongside k-NN vector search using NMSLIB, Faiss, and Lucene libraries, enabling semantic search, hybrid search combining keyword and vector scoring through normalization processors, neural sparse search, and retrieval-augmented generation workflows with built-in ML Commons for model hosting. OpenSearch Dashboards delivers interactive visualization with Discover for log exploration, custom dashboards, alerting, anomaly detection using Random Cut Forest algorithms, and Security Analytics with detection rules mapped to MITRE ATT&CK. Native Prometheus integration with full PromQL support unifies metrics alongside logs and traces in a single observability interface, while Data Prepper handles telemetry ingestion from OpenTelemetry collectors, Fluent Bit, and Logstash-compatible pipelines. SQL and Piped Processing Language queries with a visual PPL builder enable analysts to query data without learning the native DSL. Index State Management automates index lifecycle with rollover, shrink, and delete policies, while cross-cluster replication and searchable snapshots on S3-compatible storage provide disaster recovery. Scoped API keys, field-level security, document-level security, and audit logging deliver enterprise-grade access control. Docker Compose deploys multi-node clusters alongside the Kubernetes operator for orchestrated production environments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Fess
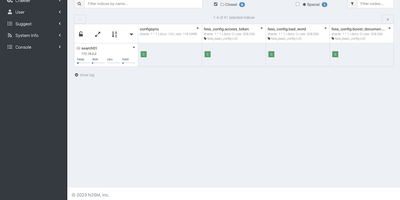
Eliminate indexing blind spots across fragmented company networks with Fess, a distributed enterprise search engine that crawls internal document repositories, corporate intranets, and cloud services to provide employees with instant, permission-aware file discovery. Organizations can schedule automated crawlers across web pages, network shares, databases, and third-party storage platforms to extract text and generate visual thumbnails from PDFs, spreadsheets, presentations, and compressed archives. Users can search indexed records using natural language queries, filtering results by file metadata, creation dates, categories, and geographic coordinates while viewing contextual snippets with highlighted keyword matches. Granular role-based permissions mirror directory security structures from Active Directory and LDAP so staff only see search results for documents they have explicit authorization to inspect. The browser-based administrative console lets operations teams define path mapping rules, manage virtual hosts, monitor active crawl jobs, inspect error logs, and configure scheduled re-indexing workflows without modifying server configuration files. Security teams can establish single sign-on across the organization using SAML or OpenID Connect authentication providers to secure administrative workflows and search portals. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Elasticsearch
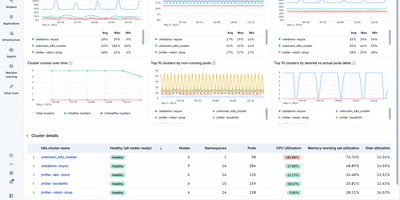
With over 70,000 GitHub stars and billions of documents indexed across enterprises like Uber, Netflix, and Wikipedia, Elasticsearch is the world's most deployed search engine, powering everything from application search to security analytics and AI-driven retrieval. Built on Apache Lucene, its inverted index architecture delivers sub-second full-text search across terabytes of data with BM25 relevance scoring, configurable analyzers for 30+ languages, and fuzzy matching for typo tolerance. The kNN vector search API uses the HNSW algorithm for approximate nearest neighbor queries on dense and sparse embeddings up to 4,096 dimensions, while reciprocal rank fusion enables hybrid search that combines lexical and semantic signals in a single query. Elasticsearch's aggregation framework supports metric, bucket, and pipeline aggregations for real-time analytics directly on indexed data without separate OLAP infrastructure. The cluster distributes data across shards with automatic rebalancing, replica allocation, and cross-cluster search for multi-datacenter deployments. Kibana provides the visualization layer with dashboards, Lens visual editor, Canvas for pixel-perfect reports, and Discover for ad-hoc log exploration. Ingest pipelines with processors like grok, dissect, GeoIP enrichment, and inference handle data transformation at index time, and ES|QL brings pipe-based query syntax with joins and columnar processing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL v3 licensed.
Elasticvue
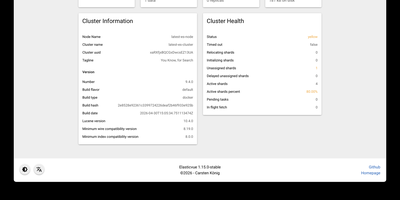
Elasticvue is a graphical interface for Elasticsearch where you can inspect cluster health, browse indices, search and edit documents, and send REST queries. Start on the Home tab, which summarizes status, nodes, shards, indices, document counts, and disk usage. Nodes shows load, CPU, RAM, heap, and disk for each member, and Shards lays out every primary and replica in a grid with a switch for shard allocation. Indices handles creation, aliases, templates, and bulk actions. Search runs query string searches across an index pattern, opens any hit in a JSON editor for updates or deletion, and downloads results as JSON. Rest sends any request from tabbed editors with history, saved queries, and examples, while Snapshots manages repositories and backups. Version 1.16 adds user and role management for Elasticsearch clusters. Secured clusters connect with basic authentication, API keys, or AWS IAM credentials, and the Docker image preloads cluster definitions from an environment variable or a mounted JSON file. Elasticvue supports every Elasticsearch version, even end-of-life releases, and speaks English, Chinese, French, Russian, Japanese, and Italian. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Parseable
Parseable replaces expensive Elasticsearch clusters and fragmented monitoring stacks with a single Rust binary that ingests, queries, and stores logs, metrics, and traces on commodity object storage at a fraction of the cost. The data lake architecture decouples stateless compute from S3-compatible storage, enabling independent scaling of ingestion throughput and query capacity while cutting storage costs by up to 90% compared to indexed alternatives. OpenTelemetry-native OTLP ingestion accepts telemetry from existing OTel collector pipelines, Prometheus Remote Write endpoints, Kafka consumers, eBPF probes, and popular logging agents including Fluentd, Fluent Bit, and Vector without proprietary format conversions. The SQL-first query interface enables cross-signal analysis across all telemetry types, while native PromQL support with 50+ functions and 12 aggregation operators provides Prometheus-compatible metrics querying that works directly with Grafana dashboards. Built-in features include customizable dashboards, real-time alerting with Webhook, Slack, and Alertmanager targets, role-based access control, OpenID single sign-on integration, LogIQ automatic unstructured-to-structured log transformation, smart caching for frequently accessed data, and retention policies for lifecycle management. AI-powered Keystone Q&A provides natural language to SQL conversion and dataset summarization. All data stored as standard Apache Parquet on object storage remains accessible to any Parquet-compatible engine (DuckDB, Spark, Trino), ensuring zero vendor lock-in. Deploys on AWS S3, Azure Blob, Google Cloud Storage, MinIO, Wasabi, and DigitalOcean Spaces. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.