Stars
Forks
Watchers
Developer links
Fess
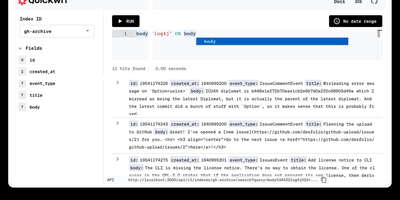
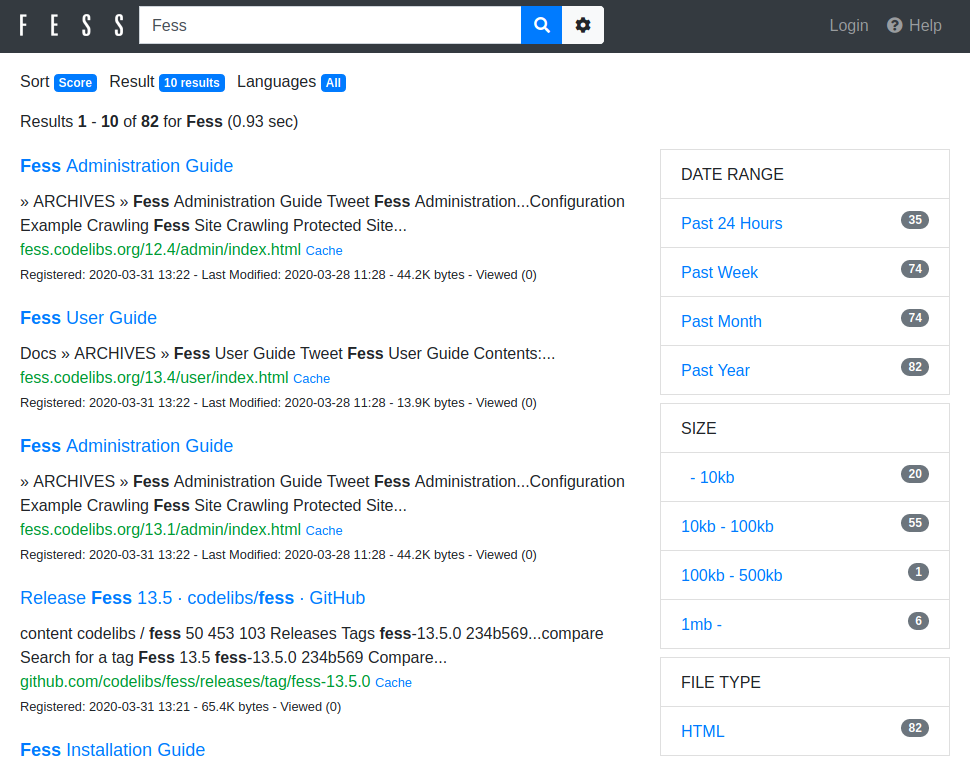
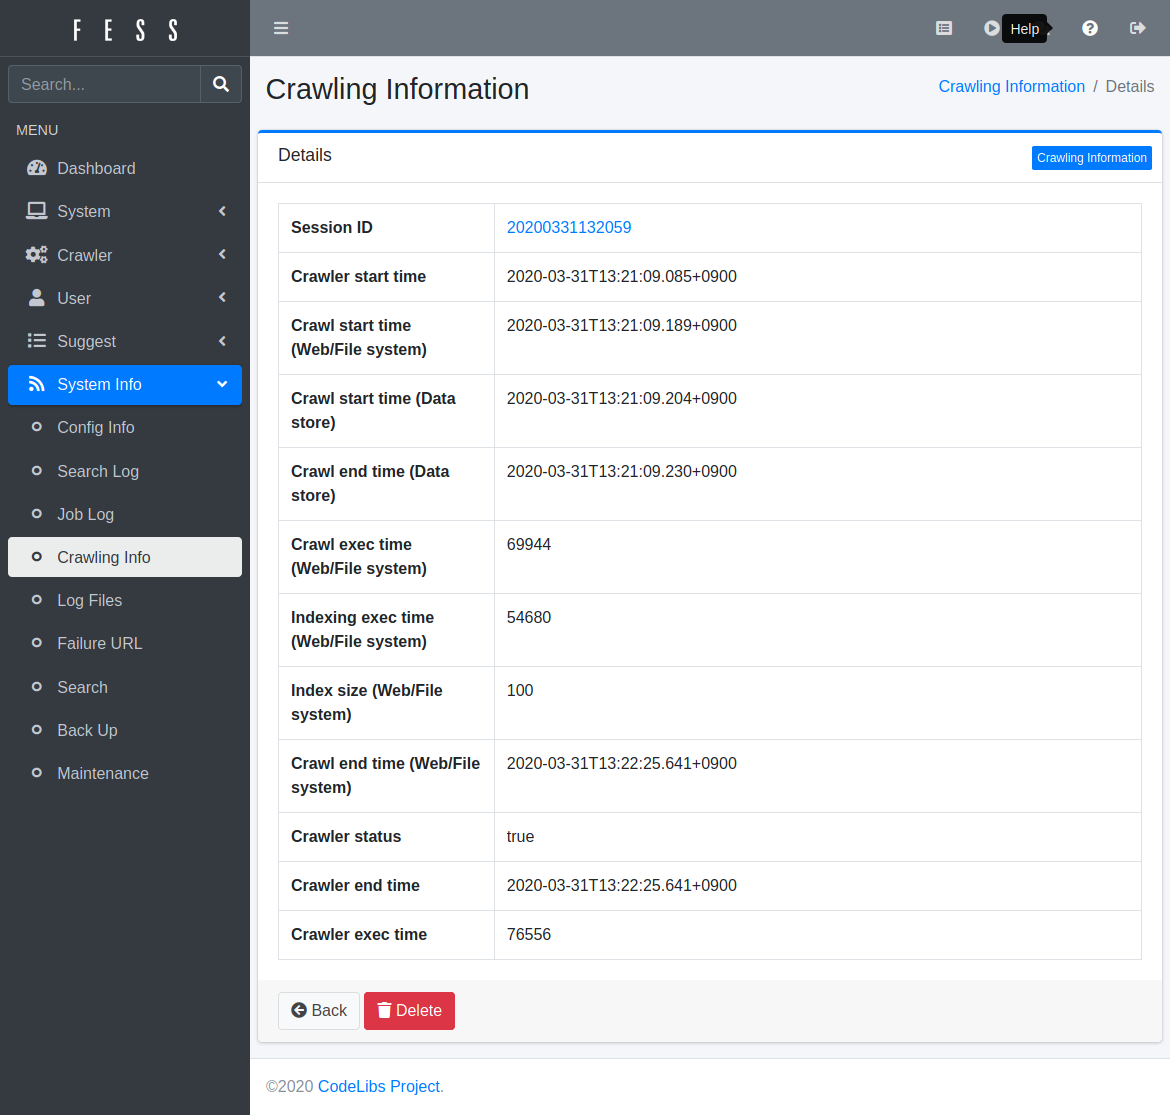
Eliminate indexing blind spots across fragmented company networks with Fess, a distributed enterprise search engine that crawls internal document repositories, corporate intranets, and cloud services to provide employees with instant, permission-aware file discovery. Organizations can schedule automated crawlers across web pages, network shares, databases, and third-party storage platforms to extract text and generate visual thumbnails from PDFs, spreadsheets, presentations, and compressed archives. Users can search indexed records using natural language queries, filtering results by file metadata, creation dates, categories, and geographic coordinates while viewing contextual snippets with highlighted keyword matches. Granular role-based permissions mirror directory security structures from Active Directory and LDAP so staff only see search results for documents they have explicit authorization to inspect. The browser-based administrative console lets operations teams define path mapping rules, manage virtual hosts, monitor active crawl jobs, inspect error logs, and configure scheduled re-indexing workflows without modifying server configuration files. Security teams can establish single sign-on across the organization using SAML or OpenID Connect authentication providers to secure administrative workflows and search portals. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Benefits
- Universal Multi-Source Document Crawling
- Crawls web portals, Windows network shares, relational databases, and S3-compatible cloud storage buckets to extract text, metadata, and preview thumbnails from documents, spreadsheets, and archives without external indexing services.
- Strict Document-Level Access Control
- Integrates with Active Directory and LDAP hierarchies to inherit existing file system access control lists, ensuring employees only view search results and text snippets for documents they are authorized to access.
- Centralized Administrative Crawler Management
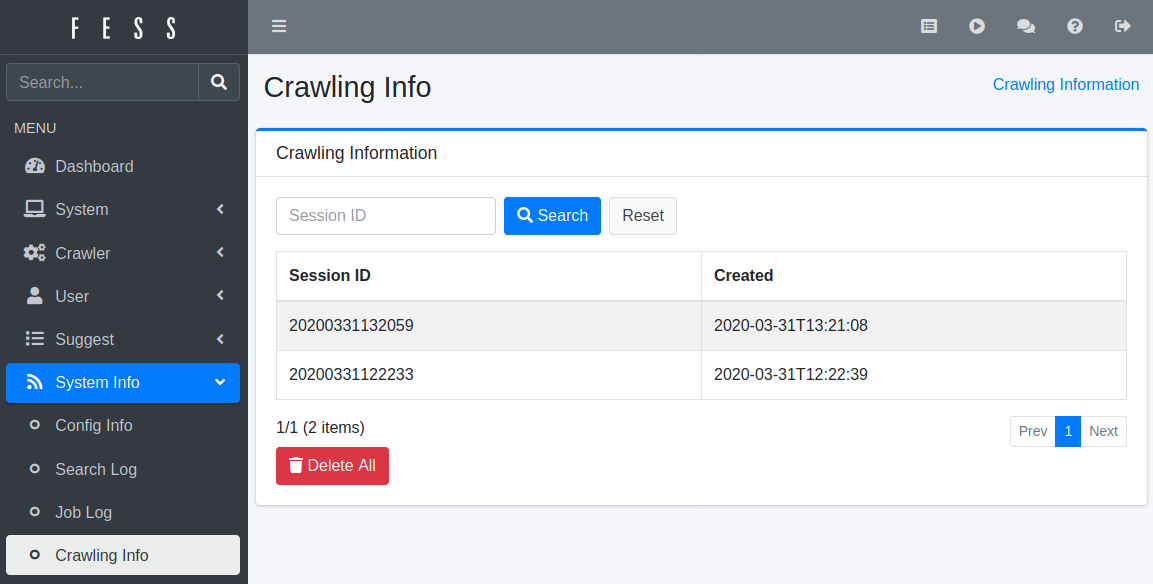
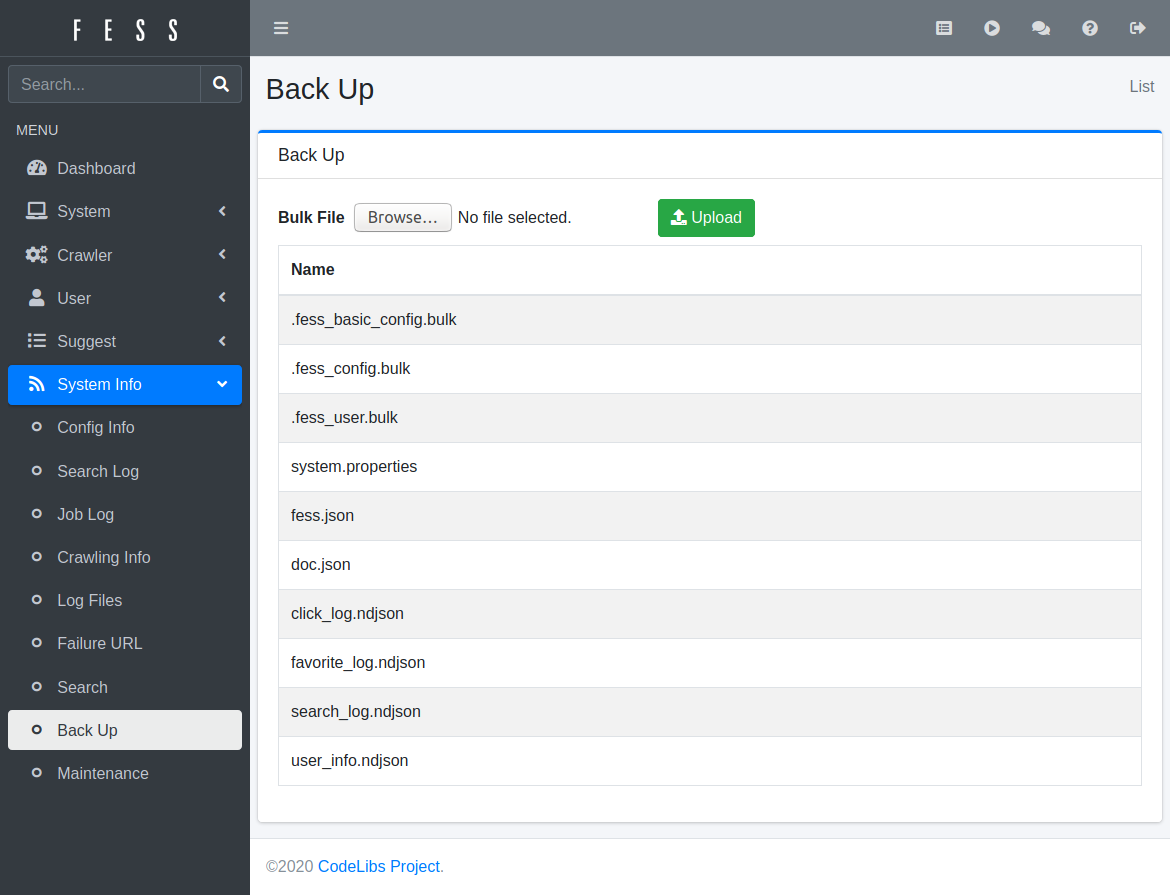
- Provides a web dashboard to configure crawling schedules, inspect detailed execution logs, establish path mapping rules, manage virtual hosts, and trigger full backup or restore operations directly from your browser.
- Faceted Multi-Language Search Experience
- Delivers query auto-completion, contextual keyword highlighting, thumbnail previews, geospatial filtering, and faceted drill-downs across more than twenty global languages using optimized distributed search cluster indexes.
Features
- Automated Web and File Crawling
- Schedules automated crawlers for SMB shares, HTTP sites, and relational databases with customizable path exclusion rules and depth limits.
- OpenSearch Distributed Indexing
- Leverages an OpenSearch cluster engine to deliver sub-second query response times, distributed fault tolerance, and scalable multi-node text indexing.
- Enterprise Single Sign-On
- Authenticates users via SAML 2.0, OpenID Connect, and CAS protocols to enforce organizational identity policies across search endpoints.
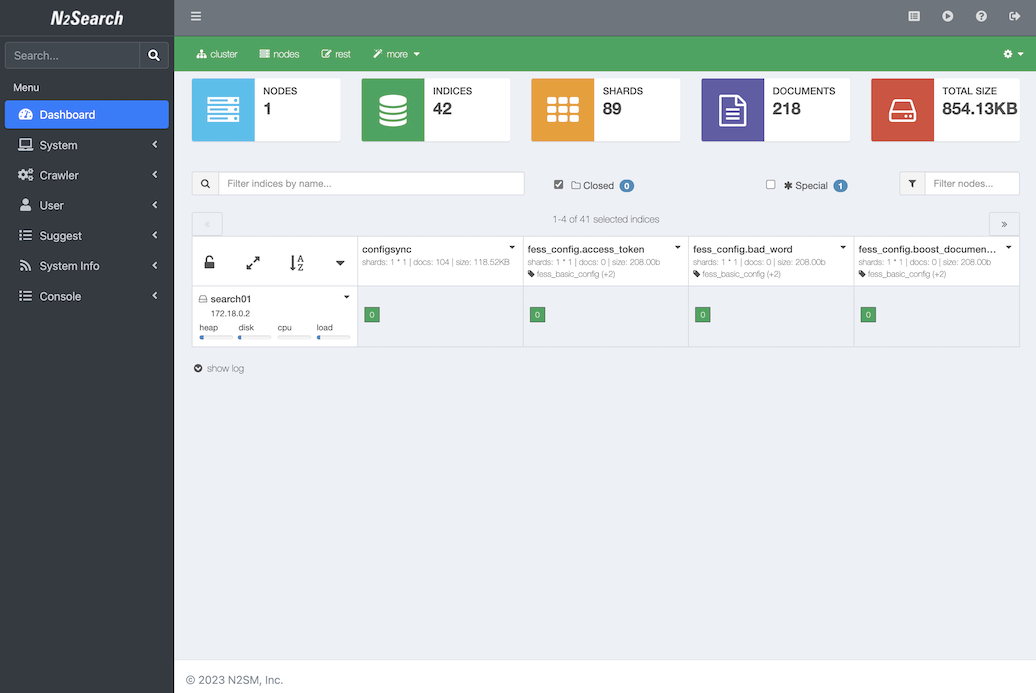
- Rich File Format Extraction
- Extracts searchable content and metadata from PDF, Microsoft Office, HTML, XML, and compressed archives using built-in parsing libraries.
- Comprehensive REST API
- Exposes full JSON search and administrative endpoints allowing external applications to query documents and automate crawler job scheduling programmatically.