Stars
Forks
Watchers
Developer links
ParadeDB
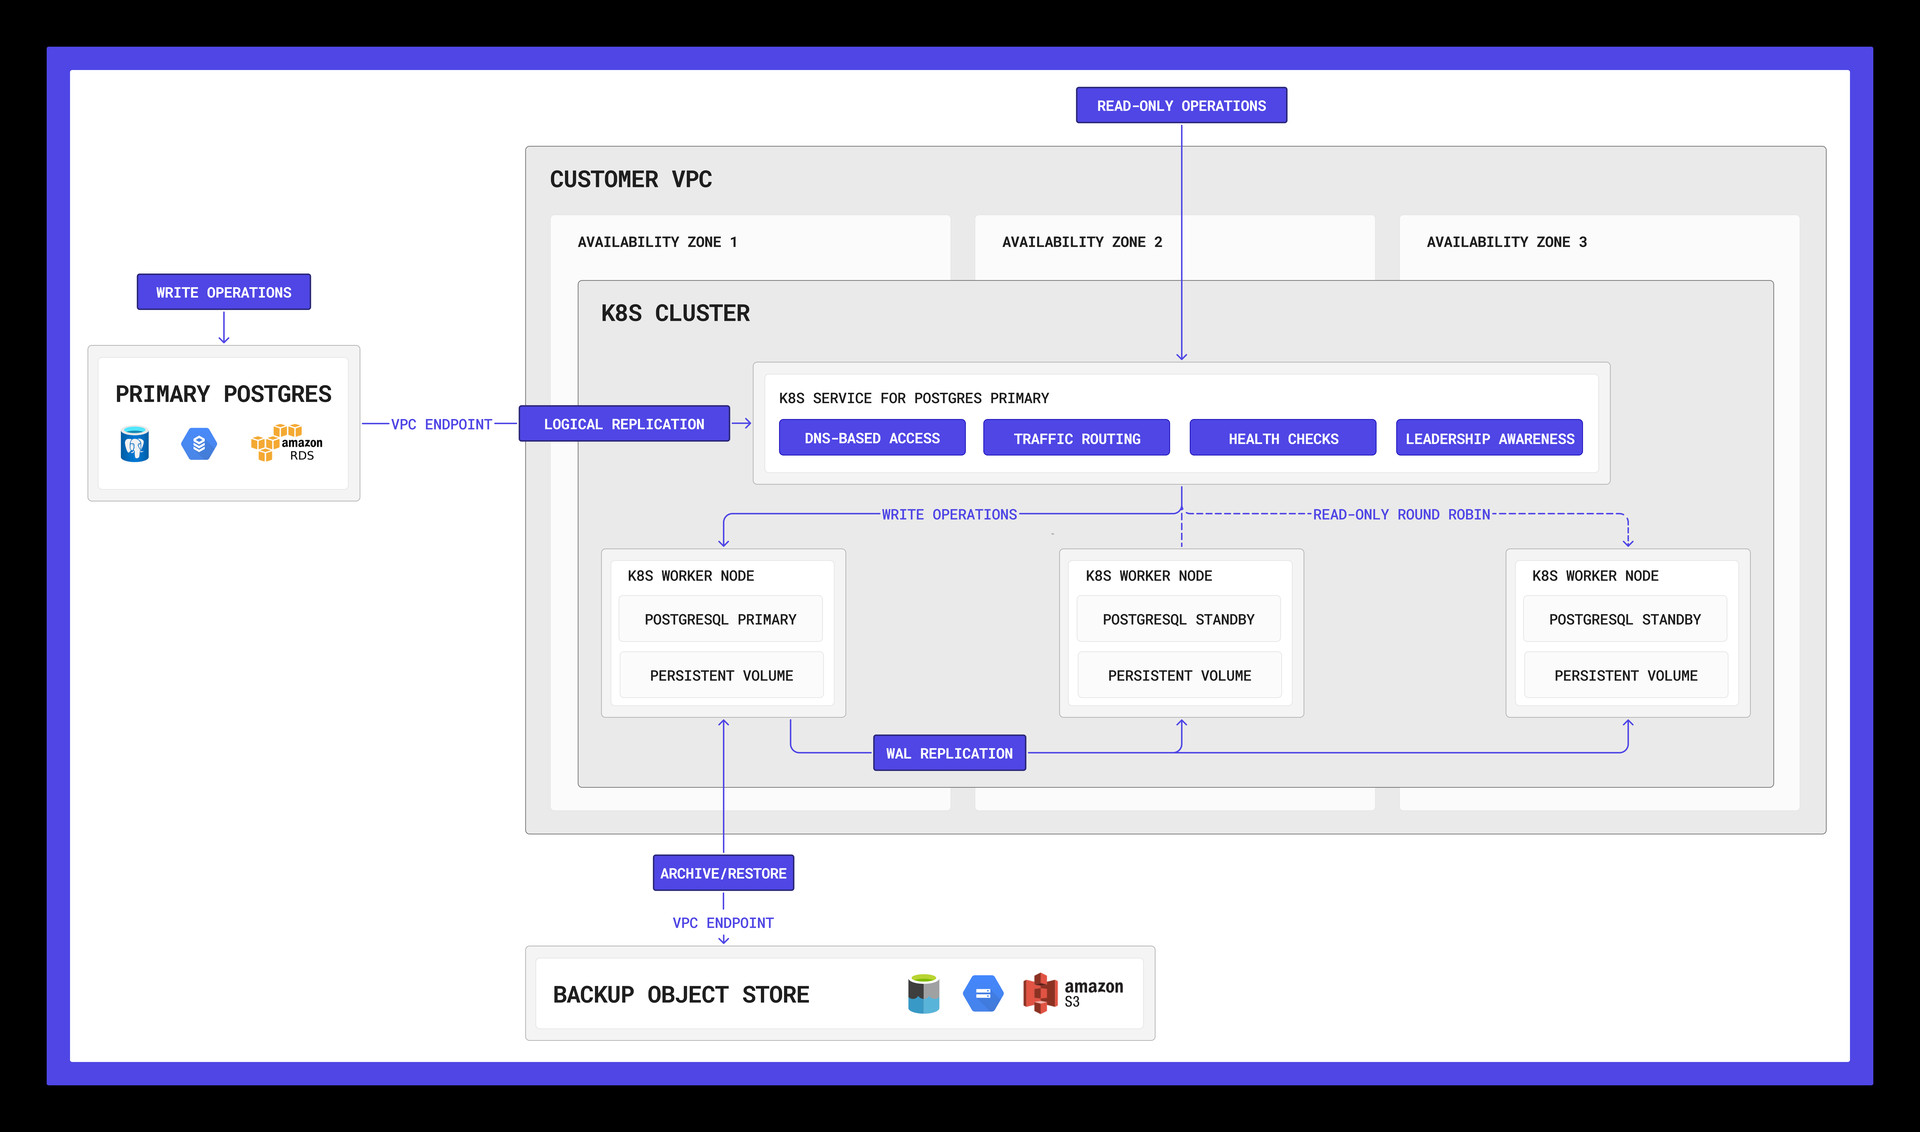
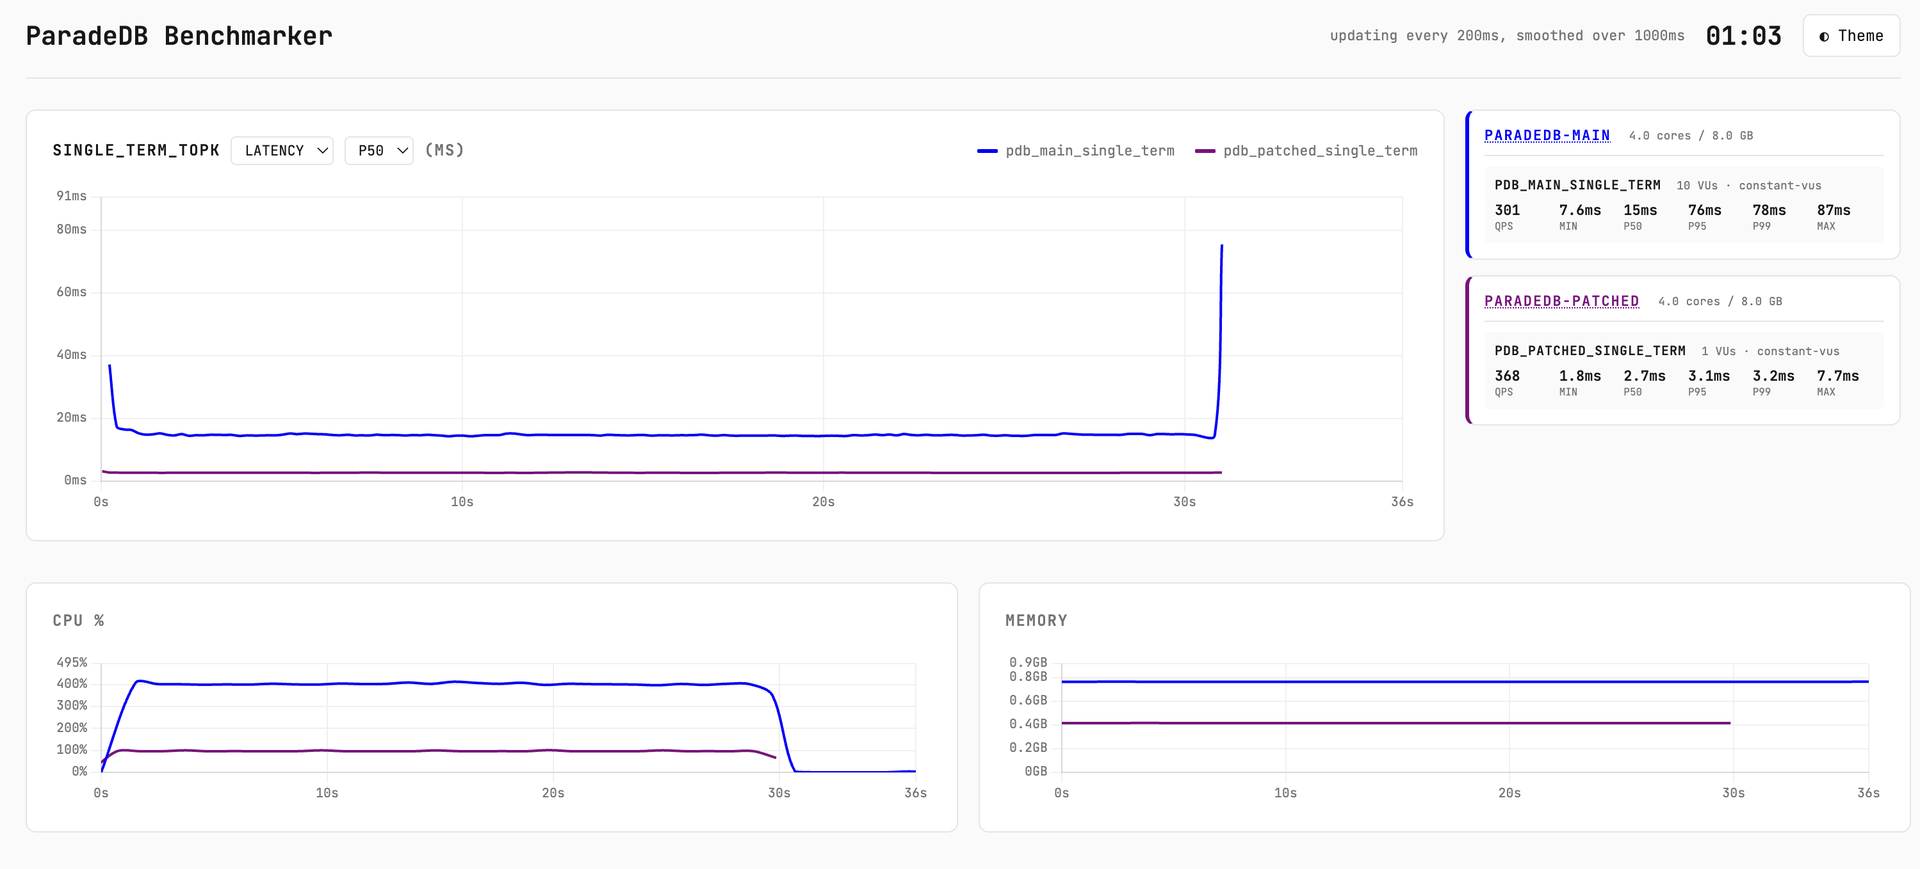
ParadeDB turns the Postgres you already run into a full search and analytics engine, so your application data, full-text search, vector retrieval, and aggregations all live in one database. Create one ParadeDB index over a table and you can run relevance-ranked BM25 queries with tokenizers, phrase matching, highlighting, and Top-K retrieval using plain SQL. The same index stores pgvector embeddings, so similarity search composes with text predicates and filters, and hybrid queries fuse both rankings when a question needs keywords and meaning at once. Aggregations push into the index too: ordinary GROUP BY queries accelerate, and Elasticsearch-style JSON aggregations return facets, histograms, percentiles, and cardinality for filterable search interfaces. Because the index updates in the same transaction as your writes, search results are never stale and there is no ETL pipeline, sync job, or second system to babysit. JOINs against the rest of your schema keep working, since search is just another index inside your system of record. Teams typically retire a separate search cluster while keeping sub-second relevance search, semantic retrieval for AI features, and faceted analytics on the data they already store. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Benefits
- One Database, No Sync
- Search indexes update in the same transaction as your writes, so results are never stale and there is no ETL pipeline, sync job, or second search cluster to operate.
- BM25 And Vectors Together
- A single index holds text and pgvector embeddings, letting keyword relevance, similarity search, filters, and hybrid rank fusion compose inside one SQL query.
- Facets Without Extra Systems
- Native SQL aggregates accelerate on the columnar index, and JSON aggregations return facets, histograms, percentiles, and cardinality for building filterable search interfaces.
- Plain SQL Throughout
- Queries, JOINs, transactions, backups, and permissions stay ordinary Postgres, so your existing tooling, drivers, and operational knowledge keep working unchanged.
Features
- BM25 Full-Text Search
- Relevance-ranked text queries with configurable tokenizers, phrase and fuzzy matching, highlighting, and Top-K retrieval, all expressed in standard SQL.
- Native Vector Search
- pgvector embeddings indexed with a SPANN-style structure support cosine, L2, and inner-product similarity that composes with filters and text predicates.
- Hybrid Rank Fusion
- Reciprocal Rank Fusion blends BM25 scores and vector distances into one ranking when queries need both exact terms and semantic closeness.
- Accelerated Aggregates
- COUNT, SUM, GROUP BY, and FILTER push into the columnar index, while pdb.agg JSON aggregations provide facets, histograms, and percentiles.
- Transactional Indexing
- Index maintenance happens inside the writing transaction under MVCC, so concurrent readers see consistent search results without external coordination.
- Extension, Not A Fork
- pg_search installs into standard Postgres as an extension, and the ParadeDB Docker image bundles it when you prefer a ready-made server.