Categories
Database Search Engine Real-Time Analytics Full-Text Search Vector Search Enterprise Search Information RetrievalStars
Forks
Watchers
Developer links
Apache Solr
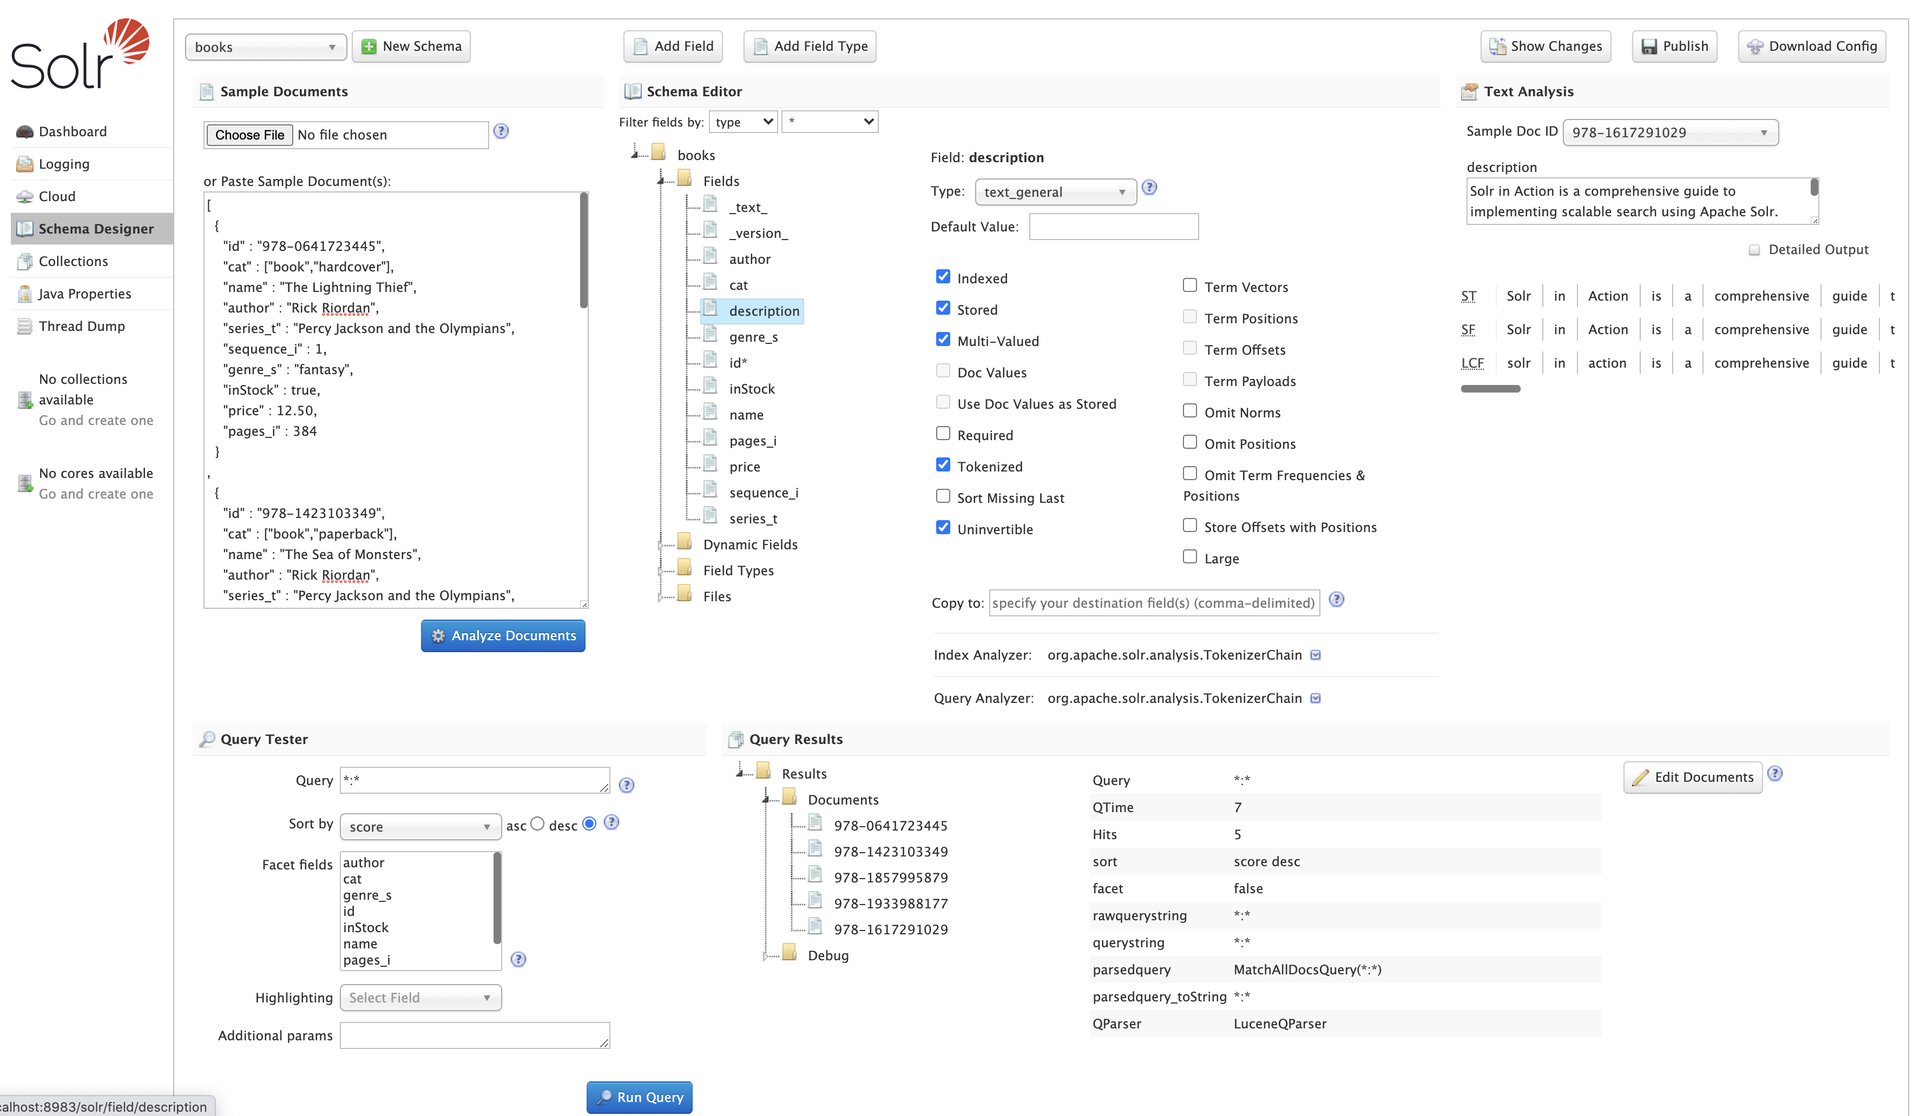
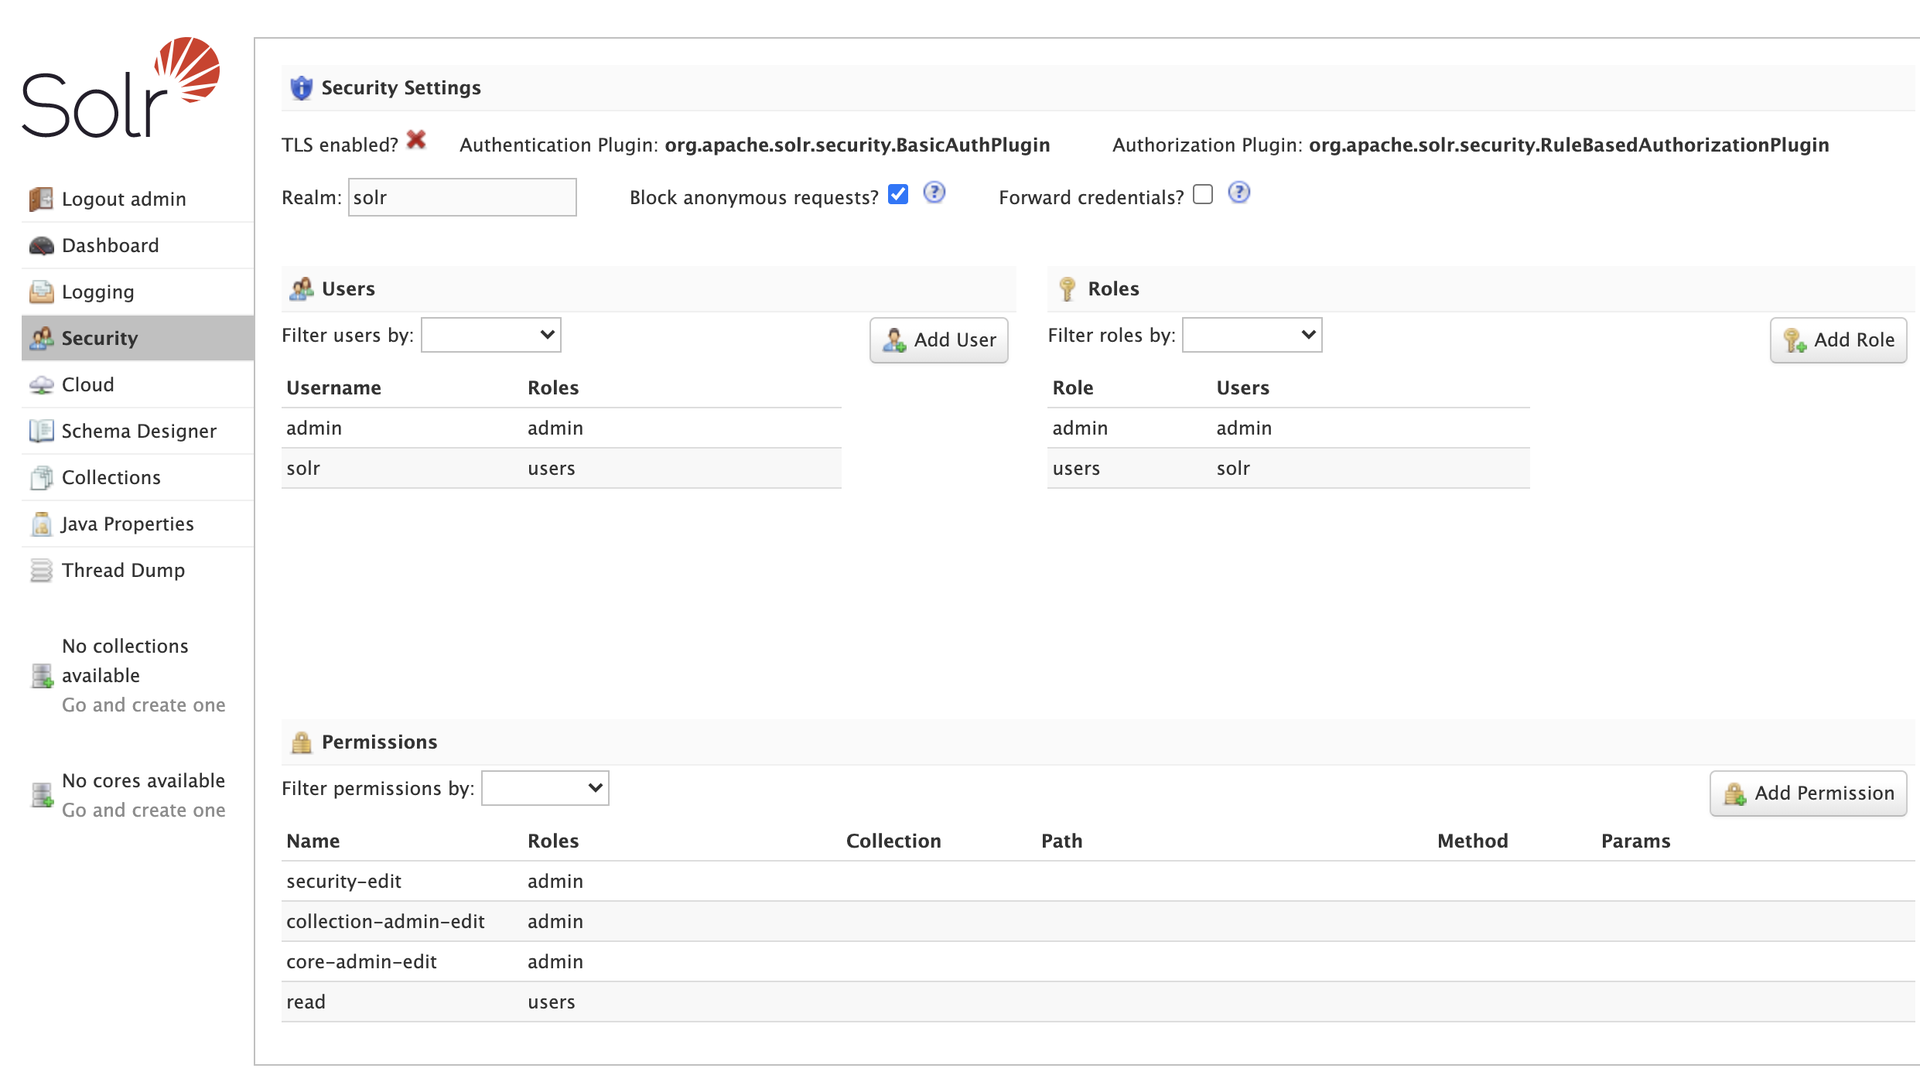
Product catalogs, help centers, and document archives all fail the same way: visitors type a few words, get the wrong results, and leave. Apache Solr is the search platform behind fast, relevant answers, returning ranked matches with faceted filters, highlighted snippets, spell suggestions, and geospatial distance in a single query. Index documents through HTTP updates or data import handlers, shape fields in the schema, and watch changes appear through near-real-time indexing without rebuilding the corpus. SolrCloud turns one index into a distributed collection: shards split large corpora across nodes, replicas copy each shard for failover and query load, and ZooKeeper coordinates configuration so every node serves the same schema. Dense vector fields store embeddings beside your text, and the KNN parser retrieves nearest neighbors through HNSW graphs, so semantic search runs in the same engine as keyword search instead of a second system. A combined query handler merges keyword and vector rankings with reciprocal rank fusion, and an enrichment processor can call language models at index time to tag or summarize documents as they arrive. Streaming expressions add analytics over results, from rollups and percentiles to joins across collections, while JWT authentication and authorization rules protect the admin console and APIs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Benefits
- One Engine, Every Search
- Full-text ranking, faceting, highlighting, spellchecking, geospatial queries, and dense vector KNN retrieval live in one platform, so applications stop stitching keyword search and semantic search together from separate systems.
- Hybrid Ranking Built In
- The combined query handler merges keyword and vector result sets with reciprocal rank fusion, and reranking controls fine-tune the top results, giving AI search interfaces one consistent relevance pipeline.
- Clusters That Self Coordinate
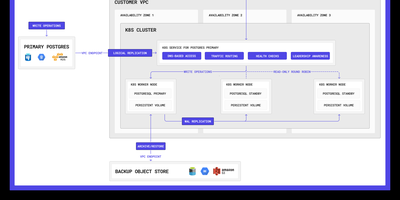
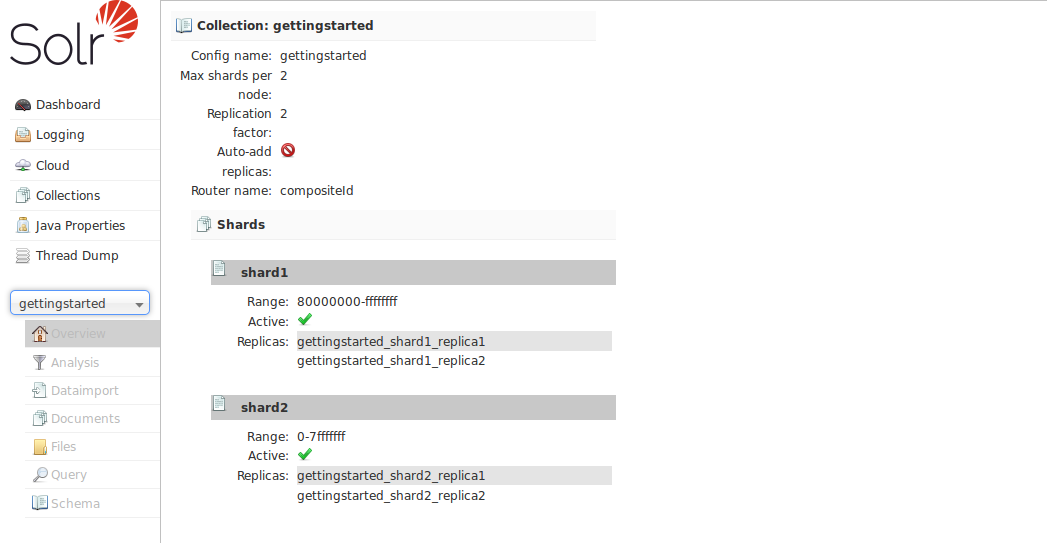
- SolrCloud manages collections as shards and replicas with ZooKeeper-held configsets, automatic failover, and centralized schema changes, so capacity and availability grow by adding nodes instead of rearchitecting the index.
- Enrichment At Index Time
- Update processors can enrich documents as they are indexed, including language-model tagging and summarization, so search results carry useful metadata without a separate preprocessing pipeline feeding the index.
Features
- Lucene Full-Text Search
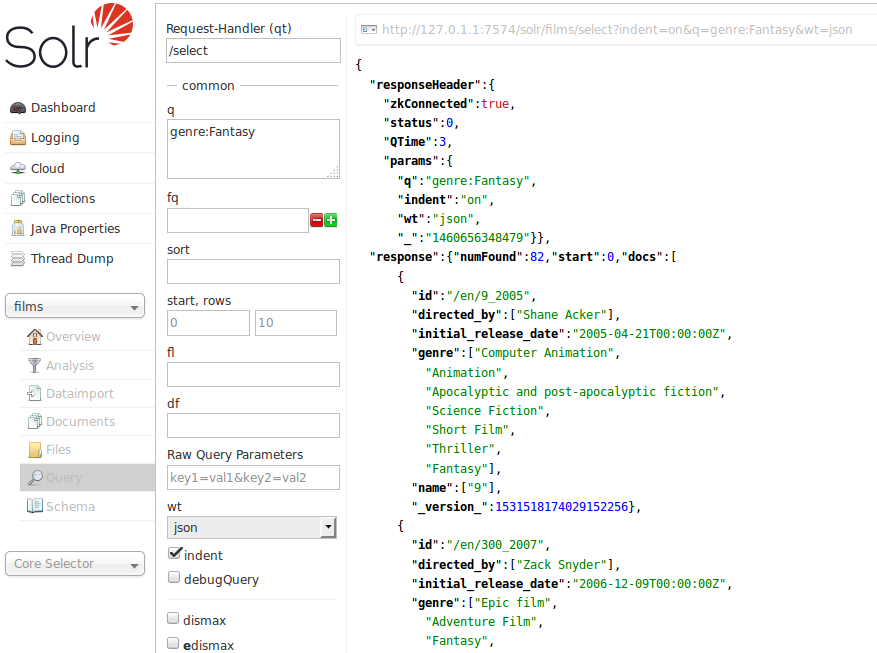
- Apache Lucene inverted indexes power ranked full-text queries with faceting, highlighting, spellchecking, suggesters, and MoreLikeThis recommendations across document collections of any size.
- Dense Vector Fields
- DenseVectorField stores float embeddings and the knn query parser retrieves nearest neighbors over HNSW graphs with cosine, euclidean, or dot-product similarity functions.
- SolrCloud Collections API
- The Collections API creates, splits, reloads, and rebalances collections whose shards and replicas are coordinated through ZooKeeper with centralized configset management.
- Streaming Expressions Analytics
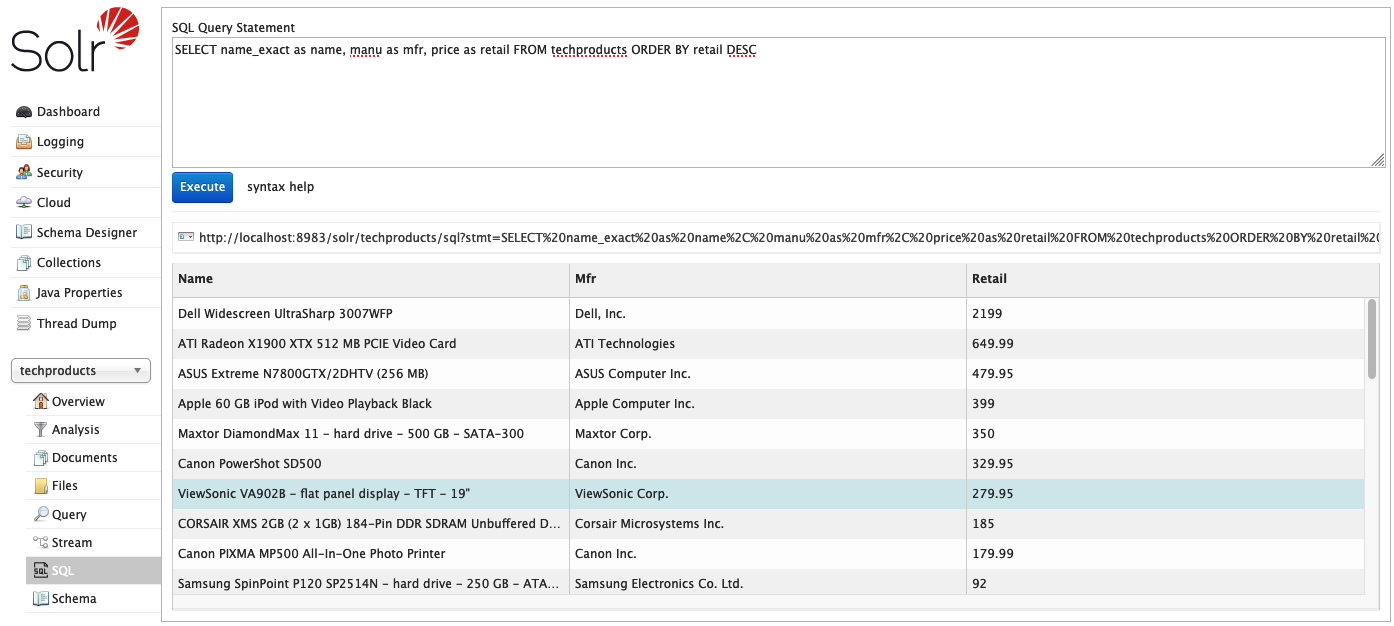
- Streaming expressions compute rollups, percentiles, count-distinct, joins, and graph traversals over search results, turning the search index into an analytics source for dashboards.
- Admin UI And APIs
- A web admin console shows cores, collections, schemas, and query performance, while REST-like HTTP APIs drive indexing, querying, and cluster administration from any client.