Octopus
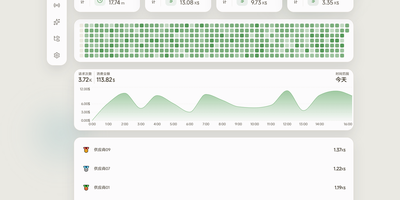
Juggling separate API keys, incompatible payload schemas, and unpredictable rate limits across OpenAI, Anthropic, and Google Gemini slows down every AI workflow, and Octopus solves it by consolidating all your upstream model providers into one self-hosted API gateway. Point Claude Code, OpenAI Codex CLI, or any SDK client at a single gateway URL and translate requests transparently between OpenAI Chat Completions, OpenAI Responses, Anthropic Messages, and Google Gemini endpoints without modifying client code. Group multiple provider channels under a unified model alias so your coding agents automatically fail over to backup providers and shield active tasks from upstream HTTP errors or rate limits. Watch live end-to-end request routing on the interactive topology canvas as prompts flow from client applications through model groups to specific upstream channels. Synchronize available model catalogs directly from connected providers and pull up-to-date token pricing from models.dev, or define custom per-million input, output, and cache-read rates for private deployments. Inspect detailed request logs, monitor token consumption trends, and audit daily API spend across every channel from the web dashboard. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Deploy