Agenta
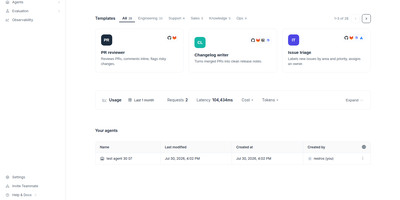
Agenta delivers a comprehensive open-source LLMOps workspace that covers the full lifecycle of AI application development — from prompt engineering through production monitoring. The platform supports 15+ model providers including OpenAI, Anthropic, Google Gemini, Mistral, Groq, Together AI, Azure, AWS Bedrock, and self-hosted models via Ollama, enabling teams to switch between providers without code changes. The prompt playground allows side-by-side comparison of different configurations, while the evaluation system offers LLM-as-a-Judge assessment, 20+ pre-built evaluators covering semantic similarity, regex matching, and factual accuracy, plus custom Python evaluators for domain-specific requirements. Teams run evaluations through both the web UI for subject matter experts and the Evaluation SDK for programmatic CI/CD integration. The observability layer captures full trace visibility across complex agentic workflows, flagging quality issues like hallucinations and off-topic responses in real time. Human annotation workflows let domain experts review and annotate LLM outputs, feeding corrections back into the evaluation loop. The architecture supports Chain of Prompts, RAG pipelines, and multi-step agent workflows, integrating with frameworks like LangChain and LlamaIndex. Self-hosting deploys via Docker Compose with Traefik for routing, requiring only a clone, environment configuration, and a single docker compose command. On RepoCloud, deploy Agenta on a dedicated VPS with root SSH access, persistent storage for evaluation datasets and traces, and complete control over model provider credentials, all under the MIT license with no usage restrictions.
LangWatch
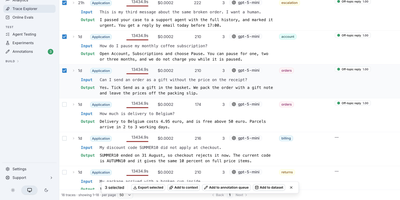
Every call your AI agents make becomes a searchable trace in LangWatch, and the same platform tests and scores those agents before a new prompt or model reaches users. The Trace Explorer filters by origin, user, model, cost, and evaluator, reads each run as a waterfall, flame graph, topology, or sequence diagram, and takes traces from the Python, TypeScript, and Go SDKs or any OpenTelemetry source. Agent Testing sends simulated users, in text or beta voice calls, through your agent while a judge passes or fails every criterion with its reasoning, adds multi-turn red teaming, and compares two agents side by side. The Experiments workbench scores prompts and agents on datasets with LLM judges, exact match, and RAG checks, then compares runs on cost, latency, and pass rate, while online evaluations monitor live traffic and guardrails block unsafe replies. Prompts keep version history and staging or production tags, Workflows wire prompts, Python code, and HTTP calls on a visual canvas, and annotation queues route traces to human reviewers. Alerts fire when a graph crosses a threshold, automations post to Slack, email, or webhooks, and scheduled reports go out by email or Slack. Claude Code, Codex, Copilot, Gemini CLI, and opencode report session cost, pull request cost, and terminal replays, and an MCP server exposes trace search and prompt management to coding assistants. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.