Categories
Self-Hosted Developer Tools AI Infrastructure API Management LLM Gateway Model Routing MCP Gateway LLMOpsStars
Forks
Watchers
Developer links
FastLLM Proxy
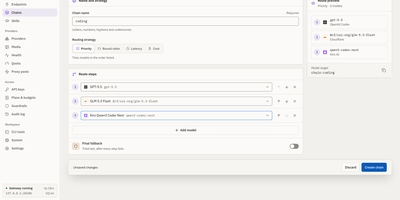
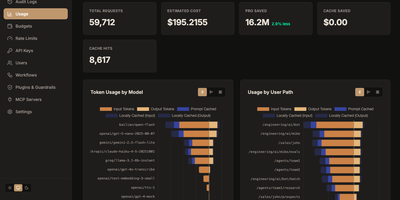
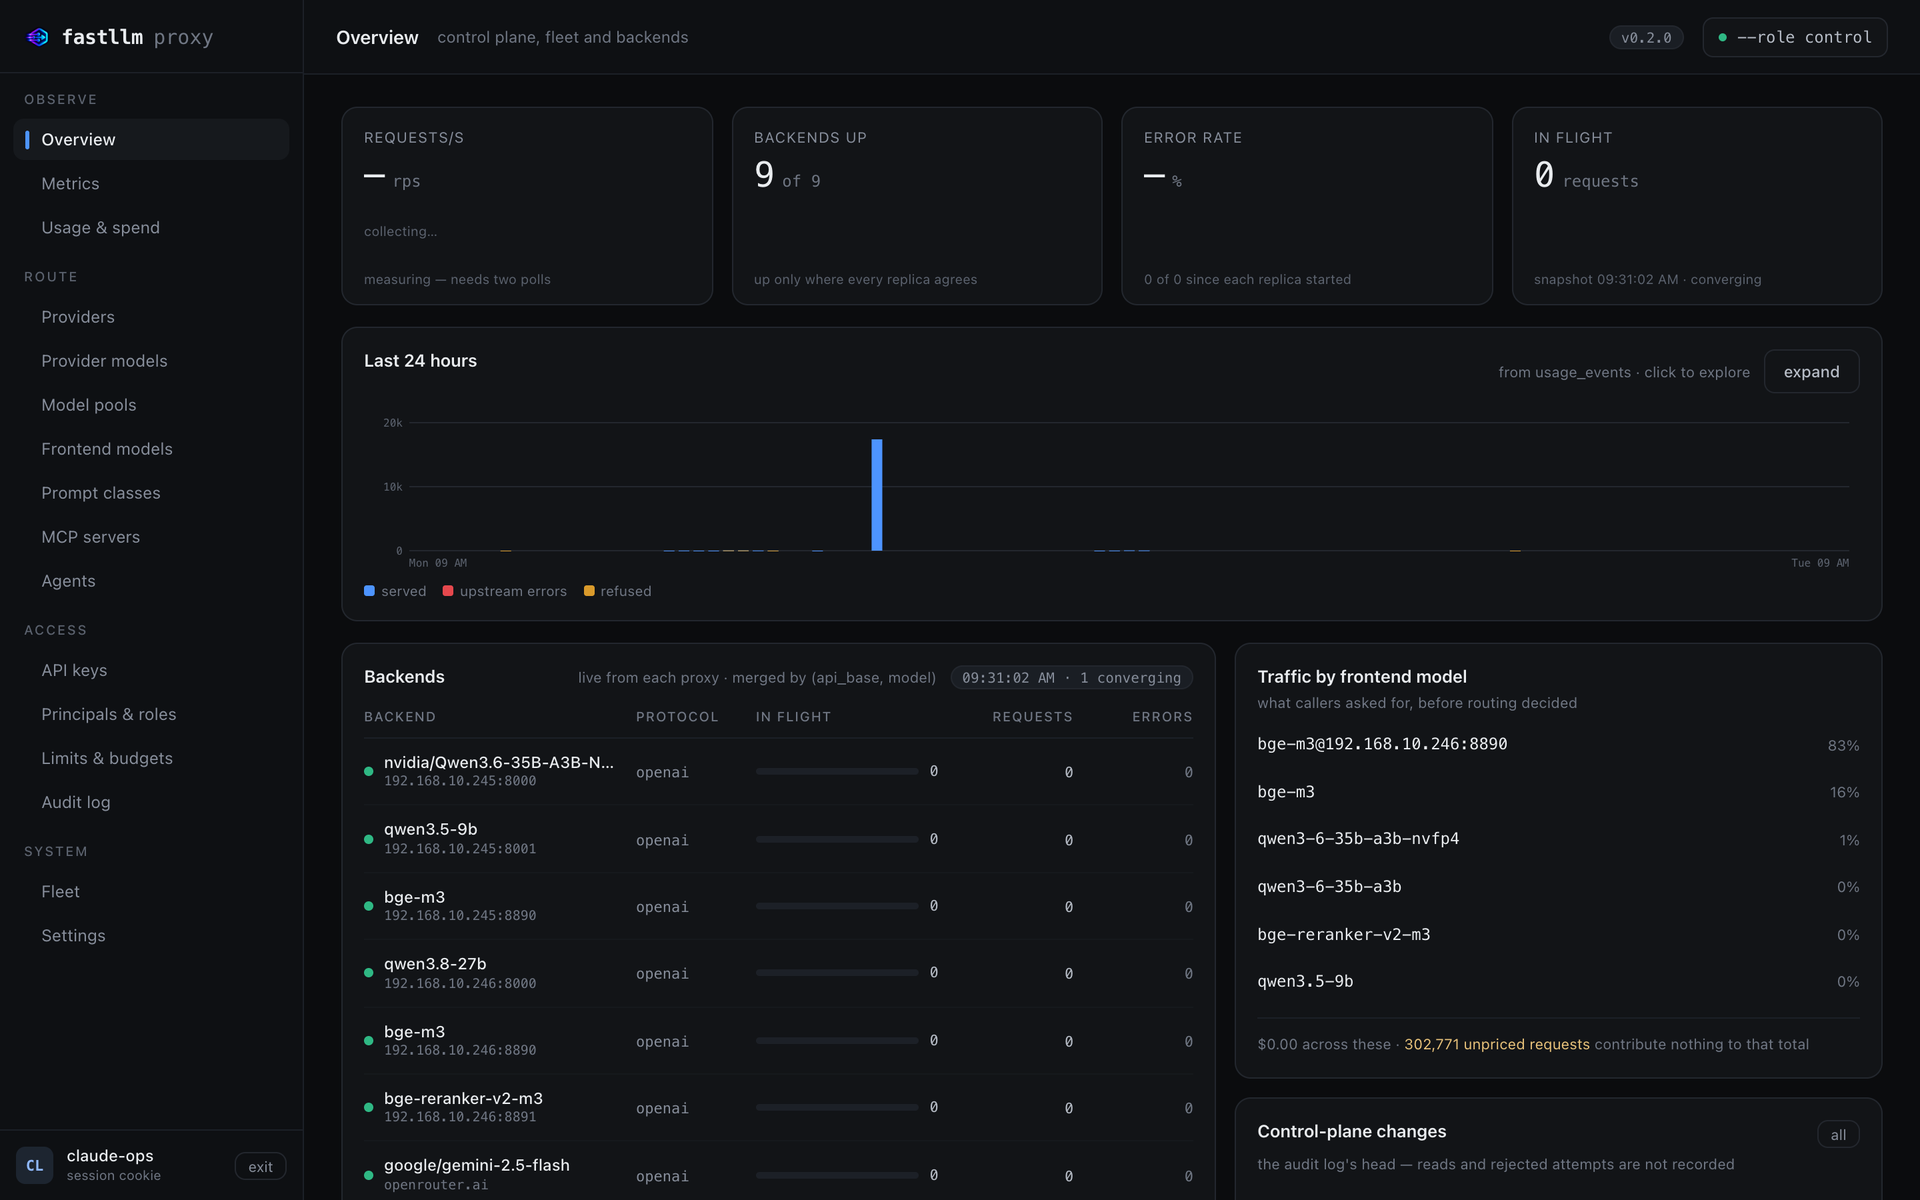
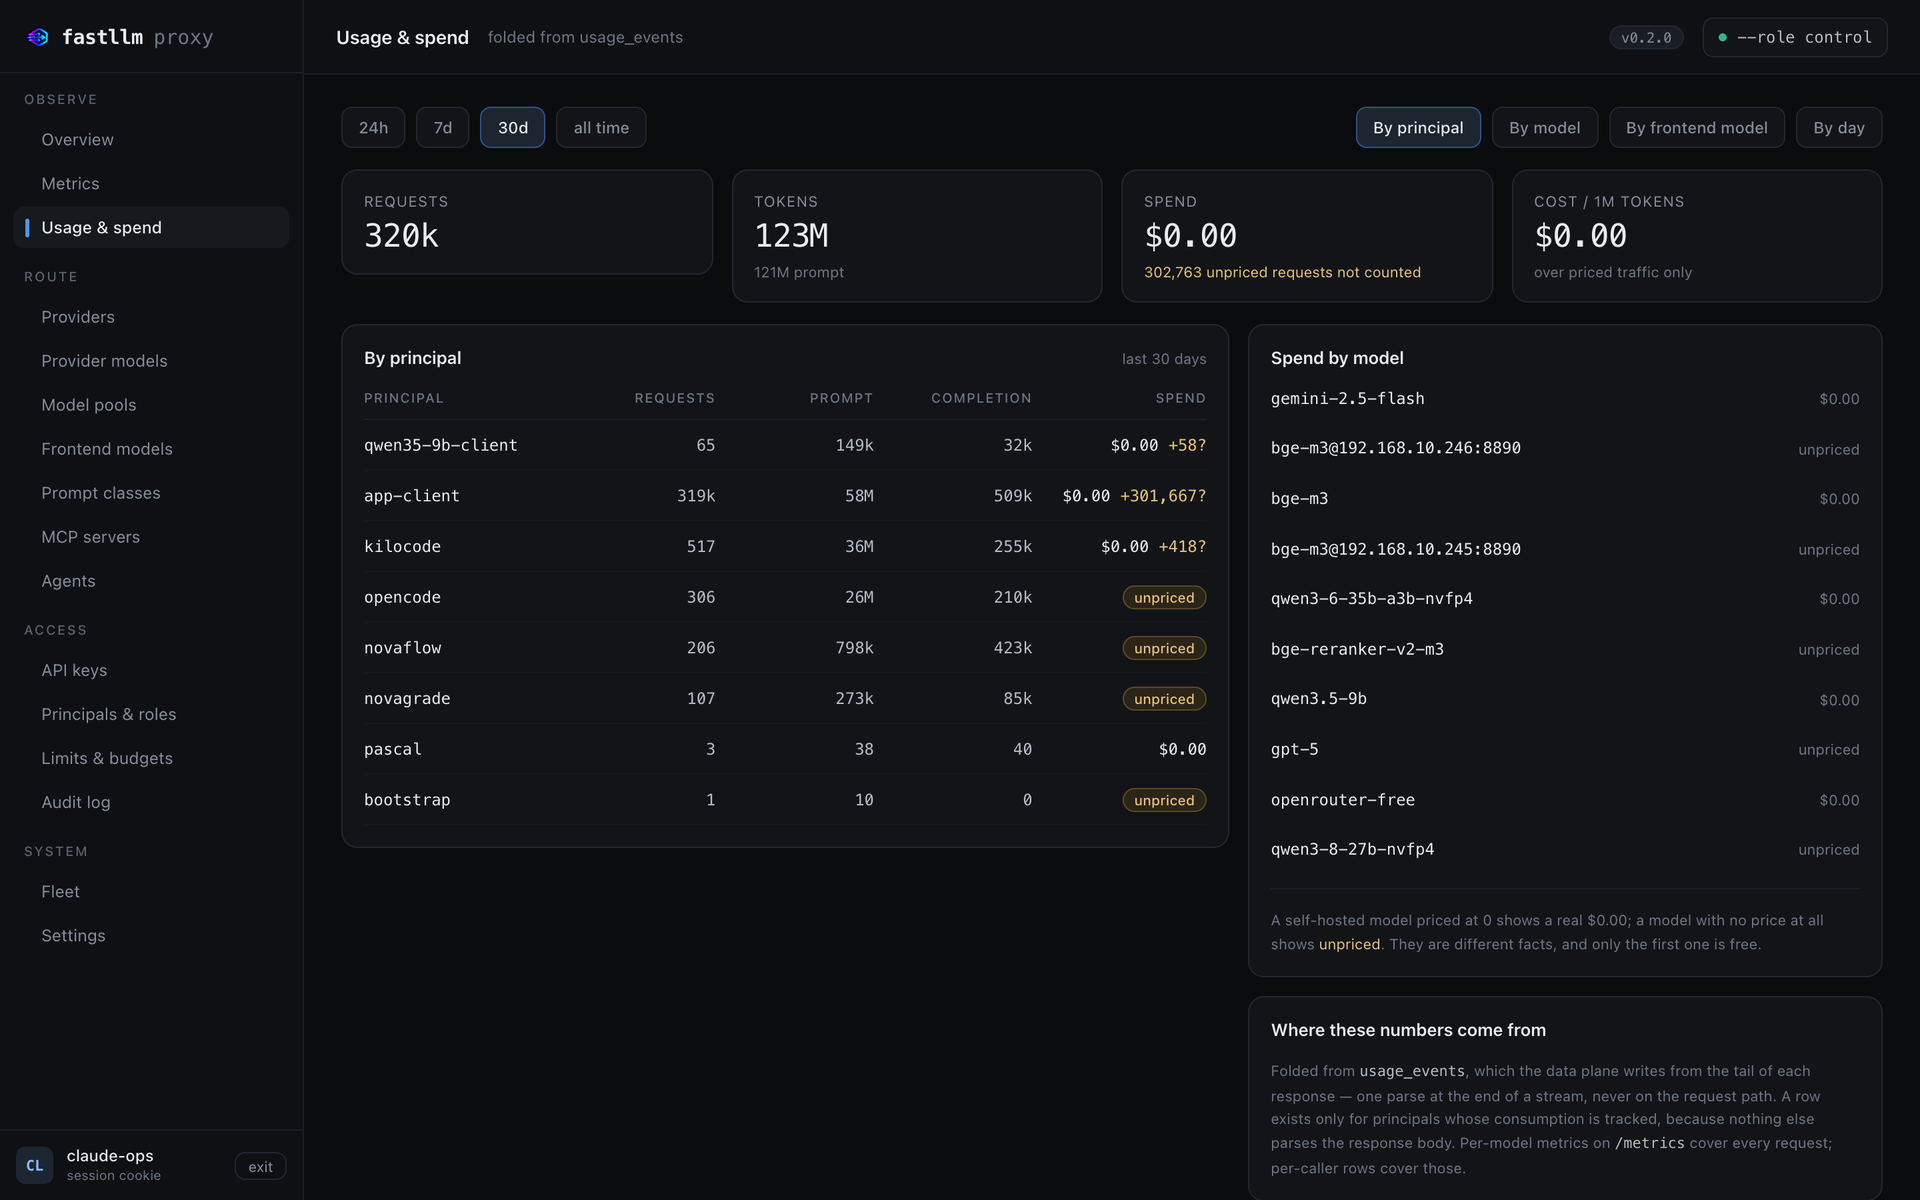
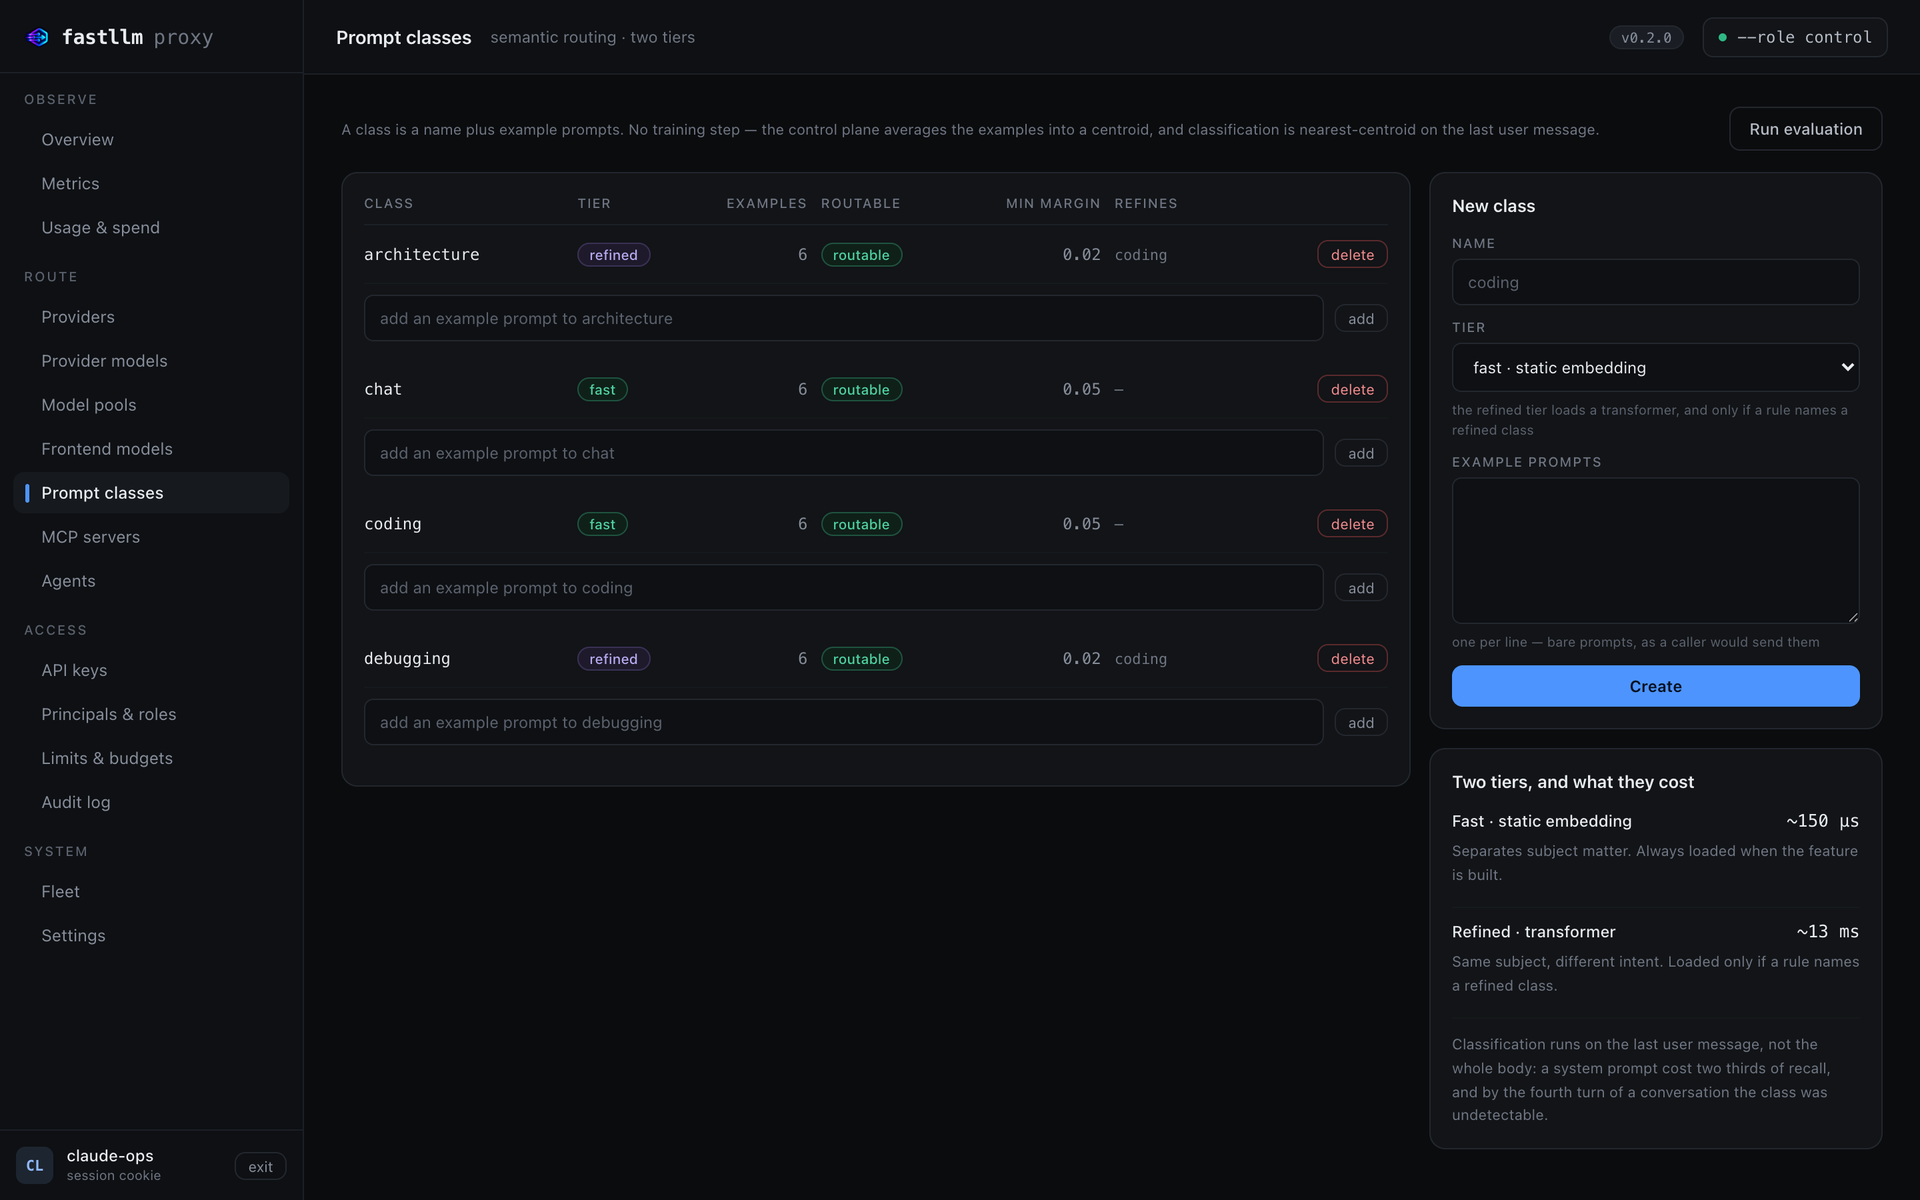
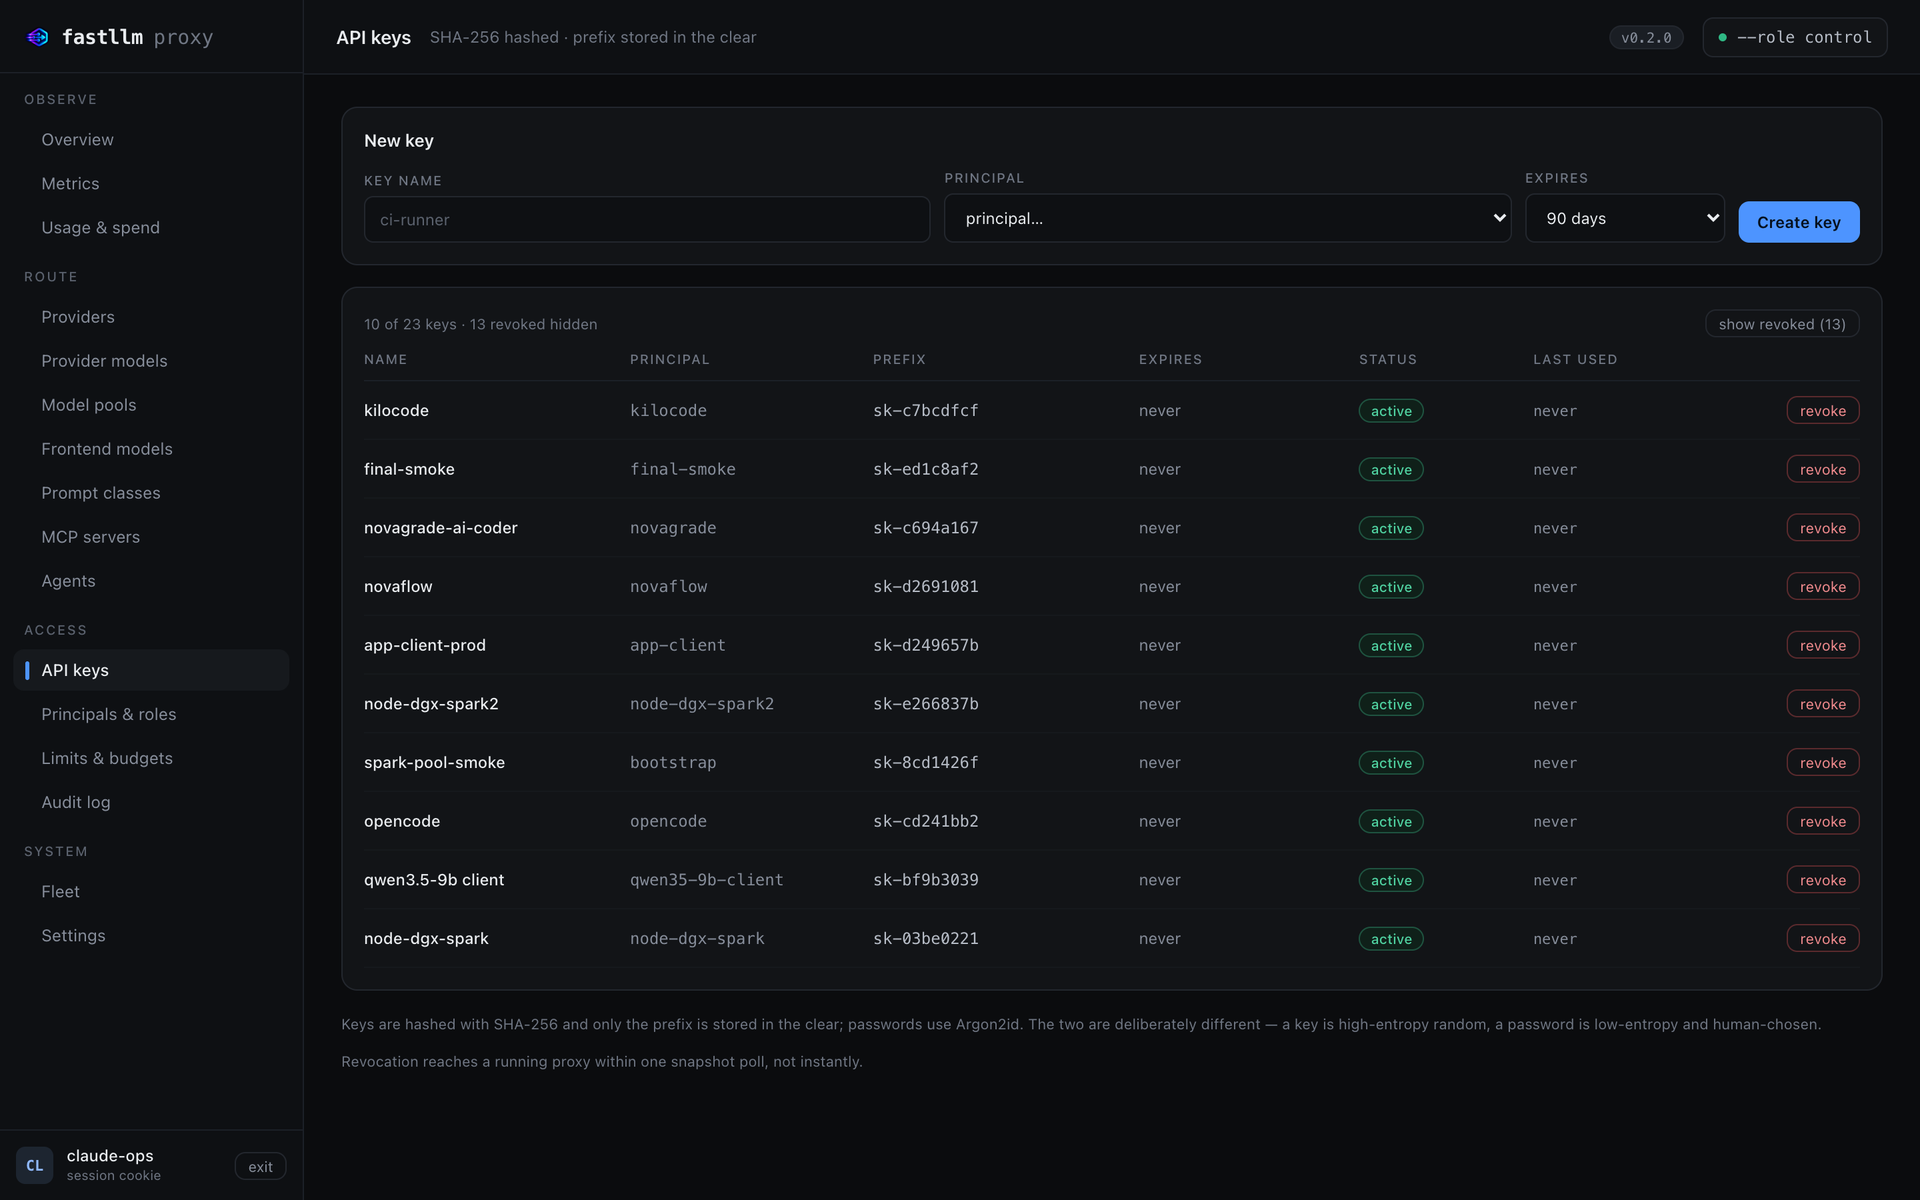
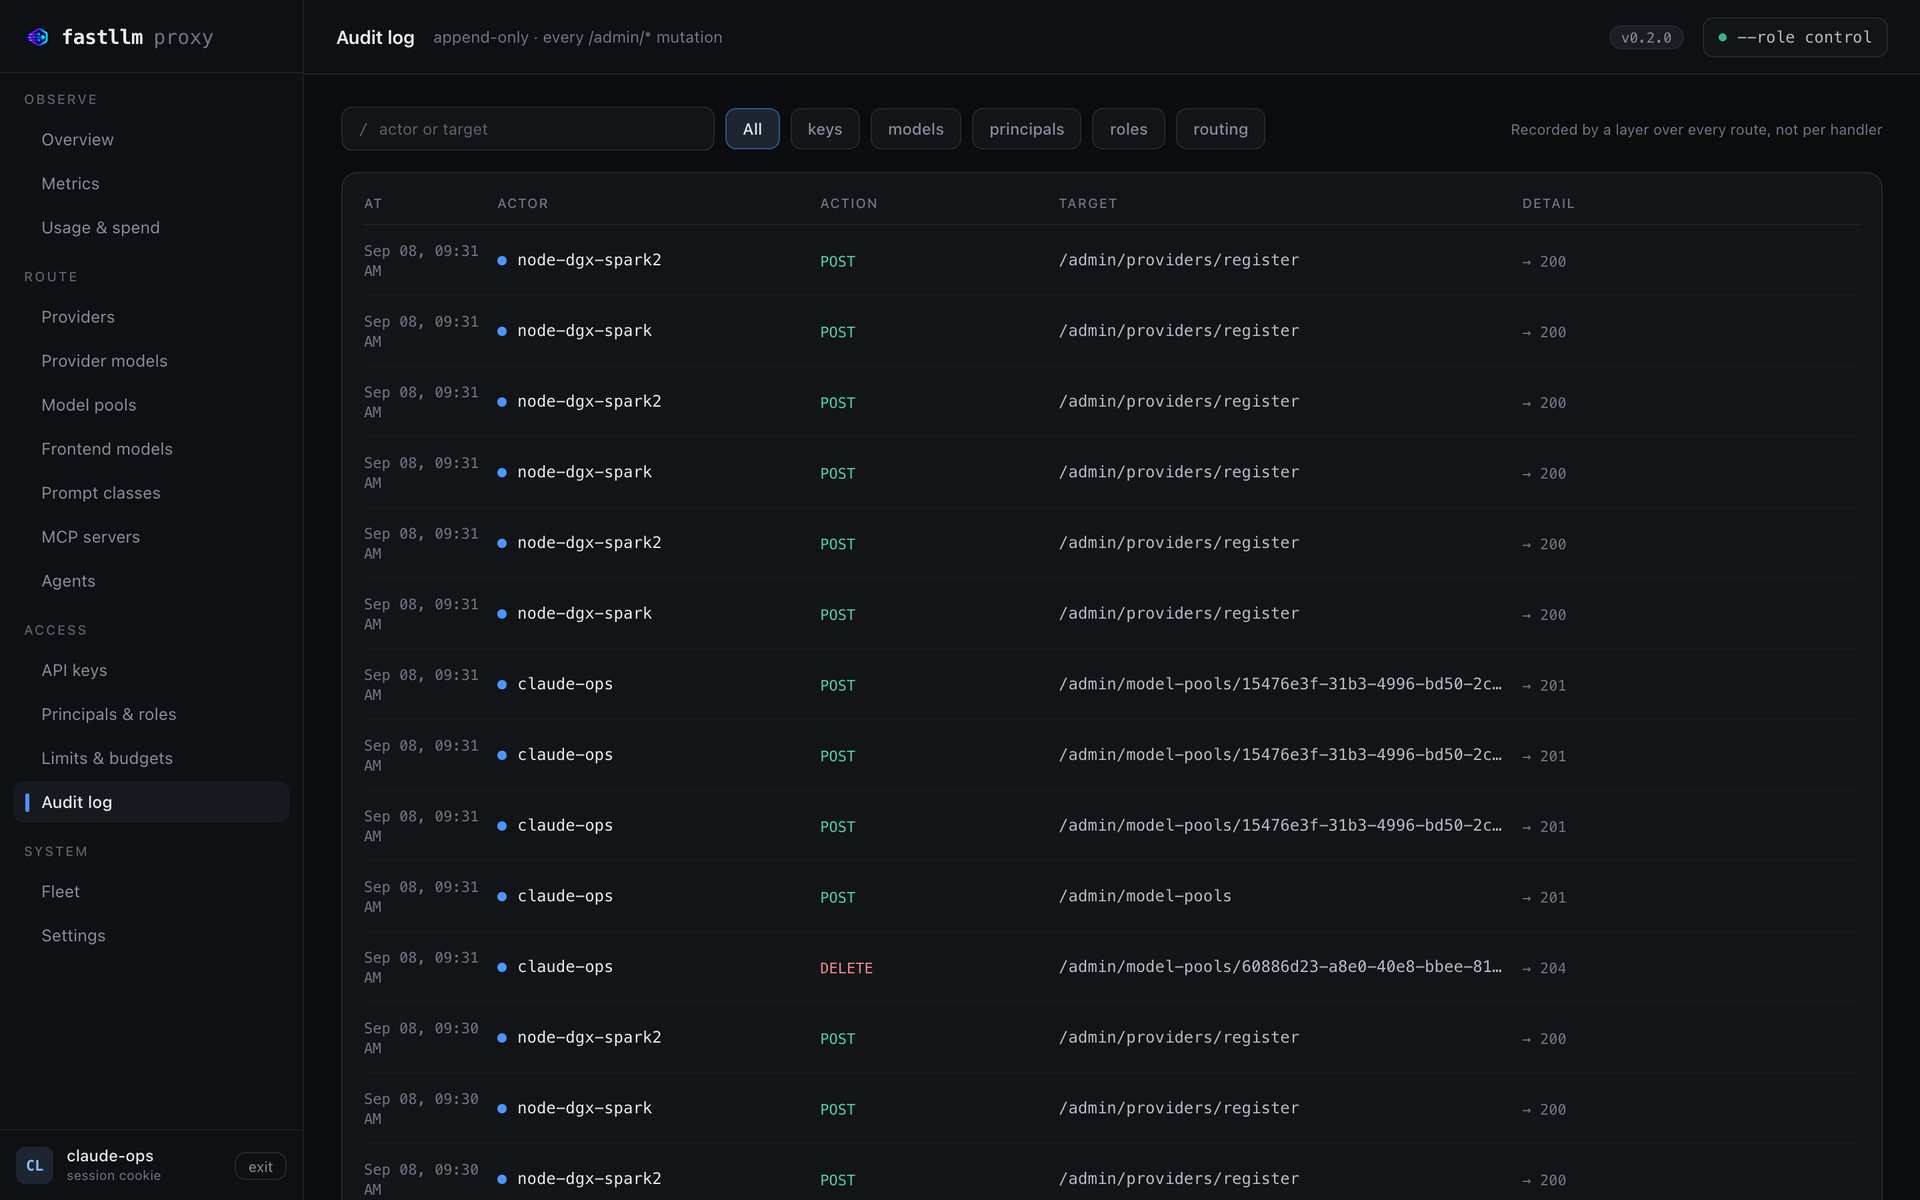
Local vLLM and llama.cpp boxes and hosted providers like OpenRouter, Anthropic, Bedrock, and Gemini all answer to one OpenAI-compatible address once FastLLM Proxy sits in front of them. Clients ask for a frontend model by name, and ordered rules pick the target by caller, prompt size, headers, budget spent, time of day, or how busy a backend is. Prompts that share a prefix return to the node holding their cache, and semantic routing sends coding questions one way and chat another using example prompts you write. API keys carry per-model grants, rate limits, and token or spend budgets, and the management console shows traffic, usage and spend, an append-only audit log, and a fleet topology. Failures fall through to the next target before a byte reaches the caller, and an admission gate turns a flooded engine into a bounded queue. An MCP gateway and an A2A agent endpoint put tool servers and agents behind the same address. Existing LiteLLM configs import unchanged. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Benefits
- One Endpoint For Every Backend
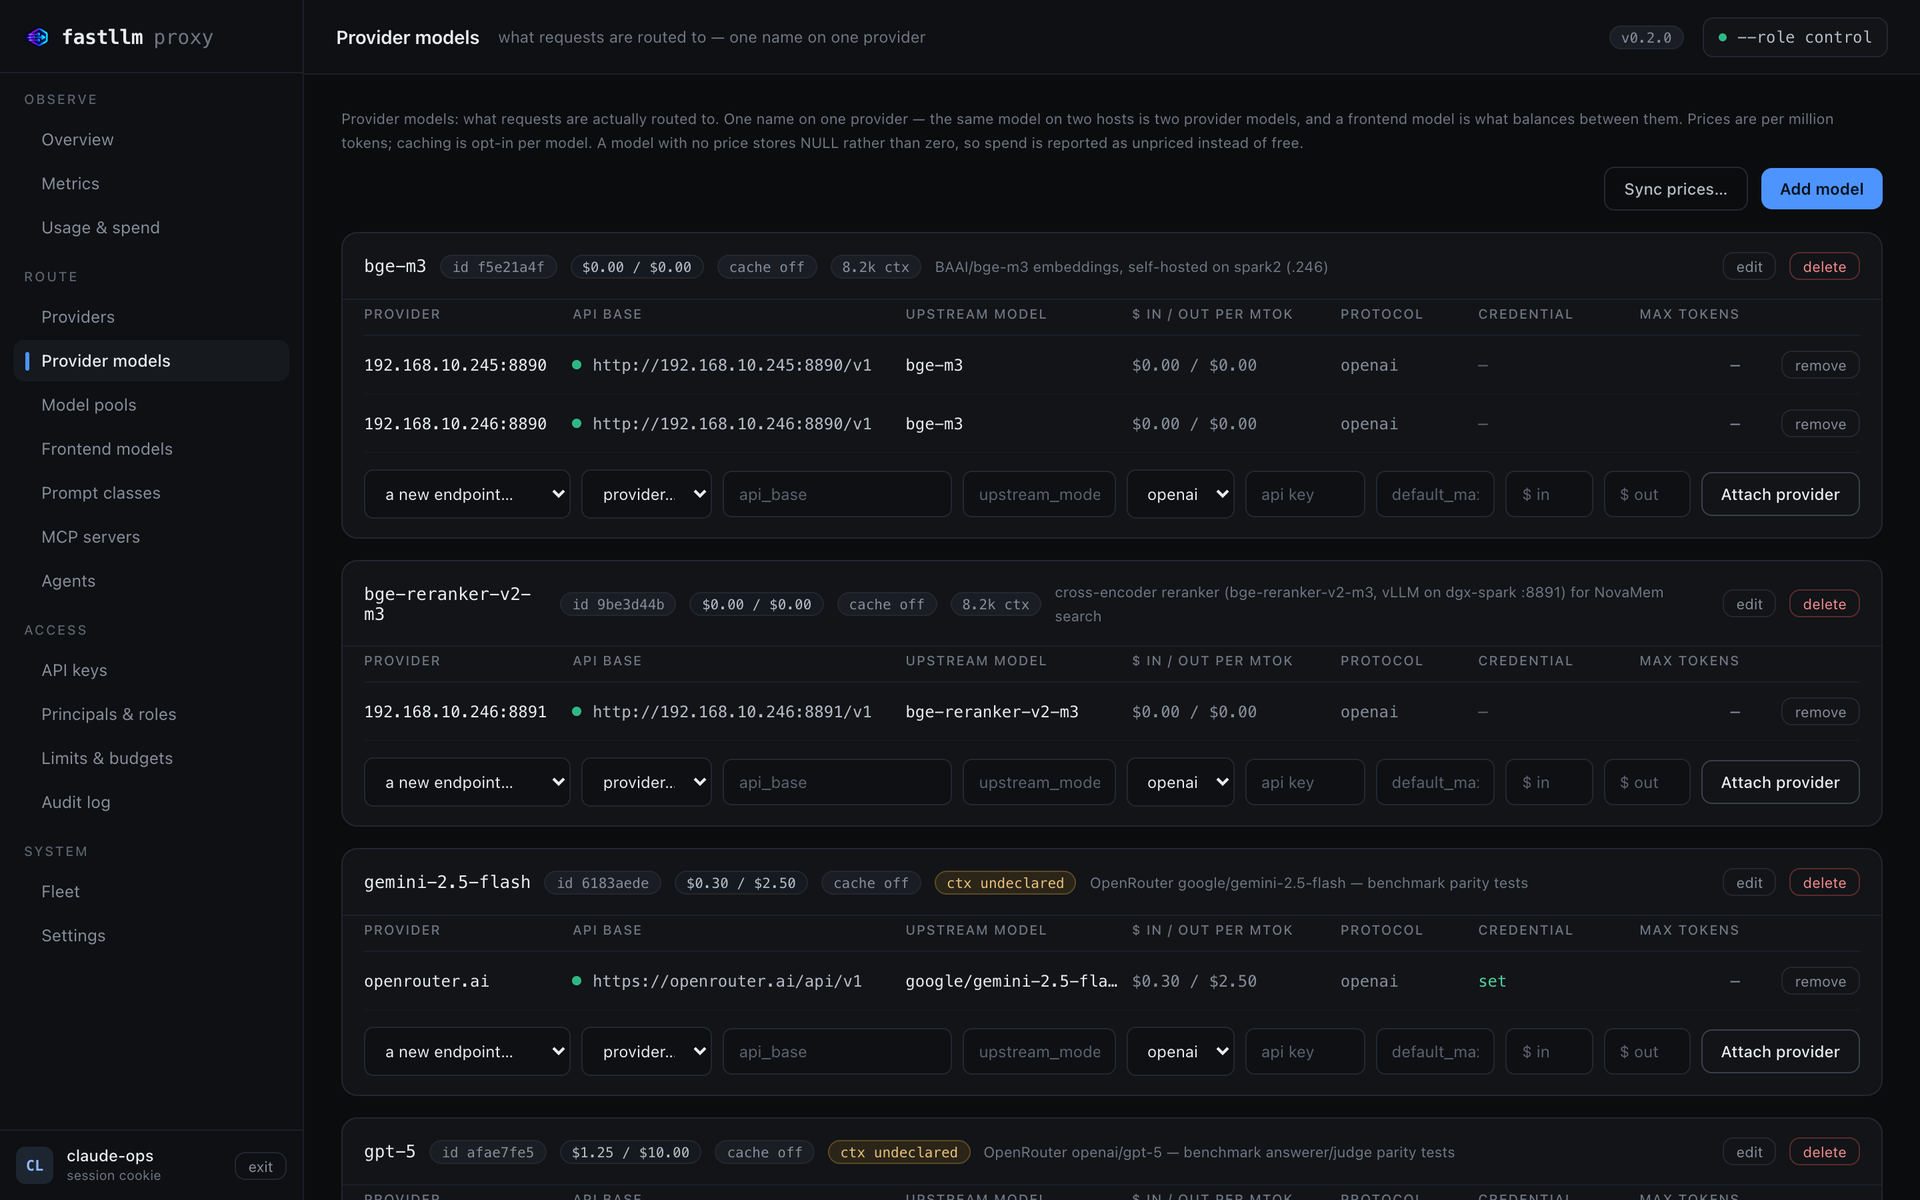
- Point every client at a single OpenAI-compatible address in front of vLLM, SGLang, llama.cpp, and 81 providers, and swap models without changing client configuration.
- Routing That Follows Your Rules
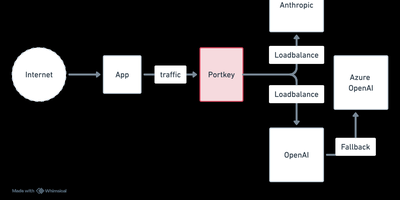
- Frontend models resolve to ordered targets by caller, prompt size, headers, budget used, time window, or backend load, with failover on 5xx and 429 before the client sees anything.
- Keys With Budgets Attached
- Each API key carries per-model grants, rate limits, and token or spend budgets, so a runaway script hits its cap instead of the whole month's invoice.
- Drop-In For LiteLLM Setups
- An importer reads existing LiteLLM config files, bringing models, backends, keys, and per-key grants across, and re-running it converges instead of duplicating records.
Features
- Cache-Affinity Routing
- Requests sharing a prompt prefix return to the vLLM or SGLang node holding its KV cache, unless that node runs hotter than the least-loaded one.
- Semantic Prompt Classes
- Define a class with example prompts and the proxy embeds each request, routing coding, maths, or legal questions to the model you chose, with an evaluation for collisions.
- Usage And Spend Console
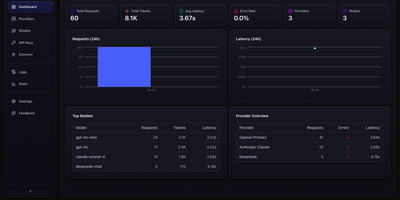
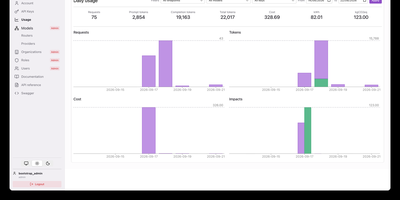
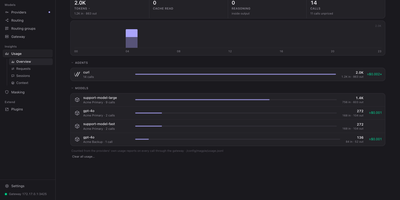
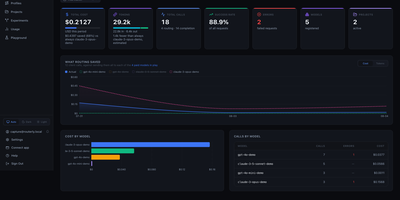
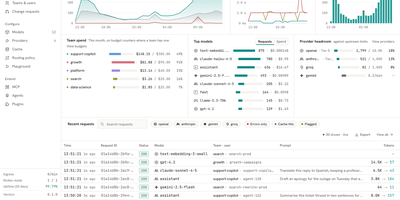
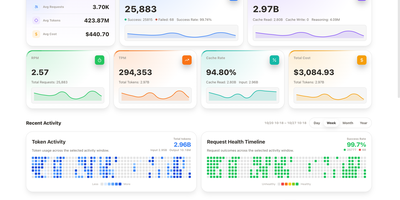
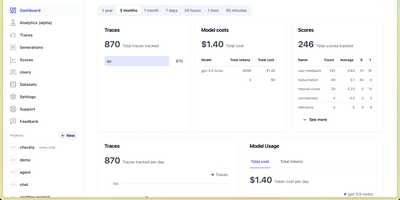
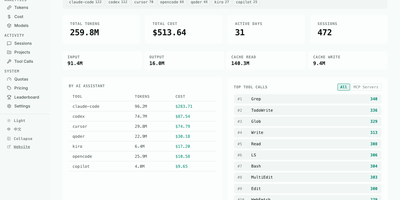
- A web console charts traffic, latency, tokens, and spend by principal, model, or day, with an audit log of every admin change.
- Admission Gate
- A per-backend gate turns a flooded self-hosted engine's endless queue into a bounded one, answering overflow with 503 and a Retry-After header.
- MCP And A2A Gateway
- Register tool servers and agents once, then reach them through the same address with namespaced tools, authorization, and pinned agent versions.
- Fleet Topology View
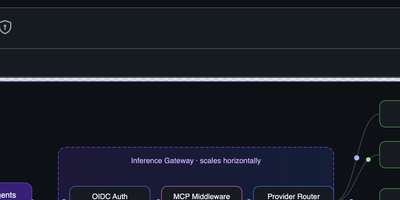
- See the control plane, proxy replicas, and engine hosts with per-node health, in-flight counts, and cache figures on one page.