Onyx
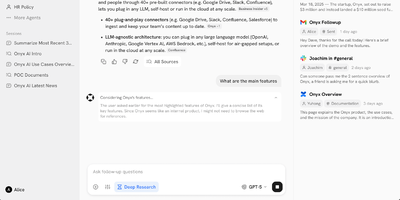
Formerly known as Danswer and now backed by over 31,000 GitHub stars with 253 releases, Onyx delivers a production-ready AI platform that turns any LLM into a context-aware enterprise assistant connected to your organization's actual knowledge. The agentic RAG pipeline combines BM-25 keyword search with prefix-aware embedding models in a hybrid index, then deploys AI agents to retrieve, verify, and synthesize answers with source citations from over 40 connected workplace tools including Google Drive, Confluence, Slack, Notion, Jira, SharePoint, GitHub, and Linear. Custom AI assistants with configurable prompts, backing knowledge sets, and document-level access control enable specialized agents for engineering, sales, support, and research workflows. The platform supports every major LLM provider — Anthropic Claude, OpenAI, Google Gemini, plus self-hosted options via Ollama, LiteLLM, and vLLM for fully air-gapped deployments. Beyond chat, Onyx provides web search with Serper, Google PSE, Brave, and SearXNG integration, an in-house web crawler, code execution, file creation, and multi-step deep research with report generation. Enterprise features include SSO via Google OAuth, OIDC, or SAML with SCIM provisioning, role-based access control, usage analytics by team and agent, query history auditing, PII removal through custom code hooks, and full whitelabeling. Deploy via Docker Compose on any infrastructure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed (Community Edition).
Deskcomm
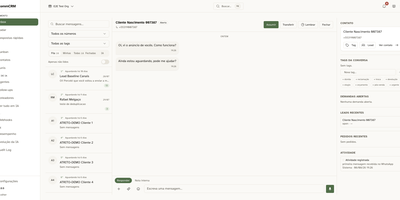
Converting inbound chat conversations into closed revenue is what Deskcomm orchestrates through an open-source sales operating system with native AI agent routing and WhatsApp integration. Sales representatives monitor incoming customer inquiries across connected WhatsApp Web sessions and official WhatsApp Cloud API channels from a real-time shared inbox with multimodal attachment previews. Autonomous AI agents qualify incoming leads, extract contact parameters, parse customer objections, and book calendar appointments before escalating complex deal negotiations to human account executives. Commercial teams organize deal progression through interactive kanban pipeline boards, where drag-and-drop movements trigger automated follow-up sequences and dynamic message templates. The built-in knowledge retrieval studio ingests internal product documentation and FAQ catalogs, allowing AI attendants to cite verified organizational knowledge during client interactions. Multi-tenant access controls enforce strict data isolation between business units with granular role assignments for managers and support operators. Administrators monitor token consumption across OpenRouter and OpenAI models while synchronizing customer records with external platforms through Model Context Protocol servers and outbound Webhooks. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
LibreDesk
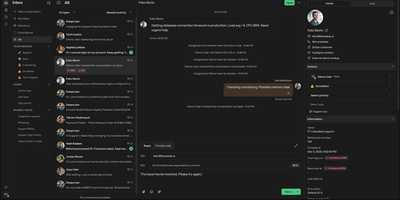
LibreDesk unifies live chat, email, and future channel integrations into a single agent inbox where every customer conversation converges regardless of origin, replacing per-seat-priced tools like Zendesk, Intercom, and Freshdesk with a zero-cost alternative that has surpassed 2,000 GitHub stars. Built on a Go backend with a Vue.js 3 and ShadcN UI frontend, it ships as a single binary requiring only PostgreSQL and Redis. The embeddable live chat widget drops onto any website with a snippet, while the AI assistant handles initial customer queries using answers grounded in your knowledge base before escalating to human agents when needed. Agent copilot drafts replies, summarizes conversation threads, and rewrites messages for tone adjustment directly within the inbox interface. Automation rules trigger on conversation events to tag, assign, and route tickets based on configurable conditions, while auto-assignment distributes workload by agent capacity or custom criteria. SLA management tracks response and resolution time targets with breach notifications, and automated CSAT surveys measure satisfaction after conversation closure. Macros save frequently sent responses as reusable templates that simultaneously set tags and assign conversations. Role-based access control provides granular per-action permissions for teams and individual agents, and SSO supports Google, Microsoft, and any OIDC provider. The HTTP/JSON API and webhook system enable custom integrations with external tools. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
big-AGI
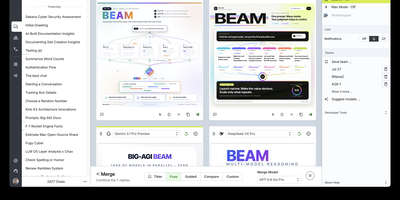
big-AGI is an open-source generative AI workspace that provides a unified, local-first interface for orchestrating multi-model reasoning, automated code execution, and custom persona workflows across private infrastructure. Users query multiple large language models simultaneously through the Beam scatter-gather engine, which prompts independent AI systems in parallel, compares candidate completions side by side, and merges optimal passages into a single refined response. Knowledge workers assemble tailored AI personas equipped with specialized system instructions, custom temperature settings, and predefined document context to handle domain-specific tasks ranging from architectural design reviews to legal contract analysis. The application renders rich multimedia outputs including interactive Mermaid sequence diagrams, LaTeX mathematical formulas, syntax-highlighted code blocks with live execution previews, and AI-generated image generation canvases. Teams integrate local inference servers like Ollama and LocalAI alongside commercial API endpoints to route confidential datasets strictly through internal networks while monitoring per-prompt token usage and operational latency. Users attach complex PDF documents, spreadsheets, and source code repositories for automatic parsing and semantic retrieval, while local-first storage engines ensure private chat transcripts and custom presets remain encrypted on host drives. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
PicoClaw
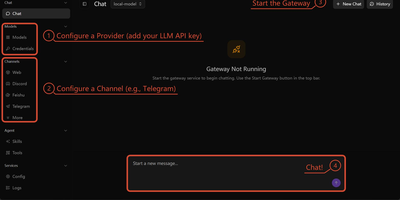
An 8MB Go binary that boots in under one second, uses less than 10MB of RAM, yet delivers full AI agent capabilities across 16+ chat platforms simultaneously. PicoClaw connects to Telegram, Discord, Matrix, IRC, Slack, WeCom, DingTalk, WeChat, LINE, and QQ while supporting LLM providers spanning OpenAI, Anthropic, Gemini, DeepSeek, AWS Bedrock, Azure, and local models via Ollama. Native Model Context Protocol support enables standardized tool integration, and the built-in smart routing engine directs simple queries to lightweight models to reduce API costs while sending complex tasks to capable models. Tool capabilities include secure shell execution, filesystem access, web search, cron scheduling for recurring tasks, and sub-agent spawning with status tracking. Gateway mode transforms PicoClaw into a full AI backend with REST API endpoints accessible from any client. The Skills system loads hierarchical behavior definitions from SKILL.md files, enabling customizable agent personalities and workflows. Compiles for x86_64, ARM64, ARMv7, RISC-V, MIPS, and LoongArch, making it deployable on hardware as cheap as a $10 Sipeed LicheeRV Nano. Achieved nearly 30,000 stars within six months of its February 2026 release. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
DispatchMail
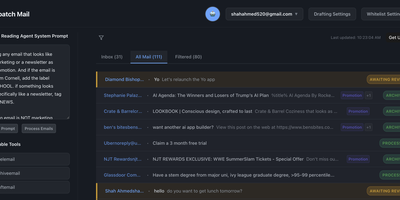
DispatchMail is an SuperHuman alternative and delivers a self-hosted AI email assistant that processes your Gmail inbox through configurable OpenAI prompts without sending data to third-party cloud services beyond the LLM API itself. The Flask backend connects to Gmail via IMAP, retrieves new messages according to your schedule, and routes them through customizable whitelist rules based on sender address, subject keywords, or natural language descriptions before AI processing begins. Two distinct prompt configurations control behavior — the Reading Prompt instructs how the AI should analyze and classify incoming messages, while the Draft Prompt defines how responses should be composed, letting you maintain consistent tone and policy across all automated replies. Whitelist filtering ensures the AI only processes messages you explicitly authorize, preventing unnecessary API costs and keeping sensitive emails out of the LLM pipeline entirely. The React web interface provides inbox management with message previews, AI-generated summaries, draft editing with human-in-the-loop approval before sending, and configuration panels for prompts and rules. Automatic labeling and archival organize processed messages into categories without manual intervention. The sender research feature uses LLM-powered deep analysis to build background profiles of email contacts. All email content, credentials, and processing results persist in a local SQLite database with zero cloud storage dependencies. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.