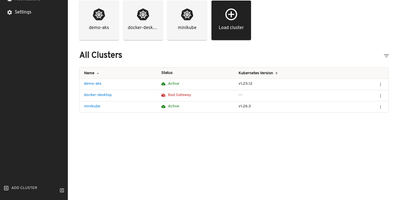
Headlamp
The Kubernetes project's own answer to cluster management UIs: maintained under SIG UI governance, Headlamp's roadmap tracks Kubernetes releases and its design philosophy reflects community needs rather than a vendor's product strategy. The React interface provides full read-write capabilities adapted to each user's RBAC permissions — delete, scale, edit, and restart buttons appear only when the authenticated user holds the corresponding cluster role, preventing accidental unauthorized actions. Multi-cluster support surfaces workloads across development, staging, and production from a single view without context switching. The plugin architecture drives extensibility through a curated catalog: an AI Assistant plugin answers natural-language cluster queries and performs operations via configurable LLM keys, Flux handles GitOps, Karpenter manages nodes. Integrated terminals provide browser-based exec access to running pods, live log streaming follows container output with filtering, and the YAML editor displays inline Kubernetes API documentation alongside resource definitions. Deployment creation forms let you configure containers, environment variables, volumes, and replicas without writing manifests. Side-by-side cluster comparison views surface differences in workload distribution. Works with any distribution: EKS, GKE, AKS, Minikube, Docker Desktop. Helm chart installation via the Headlamp repository with images on GitHub Container Registry. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
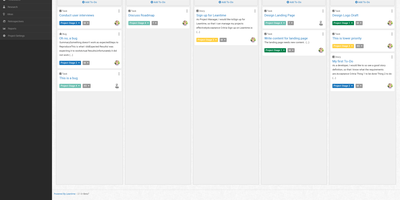
Leantime
"As simple as Trello but as feature-rich as Jira" is how the Leantime team frames its goals-focused project management system for non-project managers - built from the ground up with ADHD, autism, and dyslexia in mind, with behavioral science shaping customizable dashboards, time blocking, low-cognitive-load prioritization, and Kanban, list, table, Gantt, and calendar views so each person works the way their brain does. The PHP application (AGPL, Laravel Blade frontend) connects strategy to execution: tasks with unlimited subtasks and dependencies roll up into milestones on a timeline, sprints and retrospectives handle iteration, and strategy-level blueprint boards - Lean Canvas, SWOT, risk analysis, goal and metric tracking - keep the "why" attached to the work. Knowledge lives alongside: wikis and docs, idea boards, comments on everything, file storage on S3 or local disk, even screen and webcam recording. Time tracking with timesheets supports estimation and client billing. Admin features are serious for an OSS tool: per-project permissions, two-factor auth, LDAP and OIDC single sign-on, Slack, Mattermost, and Discord integrations, a plugin system, and an expanding API that now powers a mobile app. Recent releases added multi-collaborator task assignment and low-vision accessibility improvements. Available in 20+ languages.
Utopia
The first open-source substrate for enterprise knowledge engineering that learns passively and governs itself. The Rust-built backend paired with PostgreSQL and pgvector delivers a bitemporal knowledge graph where every fact carries two timelines: when it held in the real world and when the system came to believe it — enabling full audit trail replay of how understanding evolved. Document ingestion handles PDF, DOCX, PPTX, XLSX, CSV, Markdown, HTML, and plain text with legacy encoding detection, while scheduled syncing pulls from web pages, RSS feeds, GitHub, Jira, Notion, WebDAV, and S3-compatible buckets. Search fuses Tantivy full-text indexing with pgvector semantic vectors using Reciprocal Rank Fusion, streaming answers with inline citations that link directly to source passages. The built-in agent harness drives agentic RAG through conversation — searching documents, walking the knowledge graph at any historical date, and querying mounted databases via Ontology2SQL which achieves state-of-the-art results on BIRD Mini-Dev benchmarks. Five ontology packs ship inside the binary (schema.org, W3C Org, PROV-O, FOAF, IOF Core) with forward-chaining reasoning for transitivity, symmetry, inverses, and relation hierarchy. Entity resolution operates in three stages: exact name matching, embedding similarity, then model-based judgment with every merge reversible. Any OpenAI-compatible endpoint works including DeepSeek, Qwen, Ollama, and vLLM for fully air-gapped deployment. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
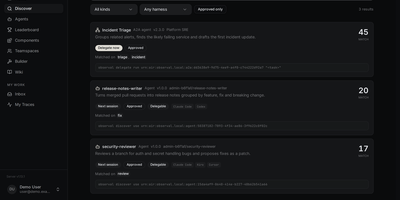
Observal
To pull a team's skills, MCP servers, hooks, prompts, and agent files out of scattered Git repositories, Observal keeps them in one reviewed registry and traces real sessions to show which ones help. Build an agent visually, with a live config preview for every harness. Submissions wait in an admin review queue, where reviewers inspect side-by-side version diffs before approving a release. Teamspaces give each team its own namespace, and approved releases can be forked into independent drafts. One pull command then writes the right config for Claude Code, Cursor, Kiro, Codex, Copilot, Pi, OpenCode, Antigravity, or Goose. Every approved resource is discoverable through the open Agentic Resource Discovery standard, and a running agent can hand part of its task to another approved agent or a remote Agent2Agent service. Hooks record each session as a trace of prompts, tool calls, MCP round trips, tokens, and errors, with turn-by-turn replay for debugging and audits. Insight reports, generated through providers such as Anthropic, OpenAI, or Ollama, list what is working, what is hindering, and quick wins. A dashboard follows adoption, cost, and department usage, a leaderboard ranks agents by downloads, and audit logs, SAML single sign-on, and SCIM provisioning are included. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Graylog
Trusted by over 60,000 organizations worldwide with more than 8,100 GitHub stars since 2010, Graylog has established itself as one of the fastest paths from raw log data to operational visibility, delivering centralized log management, security analytics, and compliance auditing through a purpose-built web interface with sub-second search at scale. The platform ingests logs from virtually any source via syslog, GELF, Beats, raw TCP/UDP, HTTP, CEF, IPFIX, and Netflow protocols, processing each message through configurable pipelines that parse fields, apply transformations, enrich events with GeoIP data from MaxMind or IPinfo lookup tables, and route messages to appropriate streams based on content rules. OpenSearch handles full-text indexing and storage with dynamic shard sizing that automatically calculates appropriate sizes from available node memory, while MongoDB stores configuration metadata including user accounts, roles, dashboards, alert rules, and pipeline definitions. The alerting system integrates with Slack, PagerDuty, and email with customizable notification templates and Replay Search links for immediate investigation context. Version 7.0 introduced MCP server integration for connecting preferred LLMs to perform AI-assisted log analysis and automation, while version 7.1 added Sigma detection rule import from private GitHub, GitLab, and Bitbucket repositories for detection-as-code workflows. The Sidecar agent management system centrally configures and deploys Filebeat, Winlogbeat, and nxlog collectors across infrastructure from the Graylog web interface. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. SSPL licensed.
OpenObserve
With 20,500+ GitHub stars and over 6,000 organizations running it in production — including a Fortune 100 company ingesting more than 4 PB per day — OpenObserve is the open-source observability platform that replaces your entire Datadog, Splunk, or ELK stack with a single Rust binary deploying in under two minutes. Apache Parquet columnar storage with zstd compression on S3-compatible object storage delivers 140x lower storage costs than Elasticsearch while providing better query performance on a quarter of the hardware. Ingest logs, metrics, and distributed traces via native OpenTelemetry OTLP endpoints with no vendor lock-in. Query logs and traces with standard SQL, metrics with SQL or PromQL — no proprietary query language to learn. The built-in dashboard builder offers 19 chart types including time-series graphs, heatmaps, gauges, tables, and top-K lists with drag-and-drop layout combining data from all signal types. Data pipelines process, enrich, redact, or normalize ingestion streams using Vector Remap Language for real-time transformations including PII redaction and logs-to-metrics conversion. Real User Monitoring captures frontend performance with session replay. The Service Catalog provides topology-based trace analysis with side-panel drill-downs into database queries and error details. Alerting supports real-time and scheduled rules with SQL and PromQL conditions. Native multi-tenancy isolates organizations and streams with complete data separation. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Fleetbase
Tracking over 50,000 fleet vehicles across production deployments, Fleetbase delivers a modular logistics operating system where each module—Fleet-Ops, Storefront, Pallet, and Ledger—works independently yet shares a unified data layer that eliminates middleware between ordering, dispatch, warehousing, and accounting. The Fleet-Ops core handles real-time driver tracking through a SocketCluster-based WebSocket event bus, interactive map-based dispatch with both directed and ad-hoc driver assignment, configurable order workflows with custom rules, automation triggers, and activity flows, plus a Kanban-style order board for visual pipeline management. Service zones let dispatchers define geographic operating areas, while proof-of-delivery capture and route optimization close the last-mile loop. The Storefront module provides headless e-commerce with products, carts, and checkout that feed directly into dispatch queues, and the Ledger module records invoices and financial journal entries across all operations. The Navigator driver app—also AGPL-3.0 licensed and fully white-label—delivers turn-by-turn navigation, live order communication, and fault reporting to drivers in the field. The extension architecture pairs backend Laravel Composer packages with frontend Ember Engine modules, enabling third-party developers to build first-class platform extensions without forking. A RESTful API with full documentation, webhook delivery via Redis-backed queues, and push notification support through APNs and FCM round out the integration surface. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Neon
Neon reimagines PostgreSQL with a serverless architecture that decouples storage from compute, enabling instant copy-on-write database branching, autoscaling under load, and scale-to-zero when idle with sub-second cold starts. The lakebase architecture distributes durability across three layers: stateless compute nodes running unmodified PostgreSQL, safekeepers providing Paxos-based WAL quorum replication, and a pageserver that materializes pages on demand while offloading immutable history to S3-compatible object storage via MinIO or AWS S3. Copy-on-write branching creates full database clones as metadata operations without duplicating data, enabling developers to spin up isolated test environments, run parallel CI/CD pipelines, or recover from data loss through point-in-time restore across the configurable history window. Autoscaling dynamically adjusts CPU and memory based on live traffic without manual capacity planning, while scale-to-zero ensures costs drop to storage-only during idle periods. Neon maintains 100% PostgreSQL compatibility with broad extension support including PostGIS, pg_cron, pgvector, pg_stat_statements, and hundreds more, so existing applications connect with standard PostgreSQL drivers and ORMs unchanged. The API-first control plane enables programmatic provisioning, branch management, and multi-tenant fleet operations for platform builders and AI agent integrations. Acquired by Databricks in May 2025 and backed by over 22,800 GitHub stars. Deploys via Docker Compose with pageserver, safekeepers, storage broker, and compute nodes backed by MinIO object storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
TaxHacker
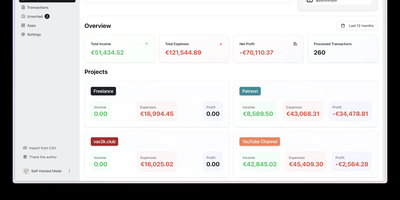
With 6,600+ GitHub stars and created by vas3k — one of the indie developer community's most recognized builders — TaxHacker is the self-hosted AI accounting application that turns receipt chaos into structured financial intelligence without surrendering a single document to third-party cloud services. Upload photos of receipts, invoices, or PDF bank statements, and the LLM pipeline automatically extracts dates, merchants, amounts, line items, tax breakdowns, and vendor information into an Excel-like structured database with custom fields you define through your own AI prompts. Currency handling covers 170+ fiat currencies and 14 cryptocurrencies (BTC, ETH, LTC, and more) with automatic conversion using historical exchange rates from the actual transaction date — critical for international freelancers filing in one reporting currency. The AI layer supports OpenAI (GPT-4o, GPT-4.1-mini), Google Gemini, Mistral, or fully local models via Ollama, LM Studio, vLLM, and LocalAI through OpenAI-compatible endpoints for complete air-gapped deployments. Features include multi-project workspace isolation, custom categories with AI-driven auto-classification, bulk document upload with batch processing, email server monitoring for automated attachment ingestion, flexible CSV export with attached documents, and comprehensive tax report generation. The tech stack runs Next.js 15+ for the frontend and tRPC API, Prisma ORM for database models and migrations, PostgreSQL 17+ for persistence, and Ghostscript plus GraphicsMagick for PDF rendering. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Jellyseerr
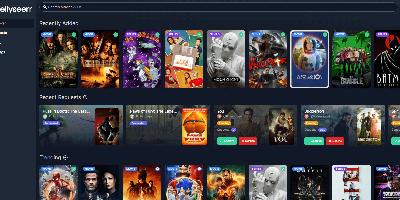
Browse trending titles, search anything, request it in two clicks: Jellyseerr gives Jellyfin, Emby, and Plex users a beautiful storefront for the media library. Born as the Overseerr fork that added Jellyfin and Emby support (the projects have since unified as Seerr), it handles the full request lifecycle - users authenticate with their existing media-server accounts, pick individual seasons or movies in a clean interface, and admins approve or decline from a simple queue, including on mobile. Approved requests flow straight to Sonarr and Radarr, which handle acquisition automatically, with support for separate 4K server instances. Regular library scans keep availability accurate, so users see instantly what already exists instead of requesting duplicates. A granular permission system controls who can request what - auto-approval for trusted users, quotas and limits elsewhere - and override rules adjust request routing by user, tag, or other conditions. Watchlist and blocklist functions curate discovery, notifications reach email, Discord, Telegram, Slack, Pushover, and Pushbullet, and both PostgreSQL and SQLite are supported. Localized into many languages, it turns "can you add this movie?" texts into a self-service system that runs itself.
Duplicati
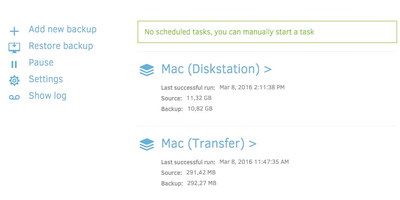
Encrypted, incremental, compressed backups on storage you already have - Amazon S3, Backblaze B2, Google Drive, Azure, OneDrive, Dropbox, MEGA, Storj, WebDAV, SFTP, FTP, SMB, or a plain local disk - is what the MIT-licensed Duplicati has quietly done for years. Its security model is Trust No One: every block is encrypted with AES-256 (or a local GPG instance) before leaving the machine, and the passphrase never travels, so the storage provider holds only ciphertext. The block-based storage engine gives the best of both backup worlds: after one initial full backup, only changed data blocks upload - modify a tiny part of a huge file and only that part transfers - yet every backup version restores like a full backup in a single operation, with no incremental chains to replay. Deduplication and compression keep remote storage growth slow even across years of versions. A web interface manages everything: the built-in scheduler keeps backups current automatically, flexible filters select folders, file types, or custom patterns, retention policies prune old versions, and an integrated updater flags new releases. On compatible object-lock backends, immutable (WORM) storage protects backup data from ransomware that reaches the credentials. Runs on Windows, macOS, and Linux, free even for commercial use.
Beszel
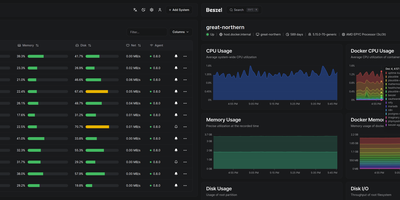
Reaching 24,000 GitHub stars within two years of its first commit in July 2024, Beszel delivers Netdata-grade monitoring dashboards from a single Docker container with no Prometheus stack, no external database, and no complex configuration — just a one-binary hub on PocketBase (SQLite embedded) and a sub-15 MB agent per host that auto-discovers Docker and Podman containers on contact. The agent connects outbound via WebSocket or SSH tunnel, requiring zero open ports on monitored servers and zero manual network configuration. Per-host metrics cover CPU usage, memory with swap and ZFS ARC breakdown, disk I/O across multiple partitions, network throughput, load average, sensor temperatures, battery charge, and GPU utilization with power draw for Nvidia, AMD, and Intel cards — features that competitors lock behind paid tiers. S.M.A.R.T. disk health including eMMC wear indicators and Linux mdraid array status surface hardware degradation before failures occur. Container statistics track CPU, memory, and network history per container with automatic discovery as new containers start. Configurable threshold alerts notify via email, Discord, Telegram, ntfy, Pushover, Gotify, Matrix, Mattermost, Signal, Slack, Microsoft Teams, and Twilio when metrics exceed defined limits. Multi-user accounts with OAuth/OIDC authentication let teams share monitored systems with role-based access, while automatic backups persist data to disk or S3-compatible storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Zammad
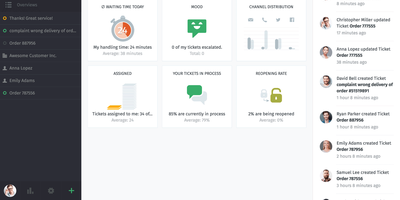
With 5,700+ GitHub stars and over a decade of active development since 2012, Zammad is the open-source helpdesk platform that unifies every customer communication channel — email, live chat, telephone, WhatsApp, Telegram, Facebook, SMS, and web forms — into a single ticket management interface backed by PostgreSQL, Elasticsearch, and Redis. Version 7.0 introduced native AI features including automated ticket categorization, priority assignment, and title rewriting via AI agents that plug into triggers, macros, and scheduler jobs, plus one-click AI ticket summaries and a writing assistant — all configurable with your choice of LLM provider: OpenAI, Anthropic, Mistral AI, Azure AI, Ollama for local models, or any custom OpenAI-compatible endpoint with full audit logging of every AI action. Define service level agreements with first response, update, and solution time tracking tied to business hours calendars, with automatic escalation notifications. The knowledge base provides multilingual FAQ management with internal and public visibility. Core workflows enable dynamic ticket masks with conditional field dependencies per group. Text modules let agents insert predefined responses via the double-colon shortcut, while macros execute multi-step actions with one click. Security includes two-factor authentication, S/MIME and PGP email encryption, and single sign-on via SAML or OpenID Connect. Integrations connect to GitHub, GitLab, Microsoft 365, LDAP with nested group support, and Exchange. Deploy via Docker Compose, Kubernetes with the official Helm chart, or DEB/RPM packages. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Pi Web
Pi Web is a browser interface for the Pi coding agent ecosystem, providing a visual workspace that reads the same local configuration and session files as the CLI. The session workspace groups conversations by project with running state indicators, context usage percentages, cost tracking, and compaction details, while two branching modes let users create independent session files from earlier messages or fork branches within existing sessions to explore alternative coding directions. Real-time streaming via Server-Sent Events delivers agent responses with structured Markdown rendering, thinking steps, tool call visualization, and image drag-and-drop input. The project file explorer browses working directories with syntax-highlighted source preview, Git diff inspection, and rendering for Markdown, images, audio, PDFs, and DOCX files with automatic refresh. Git worktree support switches checkouts from the sidebar while keeping sessions from the same repository grouped together. The Models panel manages provider authentication via OAuth and API keys, model selection, model smoke tests, and models.json configuration shared bidirectionally with the CLI agent. The Skills panel lists, searches, installs, and toggles agent skills without terminal access. The interface ships with English and Simplified Chinese translations, light and dark themes, a chat minimap, keyboard shortcuts, and completion sounds. Basic Auth protects remote access when binding to non-loopback addresses. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Automatisch
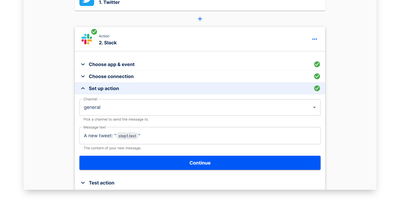
Automatisch runs your Zapier workflows on your own hardware - an open-source, self-hosted automation platform built as a direct alternative. Flows are chains of steps: one trigger (a polling or webhook event such as a new GitHub issue, a Stripe payment, or a form submission) followed by action steps that pass data downstream (post to Slack, append a Google Sheets row, update Notion). The visual builder deliberately mirrors Zapier's trigger-action model, so migrating existing Zaps requires no retraining and no programming knowledge. Roughly 60 integrations cover common business services - Slack, GitHub, Google Sheets, Notion, Stripe, Discord - and connections store credentials per service, with multiple accounts per app supported. Every execution runs on your own server: execution history, logs, and payload data never touch a third-party processor, which matters for GDPR, healthcare, and finance workloads. Error handling with retry logic, a REST API for programmatic flow management, and Docker Compose deployment round out the platform. The AGPL-3.0 Community Edition has no feature limits or per-task billing; an Enterprise Edition adds SSO, roles, and audit logs.
Fleet
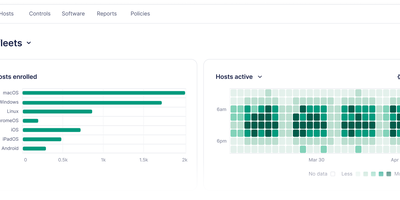
Fleet lets IT and security teams query every device in their organization like a SQL database, using osquery to surface installed software, running processes, configurations, and vulnerabilities within seconds across macOS, Windows, Linux, iOS, Android, and ChromeOS. The Go-based server exposes a web console and REST API for centralized device management, with MDM capabilities built on nanoMDM for Apple device enrollment, configuration profiles, and remote lock or wipe. Vulnerability management cross-references installed software inventories against NVD and OVAL CVE databases, automatically flagging known vulnerabilities with severity scores and remediation guidance. Software deployment handles OS updates using Apple Declarative Device Management, Windows Update, and custom installer packages distributed through S3-compatible storage. A GitOps workflow enables infrastructure-as-code management where device policies, osquery queries, and configuration profiles live as YAML files in Git repositories, with CI/CD pipelines pushing changes through the fleetctl CLI. The fleetd agent bundle includes osquery for telemetry, Orbit for version management, and Fleet Desktop providing end users a menu bar status indicator. Integrations connect to Snowflake, Splunk, Elastic, Jira, Zendesk, Vanta, and GitHub Actions for automated compliance reporting. CIS benchmark policies verify security baselines across operating systems. Deployment requires MySQL for persistence and Redis for caching, running as Docker containers or on Kubernetes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
BottleCRM
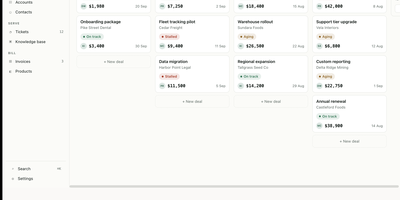
BottleCRM delivers a self-hosted customer relationship management platform that unifies sales lead qualification, visual deal pipeline tracking, helpdesk ticketing, and client invoicing into one workspace. Sales representatives capture prospects through embeddable website forms or CSV imports, qualifying leads before converting them into synchronized account, contact, and opportunity records. Account executives manage visual Kanban deal boards with stage aging timers and weighted pipeline forecasting, dragging cards across qualification phases while preserving complete interaction timelines. Customer support teams handle incoming inquiries with multi-level ticket hierarchies, business-hours service level agreement clocks, automated escalations, approval workflows, and canned response macros. Billing managers generate professional quotes and invoices directly from won deals, applying customizable line-item tax rates and tracking payment statuses through customer self-service portals. Development teams connect autonomous AI agents and third-party software using personal access tokens against the documented REST API to automate data entry and workflow updates. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Whoogle
Google's search results without Google's surveillance: Whoogle is a self-hosted proxy that strips the tracking and keeps the results. Your query goes from browser to your Whoogle instance, which fetches results from Google with a randomly generated User Agent and strips everything hostile before returning them: no ads or sponsored content, no third-party JavaScript or cookies, no AMP links, no URL tracking tags like utm_source, no referrer header - and Google sees your server's IP, never yours. Unlike metasearch engines that blend sources, Whoogle proxies Google exclusively, so result quality is exactly what you'd get logged out and incognito, minus the noise. A lightweight Flask app configured entirely through environment variables, it supports DuckDuckGo-style bang shortcuts, autocomplete suggestions, safe search, per-country and per-language filtering, site blocklists, and automatic rewriting of social links to privacy front-ends like Nitter and Invidious. Privacy hardening goes further: built-in Tor routing makes Google see an exit node instead of your server, HTTP/SOCKS proxy support covers other setups, and POST-based queries keep search terms out of logs. Light, dark, and fully custom CSS themes plus browser search-engine registration make it a drop-in default on desktop and mobile. Stateless, tiny, and trivial to run.