Rootprint
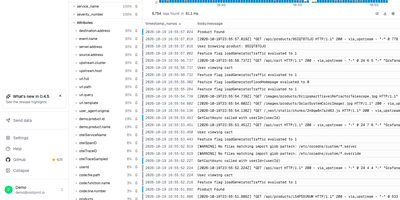
A year of searchable logs and traces no longer needs a metered logging service, because Rootprint keeps the whole index in a storage bucket you already own. A search matches any word on any line, since every log is indexed in full and no service name, stream, or label is needed first. A frequency histogram, one-click field filters, and saved views narrow the results, a fold mode collapses repeated lines, and exports arrive as NDJSON, CSV, or plain text, or as a share link. Open a trace from the log that emitted it, or paste a trace ID, and a waterfall shows per-span timing, attributes, events, and database calls grouped by query, with each span linking back to its logs. The trace explorer charts span volume, error rate, and p50, p95, and p99 latency, ranks the busiest operations, and filters spans by service, duration, and status. Every service gets its own page with request rate, error rate, operations, dependencies, and errors. Data arrives over OpenTelemetry from the Collector, Vector, or Fluent Bit, through a plain HTTP gateway, or by pulling from Kafka, Kinesis, or SQS, with guided setup for nine integrations. Indexes can live in S3, Google Cloud Storage, R2, MinIO, or Azure Blob. Teammates sign in with Google, GitHub, or any OpenID Connect provider, and scoped API keys serve scripts. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Deploy