Blinko
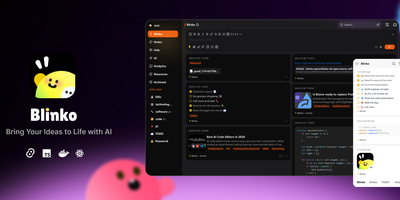
Capture fleeting thoughts as interactive flash cards and transform unorganized notes into an AI-searchable personal brain with Blinko. Users can jot down rapid notes, format rich markdown documents with code snippets and task lists, and attach multimedia files through a responsive web interface. An integrated retrieval-augmented generation engine indexes every note into vector embeddings, allowing users to query their entire personal archive using conversational natural language. You can connect local Ollama models or remote providers such as OpenAI, DeepSeek, Anthropic, and Grok to summarize lengthy entries and suggest hierarchical classification tags automatically. The interactive daily review interface presents random cards to help review, organize, or archive older insights before they are forgotten. Built-in tools include an integrated global music player for focused writing sessions, custom RSS feed ingestion, and password-protected note sharing with configurable expiration dates. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Sourcebot
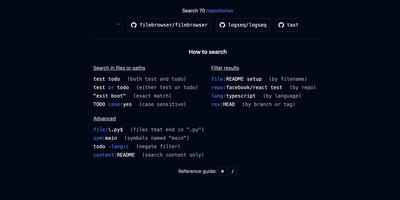
Point Sourcebot at your GitHub, GitLab, Bitbucket, Azure DevOps, Gerrit, or Gitea repositories and get regex, symbol, and filtered search results in under a second across thousands of repos and branches. Backed by Y Combinator with production deployments at NVIDIA, Shutterstock, SeatGeek, Arista, and Red Hat, the Zoekt-powered engine deploys as a single Docker container with zero external data transmission. Ask Sourcebot connects reasoning models like Claude Opus to your entire codebase, enabling natural language questions that return structured answers grounded with inline citations and navigable code snippets, backed by automatic tool calls that search code, follow references, and read files across all indexed repositories. Ask connectors extend this to Jira, Slack, Linear, and Confluence via MCP, pulling external context alongside code for debugging and documentation. IDE-level code navigation provides goto definition and find all references across repository boundaries without local cloning. The built-in file explorer renders any indexed file with syntax highlighting, breadcrumb navigation, and git blame showing per-line commit attribution. An analytics dashboard tracks daily, weekly, and monthly search activity. Permission syncing from GitHub and GitLab enforces access control lists so users only see repositories they are authorized to access. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Other licensed.
LobeHub
With over 82,000 GitHub stars and 700,000+ downloads, LobeHub has evolved from its origins as LobeChat into a comprehensive multi-agent AI collaboration platform where humans and autonomous agent teams co-evolve. The platform's Agent Harness architecture functions as an operating system between AI models and applications, handling prompt presets, tool orchestration, lifecycle hooks, planning, filesystem access, and sub-agent management across 25+ model providers including OpenAI, Anthropic Claude, Google Gemini, DeepSeek, Mistral, Groq, AWS Bedrock, Azure OpenAI, and local models through Ollama. Agent Groups enable sophisticated collaboration with sequential, parallel, iterative, and debate orchestration modes, allowing multiple specialized agents to tackle complex workflows simultaneously. The Agent Builder creates production-ready agents from natural language descriptions with auto-configuration, drawing from a marketplace of 505+ pre-built agents and 10,000+ MCP-compatible skills and plugins. Pages provide collaborative document editing with multi-agent co-authoring, while Schedules automate agent runs around the clock without human supervision. The knowledge base leverages PostgreSQL with pgvector for RAG-powered retrieval, and Personal Memory gives agents transparent, editable context that evolves through continual learning. The full self-hosted stack deploys via Docker Compose with PostgreSQL, Redis, RustFS for S3-compatible storage, and SearXNG for private web search, all configurable through environment variables. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. LobeHub Community licensed.
LightDash
With 5,600+ GitHub stars and deep dbt integration, Lightdash is the open-source Agentic BI platform that treats analytics like software — defining metrics, dimensions, joins, permissions, and caching in a governed context layer that powers dashboards, AI agents, data apps, embedded analytics, and MCP server endpoints simultaneously. The dbt Write-Back feature lets business users create custom metrics and models in the UI, then automatically generates pull requests in GitHub or GitLab so every change flows through code review and CI validation before reaching production. Context-specific AI analysts automatically select relevant models and metrics, build queries, and present insights in plain English, while row-level security, user attributes, and customer-facing permissions ensure data governance at every layer. The platform connects to BigQuery, Snowflake, Redshift, Databricks, PostgreSQL, Trino, and ClickHouse through warehouse adapters, with the TypeScript monorepo built on React, Mantine, Vite, and TanStack Query on the frontend plus Node.js, Express, Knex, and PostgreSQL on the backend. Data teams build analytics with coding agents, preview changes from the CLI, validate in CI pipelines, and review charts and dashboards in pull requests — making the entire analytics lifecycle version-controlled and reproducible. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
MiroFish
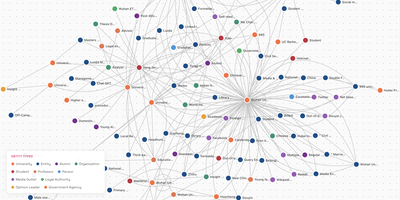
Upload a report, ask a "what if" question in plain language, and MiroFish builds a small simulated society that plays out the answer before you commit to a decision. It reads your seed documents, whether news, policy drafts, financial signals, or a novel, and extracts entities and relationships into a GraphRAG knowledge graph. Entities from the graph become agents with a profession, a biography, and interest tags, and the app estimates simulation rounds from the simulated time span, with a custom mode for shorter runs. Agents post and react on two simulated platforms at once, a feed-style plaza and a topic community, while a live monitor tracks rounds, elapsed simulated time, and actions. A ReportAgent then plans an outline and writes the prediction report section by section with the InsightForge, PanoramaSearch, QuickSearch, and InterviewSubAgent tools. Afterward you can keep questioning the ReportAgent, chat with any individual agent, or send a survey question to a selected group and read their answers. Typical uses include rehearsing public relations responses, testing policy drafts against likely reactions, and exploring alternate endings for a story. The interface switches between English and Chinese, and you bring your own model: any OpenAI SDK compatible LLM endpoint works, Zep Cloud stores agent memory, and the project suggests starting under 40 rounds because runs consume many tokens. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
World Monitor
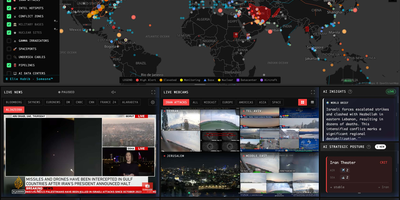
World Monitor replaces twenty or more browser tabs by fusing geopolitical, military, financial, and infrastructure signals onto a single interactive canvas built with TypeScript, Vite, globe.gl with Three.js for the 3D globe, and deck.gl with MapLibre GL for the flat map. World Monitor ingests live data from 530 upstream sources including ACLED and UCDP for conflict events, OpenSky Network for military and civilian aircraft, AISStream for vessel positions, NASA FIRMS for satellite fire detection, USGS for earthquakes, and FRED, IMF, BIS, and Finnhub for macroeconomic and market data. The Country Instability Index v8 computes real-time stress scores across 31 Tier-1 nations, while the finance radar tracks 29 stock exchanges, commodities, and cryptocurrency with a 7-signal market composite. Six specialized dashboard variants — World, Tech, Finance, Commodity, Energy, and Happy — deploy from a single codebase. AI summarization runs locally through Ollama and LM Studio integration or optionally via Groq and OpenRouter cloud providers, with Transformers.js powering browser-side inference. The platform supports 26 languages with native-language feeds and RTL layout, and provides MCP server integration for AI agent connectivity. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Octop
Modern engineering teams and busy households deploy Octop to run private, autonomous AI agents equipped with persistent memory workspaces, scheduled cron jobs, and direct browser automation. Users can orchestrate specialist agents tailored for software development, IT operations, content generation, and system diagnostics through an interactive React dashboard. The platform connects directly to Discord, Feishu, DingTalk, and WeCom, allowing team members to delegate complex tasks without leaving their everyday messaging apps. An integrated remote desktop and browser control engine lets agents navigate websites, capture screenshots, fill forms, and operate graphical software autonomously. Administrators can assign distinct MBTI personality profiles to agents, establish granular role-based permissions, configure scheduled cron workflows, and integrate custom Model Context Protocol servers for external tool access. Long-term memory persists across conversations through dedicated workspace files, ensuring contextual continuity whenever switching between underlying language models or team collaborators. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Frappe Insights
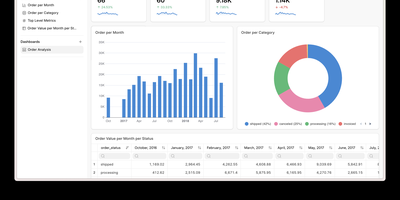
Frappe Insights delivers a self-hosted business intelligence platform where non-technical users build complex analytical queries without writing SQL. The visual query builder uses Ibis under the hood to compose optimized SQL from drag-and-drop column selections, filters, aggregations, and group-by operations — translating point-and-click interactions into performant database queries across MySQL, PostgreSQL, DuckDB, and BigQuery. The join editor provides a graphical interface for defining multi-table relationships, letting analysts connect data across schemas without understanding foreign keys or join types. The chart builder renders interactive visualizations using Apache eCharts with support for bar, line, area, pie, scatter, funnel, and pivot table chart types — each configurable with axes, colors, legends, and formatting options. Dashboards combine multiple charts into shareable views with layout customization, auto-refresh intervals, and filter propagation across widgets. Data source management handles connection pooling across multiple databases simultaneously, enabling cross-database analysis in single queries. Server scripts extend query capabilities with custom Python transformations for complex business logic that visual tools cannot express. Built on the Frappe Framework's full-stack architecture, deployment uses Docker via the official easy-install script that provisions the complete stack including MariaDB, Redis, and Nginx. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
SurfSense
Positioned as the open-source NotebookLM alternative for AI agents, SurfSense delivers a live web research platform where your agents access structured data from Reddit, YouTube, Instagram, TikTok, Amazon, Walmart, Google Maps, Google Search, Indeed, and any page on the open web through one REST API or MCP server. Scheduled and event-triggered agents transform findings into briefs, alerts, podcasts, and presentations, while a built-in knowledge base keeps every discovery searchable with Perplexity-style cited answers using hybrid semantic and full-text search powered by PostgreSQL with pgvector. Upload PDFs, Office documents, images, and audio files, or sync Google Drive, OneDrive, and Dropbox — 50+ file formats supported with AI file sorting that auto-organizes documents by source, date, and topic. The MCP server exposes scrapers, knowledge base, and workspaces as native tools for Claude, Cursor, and any MCP-compatible agent. Cross-country proxy rotation handles Reddit, TikTok, and Google Search scraping with geo-aware sticky sessions and captcha-aware anti-bot handling. The platform features collaborative chats, multi-format document export, git-native knowledge base with Open Knowledge Format export, and a desktop quick-ask panel with global shortcut. Docker Compose deployment manages nine services including Caddy proxy, PostgreSQL, Redis, FastAPI backend, Celery workers, zero-cache real-time sync, and Next.js frontend with automatic Watchtower updates. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Erxes
Replacing HubSpot, Zendesk, Intercom, and Linear with a single self-hosted platform, erxes delivers an Experience Operating System trusted by over 4,000 GitHub stars and built on a modern Nx-powered monorepo architecture. The core ships with six foundational modules — My Inbox for omnichannel conversations across email, web chat, voice, and Discord; Contacts for unified customer profiles; Products for catalog management; Segments for behavioral targeting; Automation for visual workflow builders; and Documents for template generation. Beyond the core, a plugin marketplace activates Frontline for ticket management and omnichannel support queues, Sales for deal pipelines and lead scoring, Operations for project boards with cycle management, Content for headless CMS and knowledge bases, and Team for employee directories, time clocks, and internal chat. The technical stack combines GraphQL Federation with Apollo Server v4 and tRPC v11 microservices on Node.js, React 18 micro-frontends via Rspack Module Federation with TailwindCSS 4, MongoDB with Mongoose for persistence, Redis for caching, BullMQ for job queues, and Elasticsearch for full-text search. Deployment supports Docker Compose orchestration with automatic service discovery across all plugin containers. The Global Profile architecture enables agencies to manage multiple client brands under a single login with separated data stores. iOS and Android SDKs embed the messenger widget directly into mobile applications. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
RAGFlow
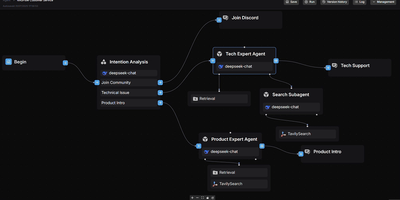
RAGFlow has established itself as one of the most widely adopted open-source RAG engines available, powering production AI systems that demand traceable, hallucination-free answers from complex enterprise data. The platform processes PDF, DOCX, Excel, and PPT files through vision-based deep document understanding with layout analysis and OCR, extracting structured knowledge from tables, charts, and images that simpler parsers miss entirely. RAGFlow's hybrid retrieval pipeline combines vector search with BM25 keyword matching and multi-stage reranking across configurable document stores including Elasticsearch, InfiniFlow's Infinity engine, OpenSearch, and OceanBase. Developers connect any combination of LLM providers — OpenAI, DeepSeek, Anthropic Claude, Google Gemini, and locally-hosted models via Ollama — through a unified configuration layer. The visual agent workflow system enables multi-step reasoning chains with persistent memory, tool calling, and pre-built templates for common enterprise scenarios. RAGFlow synchronizes data from Confluence, S3, Notion, and Google Drive, and delivers answers through chat integrations with Feishu, Discord, Telegram, and Line. The Python SDK and RESTful API on port 9380 provide programmatic access to knowledge base management, document parsing, and conversational retrieval. The full stack deploys via Docker Compose with MySQL for metadata, Redis for task orchestration, and MinIO for object storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Apache Superset
Powering data analytics at companies like Airbnb, Twitter, and Lyft where it originated, Apache Superset has become the leading open-source business intelligence platform with over 65,000 GitHub stars and an Apache Software Foundation top-level project designation. The platform ships with over forty visualization types out of the box including geographic maps, time-series charts, pivot tables, heatmaps, treemaps, and Sankey diagrams, all rendered with Apache ECharts for publication-quality output. Its SQL Lab provides a full-featured IDE experience with syntax highlighting, autocomplete, query history, and result caching for interactive data exploration. Superset connects natively to PostgreSQL, MySQL, ClickHouse, Trino, Presto, BigQuery, Snowflake, Apache Druid, Apache Hive, and dozens more databases through SQLAlchemy connectors, with support for custom database drivers via Python plugins. The semantic layer allows data teams to define calculated columns, metrics, and virtual datasets that business users can query without writing SQL. Role-based access control with row-level security enables fine-grained data governance, while the embedded analytics SDK lets you integrate dashboards directly into external applications via iframes with SSO pass-through. The caching layer supports Redis and Memcached for query result caching, and the asynchronous query execution engine powered by Celery handles long-running queries without blocking the UI. Alerts and reports can be scheduled via email or Slack with PNG or CSV attachments generated from any chart or dashboard. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Pythia
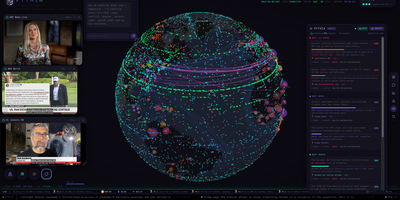
With over 400 GitHub stars and growing, Pythia transforms a local LLM into a self-calibrating geopolitical oracle that watches the entire planet and predicts what happens next — no API keys, no cloud, no cost. The Osiris-based Three.js globe frontend streams 30+ concurrent live feeds including GDELT geopolitics, armed conflict events, USGS earthquakes, NWS storm polygons, EONET disasters, FIRMS wildfires, Polymarket crowd odds, cryptocurrency and commodity prices, UNHCR displacement data, WHO disease outbreaks, and WFP food insecurity indicators. The FastAPI backend fuses these heterogeneous sources into a unified world brief, pipes it through Ollama, and generates located predictions across 24-hour, weekly, monthly, and yearly horizons — each carrying a probability, reasoning, and geocoordinates that fly the globe to the event. A council of four specialist swarm agents — Strategist, Economist, Naturalist, and Skeptic — re-scores every forecast, surfacing consensus, dissent, and splits through Brier-weighted voting where historically accurate personas earn louder votes. The engine maintains a persistent ledger graded by an LLM judge against archived world state, producing running Brier scores and calibration charts. Signal rules fire browser notifications and webhooks when conditions match, a morning brief digest summarizes overnight changes, and the agent API at port 8088 delivers the complete world view in a single JSON call compressed to approximately 50 tokens for AI agent consumption. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Flowsint
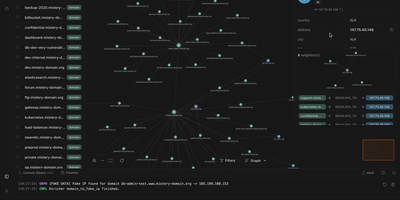
Flowsint turns scattered OSINT leads, like a domain, a username, an email, or a crypto wallet, into one interactive graph that you expand with a right click. Drop an entity on the canvas, run an enricher, and the results appear as new nodes with their relationships already drawn in. Over 30 built-in enrichers cover subdomain discovery, WHOIS and historical records, DNS and ASN lookups, IP geolocation, username searches with Maigret and Sherlock, breach checks for emails and phone numbers, Gravatar profiles, website crawling for contacts and tracking codes, and Ethereum wallet transactions and NFT transfers. Chain enrichers into flows so each output feeds the next step, then replay the same flow on any entity of that type. Missing a source? Write an enricher template in YAML, or describe the API in plain language and let the built-in AI draft it, with API keys kept in an encrypted vault instead of config files. Custom entity types, aliases, tags, JSON import and export, and basic role-based access control make it workable for small teams, and an n8n connector pipes findings into alerts and reports. Double-click the canvas to add items fast, or alt-drag between nodes to link them. Every graph stays on your own server, and no default accounts exist. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Knowhere
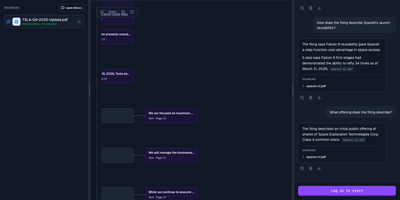
With 2,600+ GitHub stars since its May 2026 open-source launch, Knowhere solves the last-mile problem of document intelligence for AI systems — transforming complex unstructured PDFs, reports, and multi-page documents into structured JSON chunks that LLMs can consume without hallucination. The platform processes documents through an AI-native parsing pipeline that handles 20+ page documents with deep hierarchies, intricate tables, and multimodal content including images with OCR, achieving 95% precision in information extraction while reducing token costs by 50% compared to raw document ingestion. The knowledge tree architecture maintains historical context across multiple documents, enabling cross-document graph navigation for agentic retrieval that goes beyond simple chunk-based RAG. Built on Python 3.11+ with MinerU as the default PDF parser, the backend API runs alongside async workers that process document ingestion, graph construction, and embedding generation. The self-hosted Docker Compose stack packages the API server, processing workers, and Next.js dashboard for managing API keys, webhooks, and document-processing jobs, backed by PostgreSQL and Redis. Both Python and Node.js SDKs provide programmatic access for integration into existing AI pipelines and agent frameworks. LLM providers include DeepSeek and Alibaba Cloud DashScope with configurable key rotation for rate-limit management. Deploy on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Metabase
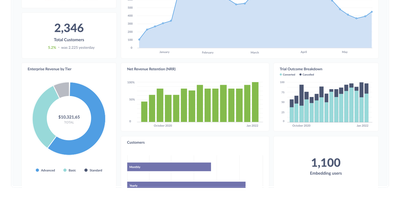
The most widely deployed open-source BI tool, Metabase is a visualization and query layer that sits on top of your existing databases without ingesting or copying data. Non-technical users ask questions through a visual query builder with drill-through menus that answer follow-ups like "broken down by month" without writing a new query, while analysts use the native SQL editor with variables and templates for complex work. Questions assemble into interactive dashboards with filters, auto-refresh, fullscreen mode, and custom click behavior, and dashboard subscriptions email or Slack scheduled reports to stakeholders. It connects to 20+ data sources including PostgreSQL, MySQL, MongoDB, SQL Server, BigQuery, Snowflake, Redshift, and ClickHouse - always querying in place, so there is no second data store to secure, sync, or pay for, and results are always current. Models and metrics let a data team define official, reusable starting points so self-service stays consistent, collections with permissions organize content, and alerts fire when a metric crosses a threshold. The practical effect is cutting the ad-hoc query queue that lands on the data team, since non-technical staff can answer their own questions. Written in Clojure, licensed AGPL, and shipped as a single JAR or Docker image with an embedded application database - a working BI instance runs before most tools finish their installer - the open-source edition has no limits on users, dashboards, or connected databases, where commercial BI platforms price per viewer as well as per creator.
Duckle
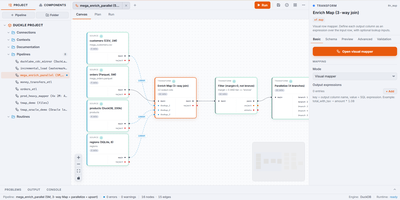
Duckle compiles visual data integration pipelines into vectorized analytical SQL executed on an embedded columnar engine, eliminating the overhead and cloud egress costs of traditional ETL infrastructure. Engineers can construct data pipelines on a drag-and-drop canvas, connecting hundreds of data sources spanning relational databases, cloud object storage, streaming event buses, vector databases, and SaaS application programming interfaces. An interactive mapping editor enables complex joins between primary data inputs and lookup streams with typed transform expressions and live sample inspections. Built-in transformation blocks execute change data capture, slowly changing dimensions, aggregation rollups, and integrated dbt models with zero row-based metering or cloud egress fees. Teams schedule headless production executions through a dedicated web console equipped with role-based access management, execution audit trails, and automated failure alerts dispatched to webhook endpoints. Embedded Model Context Protocol capabilities allow AI coding assistants to validate schema configurations, inspect execution logs, and trigger batch workflows directly through conversational commands. Workspaces store entire pipeline definitions as individual files in version control, ensuring reproducible deployments across staging and production environments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Google Maps Scraper
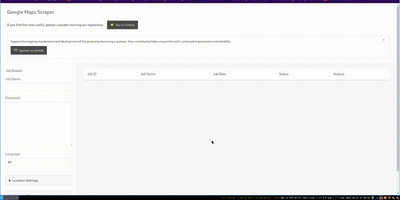
The leading open-source tool for extracting business leads from Google Maps at production scale. The Go-based engine processes approximately 120 places per minute with optimized concurrency, extracting 33+ data points per listing including business name, address, phone number, website URL, rating, review count, latitude and longitude, opening hours, price level, and optionally crawling business websites for email addresses. Three interfaces serve different workflows: the CLI accepts query files for cron jobs and CI/CD pipelines with output to CSV, JSON, PostgreSQL, S3, or LeadsDB; the Web UI provides a browser-based dashboard with real-time job monitoring, a map view of scraped places, and interactive query submission; and the REST API at /api/v1 enables programmatic integration with full Swagger documentation at /api/docs. Built-in proxy rotation supports SOCKS5, HTTP, and HTTPS with authentication for large-scale runs, while the architecture scales from a laptop to Kubernetes clusters with queue-based worker distribution. The SaaS edition adds multi-user access with API key management, admin UI with 2FA, job queue orchestration, and one-command cloud deployment via an interactive wizard. An AI Agent Skill enables coding agents to run scrapes programmatically. Deploy via Docker or build from source requiring Go 1.26.5+. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.