Memoh
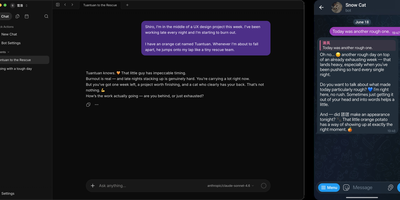
Memoh delivers an open-source multi-agent platform where every AI agent gets its own computer — not a chat window but a fully isolated container with dedicated filesystem, desktop environment, browser, network stack, and persistent long-term memory that survives across sessions, days, and platforms. The containerd-based runtime ensures each bot operates in complete isolation with snapshot and data import/export capabilities. The memory engine uses LLM-driven fact extraction with hybrid retrieval combining dense embeddings via Qdrant, sparse vectors, and BM25, plus 24-hour context loading and automatic compaction — with Mem0 and OpenViking as drop-in alternatives. Ten communication channels connect agents to users through Telegram, Discord, Lark, QQ, Matrix, WeCom, WeChat, Email, Web UI, and group chats with cross-platform identity binding. MCP tool calling enables agents to interact with external services, while browser automation drives GUI workflows for web research and data extraction. Agent hosting supports running external coding agents like Codex and Claude Code inside Memoh workspaces via ACP with per-bot configuration. Scheduled tasks run without human triggers, and agents proactively reach out when needed. The web dashboard built with Vue 3 and Tailwind CSS provides streaming chat, tool call visualization, file management, model and provider configuration, and bot lifecycle management. Deploy via Docker Compose with PostgreSQL, Qdrant, sparse service, and the Go backend server. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
LobeHub
With over 82,000 GitHub stars and 700,000+ downloads, LobeHub has evolved from its origins as LobeChat into a comprehensive multi-agent AI collaboration platform where humans and autonomous agent teams co-evolve. The platform's Agent Harness architecture functions as an operating system between AI models and applications, handling prompt presets, tool orchestration, lifecycle hooks, planning, filesystem access, and sub-agent management across 25+ model providers including OpenAI, Anthropic Claude, Google Gemini, DeepSeek, Mistral, Groq, AWS Bedrock, Azure OpenAI, and local models through Ollama. Agent Groups enable sophisticated collaboration with sequential, parallel, iterative, and debate orchestration modes, allowing multiple specialized agents to tackle complex workflows simultaneously. The Agent Builder creates production-ready agents from natural language descriptions with auto-configuration, drawing from a marketplace of 505+ pre-built agents and 10,000+ MCP-compatible skills and plugins. Pages provide collaborative document editing with multi-agent co-authoring, while Schedules automate agent runs around the clock without human supervision. The knowledge base leverages PostgreSQL with pgvector for RAG-powered retrieval, and Personal Memory gives agents transparent, editable context that evolves through continual learning. The full self-hosted stack deploys via Docker Compose with PostgreSQL, Redis, RustFS for S3-compatible storage, and SearXNG for private web search, all configurable through environment variables. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. LobeHub Community licensed.
Open WebUI
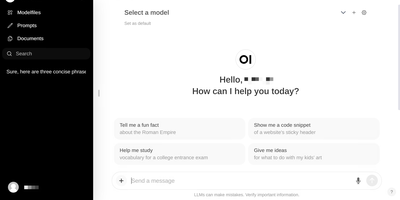
Large language models get a polished front end that can run fully offline: Open WebUI is the self-hosted front end of choice. It talks to local model runners, primarily Ollama, and to any OpenAI-compatible API, so LM Studio, vLLM, Groq, Mistral, OpenRouter, and cloud providers all plug into the same chat interface and can be mixed per conversation. RAG is built in: upload files to knowledge bases or reference them in chat with the # command, backed by a choice of nine vector databases (ChromaDB and PGVector officially maintained) and multiple extraction engines including Tika and Docling, with hybrid BM25-plus-vector search and cross-encoder reranking. Web search results from providers like SearXNG, Brave, and Tavily inject directly into conversations. Extensibility comes from Python tools and functions that run inside the chat, a Pipelines plugin framework, and native MCP support. Multi-user features include RBAC, SSO, and group permissions, and the instance itself exposes an OpenAI-compatible API your own apps can call.
AnythingLLM
Chat with your own documents: AnythingLLM, from Mintplex Labs, wraps retrieval-augmented generation (RAG) in an open-source application anyone can run. You organize content into workspaces, each an isolated namespace with its own documents, vector embeddings, chat history, and settings, so one instance can hold several separate knowledge bases. Upload PDFs, DOCX, TXT, and other formats, or scrape web pages; the built-in collector parses and chunks them into a vector database (LanceDB by default, with Pinecone, Chroma, Qdrant, and others supported). Answers cite their source documents. It works with both cloud LLMs (OpenAI, Anthropic, Gemini) and local ones via Ollama or LM Studio, and the embedding model is separately configurable. Beyond RAG chat, it includes AI agents that can browse the web and run tools, an embeddable chat widget for your website, a developer API, and multi-user mode with admin, manager, and default roles plus per-workspace access control. Context assembly is smarter than naive RAG: pinned documents, attached files, vector search hits, and recent chat history are combined under a token budget so the model's context window is filled efficiently, and each workspace supports multiple independent conversation threads against the same knowledge base. Because the embedding model, vector store, and chat LLM are all independently swappable, you can move between providers without re-ingesting a single document. The stack is Node.js with a React frontend, MIT-licensed.
FastGPT
FastGPT lets you build production AI agents and knowledge base chatbots through a visual drag-and-drop workflow editor, connecting any LLM provider to your documents with retrieval-augmented generation that cites sources and reduces hallucination. The workflow canvas chains LLM calls, conditional branching, HTTP requests, code sandbox execution, and plugin nodes into complex conversation flows and agent skill pipelines without writing backend code. The knowledge base engine ingests documents in ten formats (TXT, Markdown, HTML, PDF, DOCX, PPTX, CSV, XLSX, URL scraping, and CSV batch import) then applies automatic chunking, hybrid vector retrieval with semantic reranking, and QA-pair splitting to deliver accurate, citation-backed answers. FastGPT connects to virtually any LLM provider through its AI Proxy aggregation layer: OpenAI GPT-4o, Anthropic Claude, Google Gemini, DeepSeek, Qwen, ERNIE Bot, and models hosted via Ollama all work through a unified OpenAI-compatible API. Bidirectional MCP support enables agents to call external tools and expose their own capabilities to other systems. Completed applications can be shared via login-free links, embedded as iframe widgets, or integrated with WeCom, Lark, DingTalk, and WeChat Official Accounts through the published REST API. Application operation logs, conversation annotation, and per-model usage analytics provide full lifecycle governance for compliance-sensitive deployments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. FastGPT Open Source License (Apache 2.0 based) licensed.
Letta
With over 24,000 GitHub stars and origins in the MemGPT research paper on virtual context management, Letta has evolved into the leading open-source platform for building AI agents that maintain persistent memory, identity, and continuity across sessions rather than operating as stateless prompt-response loops. The core architecture uses memory blocks — structured, labeled text chunks that reside permanently in the agent's context window — allowing agents to programmatically rewrite their own memory, learn new skills, and improve through a sleeptime dreaming process that runs reflection and memory organization during idle periods. The self-hosted App Server deploys via Docker and exposes a WebSocket API on port 4500, letting the TypeScript Agent SDK connect from any application using local, remote, or cloud backends. Agents support git-versioned memory through MemFS where every memory change is tracked and auditable, multi-agent communication via subagents, scheduled tasks, and integration with messaging platforms including Slack, Discord, Telegram, WhatsApp, and Signal. The platform is fully model-agnostic, routing to OpenAI, Anthropic, xAI, or self-hosted open-weight models through Ollama depending on cost, performance, and data residency requirements. The Agent File format serializes complete agent state — memory, skills, prompts, and conversation history — into portable snapshots. Desktop applications for macOS, Windows, and Linux provide native interfaces alongside the terminal CLI and web chat at chat.letta.com. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Botpress
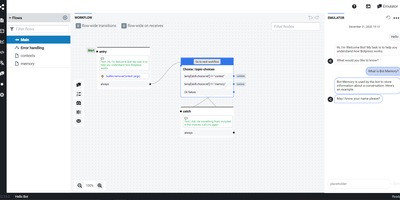
Build, deploy, and monitor chatbots and LLM-powered agents on one open-source conversational AI platform: Botpress. Its Studio is a visual development environment: a drag-and-drop canvas arranges conversation logic with nodes for messages, questions, choices, and actions, while a built-in emulator simulates conversations for debugging before anything goes live. Agents ground their answers in a knowledge base assembled from uploaded documents, ingested websites, and past conversations via retrieval-augmented generation, and the LLM layer connects to multiple model providers - GPT-4, Claude, Mistral - with a configurable model strategy. An autonomous engine handles reasoning, tool orchestration, persistent memory across sessions, and sandboxed code execution, and custom code actions in TypeScript extend agents past prebuilt workflows. Over 100 integrations deploy the same bot to WhatsApp, Telegram, Slack, Microsoft Teams, and web chat, and connect it to HubSpot, Zendesk, Zapier, and arbitrary APIs and webhooks. Human handoff, conversation analytics, and quality monitoring cover production operation. Originating in 2017 from a Montreal team, the community edition is developed openly on GitHub.
big-AGI
big-AGI is an open-source generative AI workspace that provides a unified, local-first interface for orchestrating multi-model reasoning, automated code execution, and custom persona workflows across private infrastructure. Users query multiple large language models simultaneously through the Beam scatter-gather engine, which prompts independent AI systems in parallel, compares candidate completions side by side, and merges optimal passages into a single refined response. Knowledge workers assemble tailored AI personas equipped with specialized system instructions, custom temperature settings, and predefined document context to handle domain-specific tasks ranging from architectural design reviews to legal contract analysis. The application renders rich multimedia outputs including interactive Mermaid sequence diagrams, LaTeX mathematical formulas, syntax-highlighted code blocks with live execution previews, and AI-generated image generation canvases. Teams integrate local inference servers like Ollama and LocalAI alongside commercial API endpoints to route confidential datasets strictly through internal networks while monitoring per-prompt token usage and operational latency. Users attach complex PDF documents, spreadsheets, and source code repositories for automatic parsing and semantic retrieval, while local-first storage engines ensure private chat transcripts and custom presets remain encrypted on host drives. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
PicoClaw
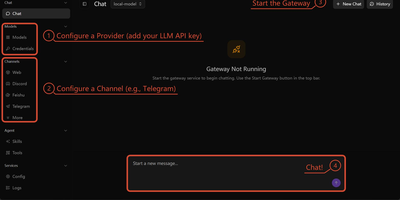
An 8MB Go binary that boots in under one second, uses less than 10MB of RAM, yet delivers full AI agent capabilities across 16+ chat platforms simultaneously. PicoClaw connects to Telegram, Discord, Matrix, IRC, Slack, WeCom, DingTalk, WeChat, LINE, and QQ while supporting LLM providers spanning OpenAI, Anthropic, Gemini, DeepSeek, AWS Bedrock, Azure, and local models via Ollama. Native Model Context Protocol support enables standardized tool integration, and the built-in smart routing engine directs simple queries to lightweight models to reduce API costs while sending complex tasks to capable models. Tool capabilities include secure shell execution, filesystem access, web search, cron scheduling for recurring tasks, and sub-agent spawning with status tracking. Gateway mode transforms PicoClaw into a full AI backend with REST API endpoints accessible from any client. The Skills system loads hierarchical behavior definitions from SKILL.md files, enabling customizable agent personalities and workflows. Compiles for x86_64, ARM64, ARMv7, RISC-V, MIPS, and LoongArch, making it deployable on hardware as cheap as a $10 Sipeed LicheeRV Nano. Achieved nearly 30,000 stars within six months of its February 2026 release. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
RAGFlow
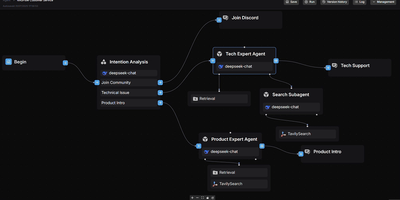
RAGFlow has established itself as one of the most widely adopted open-source RAG engines available, powering production AI systems that demand traceable, hallucination-free answers from complex enterprise data. The platform processes PDF, DOCX, Excel, and PPT files through vision-based deep document understanding with layout analysis and OCR, extracting structured knowledge from tables, charts, and images that simpler parsers miss entirely. RAGFlow's hybrid retrieval pipeline combines vector search with BM25 keyword matching and multi-stage reranking across configurable document stores including Elasticsearch, InfiniFlow's Infinity engine, OpenSearch, and OceanBase. Developers connect any combination of LLM providers — OpenAI, DeepSeek, Anthropic Claude, Google Gemini, and locally-hosted models via Ollama — through a unified configuration layer. The visual agent workflow system enables multi-step reasoning chains with persistent memory, tool calling, and pre-built templates for common enterprise scenarios. RAGFlow synchronizes data from Confluence, S3, Notion, and Google Drive, and delivers answers through chat integrations with Feishu, Discord, Telegram, and Line. The Python SDK and RESTful API on port 9380 provide programmatic access to knowledge base management, document parsing, and conversational retrieval. The full stack deploys via Docker Compose with MySQL for metadata, Redis for task orchestration, and MinIO for object storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
EDDI
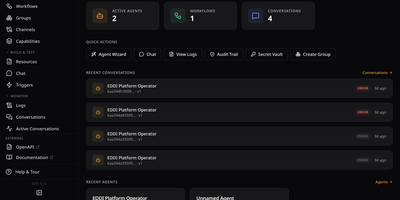
Deploy autonomous conversational AI agents and coordinate complex multi-agent workflows through EDDI, an open-source orchestration middleware that turns declarative configuration files into secure, production-grade enterprise assistants. Engineering teams connect AI models from twelve different commercial and local providers, using bilateral Model Context Protocol tools to let external desktop clients and coding assistants interact directly with running conversational services. Autonomous agents collaborate through structured group interaction patterns including round table discussions, peer reviews, Delphi consensus rounds, and devil's advocate debates to refine generated solutions before delivery. Declarative workflow extensions automate external REST API calls with dynamic request templating, extracting structured properties into persistent conversation memory and chaining multi-step service interactions without custom script glue. Built-in secret vaults safely manage sensitive API credentials, while the centralized web dashboard provides live conversation inspection, token quota enforcement, and comprehensive audit logging for regulatory compliance. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Typebot
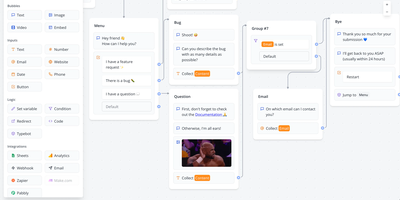
A fair-source chatbot and conversational-form builder: Typebot assembles conversations in a visual graph editor. In a visual graph editor you chain blocks from four categories: bubbles display text, images, video, audio, and embeds; inputs collect data through text fields, email, phone, buttons, picture choices, date pickers, file uploads, and Stripe payments; logic blocks handle conditional branching, variables, URL redirects, A/B testing, and custom JavaScript; integration blocks call webhooks, OpenAI, Google Sheets, Google Analytics, Meta Pixel, Zapier, Make, and Chatwoot. Build once, deploy anywhere: custom domains, WhatsApp, or embedded in any site as a container, popup, or chat bubble through a fast native JS library with no iframe and no external dependencies - plus an HTTP API for executing bots programmatically from any language. Theming covers fonts, colors, roundness, and shadows with custom CSS and reusable templates, and results arrive in real time with drop-off and completion analytics plus CSV export. Two Next.js apps (builder and viewer) self-host via Docker under the Functional Source License, which converts to Apache 2.0 after two years.
Nanobot
With over 46,000 GitHub stars, nanobot is the ultra-lightweight personal AI agent framework that delivers full agentic capabilities — tools, persistent memory, multi-agent workflows, scheduled automation, and 10+ chat channel integrations — in approximately 4,000 lines of readable Python core code. The agent loop receives messages from any connected channel, builds context from session history and long-term memory files, calls the configured LLM provider, executes requested tools, and publishes replies back to the originating channel. Supported LLM providers include OpenAI, Anthropic, Google Gemini, DeepSeek, Qwen via DashScope, Moonshot/Kimi, Ollama, vLLM for local models, and any OpenAI-compatible API through OpenRouter or LiteLLM. Chat channels connect the agent to Telegram, Discord, Slack, WhatsApp, Feishu/Lark, DingTalk, Email via IMAP/SMTP, QQ, Matrix with end-to-end encryption, Mattermost, and the built-in browser WebUI served from the published Python wheel with no separate frontend build. Built-in tools include filesystem read/write/edit, shell execution with configurable sandboxing via bubblewrap, web search and fetch with SSRF protection, MCP server integration, cron scheduling, image generation, and subagent spawning for parallel task delegation. The Dream memory system consolidates session history into persistent markdown files for long-term context retention across conversations. Deployment runs as a CLI agent, a persistent gateway server, a Docker container with Docker Compose, or an OpenAI-compatible API server. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Whatomate
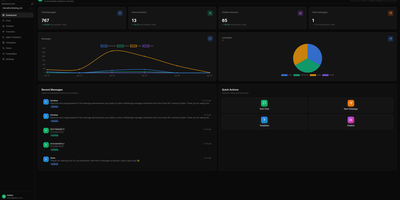
A complete WhatsApp Business Platform covering messaging, chatbot automation, and voice calling with IVR — a combination most self-hosted projects never attempt. The Fastglue/fasthttp backend processes WhatsApp Cloud API webhooks through PostgreSQL and Redis into a real-time WebSocket layer powering instant chat updates across a Vue 3 frontend built with shadcn-vue and TailwindCSS. Chatbot automation supports keyword triggers, multi-step conversation flows with branching logic, AI-powered responses from OpenAI, Anthropic, or Google models, knowledge base integration via vector stores, and seamless handoff to human agents when the bot gets stuck. The visual IVR builder uses a drag-and-drop node canvas where you wire greeting prompts, DTMF menu capture, HTTP callbacks to external APIs mid-call, business-hours routing by IANA timezone, agent team transfers with hold music, and reusable sub-flows. Every call recording streams encrypted to your S3-compatible bucket with retention you control. Multi-tenant architecture isolates organizations with separate data, roles, and API keys while a unified inbox presents both chat and call conversations to agents in a single dashboard. Meta-approved template management, bulk campaign messaging, analytics tracking, and a full REST API round out the platform. Deploy via Docker Compose with Postgres and Redis included. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL v3 licensed.
Flowise
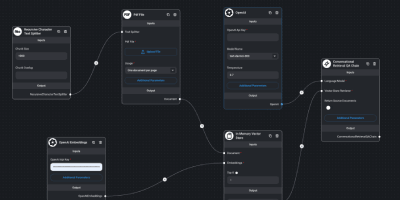
Drag nodes onto a canvas and ship an LLM app: Flowise is an open-source visual builder for AI agents and LLM applications, written in Node.js on LangChain.js and licensed Apache-2.0. You assemble flows by dragging nodes onto a canvas: models, prompts, memory, vector stores, retrievers, and tools, then wire them together and test in the built-in chat panel. Three builder types cover increasing complexity: Assistant for simple RAG chat over uploaded files, Chatflow for single-agent systems with techniques like rerankers and Graph RAG, and Agentflow for multi-agent orchestration with branching, looping, shared flow state, and human-in-the-loop checkpoints. Over 100 integrations connect data sources, vector databases, and both proprietary and open-source models, plus MCP client and server nodes for standard tool interop. Finished flows are exposed as REST APIs, embedded chat widgets, or via JS and Python SDKs - each flow gets an endpoint the moment it is saved, removing the deployment gap between a working prototype and something your application can call. Execution logs, visual step debugging, and external log streaming trace behavior, while input moderation and rate limiting act as guardrails; RBAC, SSO, and workspaces cover team deployments. Self-hosting keeps prompts, encrypted credentials, and conversation data on your own instance, which matters when flows handle internal documents or customer data - and wiring a model, prompt, memory, and vector store on the canvas replaces the boilerplate a hand-coded LangChain project would need.
DeepTutor
With 34,000+ GitHub stars and a v1.5 release driven by 36 merged community pull requests, DeepTutor from Hong Kong University's Data Science Lab delivers a full agent-native learning workspace that goes far beyond chatbot wrappers. Eight integrated surfaces — Chat, Deep Solve, Quiz Generation, Deep Research, Math Animator, Co-Writer, Book generation, and Mastery Practice — share a unified context so the objective follows the learner, not the tool. The platform's three-layer memory architecture (L1 working, L2 session, L3 long-term) makes personalization inspectable rather than opaque, letting users see exactly what the system remembers and why. Knowledge retrieval operates across five pluggable engines — LlamaIndex with FAISS vectors, PageIndex for page-level citations, GraphRAG for knowledge-graph traversal, LightRAG for local or server-offloaded retrieval, and linked Obsidian vaults — with document parsing via MinerU, Docling, markitdown, or PyMuPDF4LLM. Partners extend the tutoring brain to 15+ messaging platforms including Slack, Discord, Telegram, Matrix with E2EE, and Mattermost, each carrying private memory with branch, resume, and replay capabilities. Subagent integration brings Claude Code, Codex, Gemini, and Kimi directly into learning sessions. The system supports 30+ LLM providers from OpenAI and Anthropic to Ollama for fully local operation, with multi-user isolation, admin controls, and a full CLI interface. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Casibase
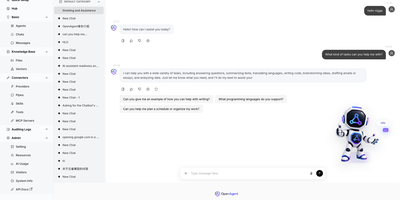
Casibase lets organizations build AI-powered knowledge bases that answer questions from their own documents, connecting to 30+ model providers through a unified admin interface with RAG retrieval and multi-agent orchestration via MCP and A2A protocols. The platform plugs into OpenAI GPT-4o, Anthropic Claude, Meta Llama, Google Gemini, DeepSeek, Ollama local models, HuggingFace, Azure OpenAI, and additional providers, while embedding APIs from OpenAI Ada and Baidu handle vector representation of ingested documents. Document ingestion parses TXT, Markdown, DOCX, PDF, CSV, XLSX, and PPTX files with intelligent chunking strategies for optimal retrieval accuracy. The built-in chat interface provides real-time AI conversations with manual session handover for human agent escalation, and comprehensive chat session logging enables audit trails for compliance. Enterprise identity management integrates Casdoor for Single Sign-On supporting GitHub, Google, WeChat, and OIDC providers with fine-grained access control via the Casbin permission engine. The multi-tenant architecture supports isolated knowledge bases per organization with role-based user management and configurable storage, model, and embedding providers per tenant. The React frontend with Ant Design v5 provides a polished admin dashboard for managing providers, knowledge stores, chat sessions, and user access, while the Go backend with Beego framework handles API logic with MySQL or MariaDB persistence. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Lobe Chat
A private ChatGPT built with Next.js: Lobe Chat is the open-source AI chat interface teams self-host instead. Its main advantage is provider breadth: one interface connects to 40+ model providers, including OpenAI, Anthropic Claude, Google Gemini, Mistral, Groq, AWS Bedrock, Azure, and local models served through Ollama, so you can switch models per conversation and compare outputs. It handles multi-modal work: image recognition, image generation, text-to-speech, and speech-to-text. A plugin system based on function calling and the Model Context Protocol (MCP) adds external tools like web search and code execution. Run it in standalone mode as a single container with settings in browser storage, or in database mode with PostgreSQL and S3-compatible storage for persistent history, multi-user auth, and RAG knowledge bases built from uploaded documents with pgvector retrieval. Because tools arrive through function calling and MCP rather than a proprietary plugin format, custom internal tools can be exposed to the assistant with a standard server over STDIO or HTTP. Hundreds of pre-configured assistant roles import from the community marketplace. For teams the cost model matters: provider API keys billed per token typically undercut a ChatGPT Plus seat per person, and self-hosting keeps API keys, uploaded files, embeddings, and conversation history entirely on your own server.