Uwazi
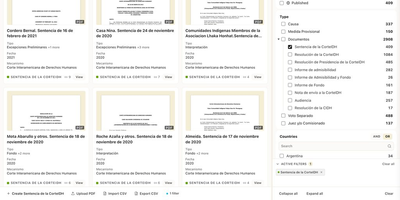
Human rights teams, legal researchers, and archivists use Uwazi to turn scattered documents and case records into searchable, structured collections that the public or trusted partners can explore online. You design templates that define exactly which fields each record carries, from dates and locations to people, organizations, and document types, then import material through the interface or in bulk from CSV files. Uploaded PDFs and documents become full-text searchable, so a phrase buried inside a scanned report is as findable as the metadata typed beside it. Relationships connect related entities across the collection, letting you trace how a person, an event, and a piece of evidence fit together instead of keeping them in isolated folders. Curators build public pages with live filters, maps, and visualizations drawn directly from collection data, while granular permissions decide which records stay private, which are shared with specific groups, and which are published for everyone. Multi-language support lets the same collection serve readers in several languages, and activity logs keep an audit trail of edits. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Papermerge
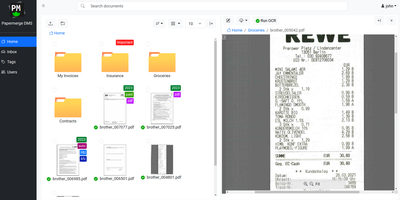
Receipts, contracts, and letters that arrive as pixels rather than text: Papermerge is a document management system built specifically for scanned documents. Upload a PDF, TIFF, JPEG, or PNG and OCR runs automatically, with a real-time status indicator beside the document title; under the hood it drives OCRmyPDF and Tesseract, supporting 130+ languages and producing a new document version with a selectable, searchable text layer you can download. Full-text search runs across everything, with multiple search-engine backends (Xapian by default). The interface deliberately mimics a modern desktop file browser: dual-panel commander, drag and drop, hierarchical folders, and colored tags on documents and folders. Page management fixes what scanners get wrong - delete blank pages, rotate, reorder, merge, extract, and move strayed pages between documents, powered by PikePDF. Document types act as categories, each with its own custom metadata fields, so invoices carry vendor and amount while contracts carry parties and dates. Versioning preserves every state of a document. Multi-user support includes groups, group ownership, permission management, and document/folder sharing between users and groups, and an OpenAPI-compliant REST API automates ingestion from scanners or scripts. Apache-licensed, ideal for long-term digital archives.
Reclip
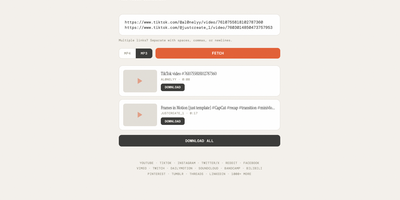
Reclip is a self-hosted web downloader that turns links from YouTube, TikTok, Instagram, and more than a thousand other video sites into MP4 or MP3 files saved on your own server. Paste one link or a whole batch of URLs, and Reclip fetches each video's title, thumbnail, duration, and uploader before you commit to anything. A quality picker lists every available resolution, so a lecture can be grabbed at 360p for a phone while a concert film comes down at full height with the best audio stream merged in. MP3 mode strips the picture away entirely, which makes it painless to archive podcasts, DJ sets, and spoken-word clips as plain audio files. Playlists expand into their individual videos automatically, repeated URLs are deduplicated before any bandwidth is spent, and a Download All button works through the whole queue without babysitting. Each job runs in a background thread with live status in the interface, so the page stays responsive while ffmpeg finishes merging streams behind the scenes. Everything lives behind one clean page with no accounts, no uploads to third-party converters, and no expiring download links, and finished files land in a downloads folder you control. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
SimpleDMS
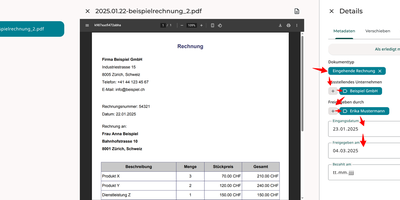
Small businesses file every invoice, contract, and letter by what it is instead of by folder with SimpleDMS, a document management system built around types, tags, and searchable metadata. Upload a document to the inbox, pick its type, and the sidebar offers exactly the tags and fields that type needs, so an incoming invoice asks for the issuing company and receipt date instead of a blank properties page. Name-giving attributes label each file automatically from its own metadata, and the Browse view finds it again by company, date, or approver in seconds. Spaces act as workspaces with their own document types, tags, and permissions, so the team shares project files in one space, exchanges papers with an accountant or customers in another, and keeps private records apart. Tag groups such as companies and employees stay consistent across thousands of documents, date and text fields capture the facts you search by later, and values can be corrected at any time when a document was filed in haste. Dark mode is built in, the interface runs comfortably on a tablet at the scanner, and no analytics or tracking watch how your office works. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
LinkWarden
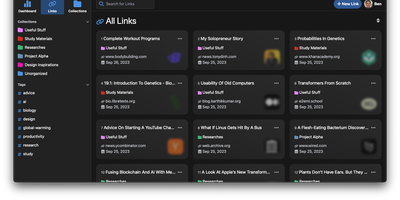
Links rot - the hard truth Linkwarden is built around, as a collaborative bookmark manager that preserves what it saves. Every page you save is fully preserved - a screenshot, a PDF, a self-contained single-file HTML archive (generated by the Monolith Rust binary), and a clean reader view - so the content survives even after the original site disappears. Think of it as a private Wayback Machine you own, with an optional one-click snapshot to archive.org on top. The reading experience matches the archival rigor: a distraction- free reader view supports text highlighting and annotation, and full-text search across everything you have saved is powered by Meilisearch. Optional AI tagging analyzes page content and auto-assigns tags - generate new ones, pick from your existing set, or constrain to predefined tags - with providers ranging from local Ollama models (fully private) to OpenAI, Anthropic, and OpenRouter. Organization is collections, sub-collections, and multiple tags per link; teams collaborate on shared collections with per-member permissions, and public collections share curated link sets (with preserved copies) to anyone. The stack is Next.js/React on TypeScript with PostgreSQL via Prisma, NextAuth supporting credentials, OAuth2, and SAML SSO, and a Playwright-driven headless Chromium worker doing the capture. Native iOS and Android apps and browser extensions feed it from anywhere.
ArchiveBox
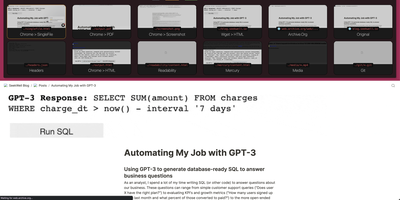
Backed by 27,700+ GitHub stars and actively developed with the v0.9.x architectural overhaul introducing an event-driven plugin ecosystem, ArchiveBox delivers the open-source self-hosted web archiving platform that preserves websites, bookmarks, social posts, media, source code, and research material in durable formats before link rot, platform shutdowns, and censorship erase them permanently. Feed it URLs one at a time or schedule automated imports from browser history, RSS feeds, Pocket, Pinboard, Instapaper, Wallabag, Shaarli, JSON, CSV, HTML bookmark exports, and browser extension captures. Each snapshot stores redundant copies as original HTML, rendered single-file HTML via SingleFile, full-page PDF, screenshot PNG, WARC archive, article text via Readability, favicons, HTTP headers, media files via yt-dlp, git repository clones, and structured metadata in SQLite. The Docker Compose deployment bundles Chrome, wget, curl, yt-dlp, SingleFile, and Readability parsers with automatic dependency management and isolation. Interact through the self-hosted web UI with search, tagging, and admin controls, the comprehensive CLI for batch operations, the REST API for programmatic access, or the Python API for custom integrations. The new abx-plugins system enables community extractors with per-plugin configuration, while the append-only-log architecture provides resumable crawls and audit trails. S3, B2, and Google Cloud storage backends sync archives to remote storage via rclone. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Clu Comics
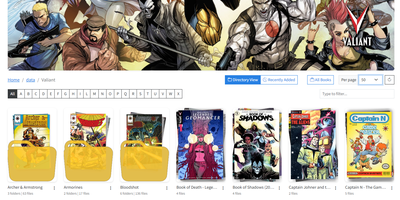
Comic Library Utilities (CLU) is a self-hosted comic library manager that converts, repairs, tags, downloads, and reads your entire comic collection from one web interface. Convert whole folders or libraries from CBR to CBZ in bulk, turn PDFs into CBZ with JPEG or WebP output, and rename thousands of files to one consistent pattern without touching a terminal. Open any CBZ in the browser editor to reorder pages, add or delete images, crop covers, split merged multi issue archives, and adjust contrast and brightness issue by issue. Write ComicInfo.xml from Metron, ComicVine, Grand Comics Database, AniList, MangaDex, MangaUpdates, or Bedetheque, then bulk apply tags across a directory with review before saving and a history log that can revert any change. Browse your library by publisher, series, or folder, read page by page in the built in reader that remembers your place, and follow weekly release calendars with a pull list and Wanted tracker for issues you do not own yet. Download new issues from Direct Download sources, Usenet through Newznab indexers with SABnzbd or NZBGet, and DC++, while folder monitoring unpacks, converts, renames, and files new arrivals automatically. Add Reader, Clerk, and Store Owner accounts with per folder permissions, publish OPDS feeds for reader apps, and sync reading history with Komga. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
PaperPull
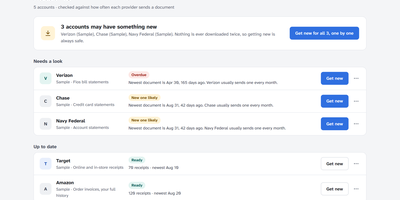
Years of bank statements, pay stubs and receipts sit scattered across dozens of websites, each demanding a login and offering one PDF at a time. PaperPull fetches that whole history for you: sign in yourself in a real browser window, answer the two-factor prompt, and it downloads statements, receipts, pay statements, W-2s and tax forms from 73 supported providers including Chase, Amex, ADP, Amazon, Walmart, Vanguard and Verizon. The tool only ever downloads; it never pays a bill, moves money or changes a setting, and that read-only promise is enforced by construction rather than by policy. Every archive is checked for freshness and for holes in the middle, so a series that looks current but quietly skipped three months is flagged by name, with per-account cadence learned from your own documents. Receipts become one long spreadsheet of every item you have ever bought across every store, with prices and dates, while transactions are read out of statement PDFs into workbook rows that are verified against each statement's printed beginning and ending balances. New documents can flow straight into a Paperless-ngx consume folder, everything runs under a password you choose on your own network, and no cloud account is involved anywhere. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Shiori
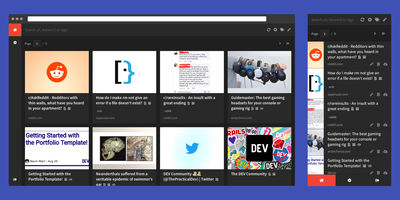
Most web links eventually break - the sobering statistic Shiori, a bookmark manager with archiving by default, is built on. Its answer is archiving by default - where possible, every bookmark you save gets a clean, readable offline copy parsed from the page, ads and navigation stripped, so the article survives even after the original URL dies. Conceived as a simple Pocket clone and written in Go, the entire server is a single binary using roughly 25-30 MB of RAM with SQLite out of the box (Postgres and MySQL supported) - genuinely the lightest archiving bookmark manager you can run. Saving is one click through the Firefox and Chrome extensions, and finding things again is where Shiori quietly outperforms its size: full-text search covers the archived page content, not just titles and tags, so you can find that article by a phrase you remember from paragraph six. Reader mode presents the cleaned text; archive mode shows the preserved page. It's dual-interface by design - a pretty web UI (installable as a PWA on mobile) and a complete CLI for terminal devotees - plus a REST API for scripting. Pocket imports work natively, and Netscape HTML handles browser imports and exports. Multi-user support included. MIT-licensed.
Yarrtube
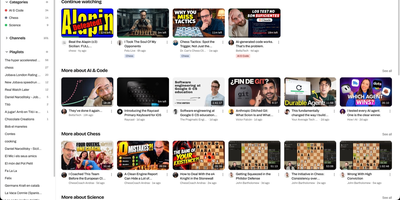
Follow the channels you actually chose, and let their newest uploads land on your own disk instead of in an algorithmic feed. Yarrtube tracks public YouTube playlists and whole channels, checks them on a schedule, and downloads fresh videos automatically the moment they appear. The built-in web player lets you watch the collected library from a desktop or a phone browser without ads interrupting. Downloads are organized into media-server friendly folders, so the same collection shows up inside Plex, Jellyfin, or Kodi next to your films and shows. For Plex homes, an optional scan trigger refreshes the library right after a download finishes, so new episodes surface without manual rescans. You control download quality per source and can cap how many videos each channel keeps, which protects limited disk space from runaway back catalogs. Grouping sources into categories and smart playlists keeps a growing archive browsable instead of turning into one long dump. Everything runs from one Docker container with two persistent mounts, one for its small database and one for the video files. A free YouTube Data API v3 key powers the new-upload checks, so setup takes minutes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
TG Vault
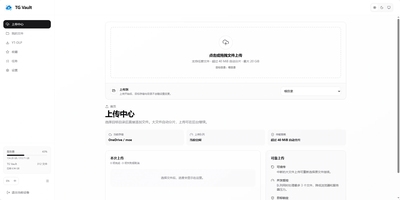
TG Vault turns Telegram into the front door of your private archive, pulling files out of channels and groups into storage you control and managing them from a proper web file manager. Batch-download channel and group media by date range or tag, subscribe to sources so new posts sync automatically, and upload, search, organize into folders, and preview media from the browser. Every transfer runs as a managed task with live progress, failure details, and pause, resume, and retry controls, whether it was started from the web console or the Telegram bot. Point the vault at local disk, OneDrive, Google Drive, Amazon S3, Aliyun OSS, WebDAV, or an OpenList instance, and let the optional qBittorrent extension forward finished downloads into the same storage, cleaning up sources or keeping them seeding. Access stays locked down with an administrator password, a bot user allowlist, and TOTP two-factor authentication, while one install script deploys and upgrades the whole Compose stack. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
TgWitness
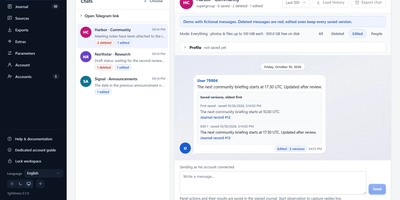
TgWitness preserves what your Telegram account actually saw, even when a message is edited three times and deleted before breakfast. A collector watches the chats, folders, or whole account you choose and records every captured message, edit version, and deletion notice in a local journal. The workspace reads like a familiar conversation view, with captured edits and deletion markers alongside the messages, and a searchable journal timeline ties observations together across chats. Open the edit history to compare versions side by side without overwriting the earlier observation. Connect people, replies, and shared links across recorded chats to trace how a claim travelled. Each account gets an isolated workspace with its own session and signing key, so separate investigations never contaminate each other. When a case moves, export the record as readable HTML, structured JSON or CSV, or a signed ZIP bundle whose hash-linked, Ed25519-signed records expose any tampering, verifiable offline with an independent fingerprint. Optional local OCR and transcription make media searchable, signed webhooks announce new observations, and encrypted backups copy the journal and timestamped checkpoints to S3-compatible storage. Read-only MCP access lets approved tools query the archive without touching the collector. Coverage reports show honestly where downtime left gaps. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Yubal
Paste any YouTube Music album, playlist, or track link into Yubal and get back a clean, fully tagged music library instead of a pile of video files. Tracks land in Artist and Year-Album folders with numbered filenames, cover art, and synced .lrc lyrics files, while playlists become M3U files that reference the album copies so a song appearing in ten playlists is stored exactly once. Subscribe to playlists and a cron-driven scheduler pulls new tracks into your library automatically on the schedule you set. The web interface shows real-time progress and a job queue that works on mobile, with automatic retries on failed downloads and graceful cancellation when you change your mind. Lyrics come from lrclib.net with a YouTube Music fallback, ReplayGain tags keep playback volume consistent across tracks and whole albums, and audio arrives as opus, mp3, or m4a, downloaded directly when possible and transcoded otherwise. Finished libraries drop straight into Navidrome, Jellyfin, or Gonic, and a browser extension for Firefox and Chrome queues downloads or subscriptions from the YouTube page you are already browsing. Optional cookie support unlocks private playlists, Liked Music, and age-restricted content, and a companion CLI downloads and inspects metadata from the terminal. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
linkding
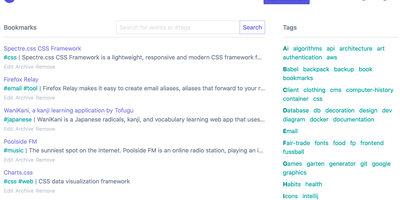
For people who found del.icio.us perfect and everything since bloated, linkding is the bookmark manager - a Django application whose entire design goal is saving and finding links with zero friction. Paste a URL and it fetches the title, description, favicon, and preview image automatically; organize with tags, search full-text across everything, mark bookmarks unread for read-it-later, attach Markdown notes, and bulk-edit whole selections at once. Its answer to link rot is archiving: bookmarked pages can be snapshotted automatically, either submitted to the Internet Archive or saved as local HTML files, and a documented SingleFile browser-extension integration uploads full self-contained page captures straight to your instance. Official Firefox and Chrome extensions (plus a bookmarklet) make saving a one-click habit, the UI installs as a Progressive Web App on mobile, and multi-user support with bookmark sharing - to users or logged-out guests - covers families and teams, with SSO via OIDC when needed. The REST API (create, search, filter by tag) has spawned a genuine ecosystem of community mobile apps and libraries. Operationally it is famously boring in the best way: one small container, SQLite by default, automated migrations, and a zero-breaking-changes policy. Import and export use standard Netscape HTML. MIT-licensed.
Omnom
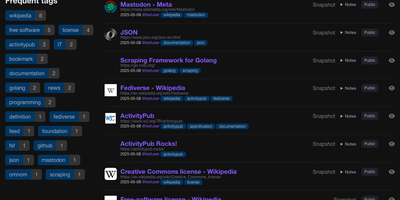
Omnom saves the pages you bookmark as full rendered snapshots, so the article, thread, or documentation page you kept is readable years later even if the original site changes or disappears. Bookmarks accumulate multiple snapshots over time, and the compare view shows two side by side or as a unified diff, revealing what an edited page used to say. Images and other media are downloaded and stored alongside each snapshot, keeping saved pages complete offline. The Firefox and Chromium extensions send pages exactly as your browser rendered them, capturing dynamic content a simple link saver would lose. A built-in reader aggregates your RSS and Atom subscriptions into one stream, where you can archive items individually or page by page and search feeds and bookmarks together. Through ActivityPub, other people can follow your public bookmarks from Mastodon or Pleroma, and you can follow Fediverse accounts in the same stream. Bookmarks can stay private or be shared publicly, organized with tags and nested collections, and filtered by date, domain, owner, or free text across saved content. Your dashboard tracks weekly, monthly, and yearly bookmark counts beside your most used tags, while a documented API and command line tools handle imports, tokens, and feed updates. Sign-in relies on one-time email tokens, OAuth, or a trusted Remote-User header from your reverse proxy, so no password is ever stored. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Paperless-ngx
A pile of paper becomes a searchable digital archive under Paperless-ngx, the community-maintained document management system. The pipeline is what makes it work: drop a file into the consumption folder (or let it poll an email inbox), and a worker hashes it for duplicate detection, routes it by type, runs OCRmyPDF with Tesseract (100+ languages) on anything without a text layer, and produces an archivable PDF/A with invisible selectable text embedded - so Ctrl+F works on your scans. Then the smart part: a scikit-learn classifier (TF-IDF plus multi-label prediction) trained on your own tagged documents automatically assigns tags, correspondents, and document types to new arrivals, alongside rule-based exact, keyword, and regex matching for deterministic cases. Full-text search includes relevance ranking, match highlighting, autocomplete, and "more like this" similarity search. Apache Tika integration extends consumption to Word, Excel, PowerPoint, and LibreOffice formats. The Django/Angular app adds custom fields, saved views on a customizable dashboard, bulk editing, workflow automation triggered on upload or matching, shareable public links with expiration, and a robust permissions system with per-document access control. Metadata lives in PostgreSQL with Redis-queued Celery workers processing documents in parallel. Your tax records, invoices, and contracts stay on your server - searchable in seconds, never in someone else's cloud.
Grimoire
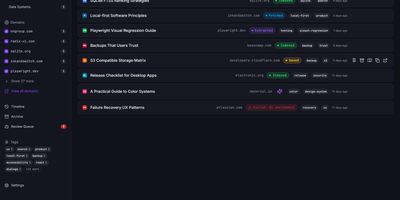
Grimoire captures, extracts, and indexes the content behind your bookmarks so you can search what pages actually say, not just their titles and URLs. The ingestion pipeline accepts links from the web UI, REST API, MCP server, browser bookmarklet, or bulk import, then fetches each page and extracts readable content using specialized parsers for GitHub repos, GitHub issues, StackOverflow threads, YouTube transcripts, PDFs, and standard web articles. Everything stores locally in SQLite with file-based content archives. Search operates in three modes: FTS5 keyword matching for exact terms, semantic embedding search for meaning-based retrieval using vector similarity, or a hybrid ranking mode combining both. Optional AI providers including OpenAI, Ollama, Anthropic, DeepSeek, and any OpenAI-compatible endpoint generate automatic tags, summaries, and embeddings without being required for core functionality. The interface built with React 18, Vite, TypeScript, Tailwind CSS, and Radix UI supports categories, nested tags, notes, archive and trash states, read-later flags, and multi-user isolated spaces. A single Bun-powered Hono process serves both the compiled frontend and the REST API on port 3210, requiring only one Docker container and a SQLite volume. Backup and restore export bookmarks, content, settings, and metadata as portable ZIP archives. Nearly 3,000 GitHub stars reflect growing adoption among developers and researchers. Running on a VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
KamiYomu
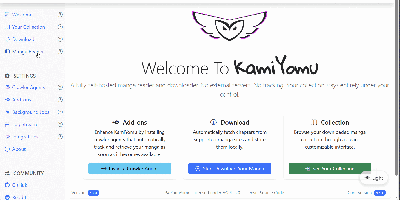
Manga readers use KamiYomu to build a private, self-hosted library: it fetches chapters from the websites they already follow, archives them locally, and serves everything back through a clean web reader on any device. The discovery flow runs on Crawler Agents, small plugins that teach KamiYomu how a particular source site lists series, chapters, and pages, so searching and fetching metadata happens inside the same interface as reading. Downloads land in a structured local archive, and reading picks up where you left off with history, filters for your library, and weekly views that surface new chapters and fresh releases. When a series is complete, export it as CBZ, PDF, or ZIP and take the files anywhere, no account or cloud library involved. Your e-reader and phone apps join through the built-in OPDS catalog, the same standard used by Moon+ Reader and KyBook, while a Swagger-documented API exposes the collection to your own scripts. Scheduled jobs keep watched series current in the background, checking sources and pulling new chapters without you babysitting tabs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.