Buzz
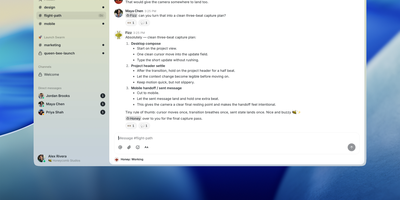
Buzz delivers the first production workspace where humans and AI agents operate as cryptographically equal team members on a self-hosted Nostr relay. The Rust-based backend stores every message, code patch, CI result, review comment, and workflow step as a signed Nostr event in a unified PostgreSQL-backed event log with Redis pub/sub for real-time presence and S3/MinIO for media storage. The integrated Git forge implements NIP-34, turning feature branches into dedicated channels where patches, reviews, and merge decisions live alongside the discussion that produced them — eliminating the split between chat tools and code hosts. Through the open Agent Client Protocol, Buzz natively supports Goose, Anthropic Claude Code, and OpenAI Codex as first-class channel members with scoped permissions, their own audit trails, and the ability to create patches, run workflows, and orchestrate multi-step automations via YAML-defined triggers including message events, reactions, schedules, and webhooks. The Tauri-based desktop client runs on macOS, Windows, and Linux, while buzz-cli provides agent-first JSON I/O for headless automation. Deploy via Docker Compose with the production bundle in deploy/compose/, Railway one-click, or build from source requiring Rust 1.88+, Node 24+, and pnpm. Multi-community mode scopes tenant data by domain with NIP-42 Schnorr authentication, rate limiting, and hash-chain audit logging. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Langflow
Langflow turns LLM application development into a visual canvas where every node maps to a real LangChain primitive (chains, agents, retrievers, memory, vector stores, and tools) that teams wire together without writing integration boilerplate. The platform supports 15+ LLM provider components including OpenAI, Anthropic, Google Gemini, Mistral, Groq, Cohere, Azure OpenAI, HuggingFace, and Ollama for fully local inference, with LiteLLM proxying to over 100 additional providers through a single OpenAI-compatible endpoint. Vector database integrations cover Pinecone, Weaviate, Chroma, Qdrant, Astra DB, OpenSearch, FAISS, and Milvus, while built-in Knowledge Bases introduced in version 1.8 allow RAG pipelines without any external vector service. Multi-agent orchestration enables agent-to-agent communication with conversation management, persistent Memory Bases for cross-session context retrieval, and step-by-step reasoning visibility in the interactive Playground. Every flow automatically becomes a callable REST API endpoint via the /run route and an MCP server exposable to Claude Desktop, Cursor, or any MCP-compatible client. Every component is a real Python class that developers can customize, extend, or replace, while Extension Bundles package third-party integrations as independent pip packages for modular installation. Tool integrations include web search, Slack, Gmail, Google Drive, GitHub, and custom REST API calls. Docker deployment with PostgreSQL persistence runs on port 7860. Backed by 153,000+ stars and DataStax. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
n8n
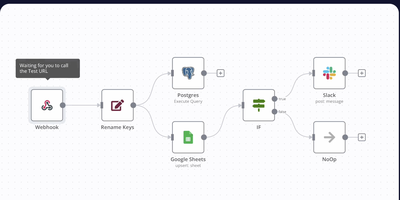
Webhooks, cron schedules, and app events trigger chains of nodes that fetch, transform, and route data: n8n is a workflow automation platform built around a visual, node-based editor. It ships with 400+ built-in integrations covering databases like Postgres, SaaS tools like Slack and HubSpot, and every major AI provider. When a pre-built node does not exist, the HTTP Request node calls any REST API, and the Code node runs JavaScript or Python inline, so you are never blocked by a missing connector. Workflows execute as directed graphs with branching, loops, error handling, and sub-workflows, and every run is logged for inspection and replay during debugging. It also includes LangChain-based nodes for building AI agents with tool calling and memory. Self-hosting on RepoCloud gives you unlimited workflow executions with no per-task pricing, and all data stays on your instance. Runs on Node.js with SQLite by default; add Postgres and Redis queue mode when you need to scale workers horizontally.
LibreChat
Every major model provider behind one ChatGPT-style interface: LibreChat spans OpenAI, Anthropic, Google, Azure, AWS Bedrock, Vertex AI, Groq, Mistral, OpenRouter, DeepSeek, and any OpenAI-compatible endpoint including local Ollama. You can switch models mid-conversation and compare providers without changing tools. Its Agents framework builds no-code custom assistants with tool access via Model Context Protocol servers, file search over uploaded documents through an optional pgvector-backed RAG service, and a sandboxed Code Interpreter that executes Python, JavaScript, Go, C++, Java, PHP, and Rust. Artifacts render React components, HTML, and Mermaid diagrams directly in chat, and image generation works through DALL-E and other configured providers. Multi-user support is enterprise-grade, with OAuth, SAML, LDAP, and two-factor authentication, per-user conversation history in MongoDB, and Meilisearch-powered search across all messages and files, plus reusable presets, forkable threads, and persistent memory across conversations. The economics favor teams: instead of a ChatGPT Plus seat per person, everyone shares one instance billed per API token, with access to every provider rather than one - and providers see individual API calls, not your accumulated organizational knowledge. Deployment is Docker Compose; API keys and endpoints are configured through .env and librechat.yaml.
Odysseus
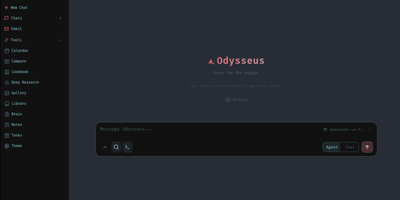
Agents with tool use, deep research, a document editor, an IMAP/SMTP email client with AI triage, notes, tasks, and a CalDAV-synced calendar - Odysseus bundles all of it into one open-source, self-hosted AI workspace. It runs local models through Ollama, vLLM, or llama.cpp and cloud APIs like OpenAI and OpenRouter, with a hardware-aware Cookbook that scans your machine and recommends quantized models that fit. Persistent memory uses ChromaDB with hybrid vector-plus-keyword retrieval, web search runs through a bundled SearXNG instance, and agents can use MCP servers, files, and shell access with safety controls, plus custom skills and scheduled agent tasks. A blind Compare mode runs side-by-side model duels with identities hidden and accumulates Elo-style ratings from your votes, so model selection is based on your actual workloads rather than leaderboard claims. Deep research mode - adapted from the Tongyi DeepResearch approach - reads sources through SearXNG and produces cited reports, while the email client tags, summarizes, sets reminders, and drafts replies locally rather than through a third-party mail AI. The writing-first document editor adds AI edits, Markdown and HTML support, and version history. The stack is Python 3.11 with FastAPI, SQLite for state, and a vanilla JS frontend, licensed AGPL-3.0 with zero telemetry. Because agents can read email and execute commands, keep authentication enabled and never expose it as a public unauthenticated service.
PentaGI
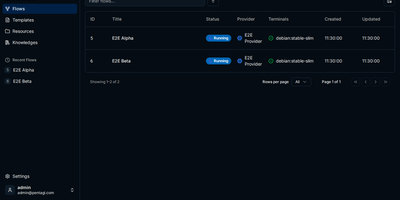
Autonomous red team execution without manual script coordination is what PentaGI delivers through a multi-agent penetration testing platform engineered for automated security assessments. Security engineers configure testing scopes, target IP ranges, domain lists, and rules of engagement through an interactive web console with real-time execution graphs. Autonomous agent personas break down high-level assessment goals into discrete tactical phases, orchestrating network port discovery, service banner fingerprinting, web application crawling, and CVE verification. Specialized agents query integrated Graphiti knowledge graphs and local vulnerability repositories to synthesize attack paths, validate exploitability, and confirm finding veracity before issuing alerts. Operators monitor live agent terminal streams, inspect sandboxed tool executions, and adjust active LLM provider routes across OpenAI, Anthropic, or local Ollama endpoints. The template editor allows red teams to compose reusable testing playbooks with customizable security prompt chains, safety constraints, and automated remediation reporting. Audit logs capture full command histories, raw tool outputs, and LLM reasoning steps to generate compliance-ready technical documentation. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Octop
Modern engineering teams and busy households deploy Octop to run private, autonomous AI agents equipped with persistent memory workspaces, scheduled cron jobs, and direct browser automation. Users can orchestrate specialist agents tailored for software development, IT operations, content generation, and system diagnostics through an interactive React dashboard. The platform connects directly to Discord, Feishu, DingTalk, and WeCom, allowing team members to delegate complex tasks without leaving their everyday messaging apps. An integrated remote desktop and browser control engine lets agents navigate websites, capture screenshots, fill forms, and operate graphical software autonomously. Administrators can assign distinct MBTI personality profiles to agents, establish granular role-based permissions, configure scheduled cron workflows, and integrate custom Model Context Protocol servers for external tool access. Long-term memory persists across conversations through dedicated workspace files, ensuring contextual continuity whenever switching between underlying language models or team collaborators. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
AMUX
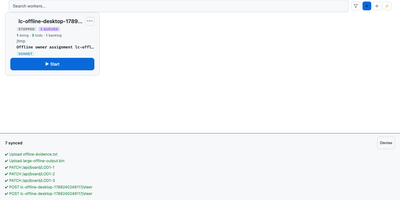
To coordinate swarms of autonomous coding agents across complex software projects, AMUX provides a concurrency-safe kanban workspace with real-time thought stream inspection and live steering controls. Engineers assign development tasks through an interactive board where autonomous worker processes claim cards using compare-and-swap mutexes to eliminate race conditions between parallel sessions. Operators monitor active reasoning streams, inspect streaming terminal outputs, and inject guidance commands mid-turn without interrupting background execution. A cryptographic origin router relays messages between agents, enabling workers to delegate sub-tasks, request automated peer code reviews, and share environment state safely. Built-in schedulers trigger recurring automated maintenance routines, dependency updates, and bug triage sweeps on cron-like timers or autonomous loop cadences. Teams can switch language models dynamically on active sessions to tackle complex architecture challenges with high-capability reasoning engines while conserving resources on routine tasks. An integrated self-healing supervisor watches over agent runtimes, automatically compacting context windows, restarting crashed terminal sessions, and resuming pending instructions seamlessly. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
AnythingMCP
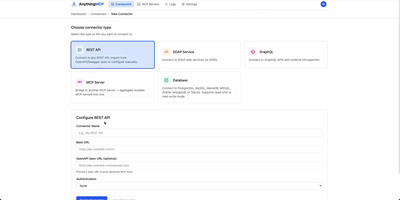
Connecting autonomous AI assistants to internal enterprise databases and legacy systems is streamlined by AnythingMCP, a visual Model Context Protocol gateway with automated knowledge graph generation and granular access controls. Engineers can import OpenAPI specifications, Postman collections, SOAP WSDL files, or raw database credentials to generate standardized Model Context Protocol tools in minutes without writing custom code. The built-in knowledge graph automatically maps entity relationships across disparate databases and software platforms, teaching agents how to correlate customer records in CRM tools with live order histories in enterprise resource planning software. System administrators can enforce fine-grained access policies by restricting tool execution permissions to specific roles and scoping database operations to read-only queries with strict row limits. An interactive web console provides real-time tool inspection, payload testing, request tracing, and comprehensive audit logs that capture every upstream invocation with full parameter visibility. Enterprise teams can integrate identity providers through OAuth2, SAML single sign-on, and SCIM automated user provisioning while protecting sensitive credentials using AES-256-GCM encryption at rest. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GNU AGPLv3 licensed.
Yep Anywhere
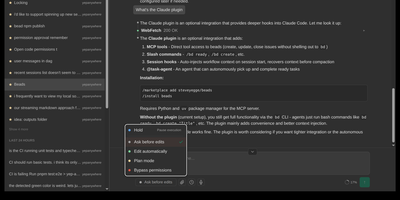
Designed for developers on the go, Yep Anywhere turns any smartphone browser into a full-featured control center for supervising, steering, and reviewing autonomous AI coding agents. Operators can monitor live execution across multiple active projects simultaneously without sitting at a desktop terminal. Real-time reasoning feeds. Instant push alerts for permission prompts. One-tap tool approvals. Developers can unblock pending tasks mid-turn, redirect active workflows, or queue sequential follow-up prompts for automatic delivery at the next safe milestone. An integrated source control viewer displays syntax-highlighted working-tree and commit diffs, allowing reviewers to attach line-level comment bundles directly back into the agent context. Mobile voice transcription lets users dictate instructions straight into running sessions, while photo library integration makes uploading bug screenshots effortless. All agent credentials, CLI configurations, and repository data remain private on the host server without requiring third-party cloud database accounts or proprietary device pairing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Opengeni
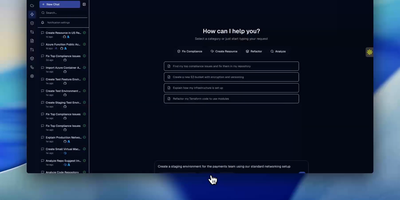
Enterprises requiring production-grade governance for long-running autonomous AI operations can rely on OpenGeni, a self-hosted orchestration platform with human-in-the-loop approvals, Connected Machine execution, and comprehensive audit replays. Operators can configure durable multi-turn workflows that execute continuously toward specified goals without premature termination, automatically pausing when human verification, structured multiple-choice decisions, or critical credential approvals are required. Teams can assign execution workloads across ephemeral cloud sandboxes or route them straight to enrolled Connected Machines to run commands directly against local code repositories without exposing inbound network ports. The integrated web console lets developers inspect live Server-Sent Event activity streams, replay complete turn histories from audit logs, inspect generated artifacts, and cancel or steer in-flight agent tasks on demand. Platform administrators can enforce fine-grained access policies through GitHub App repository bindings, broker temporary role-scoped secrets, and maintain a shared organizational knowledge base where agents propose findings for human review before vector indexing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
QwenPaw
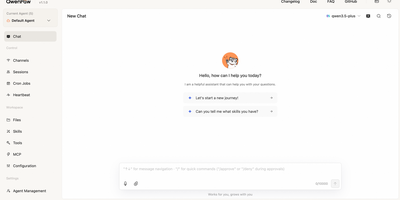
Designed as a unified personal AI workstation, QwenPaw operates as an autonomous digital copilot that coordinates scheduled automations, interactive coding sessions, and multi-channel team communication across everyday messaging apps. Users can dispatch long-running research tasks, process office documents including PDF, Excel, and Word files, and execute browser-based data collection without manual intervention. The built-in web console and terminal interface provide full visibility into agent reasoning, allowing operators to inspect intermediate thinking steps, review proposed file edits, and approve sensitive tool calls. Through direct connectors for Discord, Telegram, DingTalk, Lark, and WeChat, teams can trigger specialized skills or query shared workspaces directly from their existing group channels. A self-evolving personal memory system continuously indexes chat interactions and local resources into editable Markdown files, ensuring knowledge persists across restarts and task delegations. Built-in guardrails including a sandboxed execution runtime, tool access policies, and automated skill scanners protect underlying host files from unauthorized modifications during autonomous scripting runs. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
GPT Researcher
A question goes in; a cited, long-form report comes out - GPT Researcher is an open-source autonomous research agent. A planner agent decomposes the query into sub-questions, execution agents crawl 20+ web sources in parallel with JavaScript-enabled scraping, and a publisher aggregates findings into a 2,000+ word report with inline citations, exportable to PDF, Word, and Markdown. The Deep Research mode extends this recursively: each result yields follow-up questions that are explored to configurable breadth and depth in a tree pattern, while accumulated learnings, citations, and visited URLs are shared across branches. It also researches local documents (PDF, CSV, Word) alongside the web. LLM and search providers are pluggable, including OpenAI, Anthropic, Google, DeepSeek, and Ollama for models, and Tavily, Google, Bing, DuckDuckGo, and SearXNG for retrieval. It ships as a Python package, a FastAPI server with web frontend, a Docker image, and an MCP server for use inside Claude or Cursor. MIT-licensed.
OpenMAIC
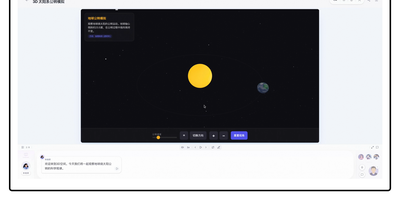
Developed by Tsinghua University researchers and validated across more than 700 students, OpenMAIC converts raw prompts, PDFs, Office documents, audio, and video into complete, multi-agent virtual learning environments. The platform leverages Next.js, LangGraph state machines, and a pluggable `@openmaic/storage` layer to orchestrate autonomous AI professors and student avatars that lecture, debate at roundtables, answer inquiries, and illustrate complex equations on a real-time SVG whiteboard. Its Pro Agent Workbench features durable PostgreSQL-backed sessions, twenty specialized curriculum-building skills, and granular JSON Patch slide editing with full `.pptx` import fidelity. OpenMAIC supports rich scene modalities including automated quiz grading, Project-Based Learning milestones, and Deep Interactive Mode offering in-browser code execution, interactive mind maps, and Three.js 3D physics simulations. Built-in audio pipelines connect with VoxCPM2 for zero-shot voice cloning, Azure STT, and FunASR for speech recognition, alongside a dedicated Chromium-FFmpeg rendering microservice for one-click MP4 video exports. Flexible model routing interfaces seamlessly with OpenAI, Anthropic Claude, Google Gemini, Amazon Bedrock, DeepSeek, and local Ollama or Lemonade instances, while OpenClaw integration enables direct classroom generation from Slack, Discord, Feishu, and Telegram. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
GoRaven
GoRaven transforms AI chat from a question-answer window into a full engineering workstation where agents read files, write code, run shell commands, query databases via MCP tools, and deliver structured results — orchestrating across OpenAI, Claude, DeepSeek, Gemini, Qwen, GLM, and Ollama with task-based routing that allocates the right model for each job based on cost and capability. Built on a Go backend using the Freedom framework with Iris HTTP and a React/TypeScript frontend powered by Vite and Tailwind CSS, each user operates in an isolated workspace with team-shared project areas and centrally managed model quotas. The skill marketplace packages prompts, scripts, and workflows as reusable installable units with automatic dependency resolution and centralized versioning. MCP toolchain integration connects agents to internal APIs, databases, private services, and CLI tools so they query data, invoke services, and trigger actions directly. RAG-powered knowledge bases ingest policies, documentation, and business data for real-time retrieval during planning, coding, and Q&A with source attribution. Long-running task support decomposes complex work through a main agent coordinating sub-agents that execute in parallel across sessions. Plugin hooks inject custom logic at conversation start and end, tool calls, and SSE event streams without forking core code. The operations dashboard tracks usage metrics, model consumption, and team activity. Supports SQLite, MySQL, or PostgreSQL with Redis or local memory caching. Deploy with a single Docker command. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Paca
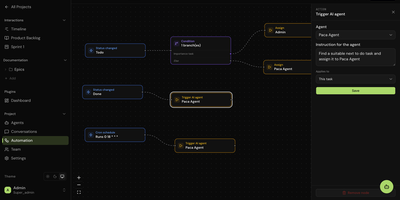
Paca is a self-hosted project management platform and Scrumban workspace where autonomous artificial intelligence agents collaborate with human software engineers as first-class Scrum teammates instead of external chat assistants. Engineering teams manage sprints, backlogs, and task lifecycles through a shared real-time board powered by Socket.IO where both humans and agents pick up assignments and post progress updates. A native Model Context Protocol server connects external coding assistants such as Claude Desktop and Claude Code directly into projects, tasks, and sprint data without custom scraping scripts. Distributed agents execute in isolated runtime sandboxes powered by the OpenHands software development kit, co-authoring behavior-driven development Gherkin scenarios with product owners and maintaining living system design documents. Visual event-driven automation builders compose multi-branch trigger, condition, and action pipelines that evaluate task dependency gates and cron schedules. A sandboxed WebAssembly plugin runtime allows developers to write custom backend logic and custom board views using Go or Rust. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Customermates
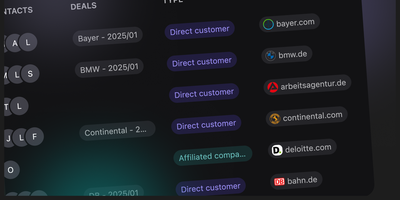
Customermates delivers a modern CRM purpose-built for teams who want practical customer management without enterprise-heavy complexity. The platform manages contacts, organizations, deals, services, and tasks through clean pipeline workflows while integrating AI agent capabilities, REST API access, webhook events, n8n automation connections, and Model Context Protocol tooling for AI-native operations. Team collaboration features include role-based permissions, comprehensive audit logging tracking every data change, and workspace organization for multi-team deployments. The deal pipeline provides customizable stages with drag-and-drop management, while task assignments and service tracking connect directly to contact and organization records for complete relationship context. API-first architecture exposes all CRM data through documented endpoints enabling custom integrations, reporting dashboards, and third-party tool connections. The n8n integration enables no-code workflow automation for lead routing, follow-up sequences, notification triggers, and cross-system data synchronization. Self-hosting requires only two files — a Docker Compose configuration and environment variables — with the published image at ghcr.io/customermates/customermates:latest running database migrations automatically on first boot. PostgreSQL provides the data layer with no additional infrastructure dependencies beyond a reverse proxy for TLS termination. The Community Edition includes unlimited users, unlimited records, full API access, n8n automation, and audit logging at zero cost. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Moltis
Moltis gives individuals and teams a completely private personal AI agent server that bridges conversational assistants to everyday messaging platforms while executing real-world computing tasks inside secure execution environments. Users can interact with autonomous agents across Telegram, Discord, WhatsApp, Slack, Matrix, and browser interfaces to draft correspondence, automate research, and schedule recurring cron tasks. The system coordinates multi-agent delegation by spinning up specialized sub-agents with dedicated roles for code generation, pull request reviews, quality assurance testing, and technical documentation. Built-in sandboxing isolates tool operations within container boundaries or WebAssembly modules, ensuring shell commands, web scraping routines, and script executions cannot alter underlying operating system files without explicit permission. Native Model Context Protocol integration allows operators to attach external data endpoints, database connectors, and custom command-line utilities without rewriting core routing logic. Persistent memory preserves conversational context and document embeddings across multiple sessions, allowing assistants to recall prior discussions, user preferences, and project guidelines indefinitely. Administrators can configure granular tool approvals, manage WebAuthn passkey authentication, and review real-time WebSocket communication logs through an embedded control panel. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.