OpenViking
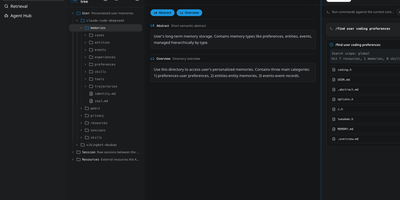
OpenViking is a self-hosted context database that gives AI agents persistent, structured memory by organizing knowledge, skills, and session history into a hierarchical virtual filesystem accessible through the viking:// URI protocol. Instead of dumping everything into a flat vector store and hoping semantic search finds the right chunks, agents navigate their context with familiar commands like ls, tree, and find, locating exactly the information they need through deterministic paths combined with semantic search. Every resource is automatically processed into three layers: a 100-token L0 abstract for quick filtering, a 2,000-token L1 overview for content navigation, and the full L2 detail loaded only when confirmed necessary. This tiered approach cuts token consumption by 83 to 96 percent compared to conventional RAG while improving task completion rates by 15 to 49 percent on benchmark tests. The built-in memory self-iteration loop automatically analyzes task execution and user feedback, updating agent memory directories so the system continuously learns and improves. You can connect to any LLM provider, including Ollama for fully local inference, OpenAI, or compatible gateways. The Web Studio UI at the /studio endpoint provides visual browsing of the entire context filesystem, and the REST API on port 1933 supports programmatic access. Deploy via Docker, Kubernetes with the included Helm chart, or as a standalone service. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Bifrost
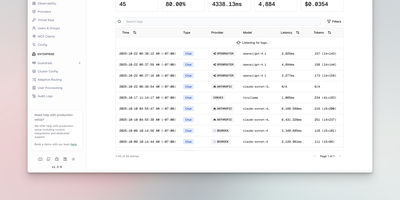
Bifrost is an open-source AI gateway that unifies 23+ LLM providers into a single OpenAI-compatible endpoint with automatic failover, semantic caching, and built-in cost governance, so one provider going down never takes your production AI application with it. Point your existing OpenAI or Anthropic SDK at Bifrost's local endpoint and gain access to OpenAI, Anthropic, AWS Bedrock, Google Vertex, Azure, Groq, Mistral, and Ollama without changing application code. Define fallback chains that automatically switch providers when one returns errors or exceeds latency thresholds, keeping response times stable during outages. The built-in web dashboard at port 8080 lets you configure providers, create virtual API keys, monitor live request traffic, and review analytics without editing configuration files. Semantic caching combines exact hash matching with vector similarity search via Weaviate, serving cached responses for identical or paraphrased prompts in sub-millisecond time to cut costs on repetitive workloads. The MCP gateway connects AI agents to external tools like filesystems, databases, and web APIs, exposing them to clients such as Claude Desktop and Cursor with per-key allow-lists. Four-tier budget hierarchy at customer, team, virtual key, and provider levels enforces spend caps, rate limits, and model restrictions across your organization. Extend functionality through custom Go plugins for analytics, monitoring, or security middleware. Native Prometheus metrics and OpenTelemetry distributed tracing give operations teams full production observability. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.

LobsterBoard
LobsterBoard lets you assemble custom monitoring dashboards from 50 pre-built widgets using a visual drag-and-drop editor, covering everything from CPU and memory gauges to AI subscription trackers, stock tickers, and camera feeds on your own server with zero cloud dependencies. The snap-grid editor handles layout composition with resize handles and a property panel, so you drag widgets onto a canvas, configure their data sources, and the dashboard is live. Real-time system statistics flow through Server-Sent Events, updating CPU load, memory pressure, disk usage, network throughput, and Docker container status without page refreshes. Five built-in themes range from a dark default to a retro CRT terminal aesthetic, a warm sepia paper look, and pastel options for different display environments. The template gallery lets you export complete dashboard layouts with auto-captured screenshot previews, share them with other users, and import configurations as a full replacement or selective merge. Custom pages extend beyond dashboards into notes, kanban boards, or any free-form layout you need. Built-in widgets connect to iCal feeds for calendar events, RSS sources for news aggregation, weather APIs for local conditions, and financial data providers for cryptocurrency and stock prices. The whole system runs from a single server.cjs file with zero cloud dependencies or external frameworks. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSL-1.1 licensed (free for non-commercial use; converts to MIT in 2030).
OpenRun
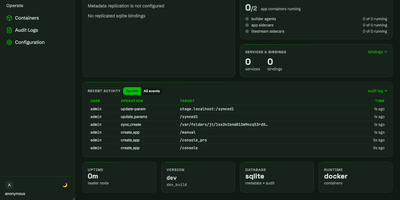
OpenRun replaces the patchwork of CI/CD pipelines, reverse proxies, and identity providers that teams typically assemble when deploying internal tools, offering declarative GitOps-based deployment of web applications to Docker, Podman, or Kubernetes from a single self-hosted Go binary. Point it at a Git repository and it builds containers from AppSpec templates, routes requests by domain or URL path, provisions TLS certificates automatically, and scales idle applications to zero when unused. Blue-green staged deployments promote new versions through development, staging, and production environments with atomic rollback across multiple apps simultaneously. Every deployed application inherits SSO authentication through OAuth, OpenID Connect, or SAML providers alongside role-based access control, all configured once at the platform level rather than per app. Service bindings provision isolated PostgreSQL, MySQL, SQLite, or Redis credentials for each application, while Litestream integration replicates SQLite databases to S3 for automatic disaster recovery. The management console provides a web interface for monitoring containers, reviewing audit logs, configuring syncs, and managing server operations. AppSpec templates handle Streamlit, Gradio, FastAPI, Flask, and FastHTML projects out of the box, deploying existing Python applications without requiring custom Dockerfiles. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Seanime
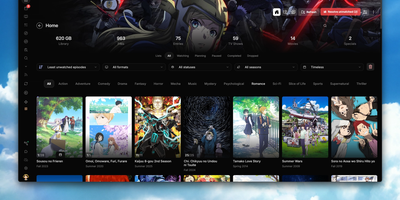
Seanime turns your server into a dedicated anime and manga command center, combining local library management, torrent streaming, an integrated manga reader, and AniList progress tracking in a single self-hosted web application. Point it at your media folders and the smart scanner automatically identifies and matches your anime files to AniList entries without requiring strict naming conventions or folder hierarchies. Stream episodes directly from torrents through qBittorrent, Transmission, Torbox, Real-Debrid, AllDebrid, or Premiumize; the built-in player starts playback before the download finishes, so there is no waiting for full transfers. The manga reader pulls chapters from community extension sources and tracks your reading progress across series automatically. An in-app extension marketplace lets you install third-party providers for streaming, manga, and torrent sources, all written in JavaScript and managed through a visual interface. Seanime Tenji, the companion mobile app for iOS and Android, connects to your server for on-the-go library browsing, content streaming, and offline downloads. Auto-download rules grab new episodes of airing series the moment torrents appear. The transcoding engine handles on-the-fly conversion for browser playback on any device, while direct play passes through compatible formats at full quality. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPL-3.0 licensed.
Gods Eye View
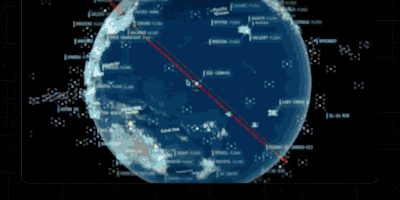
God's Eye View turns your browser into a real-time spatial intelligence command center, rendering thousands of live aircraft, ships, satellites, earthquakes, traffic flows, and public cameras on a photorealistic 3D Earth powered by CesiumJS and Google Photorealistic 3D Tiles. Click any aircraft to see its transponder telemetry from OpenSky and adsb.lol, including route history, altitude, speed, and callsign; track live vessel positions worldwide through AIS beacon data from AISStream; or follow roughly 840 satellites color-coded by class using orbital elements from CelesTrak. A hands-free voice agent powered by the OpenAI Realtime API lets you ask the planet questions in natural language, and the globe annotates your answer directly in 3D space. Toggle FLIR mode for a thermal camera aesthetic, layer in NASA FIRMS wildfire data, switch between Google 3D, Bing aerial, and OpenStreetMap base layers, or tune into a geolocated world radio dial. Public CCTV cameras are projected into 3D city geometry with viewshed cones and direct-manipulation calibration. The cockpit mode provides a pilot-style briefing surface with mission-specific overlays. Entity inspection panels show detailed metadata for every tracked object, and shareable links let you send any scene configuration to a colleague. Ten of the thirteen live data layers work with zero API keys, while the required Google Maps key offers 1,000 free 3D tile sessions per month. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
DCM
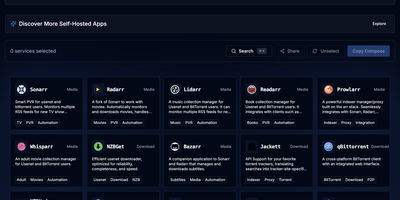
DCM is a visual builder that eliminates docker-compose copy-paste anxiety for home server enthusiasts. The TypeScript and Next.js web interface on port 7576 presents a curated catalog of popular self-hosted applications organized into categories: media management with Jellyfin, Plex, Sonarr, Radarr, and Prowlarr; dashboards like Homarr and Heimdall; databases including PostgreSQL, MariaDB, MongoDB, and Redis; monitoring stacks with Grafana and Prometheus; download clients like qBittorrent and NZBGet; security tools including Vaultwarden; storage solutions like Nextcloud; and home automation via Home Assistant. Select any combination of containers and DCM generates both compose.yaml and .env files with correct volume mounts, environment variables, PUID/PGID ownership, network modes, and port mappings — ready to paste into your terminal. Automatic port conflict detection identifies clashing services and reassigns ports before you ever hit a deployment error. The Template Gallery ships predefined multi-container stacks for common setups: media servers, development environments, database clusters, and monitoring solutions — some incorporating ten or more services in a single template. Built as a static Next.js export served from a 62 MB multi-arch Docker image supporting amd64, arm64, and arm/v7, DCM runs on everything from rack servers to Raspberry Pis. Share generated configurations via URL or download them locally. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Utopia
The first open-source substrate for enterprise knowledge engineering that learns passively and governs itself. The Rust-built backend paired with PostgreSQL and pgvector delivers a bitemporal knowledge graph where every fact carries two timelines: when it held in the real world and when the system came to believe it — enabling full audit trail replay of how understanding evolved. Document ingestion handles PDF, DOCX, PPTX, XLSX, CSV, Markdown, HTML, and plain text with legacy encoding detection, while scheduled syncing pulls from web pages, RSS feeds, GitHub, Jira, Notion, WebDAV, and S3-compatible buckets. Search fuses Tantivy full-text indexing with pgvector semantic vectors using Reciprocal Rank Fusion, streaming answers with inline citations that link directly to source passages. The built-in agent harness drives agentic RAG through conversation — searching documents, walking the knowledge graph at any historical date, and querying mounted databases via Ontology2SQL which achieves state-of-the-art results on BIRD Mini-Dev benchmarks. Five ontology packs ship inside the binary (schema.org, W3C Org, PROV-O, FOAF, IOF Core) with forward-chaining reasoning for transitivity, symmetry, inverses, and relation hierarchy. Entity resolution operates in three stages: exact name matching, embedding similarity, then model-based judgment with every merge reversible. Any OpenAI-compatible endpoint works including DeepSeek, Qwen, Ollama, and vLLM for fully air-gapped deployment. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
GPT Load
GPT Load has become the go-to self-hosted AI gateway for teams managing multiple LLM provider credentials behind a single URL. The Go-built proxy transparently preserves native API formats for OpenAI Chat Completions, OpenAI Responses, Anthropic Messages, and Google Gemini — applications swap one base URL and keep their existing SDK integration untouched. Twenty built-in channels cover official APIs (OpenAI, Anthropic, Gemini, xAI), cloud platforms (Azure OpenAI, AWS Bedrock, Google Vertex AI), model services (DeepSeek, Moonshot AI, SiliconFlow, Zhipu AI, Alibaba Cloud, Volcengine, OpenRouter, Groq), and subscription accounts (Codex, Claude, Antigravity, Grok) using the same credential management, scheduling, and health system. The intelligent key pool rotates among valid credentials using atomic counters for fair high-concurrency distribution, automatically blacklists failing keys after configurable thresholds, and recovers them via scheduled health checks — all transparent to clients. Weighted load balancing distributes traffic across multiple upstream endpoints while per-credential proxies route individual keys through different egress paths. The Vue 3 management dashboard provides real-time statistics, group configuration, key testing, request logs with full debugging context, per-model cost estimates, and route inspection. Docker deployment exposes the management interface and proxy on port 3001 with SQLite by default, MySQL or PostgreSQL optional, and Redis for distributed leader-follower cluster scaling. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.

CubeSandbox
CubeSandbox gives every AI agent its own hardware-isolated MicroVM with a dedicated Linux kernel — not a shared-kernel container but a true KVM virtual machine — booting in under 60ms with less than 5MB of memory overhead per instance, enabling thousands of concurrent sandboxes on a single server via kernel sharing and Copy-on-Write memory. The Rust-built CubeProxy exposes an E2B SDK-compatible REST API on Axum, so existing E2B Cloud applications switch by changing one environment variable with zero client code changes. CubeMaster orchestrates cluster-level scheduling in Go while Cubelet manages node-local sandbox lifecycles including create, run, pause, resume, snapshot, and destroy operations. CubeVS, the eBPF-powered network layer, enforces per-sandbox isolation with LPM trie-based egress policies entirely in kernel space — no userspace context switches — while CubeEgress provides an L7 security proxy with per-domain, per-path, and per-method allowlists plus automatic credential injection that keeps secrets invisible to sandbox code. Hundred-millisecond-granularity snapshots enable checkpoint, rollback, and parallel fork from any saved state. The volume framework supports E2B-compatible pluggable storage with independent lifecycle and cross-sandbox sharing. Production deployment uses Terraform on Tencent Cloud or Helm charts on Kubernetes, K3s, or TKE, with full ARM64 support alongside x86_64 and AutoPause/AutoResume for cost optimization. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Pixelle Video
Backed by Alibaba's AIDC team and carrying over 27,700 GitHub stars, Pixelle-Video turns a single text prompt into a publish-ready short video in approximately three minutes — handling scriptwriting, image generation, voice narration, music selection, subtitle overlay, and final MP4 export in one automated pipeline. The engine supports multiple LLM backends for script generation including GPT-4, Qwen, DeepSeek, and local Ollama deployments, while image and video creation routes through either self-hosted ComfyUI workflows, cloud-based RunningHub pipelines, or direct API connections to DashScope Wan, OpenAI, Seedream, Seedance, and Kling AI. Text-to-speech synthesis uses Edge-TTS, Index-TTS, and other mainstream engines with multi-language voice profiles. Five distinct pipelines cover Quick Create, Standard, Digital Human Avatar broadcasting, Image-to-Video transformation, and Motion Transfer from reference video. The Streamlit web UI on port 8501 provides a visual workflow builder with template selection across portrait (1080x1920), landscape (1920x1080), and square formats, while the FastAPI server on port 8000 exposes a REST API with endpoints for async video generation, task polling, content scripting, TTS and image generation, template listing, and health checks. History persistence tracks all completed generations. HTML-based visual templates support static, image-overlay, and AI-video styles with customizable prompt prefixes. The modular architecture lets operators swap any atomic capability — image model, video model, TTS engine, or VLM — by editing a workflow JSON file without touching Python code. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
OpenPencil
OpenPencil is the open-source design editor that reads and writes native Figma .fig files using the same Kiwi binary format — enabling bidirectional copy-paste between Figma and OpenPencil without data loss. The built-in AI assistant provides 90+ design tools through a chat interface, creating and modifying shapes, fills, strokes, auto-layout, components, variables, and boolean operations from natural language prompts, with BYOK support for Anthropic, OpenAI, Google AI, OpenRouter, Z.ai, MiniMax, and compatible endpoints. A Skia CanvasKit WASM renderer paired with Yoga WASM layout engine delivers Figma-parity rendering with flex and CSS Grid support including gap, padding, and alignment. The headless CLI inspects node trees via XPath queries, lints naming and accessibility, converts between document formats, analyzes color and typography patterns, extracts design tokens, and exports to PNG, SVG, JSX/Tailwind, and HTML. An MCP server exposes all design operations over stdio and HTTP, connecting Claude Code, Cursor, Windsurf, and Gemini CLI for AI-assisted design automation. Real-time P2P collaboration via WebRTC with Yjs CRDT synchronization requires no server and no account. The Vue SDK provides headless components for embedding the editor into custom applications. Ships as a 7 MB Tauri v2 desktop app for macOS, Windows, and Linux, or runs in any browser as a PWA. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
MindsHub
Backed by $50M+ from Benchmark, Y Combinator, and NVIDIA with 800+ contributors and 39,000+ GitHub stars, MindsHub Cowork is the unified AI workspace where open-source models handle entire projects — research, reporting, internal tools, scheduled operations — and return finished, shareable deliverables. The platform runs two interchangeable open-source agent harnesses, Anton and Hermes, swappable from a dropdown without losing context. A built-in Model Router pre-wires 25+ models spanning Anthropic Claude, OpenAI GPT, Google Gemini, DeepSeek, Qwen, Kimi, Grok, and MindsHub Air with automatic failover — no per-provider API keys required. A secure credentials vault connects BigQuery, PostgreSQL, Salesforce, HubSpot, Zendesk, Gong, Gmail, Google Drive, Notion, Linear, Stripe, and Slack, keeping secrets scoped per connection so agents never see raw keys. Agent output becomes publishable artifacts — documents, dashboards, apps, and code — each deployable to a live shareable URL. Cross-session persistent memory, a reusable skill library, and a background scheduler supporting hourly, daily, and weekly cadences enable autonomous recurring workflows. The architecture separates a React/Vite frontend (shipping as both Electron desktop app and web SPA) from a FastAPI backend with a versioned REST API at /api/v1 covering conversations, projects, artifacts, schedules, and connectors. Self-host via Docker Compose with nginx on port 3000 and the API on port 26866, or deploy on-prem, in a VPC, or air-gapped. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
OpenWiki
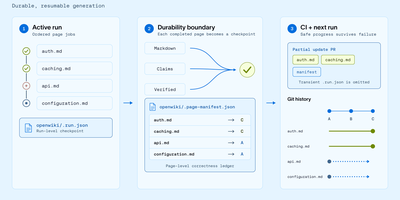
With over 15,900 GitHub stars and 40,000 weekly npm downloads in its first two months, OpenWiki from LangChain has rapidly become the standard for AI-generated codebase documentation. Built on the Deep Agents framework, it deploys a documentation agent that reads your repository's source code, tests, and configuration, then synthesizes a complete linked Markdown wiki with architecture overviews, integration guides, data-flow diagrams, and validated Mermaid visualizations. Two operating modes cover distinct workflows: code mode generates repository documentation in an openwiki/ folder with automatic AGENTS.md and CLAUDE.md integration for Codex, Claude Code, OpenCode, and Cursor, while personal mode builds a local knowledge base from nine connectors including Notion, Slack, Gmail, X/Twitter, Hacker News, LangSmith, Custom MCP, Web Search, and local git repositories. Thirteen model providers are supported out of the box — OpenAI, Anthropic, Gemini, AWS Bedrock, GitHub Copilot, OpenRouter, Nebius, Fireworks, Baseten, NVIDIA NIM, and any OpenAI-compatible endpoint like Ollama or LM Studio. Grounded Claims track every material assertion back to versioned source evidence, flagging stale propositions before they propagate. The interactive visualizer renders wiki pages as an explorable node graph with a side-by-side Markdown reader, exportable as a static site for GitHub Pages or MkDocs. Self-updating CI workflows via GitHub Actions, GitLab CI, or Bitbucket Pipelines open documentation PRs automatically when code changes. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Auto Company
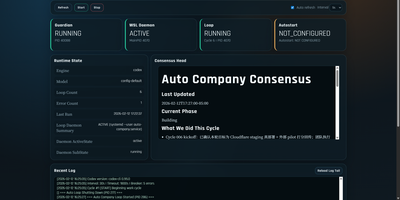
With over 2,700 GitHub stars, Auto Company is the first open-source framework that runs a fully autonomous AI company 24/7 — 14 specialized agents modeled after Jeff Bezos (CEO strategy), Werner Vogels (CTO architecture), Charlie Munger (critical analysis), DHH (full-stack engineering), Kelsey Hightower (DevOps), Seth Godin (marketing), and eight more domain experts collaborate through dynamic squad formation to ideate products, write code, deploy infrastructure, and execute marketing campaigns without human intervention. The five-layer architecture separates execution, orchestration, cognition, workflow routing, and observability, while the consensus memory pattern uses a single markdown file as a relay baton between cycles — no vector databases, no Redis, no embeddings required. A bash loop invokes Claude Code or OpenAI Codex CLI every 30 seconds, each cycle selecting 2-5 agents from the 14-person pool based on task context. Over 30 reusable skills handle specialized tasks from frontend design to competitive analysis and deployment automation. Circuit breakers trigger cooldown after consecutive errors, rate-limit detection auto-sleeps on API throttling, and sandbox rollback protects against destructive changes. The Python-powered web dashboard displays real-time cycle status, cost tracking per cycle averaging under $2, and agent activity visualization, with CLI control via make start, stop, monitor, pause, and resume. Supports macOS via launchd, Windows via WSL with systemd, and native Linux deployment. The npx create-auto-co command scaffolds a new AI company in seconds. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
OpenMAIC
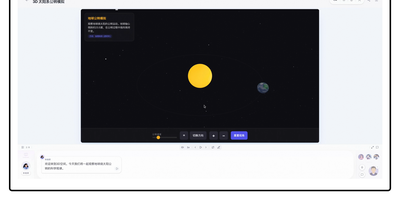
Developed by Tsinghua University researchers and validated across more than 700 students, OpenMAIC converts raw prompts, PDFs, Office documents, audio, and video into complete, multi-agent virtual learning environments. The platform leverages Next.js, LangGraph state machines, and a pluggable `@openmaic/storage` layer to orchestrate autonomous AI professors and student avatars that lecture, debate at roundtables, answer inquiries, and illustrate complex equations on a real-time SVG whiteboard. Its Pro Agent Workbench features durable PostgreSQL-backed sessions, twenty specialized curriculum-building skills, and granular JSON Patch slide editing with full `.pptx` import fidelity. OpenMAIC supports rich scene modalities including automated quiz grading, Project-Based Learning milestones, and Deep Interactive Mode offering in-browser code execution, interactive mind maps, and Three.js 3D physics simulations. Built-in audio pipelines connect with VoxCPM2 for zero-shot voice cloning, Azure STT, and FunASR for speech recognition, alongside a dedicated Chromium-FFmpeg rendering microservice for one-click MP4 video exports. Flexible model routing interfaces seamlessly with OpenAI, Anthropic Claude, Google Gemini, Amazon Bedrock, DeepSeek, and local Ollama or Lemonade instances, while OpenClaw integration enables direct classroom generation from Slack, Discord, Feishu, and Telegram. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
LobeHub
With over 82,000 GitHub stars and 700,000+ downloads, LobeHub has evolved from its origins as LobeChat into a comprehensive multi-agent AI collaboration platform where humans and autonomous agent teams co-evolve. The platform's Agent Harness architecture functions as an operating system between AI models and applications, handling prompt presets, tool orchestration, lifecycle hooks, planning, filesystem access, and sub-agent management across 25+ model providers including OpenAI, Anthropic Claude, Google Gemini, DeepSeek, Mistral, Groq, AWS Bedrock, Azure OpenAI, and local models through Ollama. Agent Groups enable sophisticated collaboration with sequential, parallel, iterative, and debate orchestration modes, allowing multiple specialized agents to tackle complex workflows simultaneously. The Agent Builder creates production-ready agents from natural language descriptions with auto-configuration, drawing from a marketplace of 505+ pre-built agents and 10,000+ MCP-compatible skills and plugins. Pages provide collaborative document editing with multi-agent co-authoring, while Schedules automate agent runs around the clock without human supervision. The knowledge base leverages PostgreSQL with pgvector for RAG-powered retrieval, and Personal Memory gives agents transparent, editable context that evolves through continual learning. The full self-hosted stack deploys via Docker Compose with PostgreSQL, Redis, RustFS for S3-compatible storage, and SearXNG for private web search, all configurable through environment variables. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. LobeHub Community licensed.
TradingAgents GUI
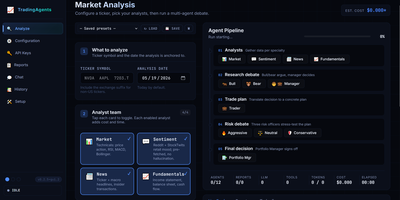
Built atop the TauricResearch TradingAgents framework with nearly 100,000 GitHub stars, TradingAgents GUI transforms a CLI-only multi-agent LLM stock analysis pipeline into a polished web application accessible at localhost:5000. The system deploys twelve specialized AI agents — fundamental analysts, sentiment experts, technical analysts, bull and bear researchers, a trader, risk management team, and portfolio manager — who collaboratively debate market conditions through structured LangGraph workflows before producing a final BUY, SELL, or HOLD recommendation. The interface supports ten LLM providers including OpenAI, Anthropic, Google, OpenRouter, DeepSeek, Ollama, xAI, Qwen, GLM, and MiniMax, with a first-run wizard that auto-detects configured API keys and tests connections. A live pipeline visualization shows each agent's status with real-time progress bars, while the tabbed output area separates Live Feed, Reports preview, and Tool calls into dedicated panes. The three-pane Reports tab provides searchable indexing, table-of-contents navigation, and export to Markdown, HTML, or PDF formats. Report length control across Concise, Standard, and Comprehensive modes saves up to 50% on token costs. Multi-session chat allows pinning past reports as grounding context with live token counting and context-window warnings. Three built-in themes — Terminal, Modern, and Bloomberg — persist per browser. Docker Compose deployment maps port 5000 with persistent report storage. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.