Traceway
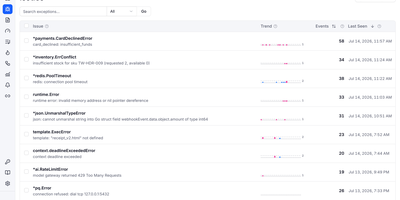
Production debugging slows to a crawl when logs, distributed traces, metrics, and session replays live in four disconnected dashboards, which is why Traceway consolidates every OpenTelemetry signal into a single self-hosted observability platform. Point any standard OTLP exporter directly at the ingestion endpoints without maintaining an intermediary collector or installing proprietary vendor SDKs. When an unhandled exception fires in production, automatic SHA-256 stack trace fingerprinting groups duplicates into prioritized issues complete with source-mapped frames and attached browser or Flutter session replays showing exact user clicks before the crash. Clicking any structured log entry jumps straight to its corresponding distributed span waterfall so engineers can trace slow database queries or failing downstream HTTP calls across microservices. Route performance bottlenecks surface immediately through per-endpoint P50, P95, and P99 latency percentiles ranked by Apdex and a five-factor impact score. Teams shipping AI features can also inspect LLM token consumption, model costs, tool calls, and multi-turn conversations grouped by customer identifier. Built-in on-call rotation schedules, escalation policies, and multi-channel alerts via Slack, Telegram, Pushover, email, and webhooks ensure incidents reach the right responder with one-click acknowledgment links. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Deploy