Imp
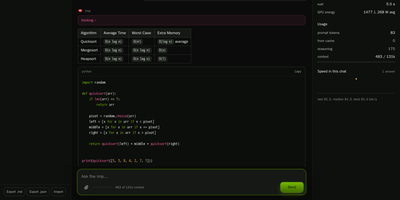
Imp runs large AI chat models privately on one NVIDIA RTX 50 or RTX PRO graphics card, exposing them through OpenAI and Anthropic compatible APIs plus a built-in browser chat. Start it with a single Docker command, point it at a model, and the chat opens in your browser with saved conversations and a live readout of generation speed. Coding agents such as Claude Code and Codex connect by changing one base URL, so your editor talks to the model on your own hardware instead of a rented cloud endpoint. Tool calls, structured JSON output, streaming responses, and reasoning models all work over the wire, and requests can be protected with an API key, per-IP rate limits, and concurrency caps. Load GGUF files you already have or NVFP4 and FP8 SafeTensors checkpoints straight from Hugging Face with no conversion step before the first answer. When a model is bigger than the card, mixture-of-experts weights stay in system RAM while the busiest experts are cached on the GPU, so a 123.6 GiB model still answers from a 32 GB card. Supported models can also read images alongside text, and tokenize, health, and model listing endpoints make the server easy to wire into scripts and monitors. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
OpenLLM
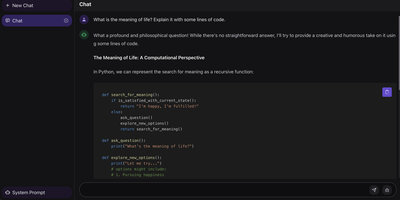
OpenLLM serves any large language model as an OpenAI-compatible API endpoint from a single CLI command, handling model download, backend selection, quantization, and port binding automatically. It supports the full spectrum of popular models including Llama 3.3, Qwen2.5, DeepSeek, Mistral, and Phi3, choosing between vLLM and PyTorch inference backends based on hardware capabilities. When vLLM is available, continuous batching with PagedAttention achieves up to 23x throughput improvement over naive serving, while GPTQ and bitsandbytes quantization reduces memory requirements for GPU-constrained deployments. The server exposes a RESTful API on port 3000 with full OpenAI client library compatibility, enabling drop-in replacement for commercial providers in any application using the standard chat completions format. A built-in web chat UI at the /chat endpoint provides immediate interactive testing without external clients. Custom model repositories allow teams to maintain private catalogs of fine-tuned models alongside the default repository that tracks the latest releases. Deployment workflows generate production-ready Docker images automatically, with Kubernetes manifest support for orchestrated scaling. Native integration with LangChain and LlamaIndex supports RAG pipelines, Transformers Agents enables tool-calling workflows, and HuggingFace Hub handles model discovery. Server-Sent Events enable real-time token streaming across all API endpoints. Backed by BentoML's production ML infrastructure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.