Categories
Machine Learning Self-Hosted AI GPU Computing Chat Interface AI Inference LLM Server OpenAI Compatible APIStars
Forks
Watchers
Developer links
Imp
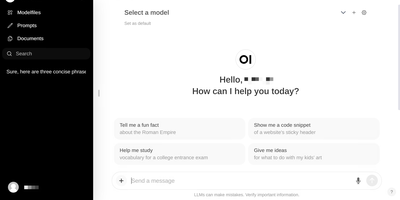
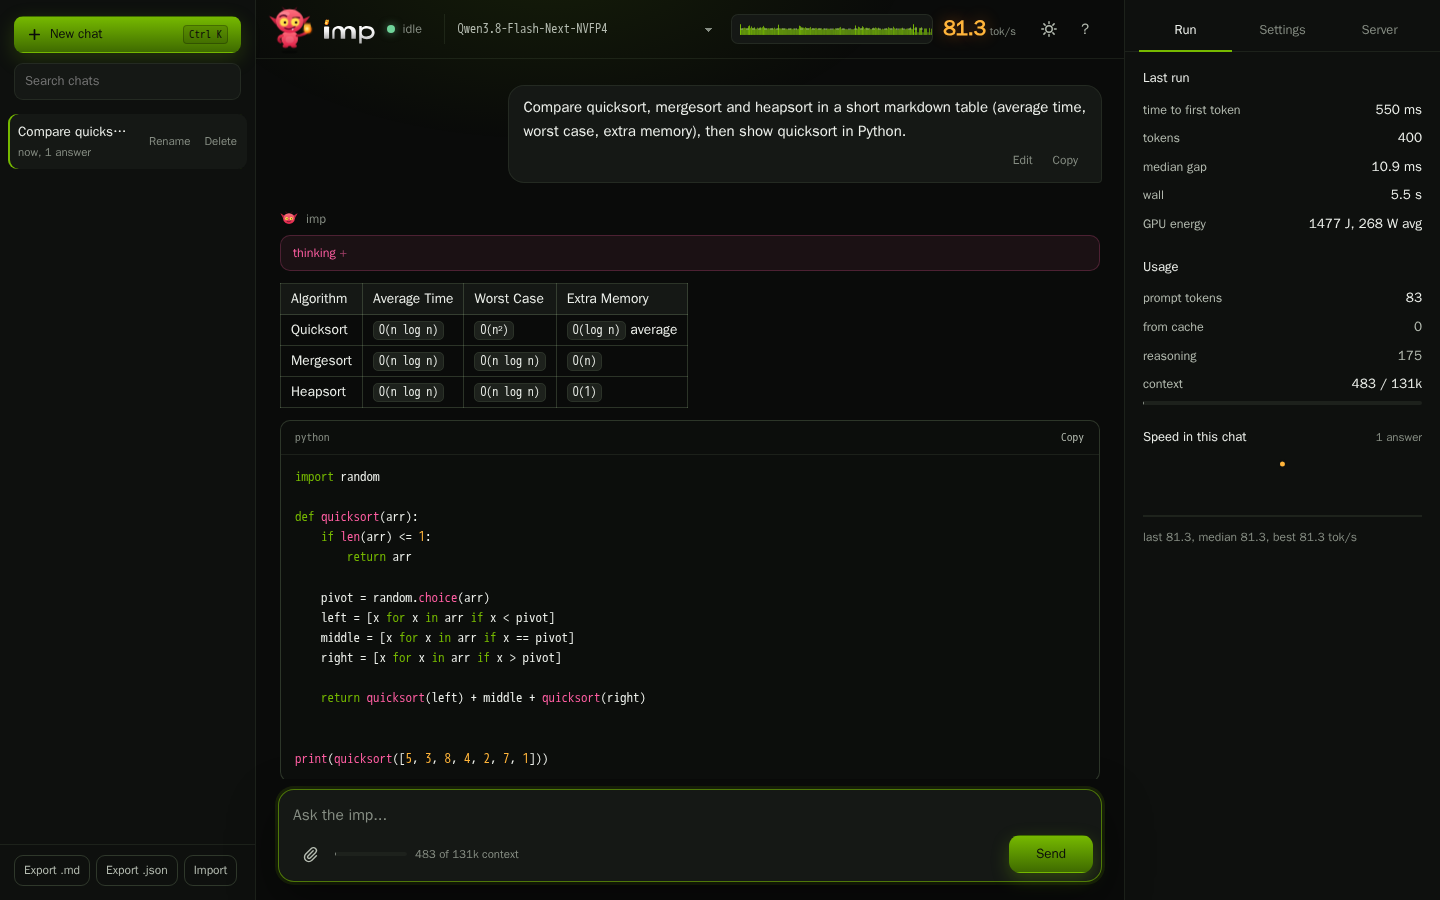
Imp runs large AI chat models privately on one NVIDIA RTX 50 or RTX PRO graphics card, exposing them through OpenAI and Anthropic compatible APIs plus a built-in browser chat. Start it with a single Docker command, point it at a model, and the chat opens in your browser with saved conversations and a live readout of generation speed. Coding agents such as Claude Code and Codex connect by changing one base URL, so your editor talks to the model on your own hardware instead of a rented cloud endpoint. Tool calls, structured JSON output, streaming responses, and reasoning models all work over the wire, and requests can be protected with an API key, per-IP rate limits, and concurrency caps. Load GGUF files you already have or NVFP4 and FP8 SafeTensors checkpoints straight from Hugging Face with no conversion step before the first answer. When a model is bigger than the card, mixture-of-experts weights stay in system RAM while the busiest experts are cached on the GPU, so a 123.6 GiB model still answers from a 32 GB card. Supported models can also read images alongside text, and tokenize, health, and model listing endpoints make the server easy to wire into scripts and monitors. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- Faster Answers On One Card
- On a single RTX 5090, Qwen3.8-27B streams at about 95 tokens per second for one user and roughly 1,975 tokens per second across 32 simultaneous users.
- Models Bigger Than VRAM
- Mixture-of-experts models keep their experts in host RAM and cache the busiest on the GPU, so a 123.6 GiB model runs on a 32 GB card.
- Drop-In API Compatibility
- OpenAI and Anthropic endpoints cover chat completions, responses, embeddings, and messages, so Claude Code, Codex, and OpenAI SDK apps connect by changing only the base URL.
- Private By Default Design
- Prompts and answers never leave your server, and optional API keys, per-IP rate limits, and concurrency caps keep a shared deployment under your control.
Features
- Built-In Browser Chat
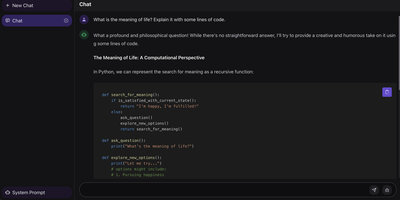
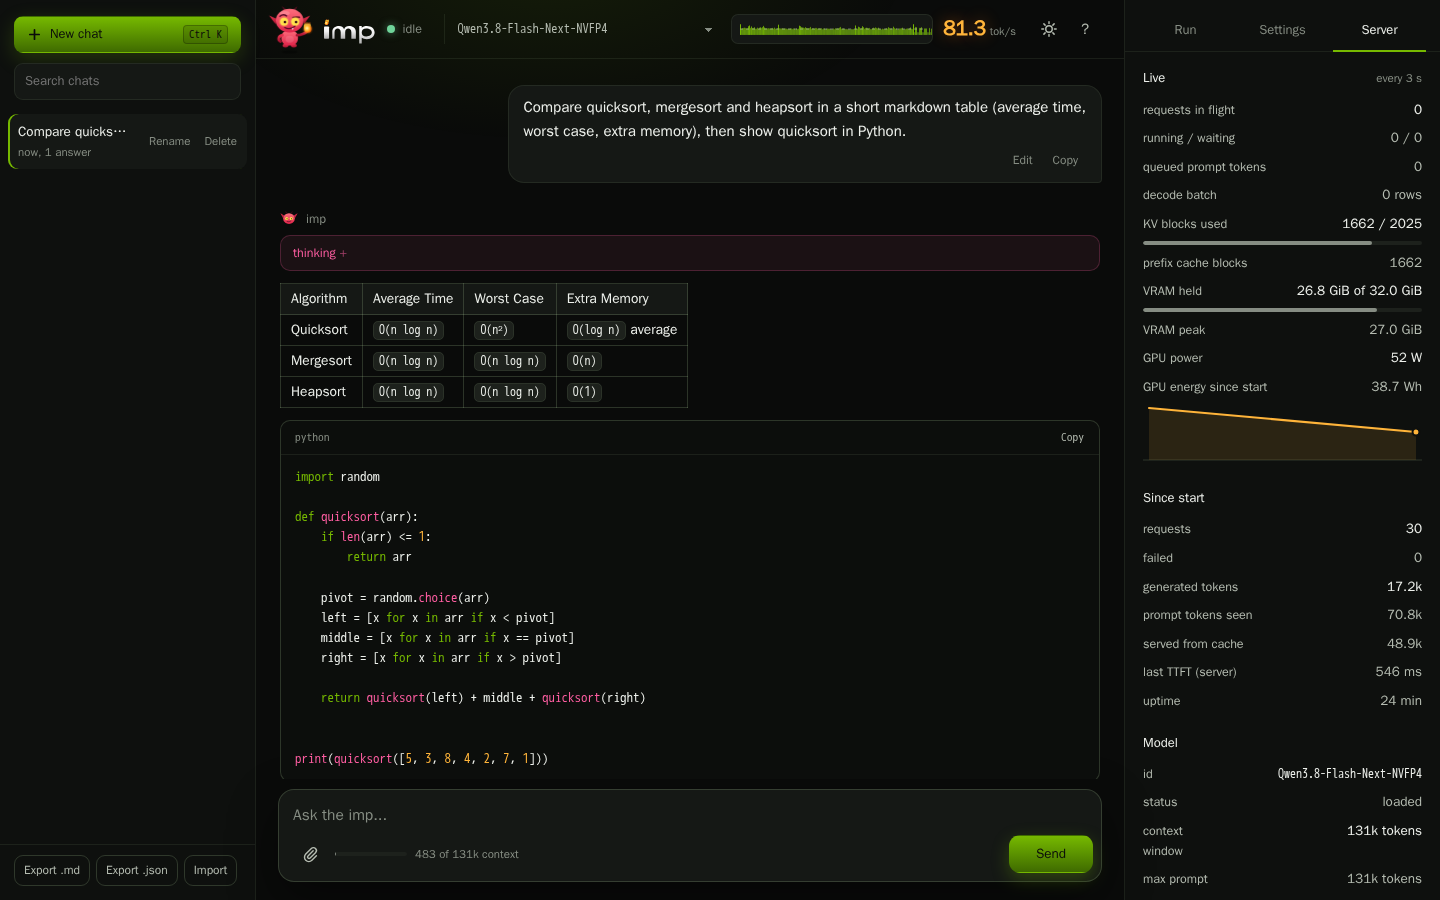
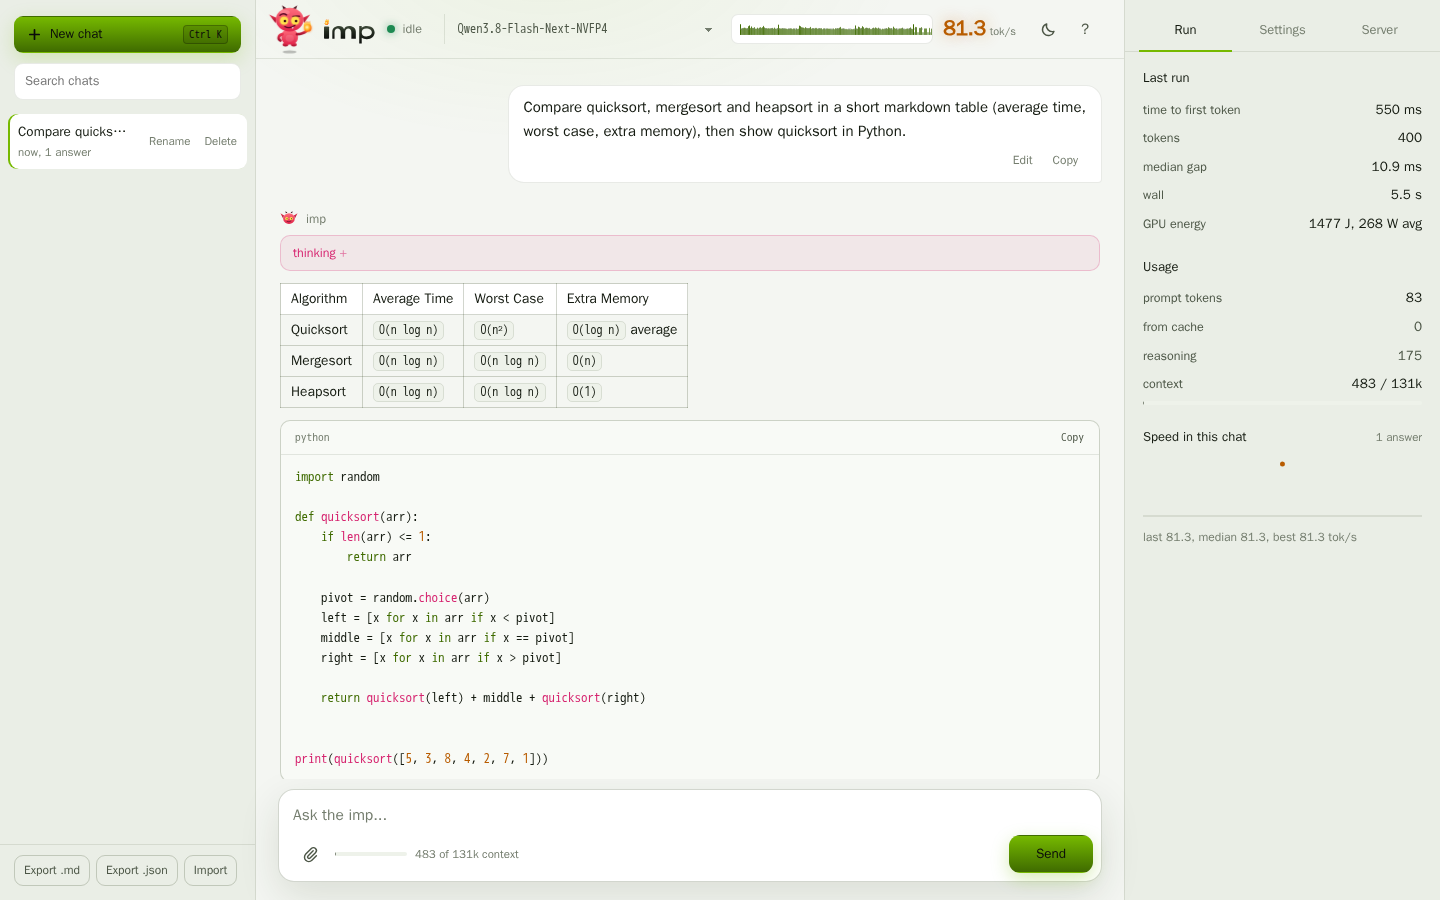
- The web interface at port 8080 keeps saved conversations and shows live generation speed, token counts, and per-request timing while answers stream in.
- OpenAI And Anthropic APIs
- Endpoints include chat completions, the Responses API, embeddings, models, and Anthropic messages, with streaming, tool calling, logprobs, and JSON output supported.
- GGUF And NVFP4 Loading
- Point the server at an existing GGUF file or an NVFP4 or FP8 SafeTensors checkpoint from Hugging Face; no conversion step is required.
- Expert Offload To RAM
- Oversized mixture-of-experts models store experts in system memory and cache hot experts in VRAM, trading a little speed for models several times the card size.
- Vision Model Support
- Attach a multimodal projector with the mmproj option so supported models such as Gemma vision checkpoints can answer questions about images as well as text.