OpenStatus
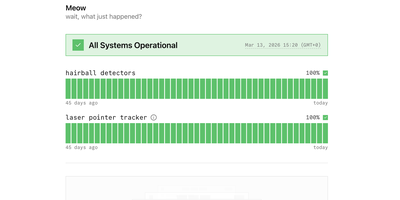
Trusted by Cal.com, WhiteBIT, and Documenso and backed by 8,800+ GitHub stars, OpenStatus delivers the open-source status page and uptime monitoring platform that replaces Atlassian Statuspage, Better Stack, and Instatus with a single self-hosted deployment. The monitoring engine runs Go-based probes across 28 global regions on three cloud providers checking HTTP, TCP, and DNS endpoints in parallel with configurable intervals and multi-region consensus to eliminate false-positive alerts. Status pages ship with custom domain support, password and email-domain access controls, maintenance windows, grouped monitor components, and subscriber notifications via email and RSS. Incident management provides structured status reports with investigating, identified, monitoring, and resolved timeline phases that publish automatically to affected status pages. The monitoring-as-code workflow supports YAML configuration synced through the CLI, a GitHub Actions integration for CI/CD pipelines, and a Terraform provider for infrastructure-as-code deployments. The typed ConnectRPC JSON-over-HTTP API exposes a published OpenAPI specification with a Node SDK for programmatic access, while an MCP server connects AI assistants like Claude, ChatGPT, and Cursor directly to workspace data. The tech stack combines Next.js with shadcn/ui for the dashboard, Hono for the API server, Drizzle ORM over Turso for application data, and Tinybird for analytics. Private monitoring locations deploy as a single 8.5MB Docker image behind firewalls to check internal services. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Kener
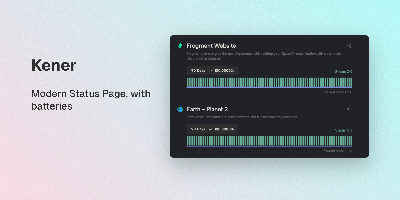
A polished public status page without Statuspage prices or a heavyweight observability suite: Kener is a status and uptime monitoring system built with SvelteKit and Node.js. It runs 11 monitor types - API, Ping, TCP, DNS, SSL certificate, SQL query, Heartbeat, gRPC, and GameDig game-server checks among them - each with configurable intervals and thresholds. Incident management covers the full lifecycle: structured timelines from investigation through resolution, acknowledgements, and subscriber-visible updates, plus maintenance windows with RRULE-based recurring schedules and automatic status transitions. Notifications reach email, Slack, Discord, and custom webhooks through trigger-based workflows with template-driven messaging. One instance can serve multiple branded status pages - per product, team, or region - with custom logos, colors, and CSS, localization into 21 languages, timezone-aware displays, and server-rendered pages that stay fast and SEO-friendly. Operations tooling includes role-based access for teams, API key management, a secrets vault, analytics integrations (Google Analytics, Plausible, Umami, and others), and a REST API with 17+ endpoints for automating incidents and monitors from CI/CD. MIT-licensed; Docker deployment with Redis, SQLite by default, PostgreSQL or MySQL for production.
UptimeKit
UptimeKit watches your services from several regions at once and publishes the verdict on a status page your customers can actually read. A central dashboard assigns checks to worker probes that run them on schedule, covering HTTP and HTTPS, TCP, ICMP ping, DNS, keyword matches, and JSON responses. Monitors are sorted into nested groups and tags, and HTTPS targets get automatic certificate expiry tracking. When something breaks, an incident takes shape with severity, status transitions, comments, and a resolution flow, either from the dashboard or from a Prometheus AlertManager alert. Status pages come in multiple flavors: public, password protected, or tied to a custom domain, with themes, uptime history bars, and email subscribers who hear about every update. Notifications reach Discord, Google Chat, Telegram, ntfy, Apprise, and plain webhooks. Organizations with roles keep several teams in one installation, and OIDC single sign-on connects the login to an existing identity provider. Response time charts break latency into percentiles per region over any period you pick. A planned maintenance window announces itself on the status page before it begins. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Vigil
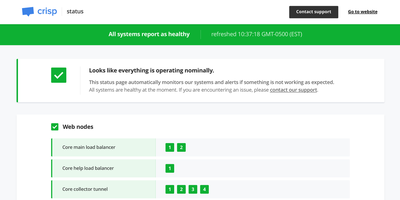
Vigil monitors your entire distributed infrastructure and generates a public status page from a single Rust binary small enough to run on a Raspberry Pi, consuming minimal CPU and memory while providing crash-free reliability. Four distinct monitoring modes cover every topology: poll probes check HTTP, TCP, SSH, and ICMP endpoints for reachability with configurable intervals and thresholds; push probes receive health reports from Vigil Reporter libraries embedded in your application code across Node.js, Python, Golang, Rust, TypeScript, Dart, and C#; local probes delegate monitoring to Vigil Local slave daemons running behind firewalls on separate LANs; and script probes execute custom shell commands for specialized health checks. Each monitored service transitions through healthy, sick, and dead states based on consecutive probe failures, with configurable thresholds controlling state transition sensitivity. When services change state, Vigil dispatches notifications through twelve alert channels including Slack, Email, Twilio SMS, Telegram, Pushover, Gotify, XMPP, Matrix, Zulip, Cisco Webex, and generic webhooks. The generated status page displays service groups organized by category with real-time replica status, system load metrics from reporter probes, and a maintenance announcement system for communicating planned downtime through the Manager HTTP API. Configuration uses a single TOML file defining all probes, services, and notification channels with no database dependency. Docker deployment pulls the official image with volume-mounted configuration. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MPL-2.0 licensed.
Better Status Page
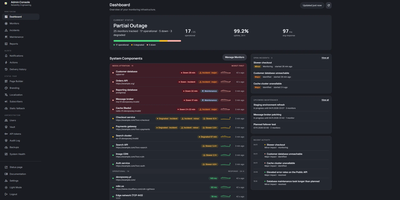
Better Status Page watches your services around the clock and turns outages into calm, branded status updates for your users instead of a flood of support tickets. Its monitors probe HTTPS endpoints with authentication flows and TLS expiry warnings, ping and TCP ports, DNS records, Docker containers, mail servers over SMTP, IMAP, and POP3, and databases from PostgreSQL and MySQL to Redis, MongoDB, SQL Server, and Oracle. A slower-than-usual alert fires when a monitor's p95 response time climbs against its own last seven days, and passive webhook heartbeats catch jobs that simply stop checking in. Alerts reach the team through email, Slack, Discord, Microsoft Teams, Telegram, ntfy, Pushover, webhooks, and Twilio SMS or voice calls, with failure thresholds, quiet hours, rate caps, and grouping keeping the noise down. Incidents carry severity levels, public updates, linked monitors, and recurring maintenance windows, and subscribers follow along by email, webhook, RSS or Atom feed, or a JSON status API. A drag-and-drop builder restyles the public page with your branding, dark mode, and translations, a static fallback keeps the page readable if the server itself falls over, and uptime reports export to CSV for SLA reviews. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Cachet
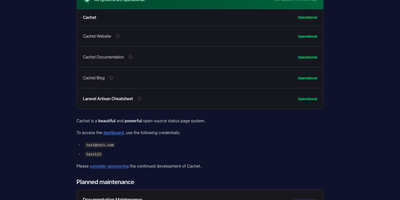
Cachet Core is the open-source engine behind Cachet 3.x status pages, giving your team a self-hosted page where incidents, maintenance windows, component health, and live metrics keep customers informed during downtime. You publish an incident with a name, status, and visibility, then post updates on its timeline as work progresses, and the public page reflects every change immediately. Services become components you can group and mark operational, degraded, partially out, or fully down, so visitors see exactly which part of your platform is affected. Maintenance gets scheduled ahead with its own updates, and subscribers receive notifications when new incidents appear or change. Custom metrics accept data points through the API and render as charts on the page, turning response times or queue depths into public proof of recovery. A JSON API creates and updates incidents from your monitoring stack, and webhooks push incident events to the chat rooms and tools your team already watches. The dashboard handles components, incidents, metrics, subscribers, tags, and user accounts, with status page customization and localization in more than 10 languages. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.