OpenClaw VPS
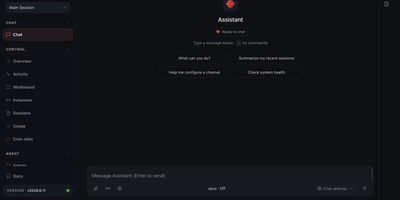
A personal AI assistant that remembers what it learns and reaches you wherever you are — OpenClaw is an open-source agent gateway built by the OpenClaw Foundation with 247,000+ GitHub stars. It connects to 200+ LLM models through providers like Anthropic, OpenRouter, and OpenAI, and meets you on 21+ messaging channels: Telegram, Slack, Discord, WhatsApp, Signal, iMessage, Matrix, and more. Persistent memory with full-text search lets the agent recall context across sessions, and a self-improving skills system means it gets more capable the longer it runs. Voice wake words and talk mode enable hands-free interaction on macOS, iOS, and Android. A live canvas provides an agent-driven visual workspace. Built-in browser automation, cron scheduling for unattended tasks, and subagent spawning for parallel workstreams round out the toolset. The gateway architecture keeps all sessions, credentials, and conversation history on your own server — nothing transits a third-party cloud unless you choose to connect one. The API key you provide for your chosen LLM provider powers the underlying calls; billing goes through your own account. Running on a dedicated VPS with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
NextChat
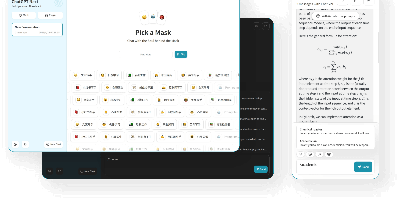
Thirteen-plus LLM providers, one unified client: NextChat (formerly ChatGPT-Next-Web) is an open-source AI chat interface built on Next.js that spans OpenAI GPT-4, Anthropic Claude, Google Gemini, DeepSeek, Groq, Azure endpoints, and self-hosted backends like Ollama, LocalAI, and RWKV-Runner. Its defining trait is minimalism - the first screen loads in about 100 KB, the desktop client is roughly 5 MB, and there is no database or user system to operate; chat history lives locally in the browser with optional WebDAV or UpStash Redis sync. The Mask system saves reusable prompt-template personas you can share and debug, long conversations auto-compress to fit context windows, and Markdown rendering covers LaTeX, Mermaid diagrams, and code highlighting with streaming responses. Plugins add web search and calculators, MCP support enables external tool calling, and Artifacts previews generated content in a separate pane. Ships as a web app, Docker image, and Tauri desktop builds for Windows, macOS, and Linux, translated into 20+ languages. MIT-licensed.
Morphic
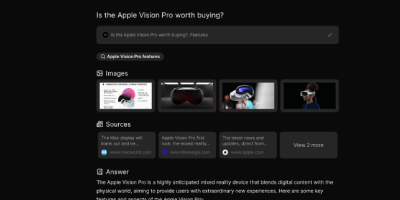
Perplexity's answer-engine experience, self-hostable and open-source: Morphic searches the web and writes cited answers. Instead of returning a list of links, it searches the web, reads the sources, and generates a complete answer with inline numbered citations. The generative UI streams rich components, source cards with thumbnails, image grids, syntax-highlighted code, and LaTeX math, rather than plain markdown. Quick mode answers fast; Adaptive mode runs deeper multi-step research. Search backends are pluggable: the Docker Compose bundle ships with a private SearXNG instance so no search API key is required, and Tavily, Brave, and Exa are supported alternatives. LLM providers include OpenAI, Anthropic, Google, Ollama, and any OpenAI-compatible endpoint, with per-mode model mapping - fast, cheap models for quick searches, stronger models for adaptive research, tuning the cost-quality trade-off per query type. An inspector panel exposes tool execution during multi-step research, and AI-suggested follow-up questions keep an investigation moving. Chat history persists in PostgreSQL, results are shareable by URL, file uploads feed context into queries, and optional Supabase authentication adds multi-user or guest access. Because the default search path is your private SearXNG instance, research topics never hit a commercial search API - and with local Ollama models the marginal cost of a query approaches zero. Built with Next.js, TypeScript, and the Vercel AI SDK under Apache 2.0.
Nanobot
With over 46,000 GitHub stars, nanobot is the ultra-lightweight personal AI agent framework that delivers full agentic capabilities — tools, persistent memory, multi-agent workflows, scheduled automation, and 10+ chat channel integrations — in approximately 4,000 lines of readable Python core code. The agent loop receives messages from any connected channel, builds context from session history and long-term memory files, calls the configured LLM provider, executes requested tools, and publishes replies back to the originating channel. Supported LLM providers include OpenAI, Anthropic, Google Gemini, DeepSeek, Qwen via DashScope, Moonshot/Kimi, Ollama, vLLM for local models, and any OpenAI-compatible API through OpenRouter or LiteLLM. Chat channels connect the agent to Telegram, Discord, Slack, WhatsApp, Feishu/Lark, DingTalk, Email via IMAP/SMTP, QQ, Matrix with end-to-end encryption, Mattermost, and the built-in browser WebUI served from the published Python wheel with no separate frontend build. Built-in tools include filesystem read/write/edit, shell execution with configurable sandboxing via bubblewrap, web search and fetch with SSRF protection, MCP server integration, cron scheduling, image generation, and subagent spawning for parallel task delegation. The Dream memory system consolidates session history into persistent markdown files for long-term context retention across conversations. Deployment runs as a CLI agent, a persistent gateway server, a Docker container with Docker Compose, or an OpenAI-compatible API server. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Deep Research Web UI
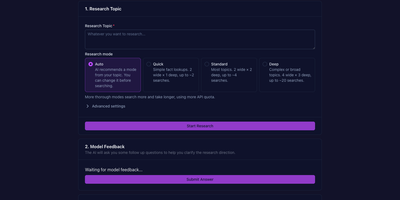
Ask a hard question and get back a cited report instead of a chat answer: Deep Research Web UI plans its own searches, reads the pages it finds, checks claims against the sources, and shows its work as it goes. The research unfolds as a live tree in your browser, each branch a search direction with streaming responses, so you watch a broad question narrow into answerable parts. When snippets are not enough, it fetches full source pages and extracts verbatim evidence, sharing one token and request budget across the run. Every claim cites its source inline, and clicking a citation opens an evidence panel with the source, retrieval time, and the excerpt behind the finding. Findings can be followed up: name what to verify and the agent searches again, updating only the passages that cite that finding while the original report stays untouched in your history. You bring the models, from OpenAI-compatible endpoints, DeepSeek, and OpenRouter to a local Ollama or LiteLLM proxy, paired with Tavily, Firecrawl, Google PSE, You.com, or Serply for the searching. Finished reports export as Markdown or PDF, search separates your question from time and source filters and retries once with a revised query when evidence is thin, and Server Mode keeps the team's API keys in environment variables behind an optional access password instead of in every visitor's browser. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Trinity
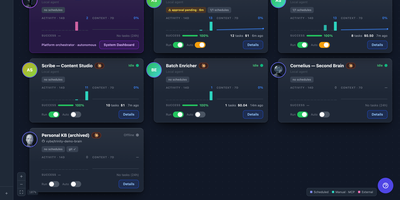
Trinity runs your AI agents the way a company runs employees, with departments, roles, reporting lines, and receipts for everything they do. Each agent holds a seat on record tied to an objective and a declared metric, so whether it is working is a number with a date on it rather than an impression. Agents work on three runtimes, Claude Code, OpenAI Codex, and Gemini CLI, chosen per chat without changing the agent's state, history, or permissions. A schedule fires, the agent works inside its own container, and anything irreversible waits in a human approver's Inbox as a card naming the agent, the skill, and the input until someone approves, discusses, or rejects it. Every agent is a git repository you own: it commits its own work, its tool calls land in an append-only audit log, and every run appears in an execution ledger with its trigger, cost, and outcome, searchable across the fleet. The same agents answer in the browser Workspace, in Slack, Telegram, and WhatsApp, over a public chat link, through MCP, and from the CLI. Guardrails bind agents by what they hold rather than what they are told, with hooks they cannot switch off, cost limits, loop budgets, and a kill switch for outbound calls. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Ollama GUI
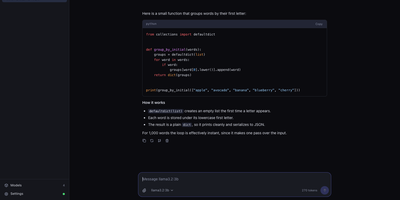
Chat with your own local language models from a clean, fast browser interface. Ollama GUI gives every model on your Ollama server a proper home: streaming replies you can stop, regenerate, or edit, with each edit saved as a version you can flip back to. Reasoning models show their thinking in a collapsible block, and you pick between thinking on, off, or an effort level. Attach images for vision models or drop in text and code files, and answers render with highlighted code, tables, and math. Pull models from a searchable catalog with live progress, check their capabilities and context length, unload them from memory, or delete them in a click. Chats are grouped by date, pinned, archived, renamed, titled automatically, and searched across every message from a command palette. System prompts and generation settings apply globally, per model, or per chat. Light and dark themes, locale-aware dates, and JSON or Markdown export round out the daily routine. Run one shared front end for a whole team or homelab, and every browser keeps its own private history. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.