RisingWave
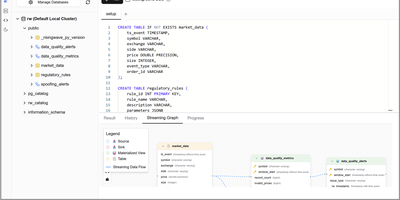
With over 9,100 GitHub stars and production deployments powering real-time analytics at companies like SHOPLINE where it reduced API latency by 76.7%, RisingWave is the PostgreSQL-compatible streaming database that collapses the traditional Debezium-plus-Kafka-plus-Flink-plus-serving-database stack into a single Rust-powered system. The platform continuously ingests data from PostgreSQL and MySQL via native CDC connectors that eliminate Debezium middleware, consumes Kafka, Redpanda, Pulsar, and Kinesis topics, accepts webhook events from SaaS applications, and batch-loads historical data from S3 and data warehouses. Standard SQL defines sources, materialized views, and sinks — no new DSL, no Java, and no custom API — while the PostgreSQL wire protocol means psql, DBeaver, pgAdmin, Grafana, Metabase, Superset, Tableau, and every PostgreSQL client library works without modification. Materialized views are incrementally maintained as events arrive, delivering point lookups in single-digit milliseconds without recomputing aggregates from scratch. For long-term retention, RisingWave writes to Apache Iceberg tables with a hosted REST catalog and automated table maintenance including compaction, small-file optimization, and snapshot cleanup, with data queryable by Spark, Trino, DuckDB, and DataFusion. The disaggregated compute-storage architecture uses S3-based state management for elastic scaling, instant failure recovery measured in seconds rather than the minutes-to-hours typical of RocksDB-based systems, and cost-efficient storage tiering. An MCP server enables AI agents to query and operate RisingWave directly. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Redpanda
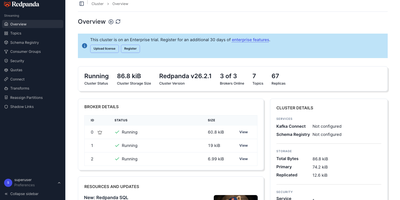
With 12,400 GitHub stars and adoption across enterprises processing billions of events daily, Redpanda delivers a complete Kafka wire protocol implementation in C++ that existing Kafka producers, consumers, Kafka Connect connectors, and Kafka Streams applications connect to without code changes — eliminating JVM garbage collection pauses and ZooKeeper coordination overhead through a single binary architecture built on the Seastar framework's thread-per-core model. The integrated schema registry supports Avro, Protobuf, and JSON Schema validation directly within the broker without separate infrastructure. Tiered storage automatically offloads cold data to object storage while maintaining seamless consumer access across the full retention window. Redpanda Console provides a web-based management interface for topic inspection, consumer group monitoring, schema management, and ACL configuration. Redpanda Connect extends the platform with 200+ pre-built connectors for data pipelines between databases, cloud services, and streaming systems. Exactly-once semantics with idempotent producers and transactional guarantees ensure data integrity for financial, healthcare, and compliance workloads. The Adaptable Data Plane in version 26.1 enables per-topic performance profiles balancing throughput, latency, and durability within a single cluster. Deploy via Docker or Kubernetes with official Helm charts — a three-node cluster starts with a single rpk command. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSL 1.1 licensed (converts to Apache 2.0 after four years).
Apache Kafka
Used by over 80% of Fortune 100 companies including LinkedIn, Netflix, Uber, and Goldman Sachs, Apache Kafka processes trillions of messages per day as the world's most widely deployed distributed event streaming platform. Since version 4.0 released in March 2025, Kafka operates exclusively with KRaft consensus, replacing Apache ZooKeeper entirely with an internal Raft-based metadata quorum managed by controller nodes, reducing operational complexity and eliminating external coordination dependencies. Topics are organized as append-only partitioned commit logs with configurable replication factors across brokers, delivering network-limited throughput with end-to-end latencies as low as 2 milliseconds. Kafka Streams provides a client library for building stateful stream processing applications with exactly-once semantics, windowed aggregations, joins across streams and tables, and interactive queries against local state stores. Kafka Connect integrates with hundreds of systems including PostgreSQL, MySQL, Elasticsearch, Amazon S3, MongoDB, HDFS, and JMS through a standardized connector framework with distributed worker mode and automatic offset management. Share Groups introduced in version 4.2 deliver queue-style consumption semantics alongside traditional consumer groups, enabling Kafka to serve both pub-sub and point-to-point messaging patterns natively. The Schema Registry enforces Avro, Protobuf, and JSON Schema compatibility rules across producers and consumers, preventing schema evolution from breaking downstream applications. Tiered Storage offloads older log segments to object storage like S3 while maintaining transparent consumer access, dramatically reducing local broker storage costs for long-retention topics. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
AKHQ
AKHQ puts every Kafka cluster your team runs into one browser console, so topics, messages, consumer lag, schemas, and connectors stop being command-line archaeology. Browse live data inside any topic with search and Live Tail, inspect records by key or partition, and produce test messages without touching a console producer. Consumer group views show lag per partition, and offset resets take a couple of clicks instead of a maintenance window. Multiple clusters sit side by side in the same interface, each with its own Schema Registry, Kafka Connect, and ksqlDB connections attached. Schemas can be created, updated, and versioned from the UI, and Connect clusters report connector and task status you can pause, restart, or reconfigure. Administrators manage ACLs and cluster configuration from the same screens developers use to explore data. Access control goes deep: roles bundle resources and actions, groups scope them with topic patterns and cluster restrictions, and sign-in plugs into OIDC, LDAP, or basic authentication. Point it at your brokers with one configuration file, run it as a single container, and the whole platform team shares one safe window into production Kafka. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Apache RocketMQ
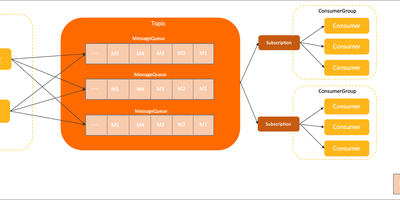
When your services need to talk without waiting on each other, Apache RocketMQ carries the conversation: a distributed messaging platform where producers publish to topics and consumers process at their own pace, with delivery guarantees you can build money movement on. Send ordinary messages for fire-and-forget events, transactional messages that commit or roll back with your local database transaction, ordered and FIFO messages for sequences that must not shuffle, and delayed messages that arrive seconds or days later on schedule. Consumers pull with long polling, filter by tag or SQL expression at the broker, and retry failures through built-in retry queues and dead letter queues instead of losing work. Clusters scale by adding brokers, while Controller mode elects broker replicas automatically so a failed node stops being a page. The Proxy component speaks gRPC with modern multi-language clients and adds POP consumption, where messages become invisible while processed and reappear if the consumer never acknowledges. Tiered storage offloads cold messages to cheaper object storage while hot data stays on local disk, and RocketMQ Streams, Connect, and an MQTT bridge extend the same cluster into stream processing, data integration, and device messaging. Lite Mode trims subscription overhead for AI workloads, and the separate RocketMQ Dashboard gives operators a web console for topics, consumers, and message tracing. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Fluvio
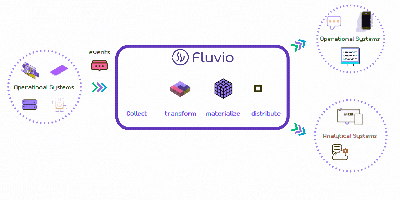
Fluvio is a distributed data streaming platform that moves records between your applications on partitioned topics and transforms them in flight with WebAssembly modules before they land anywhere. Producers publish to topics and consumers read at their own pace, with client libraries for Rust, Python, and JavaScript plus a full command line for producing and consuming interactively. SmartModules are reusable WebAssembly functions that filter, reshape, and enrich records inside the stream, so cleanup and routing logic runs once at the platform layer instead of inside every consumer. Stateful DataFlow builds continuous processing on top of the same streams, keeping state across records to aggregate, join, and react as data arrives. Inbound connectors collect from HTTP endpoints, webhooks, MQTT brokers, and Kafka clusters, and outbound connectors deliver to HTTP, SQL databases, and Kafka, with a development kit for building connectors to your own systems. A local cluster starts with one command for development, and the same platform deploys on Kubernetes for production streaming at the edge or in the cloud. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Apache EventMesh
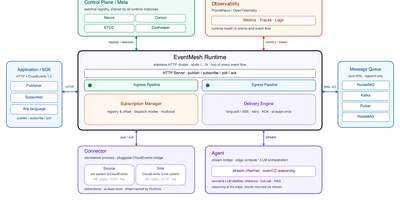
Applications publish an event once and stop caring who needs it next: Apache EventMesh receives CloudEvents over plain HTTP, stores them durably, and delivers each one to every subscription that matches. Producers call publish, consumers call subscribe or unsubscribe, and the runtime owns the registry, offsets, acknowledgements, and redelivery that messaging clients usually force you to build yourself. Subscribers choose load-balanced delivery for competing workers, broadcast delivery for every listener, or multicast for selected groups, and they receive events by HTTP long polling, Server-Sent Events, or WebSocket push. Filters drop irrelevant events before they leave the mesh, while transformers reshape payloads so a producer and consumer can disagree about format without either one changing code. Kafka and RocketMQ act as pluggable write-ahead storage, with an in-memory backend for development, and stateless runtime instances scale horizontally without consumer-group rebalancing. Twenty-three connectors move events into and out of RabbitMQ, Pulsar, MongoDB, MySQL change data capture, Redis, S3, Prometheus, Slack, DingTalk, Lark, WeChat, and AI services, each checkpointing offsets so failures replay instead of silently losing data. Agent-to-Agent protocol support and MCP connectors let AI agents exchange asynchronous events alongside synchronous tool calls, and event-triggered agents can publish decisions back into the mesh for downstream delivery. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.