Duplicati
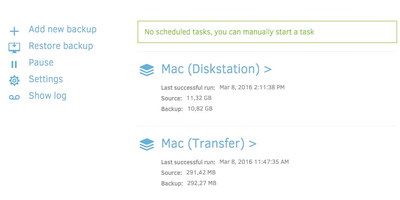
Encrypted, incremental, compressed backups on storage you already have - Amazon S3, Backblaze B2, Google Drive, Azure, OneDrive, Dropbox, MEGA, Storj, WebDAV, SFTP, FTP, SMB, or a plain local disk - is what the MIT-licensed Duplicati has quietly done for years. Its security model is Trust No One: every block is encrypted with AES-256 (or a local GPG instance) before leaving the machine, and the passphrase never travels, so the storage provider holds only ciphertext. The block-based storage engine gives the best of both backup worlds: after one initial full backup, only changed data blocks upload - modify a tiny part of a huge file and only that part transfers - yet every backup version restores like a full backup in a single operation, with no incremental chains to replay. Deduplication and compression keep remote storage growth slow even across years of versions. A web interface manages everything: the built-in scheduler keeps backups current automatically, flexible filters select folders, file types, or custom patterns, retention policies prune old versions, and an integrated updater flags new releases. On compatible object-lock backends, immutable (WORM) storage protects backup data from ransomware that reaches the credentials. Runs on Windows, macOS, and Linux, free even for commercial use.
Borg Backup Server
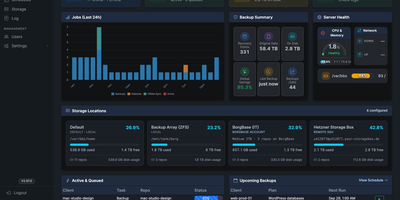
Every connection starts at the endpoint, never at the server, so Borg Backup Server can back up Linux, Mac, and Windows machines behind NAT and firewalls without opening a single inbound port. A lightweight agent on each machine polls for tasks over HTTPS, pushes deduplicated archives over SSH, and reports live progress. Append-only SSH access means an endpoint can add and restore archives but never prune or delete them. The dashboard shows backup charts, server stats, and active jobs at a glance. Plans run from hourly to monthly, several per client, built from reusable directory templates for common server roles, with per-plan retention from hourly to yearly. Lost a file? Browse the archive tree in your browser, tick what you need, and restore it to the client or download a .tar.gz. MySQL and PostgreSQL dumps run before each backup and restore as a copy or a replacement. Repositories can live on the server, on BorgBase, Hetzner, or rsync.net, and mirror to S3-compatible storage such as AWS, Wasabi, or Backblaze B2. Apprise alerts reach more than 100 services, and a nightly report lands in your inbox. Two-factor login and role-based access guard the console. Upgrades roll out to the server and every agent together, and the server backs itself up daily. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Pluton
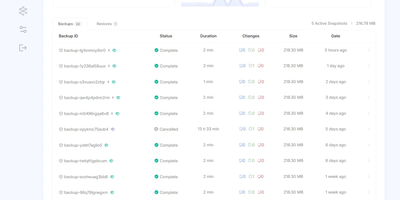
On a schedule you choose, Pluton backs up your folders to cloud storage and other disks, then lets you verify and restore every snapshot and see exactly what happened in a clean, self-hosted web dashboard. Three copies: every plan writes to a primary storage and can replicate to up to two more, so the 3-2-1 rule is a toggle in the plan wizard rather than a weekend project. Two kinds of media: pair a local disk or mounted drive with Backblaze B2, Cloudflare R2, Google Drive, Dropbox, pCloud, SFTP, S3-compatible buckets, or any of 70+ connectors, and press Verify to test a connection before trusting it. One place to look: the plan page charts file counts and sizes over a selectable range, a health strip colors recent runs, and a live panel counts files, bytes, and time remaining while each mirror initializes and replicates. Zero mysteries: every backup keeps a timestamped event timeline from dry run to pruning, and plan logs filter by level and task, search messages, and download as a file. Schedules run from every few minutes to monthly, including chosen weekdays; retention keeps daily, weekly, and monthly snapshots; and scripts can run before or after a job. Alerts reach you by email, Slack, Discord, or ntfy, and optional two-factor sign-in guards the dashboard. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Kopia
Engineers who have outgrown Duplicati or rsync scripts tend to appreciate Kopia's design: encrypted, compressed, content-deduplicated snapshots in Go, stored in a repository on any storage you control - S3, Google Cloud Storage, Azure Blob, Backblaze B2, SFTP, WebDAV, or a plain filesystem. Encryption is mandatory and end-to-end: every block is encrypted client-side with AES-256-GCM or ChaCha20-Poly1305 using keys derived from your repository password, and even file names never leave the machine in plaintext. Blocks are packed into 20-40 MB blobs with random names, so the storage provider learns nothing about content or structure. Deduplication is automatic and content-based - identical data across files, snapshots, and even multiple machines backing up to the same repository is stored once. Policies govern everything per-directory: compression choice, retention (hourly through annual), scheduling, and ignore rules. Incremental snapshots are point-in-time records you can mount and browse like a filesystem. This deployment runs the Kopia repository server with its web UI, centralizing backups from multiple client machines over an authenticated API - each client connects with the server URL and certificate fingerprint, and users only see their own snapshots. Error correction, high-latency-tolerant caching, and both CLI and GUI round it out.