Ollaya
Ollaya serves decision models that answer typed questions about a message, ticket, or document with calibrated probabilities, through a self-hosted API shaped like the hosted service it can replace. Send a state, which can be an email, a support ticket, or any JSON, plus typed choice, score, and yes or no questions, and the model answers in one forward pass in milliseconds without generating text. Pull models by name the way Ollama users already know, with run, list, ps, show, copy, and remove commands managing the local store. Downloads verify every layer against its sha256 digest, resume when interrupted, and share blobs between models so storage stays lean. Existing TypeSafe code keeps working by changing one environment variable, because the /v1/systemone and /v1/decisions endpoints are wire-identical and the official SDK sends its key the same way. The native /api adds routing information and timings, model loading and unloading, and streamed pull progress for your own tooling. Put it to work triaging inboxes, routing requests to the right model or team, screening prompts for injection and jailbreak attempts, or replacing per-token LLM classification calls with a local answer. Agents reach the same engine through the bundled MCP server, and LiteLLM, LangChain, DSPy, LlamaIndex, n8n, and Dify connect through their existing integrations. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Imp
Imp runs large AI chat models privately on one NVIDIA RTX 50 or RTX PRO graphics card, exposing them through OpenAI and Anthropic compatible APIs plus a built-in browser chat. Start it with a single Docker command, point it at a model, and the chat opens in your browser with saved conversations and a live readout of generation speed. Coding agents such as Claude Code and Codex connect by changing one base URL, so your editor talks to the model on your own hardware instead of a rented cloud endpoint. Tool calls, structured JSON output, streaming responses, and reasoning models all work over the wire, and requests can be protected with an API key, per-IP rate limits, and concurrency caps. Load GGUF files you already have or NVFP4 and FP8 SafeTensors checkpoints straight from Hugging Face with no conversion step before the first answer. When a model is bigger than the card, mixture-of-experts weights stay in system RAM while the busiest experts are cached on the GPU, so a 123.6 GiB model still answers from a 32 GB card. Supported models can also read images alongside text, and tokenize, health, and model listing endpoints make the server easy to wire into scripts and monitors. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
LocalAI
With over 48,000 GitHub stars and monthly releases since March 2023, LocalAI is the self-hosted AI engine that replaces every OpenAI endpoint with a single Docker container running on your own infrastructure — serving chat completions, image generation, text-to-speech, speech-to-text, embeddings, vision, video generation, and function calling through identical API schemas that require zero application code changes. The composable backend architecture isolates each inference engine as a separate gRPC service running in its own OCI container, so llama.cpp, vLLM, SGLang, transformers, whisper.cpp, diffusers, MLX, Stable Diffusion, and Flux install on demand without touching the core, can run on separate machines, and a fault in one never affects others. Hardware acceleration spans NVIDIA CUDA 12 and 13, AMD ROCm, Intel oneAPI/SYCL, Apple Silicon Metal, Vulkan, and NVIDIA Jetson L4T — or runs entirely on CPU without any GPU. Built-in AI agents support autonomous tool use, retrieval-augmented generation, Model Context Protocol integration, and skill-based workflows directly in the web interface. The model gallery provides curated YAML configuration files for hundreds of models that install with a single command, while P2P federated inference distributes model shards across multiple machines for running models larger than any single node's memory. Multi-user API key authentication with quotas and role-based access enables team deployments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
FreeLLMAPI
FreeLLMAPI collapses the chaos of 29 free LLM providers — Google AI, Cerebras, Groq, Mistral, OpenRouter, GitHub Models, Cohere, Cloudflare Workers AI, NVIDIA NIM, HuggingFace, SiliconFlow, Reka, Z.ai, and more — into a single /v1 endpoint that speaks both OpenAI and Anthropic protocols. The smart router selects the best available model for each request, automatically fails over to the next provider when rate limits hit, and tracks per-key token consumption so you never exceed a free-tier cap. Keys are stored with AES-256-GCM encryption and clients authenticate using a single unified bearer token, never exposing upstream provider credentials to downstream applications. The catalog tracks 251 model families across 358 provider/model endpoints with approximately 4 billion tokens per month of aggregate free-tier capacity, auto-refreshing from a signed manifest at freellmapi.co twice daily without requiring git pulls. Beyond chat completions, the proxy handles embedding, image generation, and audio/TTS endpoints, plus structured outputs with JSON schema forwarding, JSON healing, and format-ignore failover. An integrated MCP server at /mcp provides gateway introspection for coding agents, while the self-hosted OpenAPI reference at /v1/docs documents every route. Compatible with OpenAI SDKs, LangChain, LlamaIndex, Continue, Claude Code, and Hermes — just change base_url. Deploy via Docker, npm, or build from source. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Forge
Forge intercepts failing LLM tool calls and fixes them before they derail your agent workflow, applying rescue parsing, retry nudges, response validation, and step enforcement between your AI clients and local model backends. The proxy server mode drops in as a transparent intermediary speaking both the OpenAI chat-completions API and the Anthropic Messages API, so tools like Aider, Claude Code, Continue, and opencode connect through it without configuration changes. Under the hood, the WorkflowRunner provides a complete agentic loop manager with system prompt injection, tool execution, context compaction with configurable thresholds, and VRAM budgeting for consumer GPUs with 12-32 GB. SlotWorker enables priority-queued access to shared inference slots with automatic preemption for multi-agent architectures. The guardrails middleware exposes a two-method check-and-record API that wraps into any existing orchestration loop, providing malformed tool-call rescue parsing, retry nudge generation, required step enforcement, and prerequisite ordering without taking over execution control. Backend adapters support generic OpenAI-compatible endpoints, Ollama, llama-server, Llamafile, vLLM, and Anthropic with automatic model discovery and health checking. Architecture Decision Records document every design choice. Launched February 2026, already at 2,200+ GitHub stars. MIT licensed.
OwnPilot
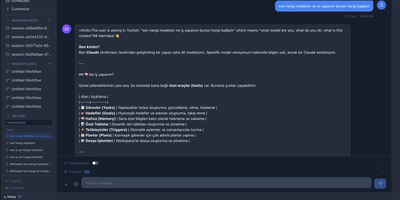
Bridging local hardware and cloud intelligence, OwnPilot orchestrates autonomous multi-channel agent swarms and visual workflow pipelines while keeping sensitive personal records strictly on private infrastructure. Users can trigger autonomous task runs that browse websites using headless browser automation, extract data tables, and summarize research directly into encrypted markdown notebooks. The built-in workflow canvas allows individuals to construct branching automation sequences combining large language models, conditional logic gates, iterative data loops, and human-in-the-loop approvals. Users delegate calendar scheduling, task tracking, expense budgeting, and contact lookups through conversational chats conducted over web portals, Telegram bots, or WhatsApp numbers. Operators can dispatch coding agents to inspect local repositories, execute shell commands in sandboxed environments, and stream live terminal logs as automated patches develop. The platform also enables home automation enthusiasts to monitor MQTT telemetric feeds from microcontrollers, queue device commands, and receive instant alert notifications when sensor thresholds trigger. Advanced security layers inspect all incoming prompts for personal data patterns, enforce strict permission boundaries across file directories, and generate tamper-evident audit logs for every autonomous tool call. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.