Tracely
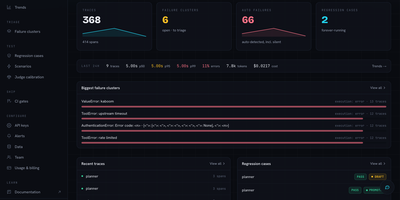
When an AI agent breaks in production, Tracely freezes that exact run into a replayable regression test and blocks the pull request that would ship the bug again. Span soup hides the failure. OTLP/HTTP traces group into conversation threads, and a waterfall marks the failing span in red with its input and output. Nobody knows if an answer was good. Evaluators sit as columns on the trace table, mixing model-free checks with LLM judges at conversation, run, or span level. Thirty-one broken runs, one issue. Clustering turns them into a single counted issue and can suggest the evaluator that would have caught it. A fix nobody can prove. One click promotes a failing trace into a hermetic case with recorded fixtures and a fail-to-pass contract, and scenarios send a red-team model after an adversarial goal. Model bills on every CI run. The suite replays offline with no API keys and no model spend, and tracely gate posts a commit status, comments on the pull request, and blocks regressions. No warning when it breaks again. Alert flows drawn on a canvas react to failed gates, broken conversations, unseen failure modes, or rising failure rates by messaging Slack, sending email, calling a webhook, or prompting an LLM. Coding agents can read traces and write evaluators through an MCP endpoint. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
PanWatch
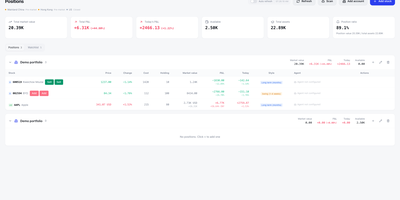
PanWatch's three scheduled AI agents plan the trading day before the bell, watch the session, and review it after the close for your China A-share, Hong Kong, and U.S. holdings. Day one begins with the portfolio: several brokerage accounts, holdings and profit and loss, and search for stocks or listed ETFs by code or name. The pre-market agent folds overnight moves, news, and technical structure into that plan and skips exchange holidays. Through the session, the intraday monitor watches for unusual moves and technical signals. Price alerts combine price, percentage change, turnover, and volume ratio with AND/OR logic, cooldowns, and expiry times. Each rule picks its own channel from Telegram, WeCom, DingTalk, Feishu, Bark, or a webhook. Spot something odd? The brain icon next to a holding starts TradingAgents, where four analyst roles feed a bull and bear debate, a risk review, and a portfolio-manager decision, with the reasoning trail in the app and your notifications. The opportunities screen ranks AI-scored ideas with entry levels and targets, and paper trading simulates signal-based entries and exits and tracks equity and performance. At day's end, the daily report reviews the session and prepares the next trading day's plan. OpenAI-compatible providers or local Ollama models power the analysis, and the PWA installs on a phone in English or Simplified Chinese. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Octopus
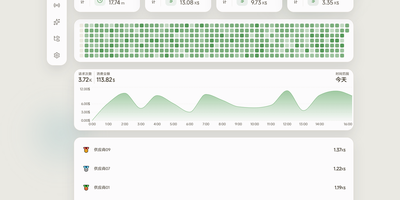
Juggling separate API keys, incompatible payload schemas, and unpredictable rate limits across OpenAI, Anthropic, and Google Gemini slows down every AI workflow, and Octopus solves it by consolidating all your upstream model providers into one self-hosted API gateway. Point Claude Code, OpenAI Codex CLI, or any SDK client at a single gateway URL and translate requests transparently between OpenAI Chat Completions, OpenAI Responses, Anthropic Messages, and Google Gemini endpoints without modifying client code. Group multiple provider channels under a unified model alias so your coding agents automatically fail over to backup providers and shield active tasks from upstream HTTP errors or rate limits. Watch live end-to-end request routing on the interactive topology canvas as prompts flow from client applications through model groups to specific upstream channels. Synchronize available model catalogs directly from connected providers and pull up-to-date token pricing from models.dev, or define custom per-million input, output, and cache-read rates for private deployments. Inspect detailed request logs, monitor token consumption trends, and audit daily API spend across every channel from the web dashboard. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.