Azimutt
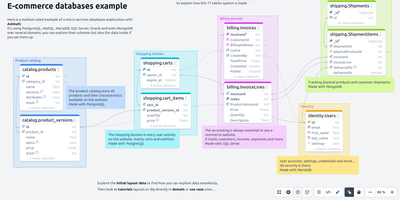
Inheriting a sprawling database with hundreds of undocumented tables usually means weeks of guesswork, unless you open it in Azimutt to visually map schemas, trace relationships, and inspect live rows in one workspace. Instead of dumping every table onto a cluttered canvas that crashes your browser, the visual explorer starts clean so you can search across entity names, column types, and SQL comments to reveal only the tables relevant to your investigation. Clicking foreign-key or primary-key indicators expands incoming and outgoing relations step by step, while the graph path-finder automatically calculates the shortest join route between any two distant entities. When debugging production issues or answering support tickets, you can query live records across PostgreSQL, MySQL, MariaDB, SQL Server, Oracle, SQLite, MongoDB, Couchbase, Snowflake, and BigQuery, then click directly through foreign keys in the result rows to follow data lineage visually. Architects and developers also design new schemas at typing speed using Azimutt Markup Language (AML), attach contextual markdown notes, tags, and memos to saved layouts for team onboarding, and run automated schema analysis that flags missing primary keys, implicit foreign keys, inconsistent column types, and oversized tables. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Marmot
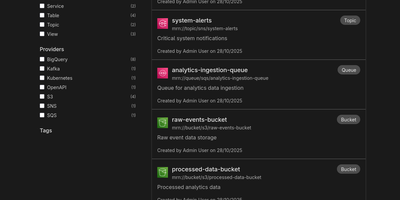
Cataloging tables, topics, queues, and APIs across fragmented data stacks usually demands heavyweight enterprise governance suites, yet Marmot delivers fast full-text asset discovery and AI-ready metadata context in a single self-hosted service. Data engineering and platform teams use its 71 official plugins to automatically ingest schemas, run histories, and dependencies from Apache Kafka, Airflow, Iceberg, Superset, PostgreSQL, BigQuery, and AsyncAPI specifications without moving raw table rows or message payloads. From the web interface, analysts can run structured boolean queries, filter assets by custom tags or PII classifications, and inspect column-level schemas in seconds. Interactive upstream and downstream lineage graphs let engineers trace how events flow from message brokers into warehouse tables and BI dashboards so they can assess what breaks before renaming a column or deprecating an endpoint. Shared business glossaries, bidirectional ownership assignments, and curated data product bundles ensure every department speaks the same language and knows exactly which team maintains each pipeline. Through the built-in Model Context Protocol server, AI assistants in Cursor, Claude Desktop, and LibreChat can invoke tools like discover_data, find_ownership, and lookup_term to answer natural-language questions against live catalog metadata instead of guessing. Platform administrators can also manage catalog resources declaratively using the REST API, CLI, Terraform provider, or Pulumi integration. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.