Lightpanda
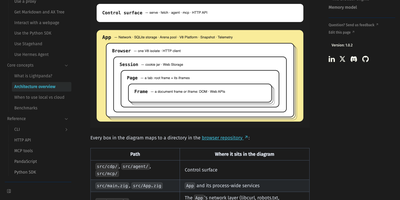
Lightpanda is a headless browser built for AI agents and automation that loads and runs web pages without ever drawing them, so crawling, scraping, and agent browsing finish far faster and lighter than in Chrome. You drive it with the tooling you already have: Puppeteer, Playwright, and Chromedp connect over the Chrome DevTools Protocol, Selenium works over WebDriver BiDi, and existing Chrome automation scripts keep running against the new endpoint. Scripts can execute JavaScript on real pages, wait for network activity, read and mutate the DOM, submit forms, and pull structured data out of dynamic sites that plain HTTP clients cannot see. An MCP server mode hands the browser to AI applications as a callable tool, so a model can open pages, follow links, and read content in the middle of an agent workflow. The built-in agent accepts plain-language browsing tasks and can export what it did as PandaScript, a replayable JavaScript file that runs later with no model call at runtime. A fetch command loads one or more URLs and prints the result as HTML or Markdown, which turns page extraction into a single shell step inside data pipelines. In the project's published crawl benchmark it processed pages roughly nine times faster than headless Chrome at a fraction of the memory, so one server can hold many more concurrent browsing sessions. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
CRW
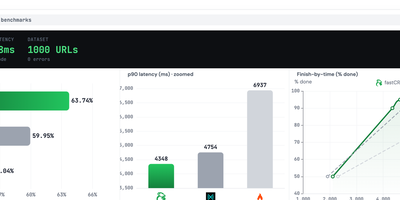
CRW gives your apps and AI agents a private web data API that scrapes pages, crawls sites, maps links, and searches the web without sending every request to a hosted scraping service. Post a URL to the scrape endpoint and receive clean Markdown, HTML, screenshots, links, or structured JSON shaped by a schema you supply. Start a crawl when a whole section matters, then poll for progress while CRW walks pages asynchronously and returns the collected content in one job. Use map first to discover the URLs on a site before spending effort extracting pages you do not need. Connect agent tools through the MCP endpoint so assistants can search, scrape, and crawl from the same self-hosted service your applications call. Add browser rendering when JavaScript-heavy pages hide content from a plain HTTP fetch, and keep simpler pages on the fast lightweight path. Protect a public deployment with Bearer token authentication, your own reverse proxy, logging, and rate limits, or keep the service inside a private network for internal tools. Run one Docker container for the core API, or use the Compose stack when you want bundled search and rendering sidecars beside it. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.