Stars
Forks
Watchers
Developer links
CRW
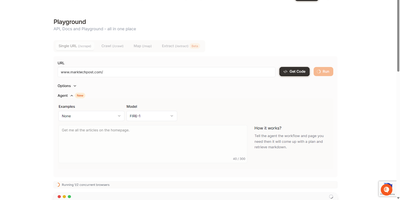
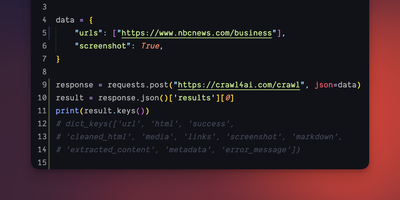
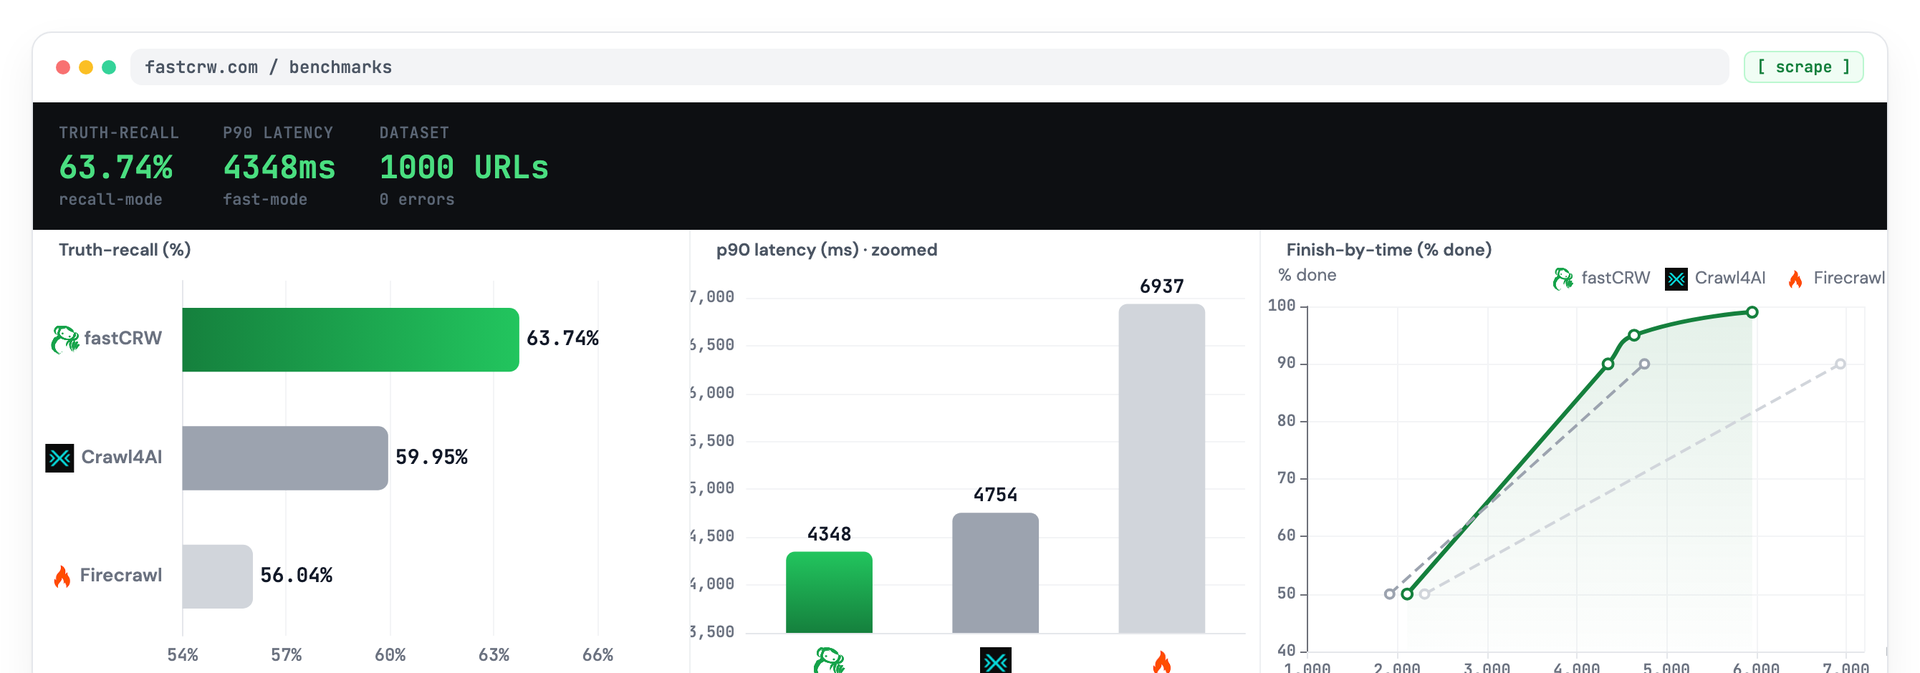
CRW gives your apps and AI agents a private web data API that scrapes pages, crawls sites, maps links, and searches the web without sending every request to a hosted scraping service. Post a URL to the scrape endpoint and receive clean Markdown, HTML, screenshots, links, or structured JSON shaped by a schema you supply. Start a crawl when a whole section matters, then poll for progress while CRW walks pages asynchronously and returns the collected content in one job. Use map first to discover the URLs on a site before spending effort extracting pages you do not need. Connect agent tools through the MCP endpoint so assistants can search, scrape, and crawl from the same self-hosted service your applications call. Add browser rendering when JavaScript-heavy pages hide content from a plain HTTP fetch, and keep simpler pages on the fast lightweight path. Protect a public deployment with Bearer token authentication, your own reverse proxy, logging, and rate limits, or keep the service inside a private network for internal tools. Run one Docker container for the core API, or use the Compose stack when you want bundled search and rendering sidecars beside it. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Benefits
- Private Web Data API
- Keep scraping, crawling, mapping, and search requests inside infrastructure you control, with optional Bearer authentication, private-network placement, reverse proxy rules, logging, and rate limits for safer public exposure.
- Clean Content For Agents
- Turn messy web pages into Markdown, HTML, links, screenshots, or schema-shaped JSON that applications, retrieval pipelines, and AI agents can consume without building brittle parsers for every site.
- Fast Lightweight Core Service
- Run the core API as one Docker container or single binary on port 3000, then add rendering or search sidecars only when a workload actually needs those heavier capabilities.
- Firecrawl-Compatible Migration Path
- Use familiar scrape and crawl concepts through native v1 endpoints and compatibility routes, making it easier to move existing web extraction workflows away from metered hosted scraping services.
Features
- Scrape Endpoint
- POST a single URL to /v1/scrape and request Markdown, HTML, screenshots, links, or structured JSON extraction using a caller-supplied schema for predictable downstream processing.
- Async Crawling
- Start multi-page crawls through /v1/crawl, poll job status by ID, cancel active work, and collect completed pages without blocking your application on long-running site walks.
- Map And Search
- Discover URLs with /v1/map before extraction, and use /v1/search with the bundled search backend to find relevant pages when target addresses are not known yet.
- MCP Tool Access
- Expose search, scrape, and crawl capabilities to MCP-compatible assistants so agents can gather live web context through the same self-hosted service your software already calls.
- Optional Browser Rendering
- Add LightPanda or Chrome-backed rendering for JavaScript-heavy targets while keeping ordinary pages on the faster HTTP path, with compose profiles for heavier production workloads.