ScribeCrate
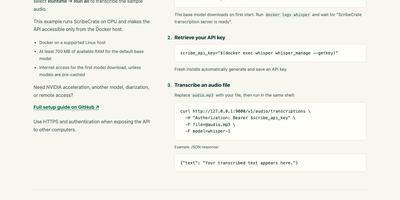
ScribeCrate is a self-hosted speech-to-text API that turns recordings into transcripts, subtitles, and English translations on your own server. It speaks the OpenAI Whisper API fluently: point any compatible client at your server's address, swap in your API key, and uploads come back as text. Ask for plain text, JSON with timestamps, or ready-to-publish SRT and WebVTT subtitle files, and for long recordings the segments can stream back over SSE as they are decoded. Turn on speaker diarization and every segment is labeled with who is speaking, which makes interview and meeting transcripts readable at a glance. Choose the model that fits the job, from tiny for quick drafts to large-v3 for maximum accuracy, and run it on a modest CPU, a Raspberry Pi class ARM board, or an NVIDIA GPU. Almost any recording works: MP3, M4A, WAV, WebM, OGG, and FLAC are all accepted, and with models cached in advance the server keeps transcribing with no internet connection at all. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
MeetDo
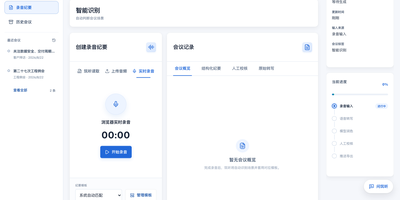
The meeting ends and, instead of a raw transcript, you get minutes you can file: MeetDo is an open-source meeting-to-action system that hosts the meeting, captions it locally, and finishes the record for you. Start a browser meeting with video, screen sharing, and chat, and watch captions stream from a speech model running on the same infrastructure, so no audio is sent to a cloud note-taker. When the call ends, the transcript becomes structured minutes: summary, agenda flow, conclusions, and action items with owners, instead of a wall of raw text. Five meeting types, from management reviews and project weeklies to interviews and customer calls, shape the record, and custom templates export to DOCX or PDF with your original layout preserved. Domain vocabulary is corrected after recognition, so names, units, and industry terms survive transcription instead of turning into near-miss words. Past meetings stay searchable in a local history, and questions can be asked across them without anything leaving the machine. Editable transcripts let a human fix the record before it is filed, and the whole pipeline works offline after the first model download. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Speakr
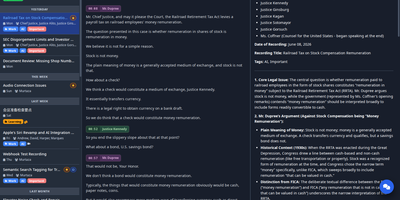
Speakr transforms audio recordings into organized, searchable, AI-enhanced notes with speaker recognition that identifies who said what across your entire recording library. The Python/Flask backend with Vue.js 3 and Tailwind CSS frontend deploys via Docker on port 8899, offering multiple transcription engines through auto-detected connectors: WhisperX for local processing with speaker diarization and voice embeddings, OpenAI Whisper and GPT-4o-transcribe, Mistral Voxtral for cloud diarization, AssemblyAI for multi-hour files, and any custom ASR webservice. Speaker voice profiles use embedding comparison to recognize individuals across different recordings automatically, while custom vocabulary biases the transcriber toward domain-specific jargon. The AI layer goes well beyond transcription: customizable summaries with per-recording, per-tag, and per-folder prompt templates; event extraction surfacing action items and calendar events; per-recording chat with streaming responses; and Inquire Mode for semantic search and natural-language queries across your entire library simultaneously. Smart tags execute custom AI prompts on transcripts for automatic categorization. The REST API with Swagger documentation supports signed webhooks integrating with n8n, Zapier, and Make. Auto-export pushes to Obsidian and Logseq, auto-processing watches directories, and the installable PWA provides mobile-first, offline-capable access with share-target support. 3,600+ stars since May 2025. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.

Vexa
Vexa is the only Apache 2.0 meeting bot API that self-hosts the complete transcription pipeline, from bot dispatch to Whisper speech-to-text to knowledge agents, with zero audio leaving your infrastructure. A single POST /bots request sends a transcription bot into any Google Meet, Microsoft Teams, or Zoom call, where it captures audio, runs speaker-attributed transcription through faster-whisper or any OpenAI-compatible endpoint, and streams results to your application via real-time WebSocket with sub-second latency. The built-in agent framework watches live transcripts and your accumulated workspace context, answering mid-call questions grounded in your own meeting history and wiki. An MCP server connects Vexa to Claude, Cursor, and other compatible AI tools, turning every captured meeting into queryable context for external agents. The Terminal, a bundled Next.js web workbench, lets you send bots, watch live transcripts, manage users and API tokens, and chat with your meeting archive from a browser. Docker Compose brings the full stack up on one Linux host in five minutes; the Helm chart scales to thousands of users on Kubernetes with a Pod-per-bot architecture and built-in RBAC. Recordings persist in MinIO or any S3-compatible store, transcripts in Postgres, with Redis handling queues and scheduling. Deploy on RepoCloud for a dedicated VPS with full root SSH access and browser console. Apache 2.0 licensed.
ScribeWizard
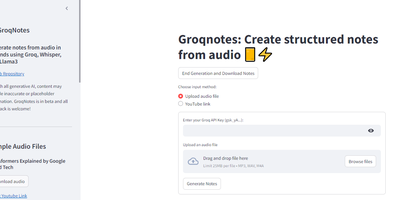
Audio lectures become structured, Markdown-formatted notes in about a minute with ScribeWizard (also known as GroqNotes). Upload an MP3, WAV, or M4A file - or paste a YouTube link - and the app runs a three-stage pipeline on Groq's LPU inference hardware: Whisper Large v3 transcribes the audio, a larger Llama model drafts a comprehensive outline of the material, and a faster Llama model fills each section with detailed content. This scaffolded prompting strategy is the core idea: the strong model handles structure where quality matters most, the fast model handles volume, and Groq's 1200+ tokens-per-second inference keeps the whole process near real time. Output renders as clean Markdown with support for tables and code blocks, and finished notes download as text or PDF. Model selection is configurable - swap in other Groq-hosted open models like Mixtral or Gemma to trade speed against quality or work around rate limits. Built as a single Streamlit app by Benjamin Klieger at Groq, it needs only a Groq API key to run, making it one of the simplest self-hosted AI tools to operate.