Stars
Forks
Watchers
Developer links
ScribeCrate
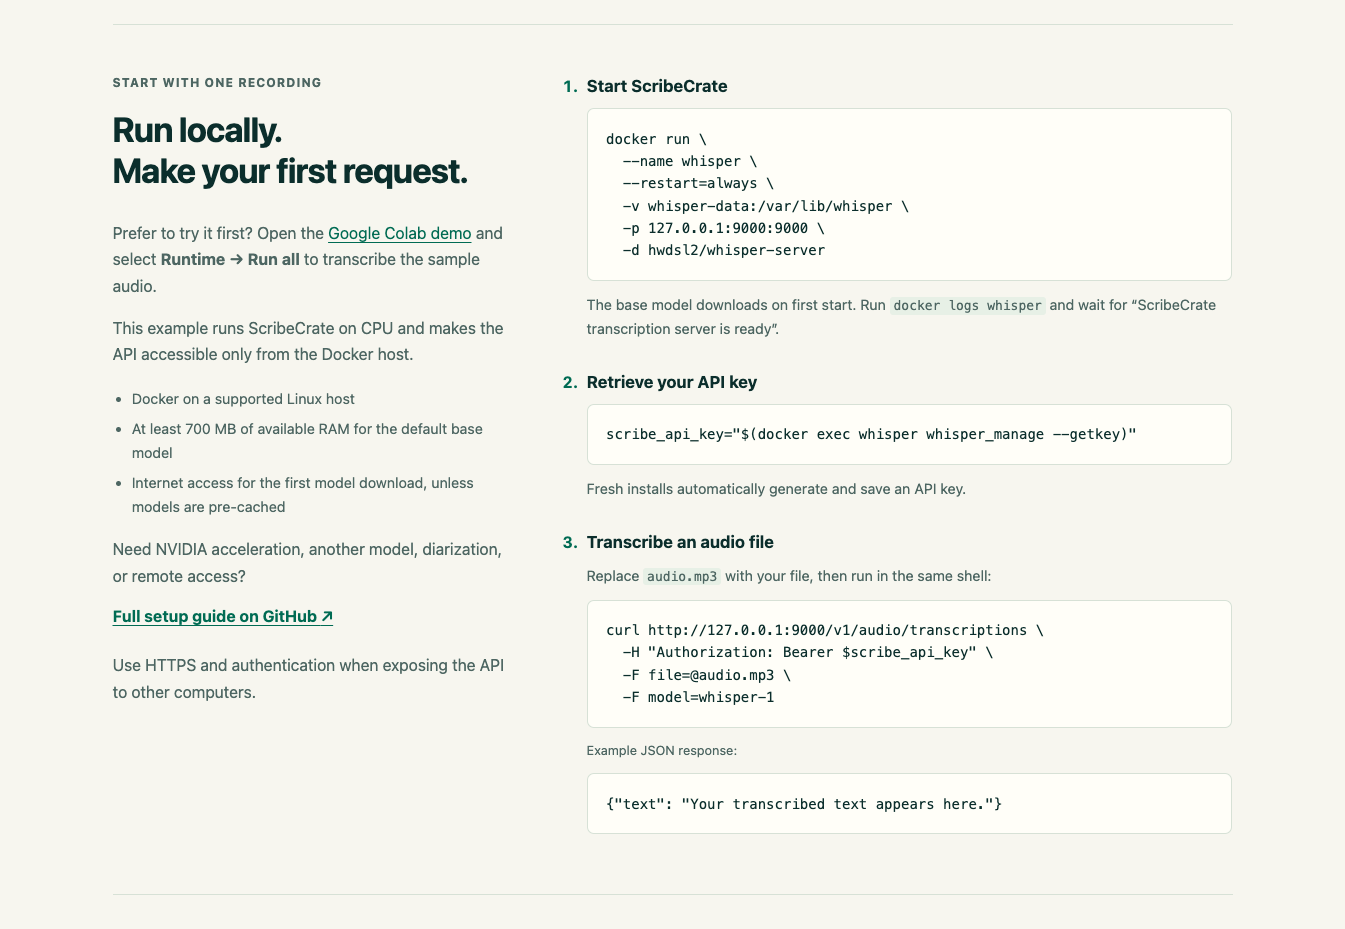
ScribeCrate is a self-hosted speech-to-text API that turns recordings into transcripts, subtitles, and English translations on your own server. It speaks the OpenAI Whisper API fluently: point any compatible client at your server's address, swap in your API key, and uploads come back as text. Ask for plain text, JSON with timestamps, or ready-to-publish SRT and WebVTT subtitle files, and for long recordings the segments can stream back over SSE as they are decoded. Turn on speaker diarization and every segment is labeled with who is speaking, which makes interview and meeting transcripts readable at a glance. Choose the model that fits the job, from tiny for quick drafts to large-v3 for maximum accuracy, and run it on a modest CPU, a Raspberry Pi class ARM board, or an NVIDIA GPU. Almost any recording works: MP3, M4A, WAV, WebM, OGG, and FLAC are all accepted, and with models cached in advance the server keeps transcribing with no internet connection at all. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- OpenAI-Compatible By Design
- Existing Whisper API clients and the OpenAI SDK work by changing only the base URL and key, so transcription slots into your stack in minutes.
- Audio Never Leaves Your Server
- Recordings are processed locally and models can be pre-cached for fully offline work, keeping interviews, meetings, and voice notes off third-party clouds.
- Subtitles Without Extra Tools
- One request returns plain text, timestamped JSON, SRT, or WebVTT, so podcasts and videos get publishable subtitles straight from the transcription call.
- Runs Anywhere From Pi To GPU
- Docker images cover amd64 and arm64 CPUs plus NVIDIA CUDA, so the same API runs on a home server today and a GPU box tomorrow.
Features
- Whisper Model Choice
- Load tiny, base, small, medium, large-v3, or large-v3-turbo models and switch between them, trading speed against accuracy for each workload.
- Speaker Diarization
- The sherpa-onnx extension with pyannote segmentation models labels who speaks in each segment, entirely on your hardware and verified against pinned hashes.
- SSE Streaming Results
- With stream=true, decoded segments arrive over Server-Sent Events as they are produced, so long files start yielding text within seconds.
- English Translation Endpoint
- The translations endpoint converts speech in dozens of languages into English text using multilingual Whisper models, through the same familiar API shape.
- Interactive API Documentation
- A built-in Swagger UI at the /docs path lets you explore endpoints and try requests from the browser before writing any client code.