Containarium
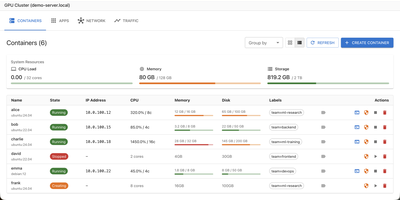
Containarium gives every AI agent a persistent Linux box of its own, reachable over SSH and driven through structured tools instead of a fragile terminal session. One command creates a named sandbox, syncs the SSH configuration, and wires the box into Claude Code, Codex, Gemini or Cursor through an MCP server that runs inside the container. From there the agent can execute shell commands, read and write files, install services, and expose a port on a public hostname with TLS terminated by a Caddy sentinel. Detached code runs keep working after a laptop sleeps or a connection drops, and the operator reattaches to the same byte-exact log later, checks status, or stops the run without losing output. An optional per-tenant eBPF egress policy limits outbound traffic per box, logs denied attempts for audit, and keeps provider API keys inside a model gateway rather than inside the agent environment. Boxes run on LXC or Kubernetes, keep state between agent sessions, support GPU passthrough for local model work, and stay separate from the host operating system and the cluster control plane. The dashboard presents containers, traffic, security events, audit records, GPU state and monitoring in one place. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Sandstorm
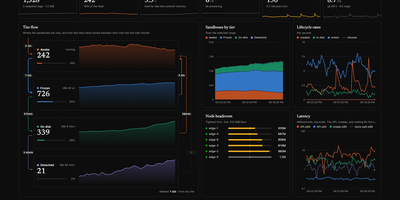
Agent code needs somewhere disposable to run, and Sandstorm turns one modest VPS into a fleet of thousands of isolated sandboxes that wake the moment work arrives. You create sandboxes through a plain HTTP API, starting from a registered template or forking a tagged snapshot, with per-sandbox memory ceilings, attached volumes, and egress rules set on each call. Every sandbox is a gVisor container with its own network namespace, so untrusted agent code runs away from your host and away from its neighbors. Idle sandboxes cool down through four tiers, from running hot, to frozen in place with a wake time near ten milliseconds, to checkpointed on disk and back in about a fifth of a second, so a small machine can hold far more sandboxes than it could ever keep running at once. A single binary acts as master, node, and web console: the master tracks desired state and places work across nodes, nodes behind NAT dial out to join the fleet, and a gateway on each node wakes a sleeping sandbox and forwards its traffic automatically. The built-in Hub pulls ready-made snapshot packs for warmed runtimes like Python with numpy or a pre-warmed Playwright browser, skipping cold starts entirely. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.

CubeSandbox
CubeSandbox gives every AI agent its own hardware-isolated MicroVM with a dedicated Linux kernel — not a shared-kernel container but a true KVM virtual machine — booting in under 60ms with less than 5MB of memory overhead per instance, enabling thousands of concurrent sandboxes on a single server via kernel sharing and Copy-on-Write memory. The Rust-built CubeProxy exposes an E2B SDK-compatible REST API on Axum, so existing E2B Cloud applications switch by changing one environment variable with zero client code changes. CubeMaster orchestrates cluster-level scheduling in Go while Cubelet manages node-local sandbox lifecycles including create, run, pause, resume, snapshot, and destroy operations. CubeVS, the eBPF-powered network layer, enforces per-sandbox isolation with LPM trie-based egress policies entirely in kernel space — no userspace context switches — while CubeEgress provides an L7 security proxy with per-domain, per-path, and per-method allowlists plus automatic credential injection that keeps secrets invisible to sandbox code. Hundred-millisecond-granularity snapshots enable checkpoint, rollback, and parallel fork from any saved state. The volume framework supports E2B-compatible pluggable storage with independent lifecycle and cross-sandbox sharing. Production deployment uses Terraform on Tencent Cloud or Helm charts on Kubernetes, K3s, or TKE, with full ARM64 support alongside x86_64 and AutoPause/AutoResume for cost optimization. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
sandboxd
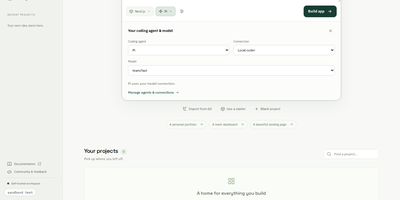
Describe an app in one sentence and sandboxd, a self-hosted AI app builder, has a coding agent build it in an isolated sandbox and hand back a live preview URL. Start from a blank prompt, a React, Next.js, Express, or FastAPI starter, or an imported public Git repo. Refine it in one persistent chat beside Preview, Code, Terminal, and Git tabs. Pick OpenCode, Pi, or Claude Code. Point OpenCode or Pi at local or remote OpenAI-compatible and Anthropic-compatible endpoints, LiteLLM gateways included. A proxy injects provider keys on the wire, so nothing secret lands in a sandbox. Did the agent get it wrong? Every task is checkpointed first, so one click reverts the turn. Snapshots, forks, and named versions keep known-good points to branch from. Edit files in the browser, review file-by-file diffs, commit, and push. Secrets are write-only and encrypted per app. Idle sandboxes sleep and wake on the next request. One modest server can host per-user previews, coding playgrounds, or an agent platform. The app library installs 80+ curated open-source apps, such as Ghost, n8n, Gitea, and Grafana, each in its own sandbox. Every console action is also a /v1 HTTP call with an OpenAPI spec. Upgrades back up the database, health-check the new version, and roll back on failure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Umpteenth
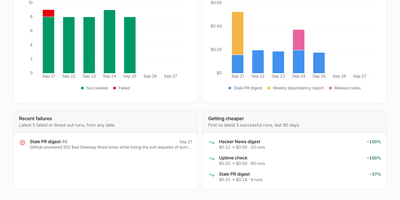
Recurring chores should get cheaper every time you run them, and Umpteenth is a self-hosted agent service built on that idea: describe a job once in plain language, and each run teaches it to need less help. A job starts on a schedule, a webhook call, the API, or the Run now button, and each run gets a fresh disposable container destroyed afterwards. The first run is an Explore run where the agent works out the steps; afterwards a reflection step reads the transcript and writes short learnings plus reusable toolkit scripts into a numbered playbook version. Later runs are Assisted, starting from those learnings, and after three successful assisted runs that take the same steps, the job graduates: reflection writes a main script, and scripted runs execute it alone, spending no model tokens unless a check asks for a judgment call. If a scripted check fails, the agent takes over in the same sandbox, finishes the job, and repairs the script. The job page charts cost per run dropping toward zero. Connect HTTP MCP servers such as GitHub or Slack; model keys and MCP credentials stay on the host and never enter the sandbox. Each job sets its own schedule, model, reach, and per run spending limit. Deploy with Docker Compose, or on Kubernetes with the Helm chart, where every sandbox is a pod. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.