StirlingPDF
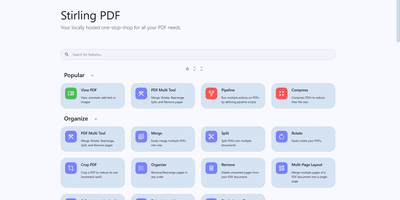
Adobe Acrobat and Smallpdf, answered by a self-hosted Java web application: Stirling PDF processes every file with its 60+ tools on your own server and deletes it after the task completes. Nothing is uploaded to a third party, which is the whole point for contracts, invoices, and medical records. The toolbox covers page operations (merge, split at page numbers or scanned dividers, rotate, reorder, crop, extract), conversion in both directions between PDF and Word, Excel, PowerPoint, images, HTML, and Markdown, OCR that turns scans into searchable PDFs via Tesseract/OCRmyPDF (including PDF/A archival conversion), and security tools for passwords, permissions, watermarks, signatures, and true UI-driven text redaction. A built-in viewer handles annotation, drawing, and text or image insertion, and V2 added stateful processing - upload once, chain multiple tools - plus undo/redo history. For automation, nearly every tool has a REST API endpoint, no-code pipelines combine operations into custom logic chains, and watched folders process files automatically. Enterprise deployments get SSO, user management, and audit logging; the interface ships in 40+ languages. With 84K+ GitHub stars it is the most popular PDF tool in self-hosting, replacing $20/month Acrobat subscriptions with flat infrastructure cost.
BentoPDF
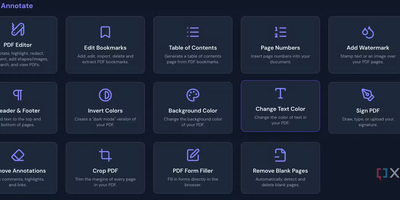
Merge, split, compress, convert, edit, annotate, redact, OCR, and sign PDFs - BentoPDF packs over 130 tools into a privacy-first toolkit that runs entirely in the browser through WebAssembly. Files are never uploaded - processing happens in browser memory on the user's machine and disappears when the tab closes, which makes the tool GDPR-clean by architecture and safe for financial, legal, and internal documents. The engine combines WASM builds of PyMuPDF, Ghostscript, and CoherentPDF; Tesseract handles OCR with searchable text-layer output; Office conversions cover Word, Excel, and PowerPoint; and digital signatures use X.509 certificates (PFX/PEM) with the private key staying on the client. Because there is no server-side processing, deployment is a static-file exercise: a single Docker container, or any static host. A dedicated self-hosted build strips the marketing pages while keeping every tool, and air-gapped deployments are first-class - an automated script bundles the WASM modules, OCR language data, and fonts for fully offline networks. No accounts, no limits, no watermarks; TypeScript and Vite under the hood.
Thesys
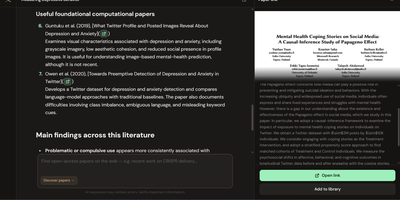
Thesys is a research workspace where you search academic papers, build your own library, and ask questions that answer with citations you can click straight onto the highlighted passage of the PDF. Discovery searches OpenAlex and arXiv in one pool, so a paper you find can be previewed and added to your library without leaving the workspace. Uploaded PDFs are ingested locally, and when you ask a question the answer cites its sources in the document, jumping the preview to the retrieved passage with either a full-passage or a tighter focused highlight. Reader mode opens a paper full-width so you can select any span of text and ask about that exact passage. Document summaries follow a consistent structure of problem statement, methodology, key findings, limitations, and metrics, with citations that still land on the source text. Figures and flowcharts are described during ingest, so questions and summaries can reference them too. When two papers disagree, Compare mode takes one claim and classifies each retrieved pair as corroboratory, contradictory, or neutral, with confidence shown in a side panel. Your bibliography exports as BibTeX, RIS, EndNote, or CSV for whatever reference manager you already use. Papers, embeddings, and chat history stay on your own disk the whole time. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.