GPUStack
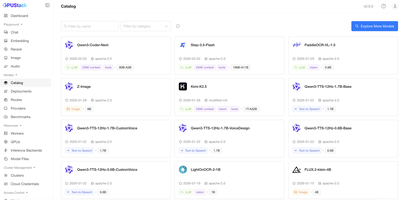
GPUStack is a control plane that turns a pile of GPU servers into a model-serving platform, where you pick a model from a catalog and the system decides which machine, engine, and settings run it. Deploy language, embedding, reranker, speech, and image models from the Catalog page, then watch each replica move from downloading to Running on the Deployments screen. A built-in Playground offers chat, side-by-side model comparison, embedding and rerank testing, audio, and image generation and editing, so a model gets judged before it is wired into an app. Add GPU workers with a generated Docker command, register a Kubernetes cluster, or provision cloud machines, and manage several clusters from one server. Create API keys for teammates, apply access control, and read token, GPU-hour, and storage usage by user, key, or model. Auto Tune benchmarking searches for the highest throughput that still meets your latency targets. GPU Instances hand out SSH-accessible machines for fine-tuning and interactive work. Single sign-on works through OIDC or SAML. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Xinference
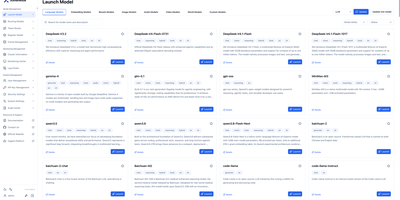
Xinference lets a team swap a hosted model API for models running on its own machines, with the same client code and a web console for managing them. The Launch Model page lists 300+ models across language, vision, embeddings, reranking, images, audio, video, and experimental world generation, and a Recommend configuration button fills in engine, size, format, and quantization for your hardware. Custom models, including traditional machine learning models, can be registered beside the built-in ones. Chat models can run on vLLM, SGLang, TRT-LLM, Transformers, llama.cpp, or MLX across CPUs, GPUs, and Apple Silicon. Workers and replicas can be added to serve one large model across several machines. Running Models shows each replica and a built-in chat window, and Performance Tests measure throughput and latency at several concurrency levels, with saved runs to compare. Endpoints speak the OpenAI and Anthropic protocols with streaming and tool calling where a model supports it. API keys, user management, and an audit center cover access control. The interface is available in five languages. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.