Categories
Self-Hosted AI Infrastructure Image Generation Model Serving OpenAI-Compatible API LLM Inference Embeddings Distributed InferenceStars
Forks
Watchers
Developer links
Xinference
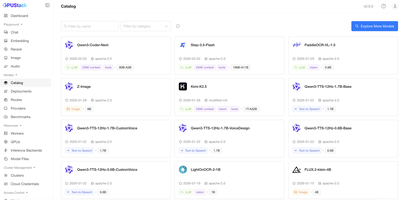
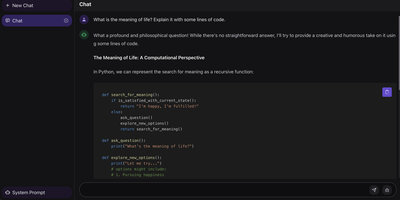
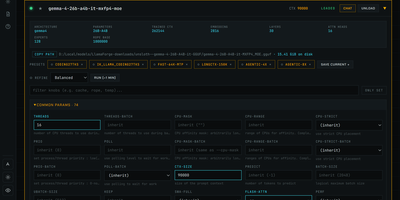
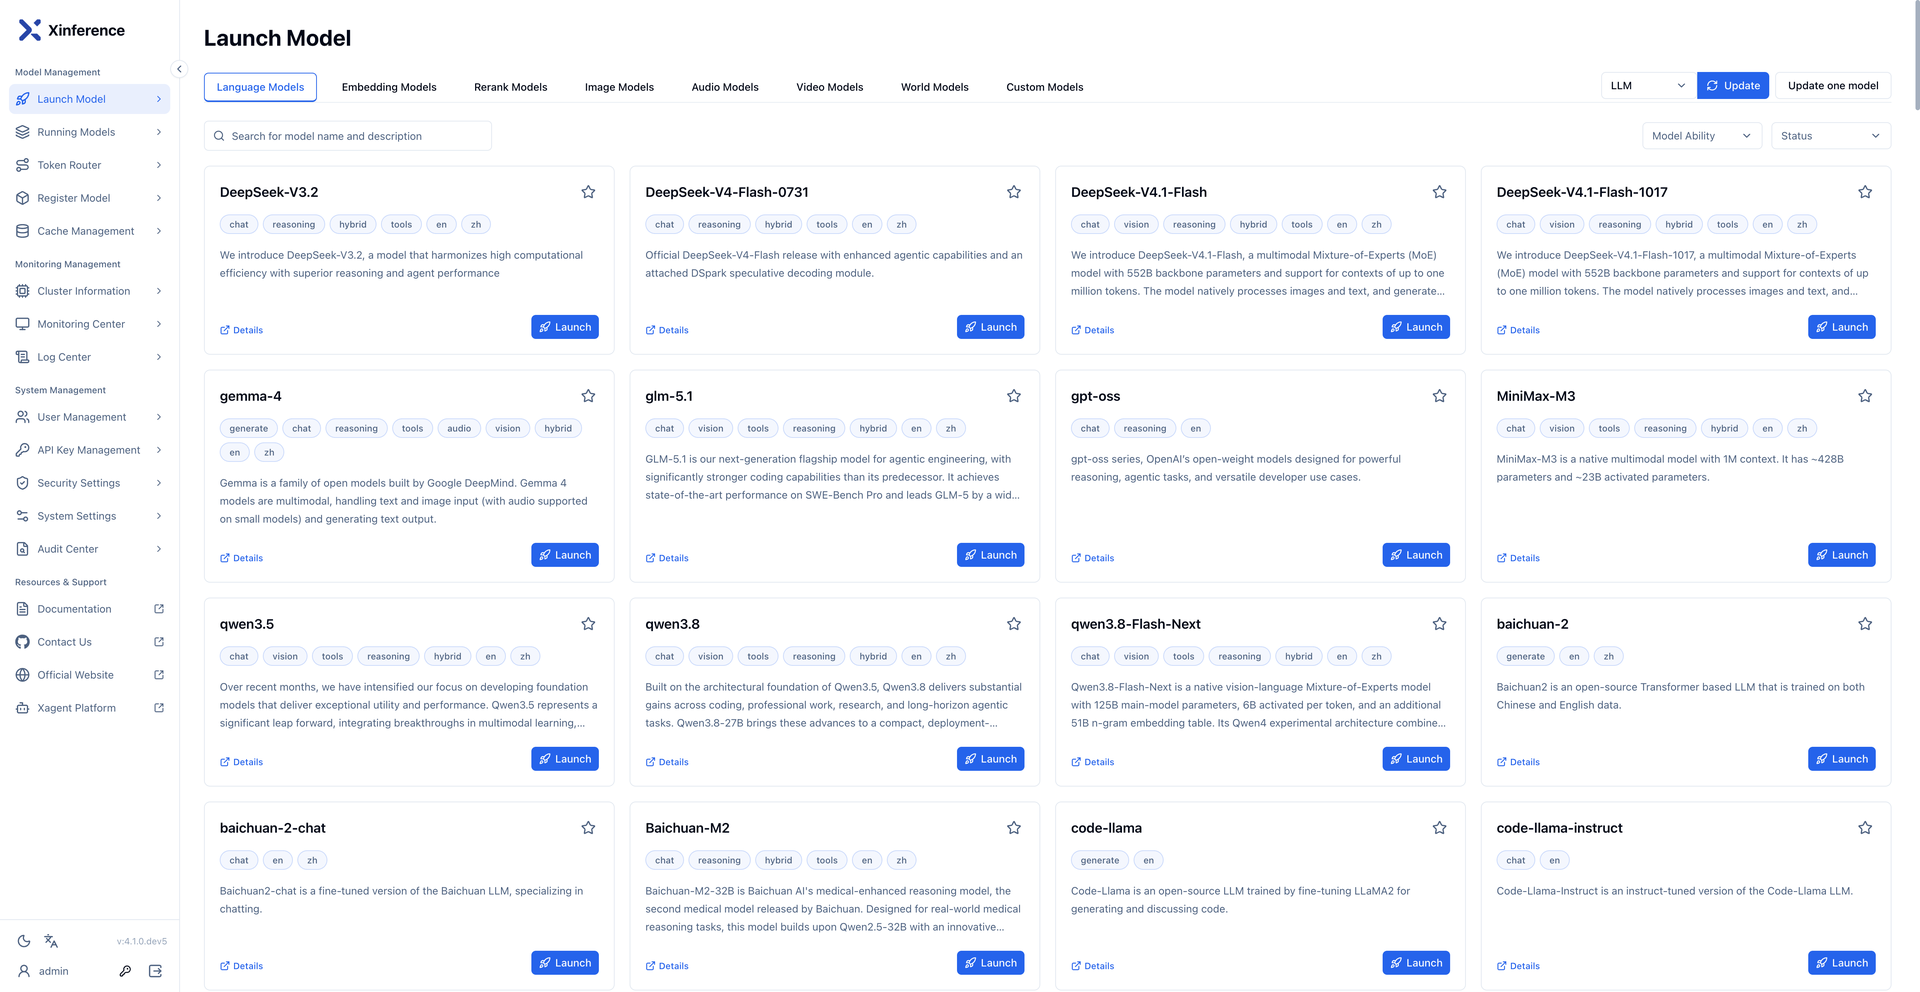
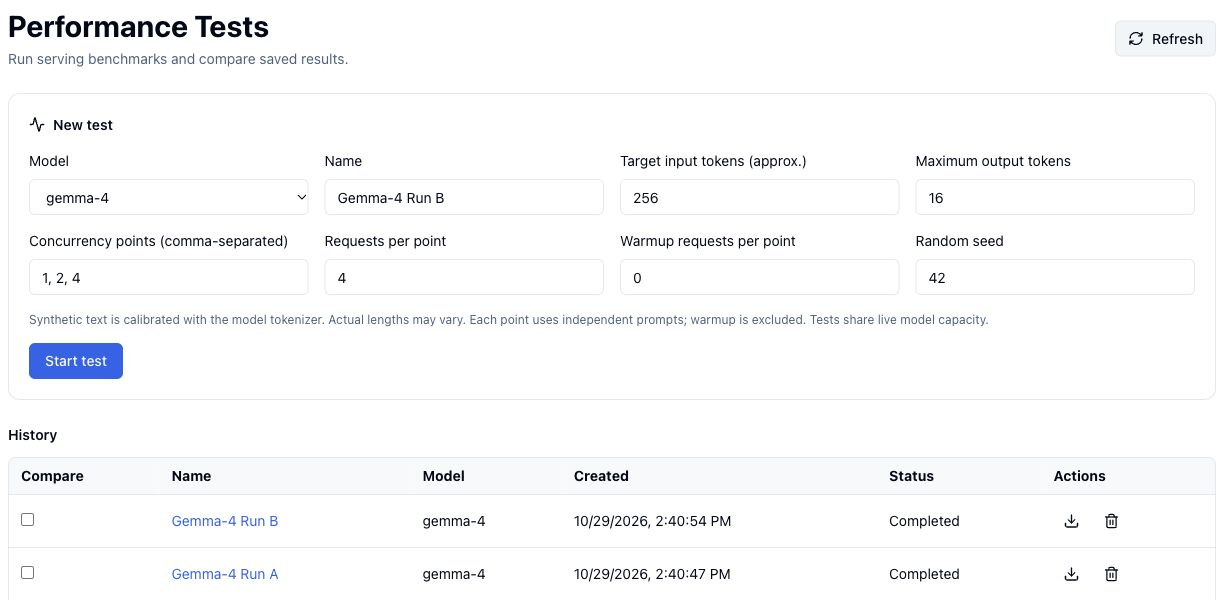
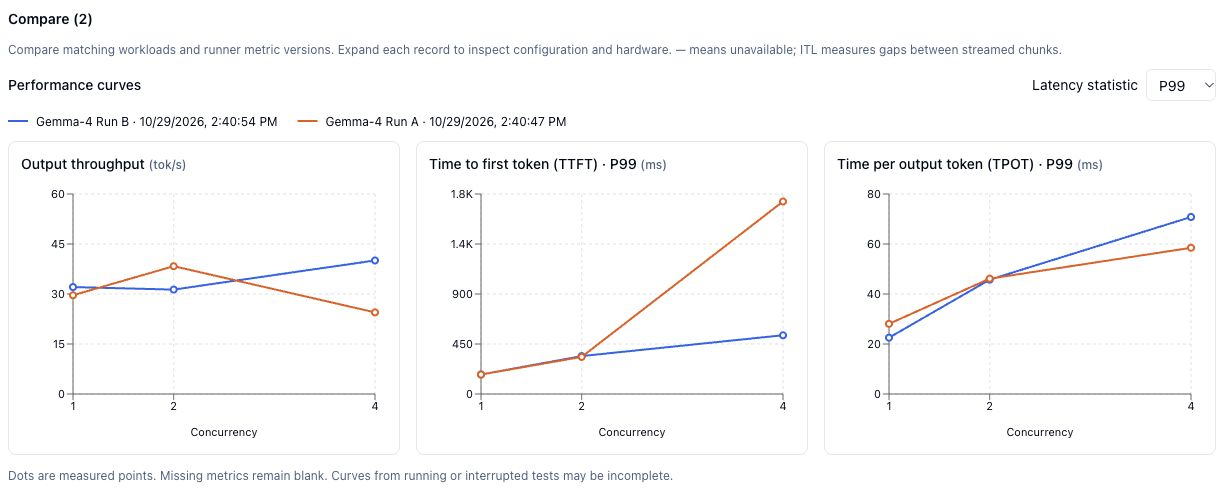
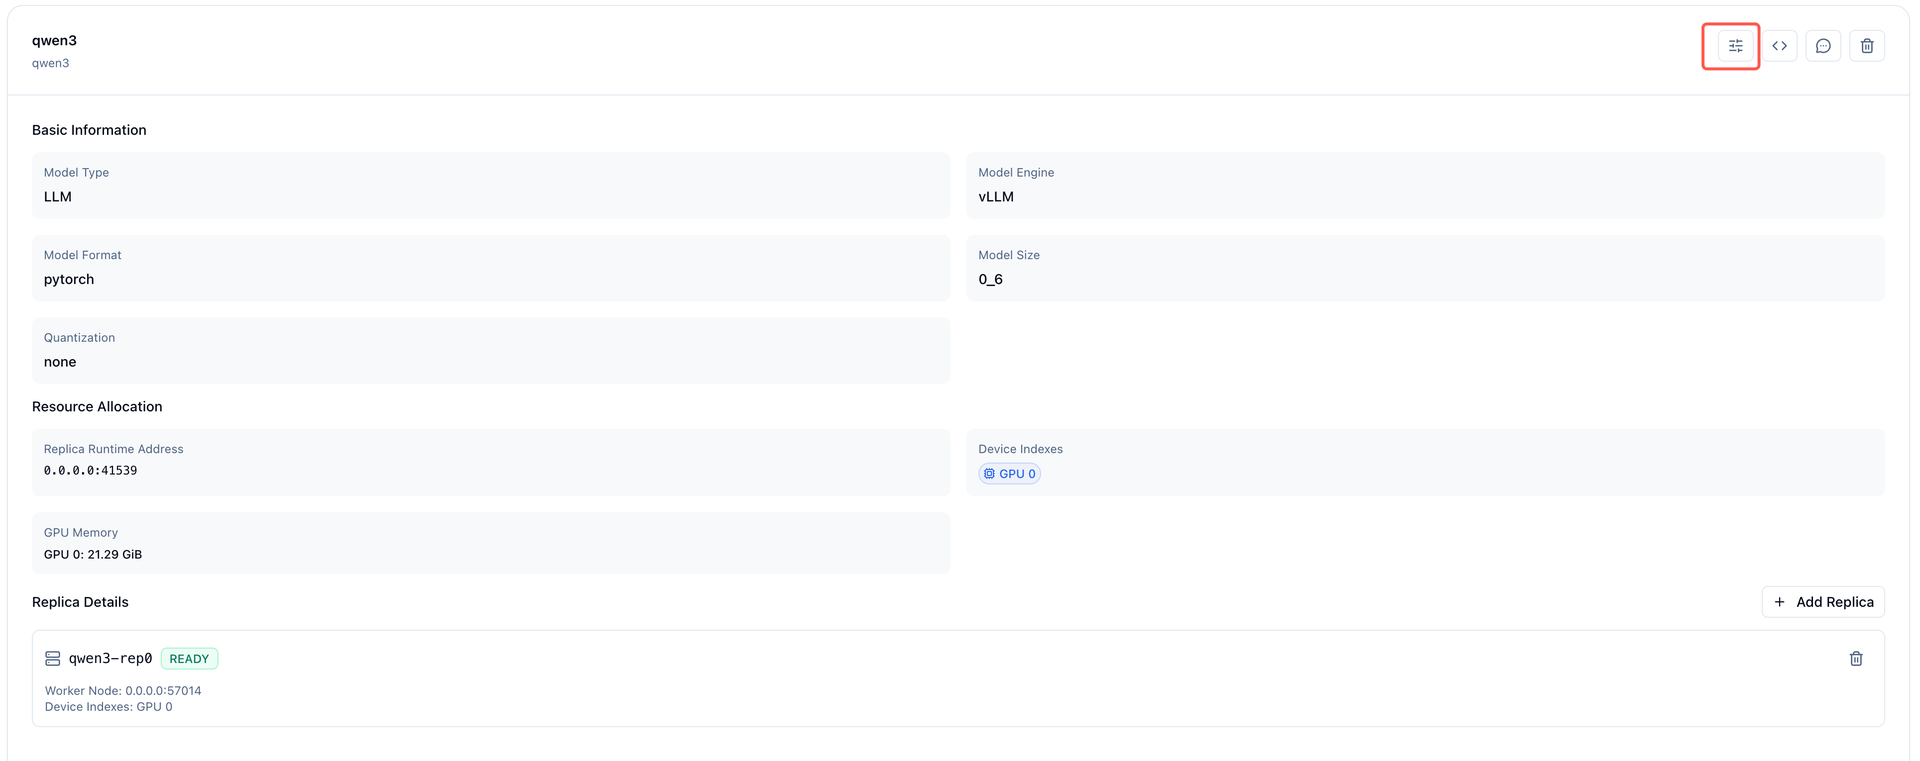
Xinference lets a team swap a hosted model API for models running on its own machines, with the same client code and a web console for managing them. The Launch Model page lists 300+ models across language, vision, embeddings, reranking, images, audio, video, and experimental world generation, and a Recommend configuration button fills in engine, size, format, and quantization for your hardware. Custom models, including traditional machine learning models, can be registered beside the built-in ones. Chat models can run on vLLM, SGLang, TRT-LLM, Transformers, llama.cpp, or MLX across CPUs, GPUs, and Apple Silicon. Workers and replicas can be added to serve one large model across several machines. Running Models shows each replica and a built-in chat window, and Performance Tests measure throughput and latency at several concurrency levels, with saved runs to compare. Endpoints speak the OpenAI and Anthropic protocols with streaming and tool calling where a model supports it. API keys, user management, and an audit center cover access control. The interface is available in five languages. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Benefits
- Replace Hosted APIs With Your Own
- Serve models behind OpenAI-compatible and Anthropic-compatible endpoints, so existing clients and SDKs keep working after you change the base URL and move inference onto hardware you control.
- Deploy Models With Recommended Settings
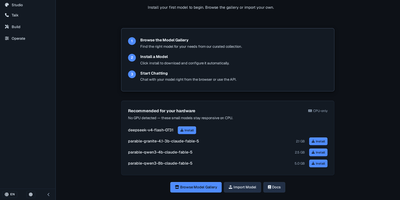
- Pick a model from the catalog and let Recommend configuration choose engine, format, size, and quantization for your hardware, then review the settings and deploy from the browser.
- Scale From Laptop To Cluster
- Start on a single machine, then add workers and replicas, or run one large model across several nodes, using the same console and API for every deployment.
- Measure Performance Before Launch
- Built-in performance tests sweep concurrency levels and chart throughput, time to first token, and time per output token, and saved runs can be compared side by side.
Features
- 300+ Built-In Models
- Language, vision, embedding, reranking, image, audio, video, and experimental world models, plus registration of your own custom models.
- Multiple Inference Engines
- Choose vLLM, SGLang, TRT-LLM, Transformers, llama.cpp, or MLX per deployment, on CPUs, GPUs, and Apple Silicon.
- Distributed Model Serving
- Add workers and replicas, run a large model across machines, and reload replicas one at a time during changes.
- Running Models Console
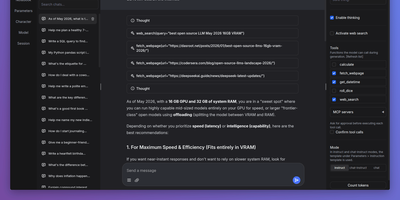
- Inspect each replica, its engine, device, and memory, open a chat window to test a prompt, or copy API code.
- Access And Audit Controls
- Create administrators and users, issue API keys, and review activity in an audit center, with optional single sign-on.
- Compatible APIs And SDK
- Call models through OpenAI and Anthropic style endpoints with streaming and tool calling, or use the CLI and Python client.