Categories
Self-Hosted AI Infrastructure MLOps LLM Serving Inference OpenAI-Compatible API GPU Management Model DeploymentStars
Forks
Watchers
Developer links
GPUStack
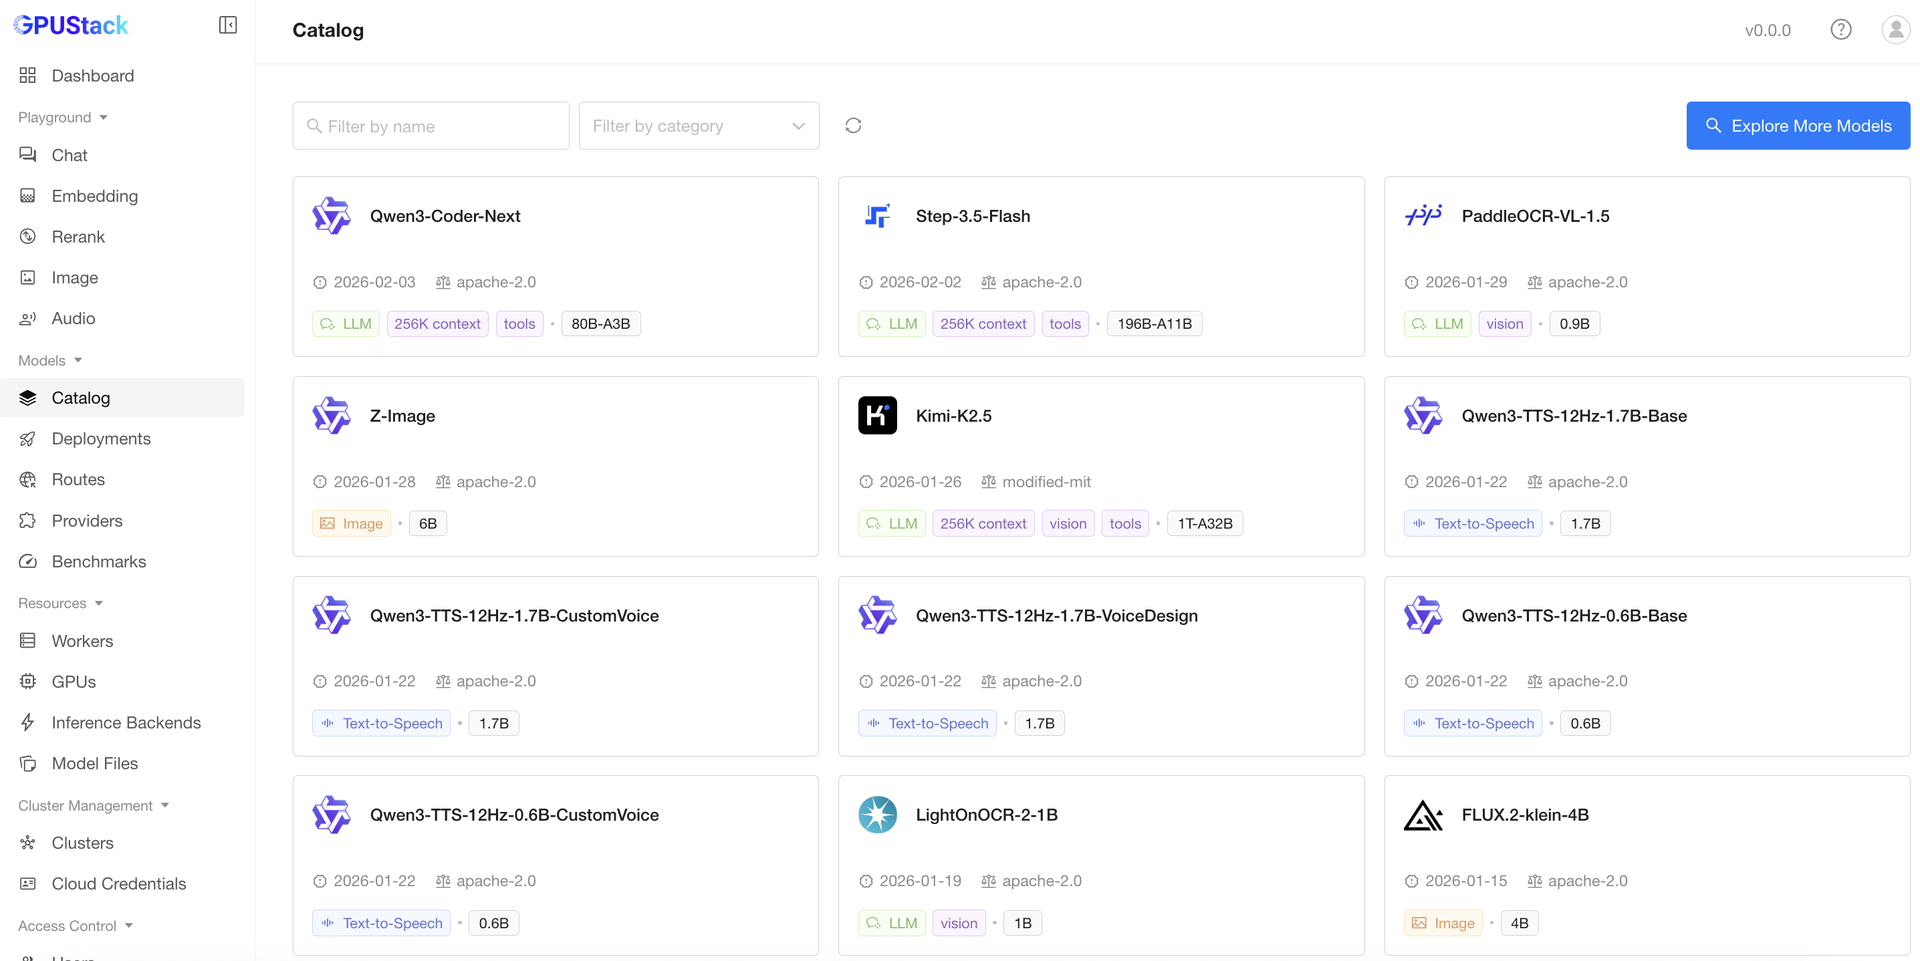
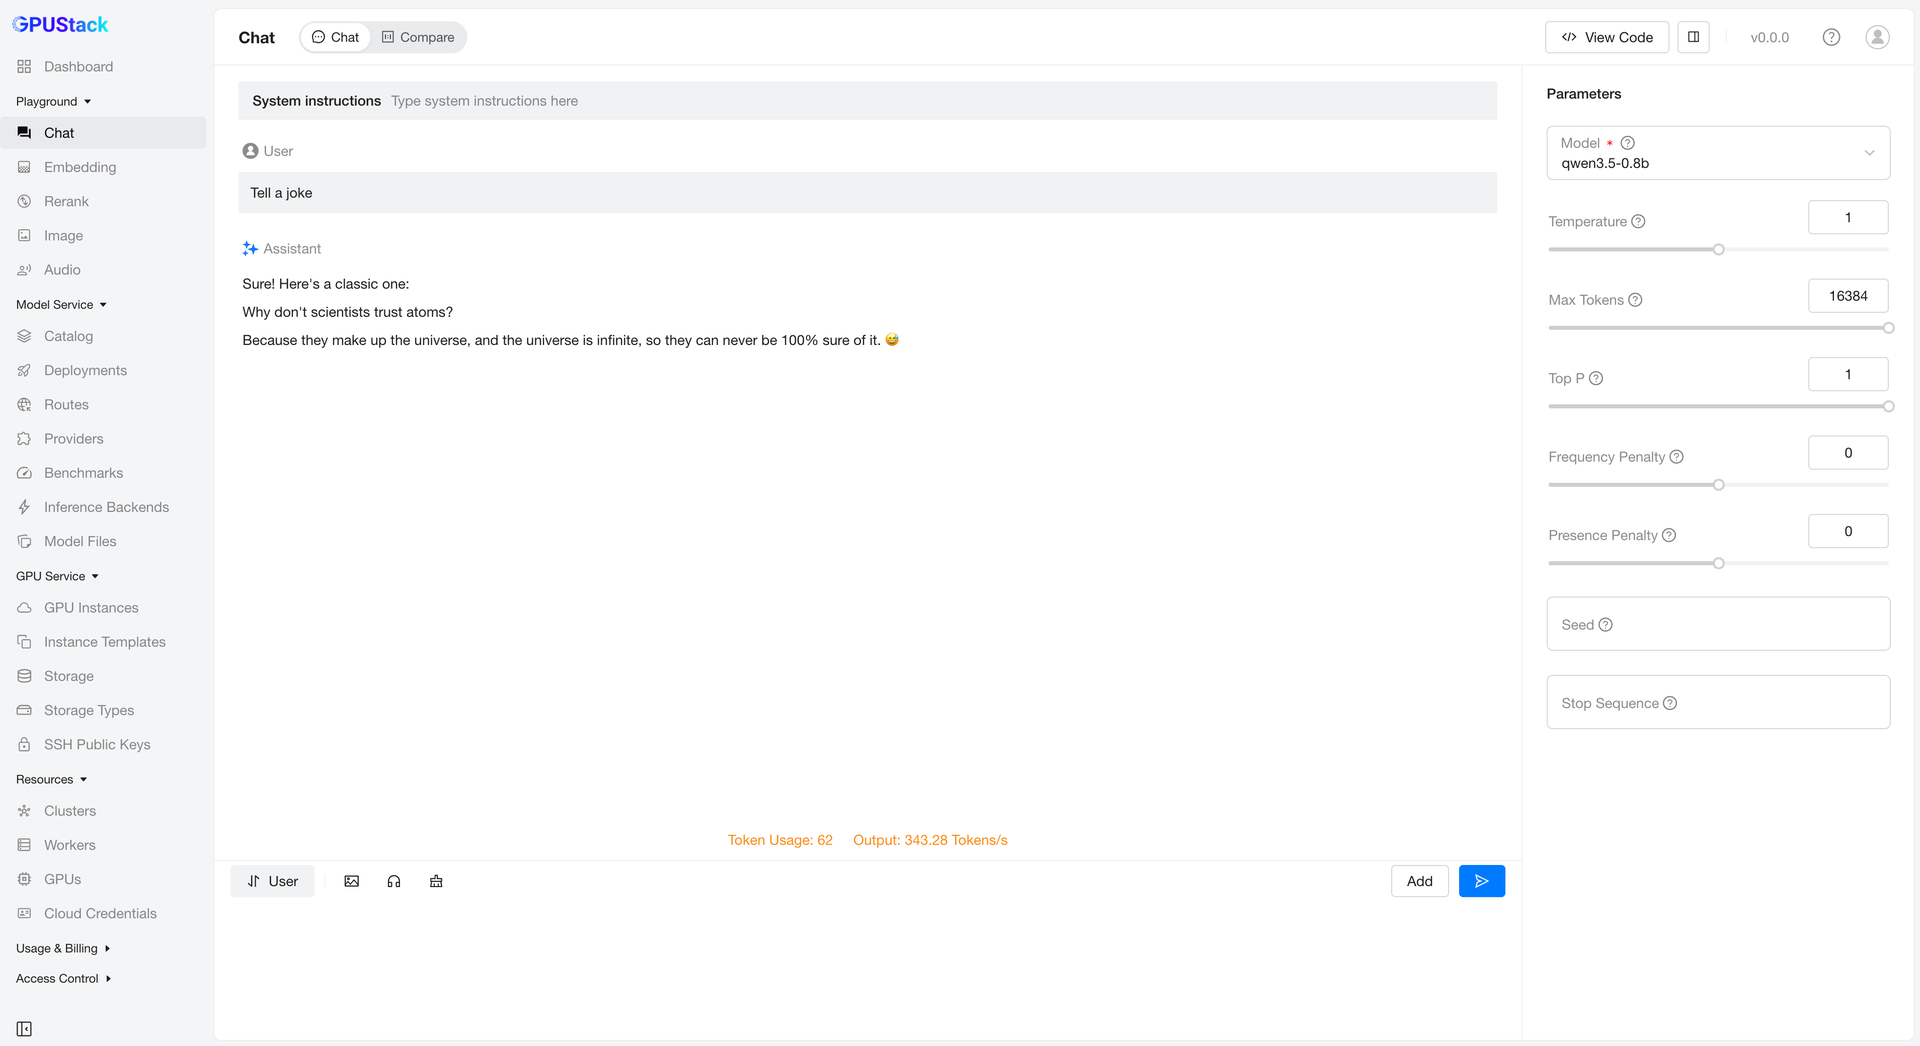
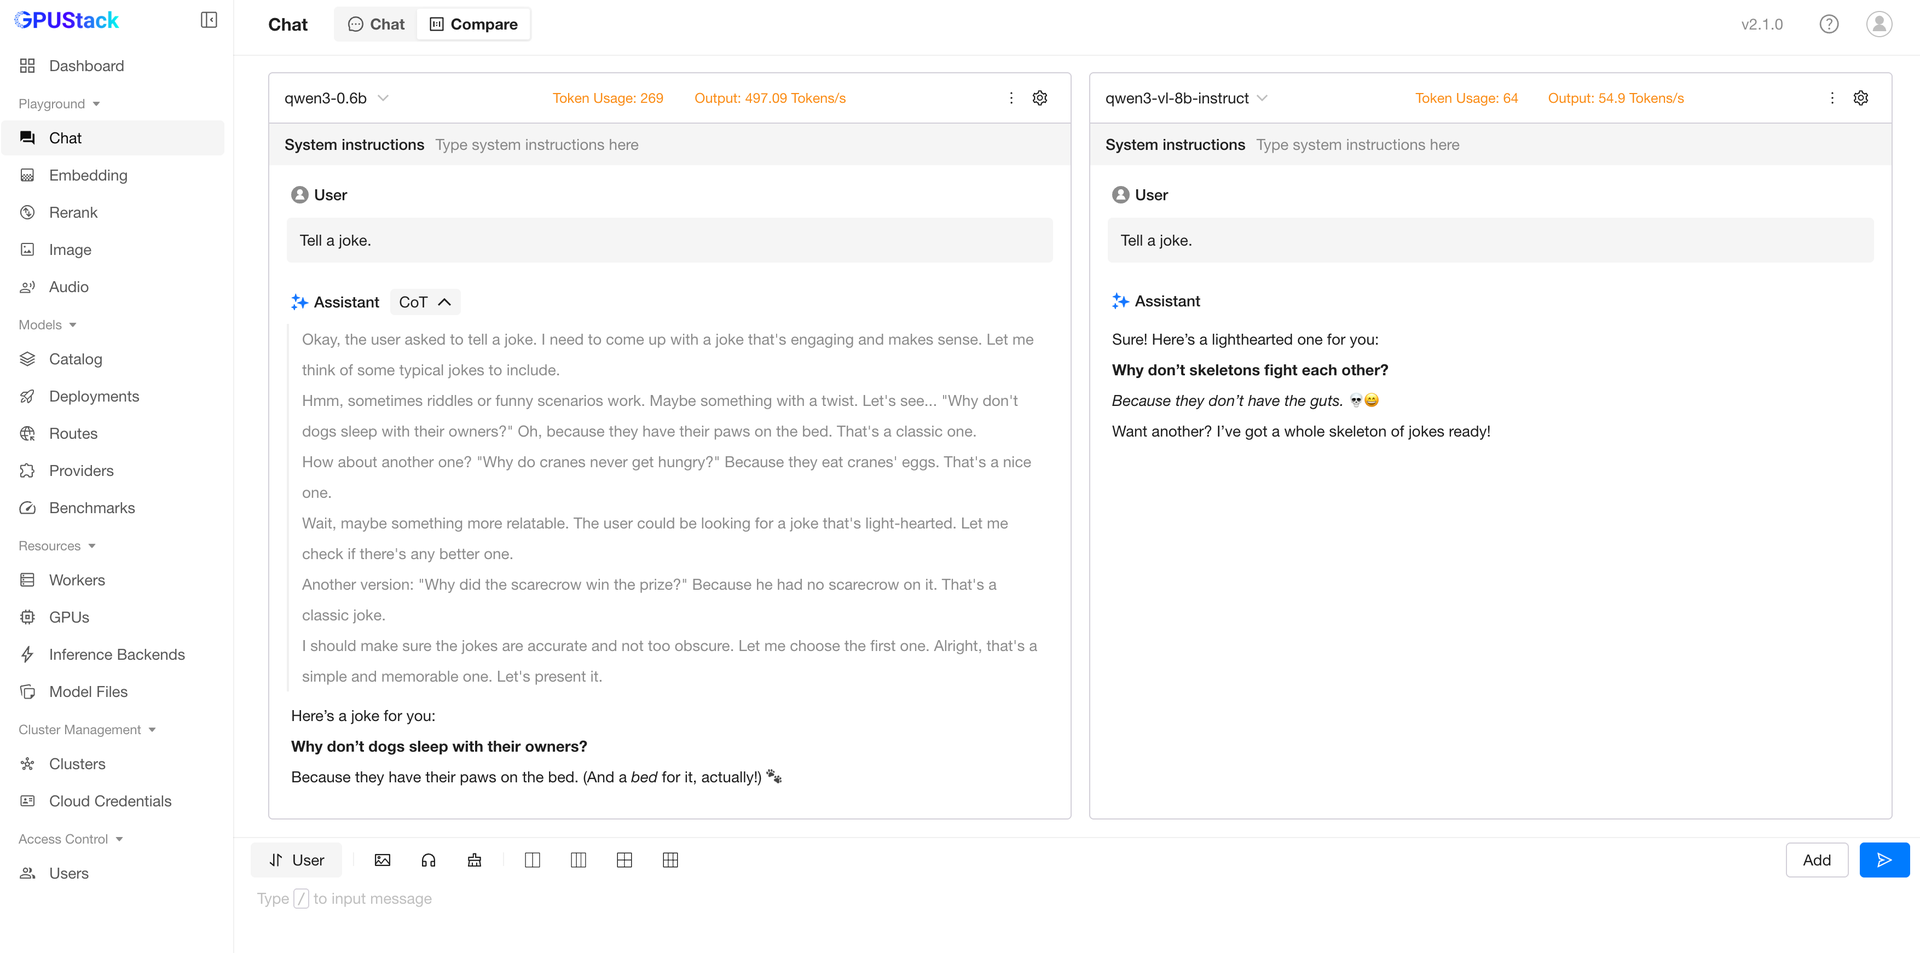
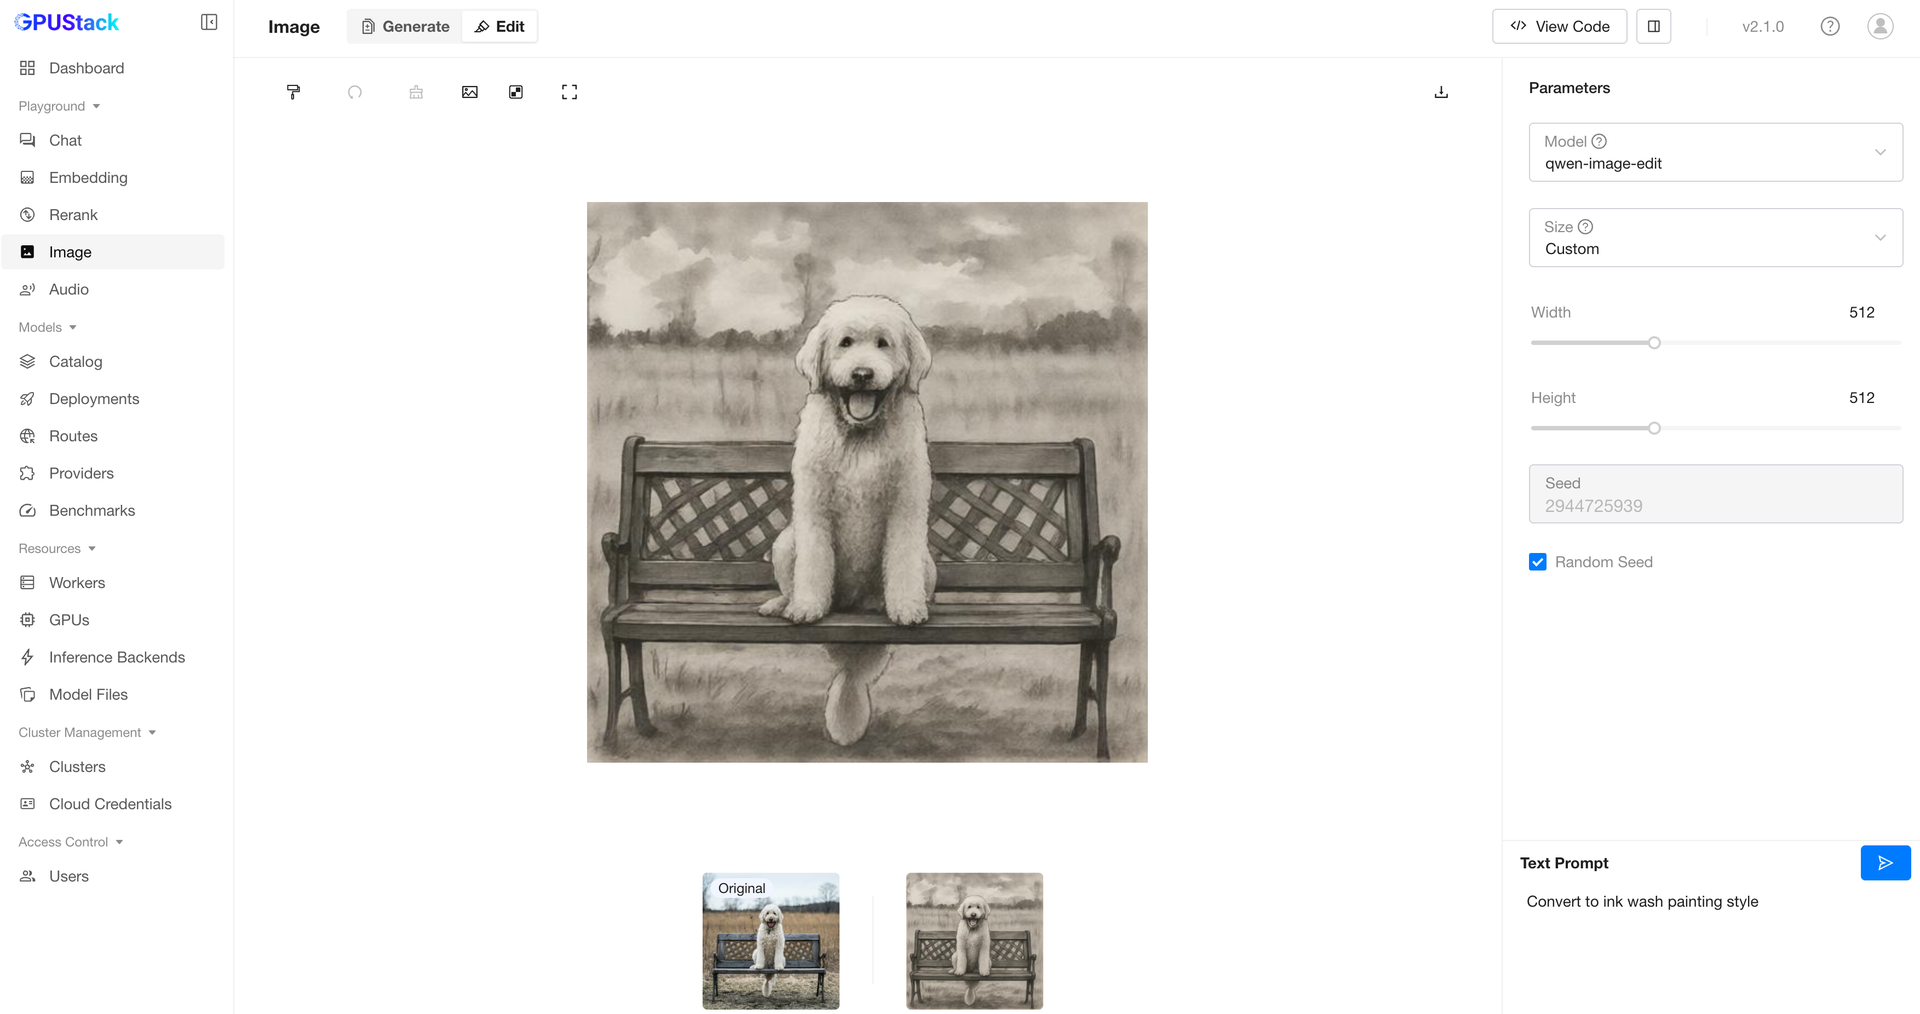
GPUStack is a control plane that turns a pile of GPU servers into a model-serving platform, where you pick a model from a catalog and the system decides which machine, engine, and settings run it. Deploy language, embedding, reranker, speech, and image models from the Catalog page, then watch each replica move from downloading to Running on the Deployments screen. A built-in Playground offers chat, side-by-side model comparison, embedding and rerank testing, audio, and image generation and editing, so a model gets judged before it is wired into an app. Add GPU workers with a generated Docker command, register a Kubernetes cluster, or provision cloud machines, and manage several clusters from one server. Create API keys for teammates, apply access control, and read token, GPU-hour, and storage usage by user, key, or model. Auto Tune benchmarking searches for the highest throughput that still meets your latency targets. GPU Instances hand out SSH-accessible machines for fine-tuning and interactive work. Single sign-on works through OIDC or SAML. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Benefits
- One Console For Every GPU
- Manage GPU workers from on-premises servers, Kubernetes clusters, and cloud providers through one server and one web console, with workers, GPUs, and model files listed in the same place.
- Deploy Models Without Engine Tuning
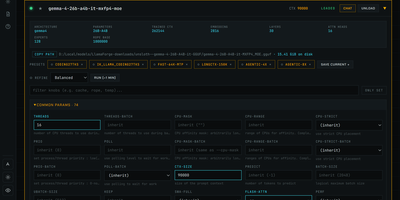
- Pick a model from the catalog and GPUStack chooses between vLLM, SGLang, and TensorRT-LLM, sets parameters, and places replicas on workers with enough VRAM, so new releases can run on day one.
- Know Who Used What
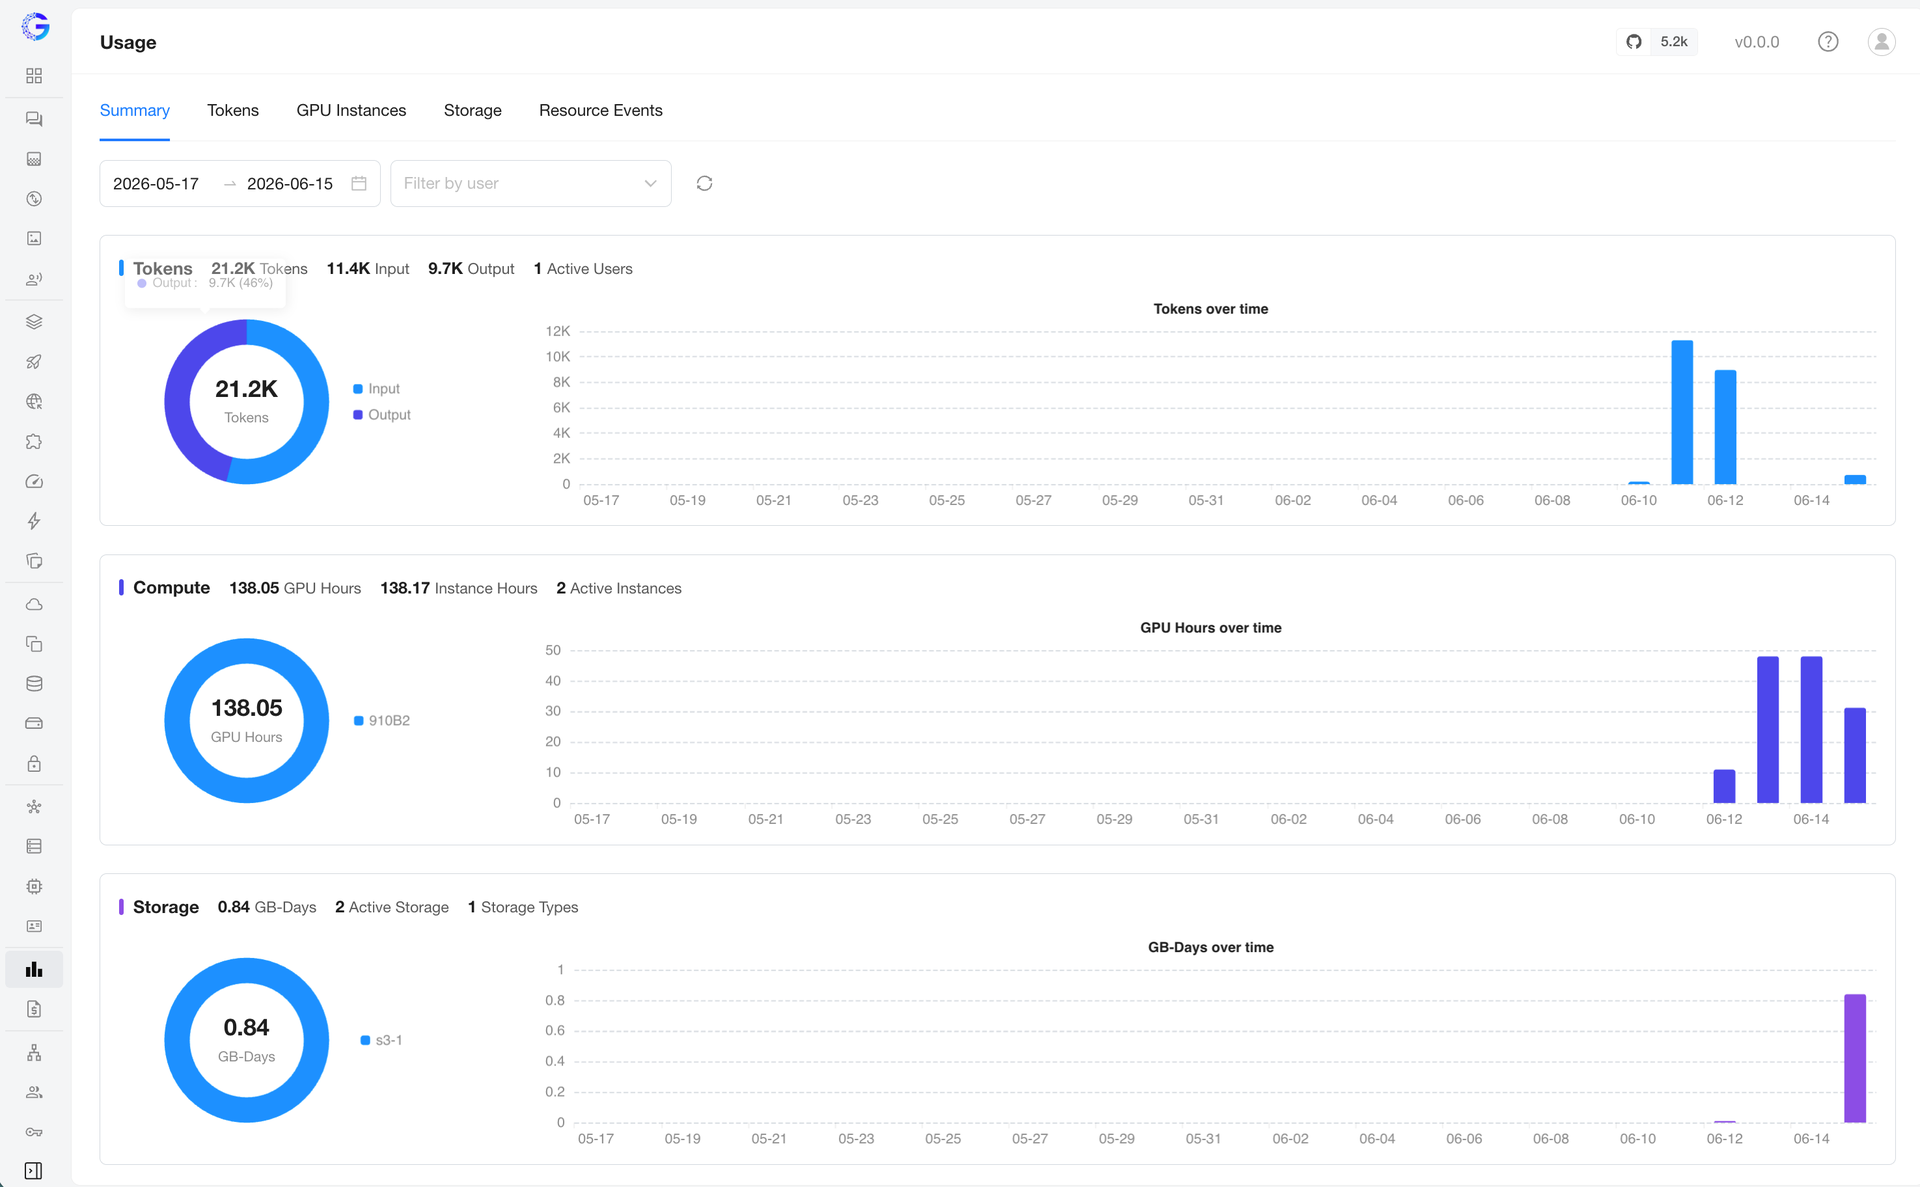
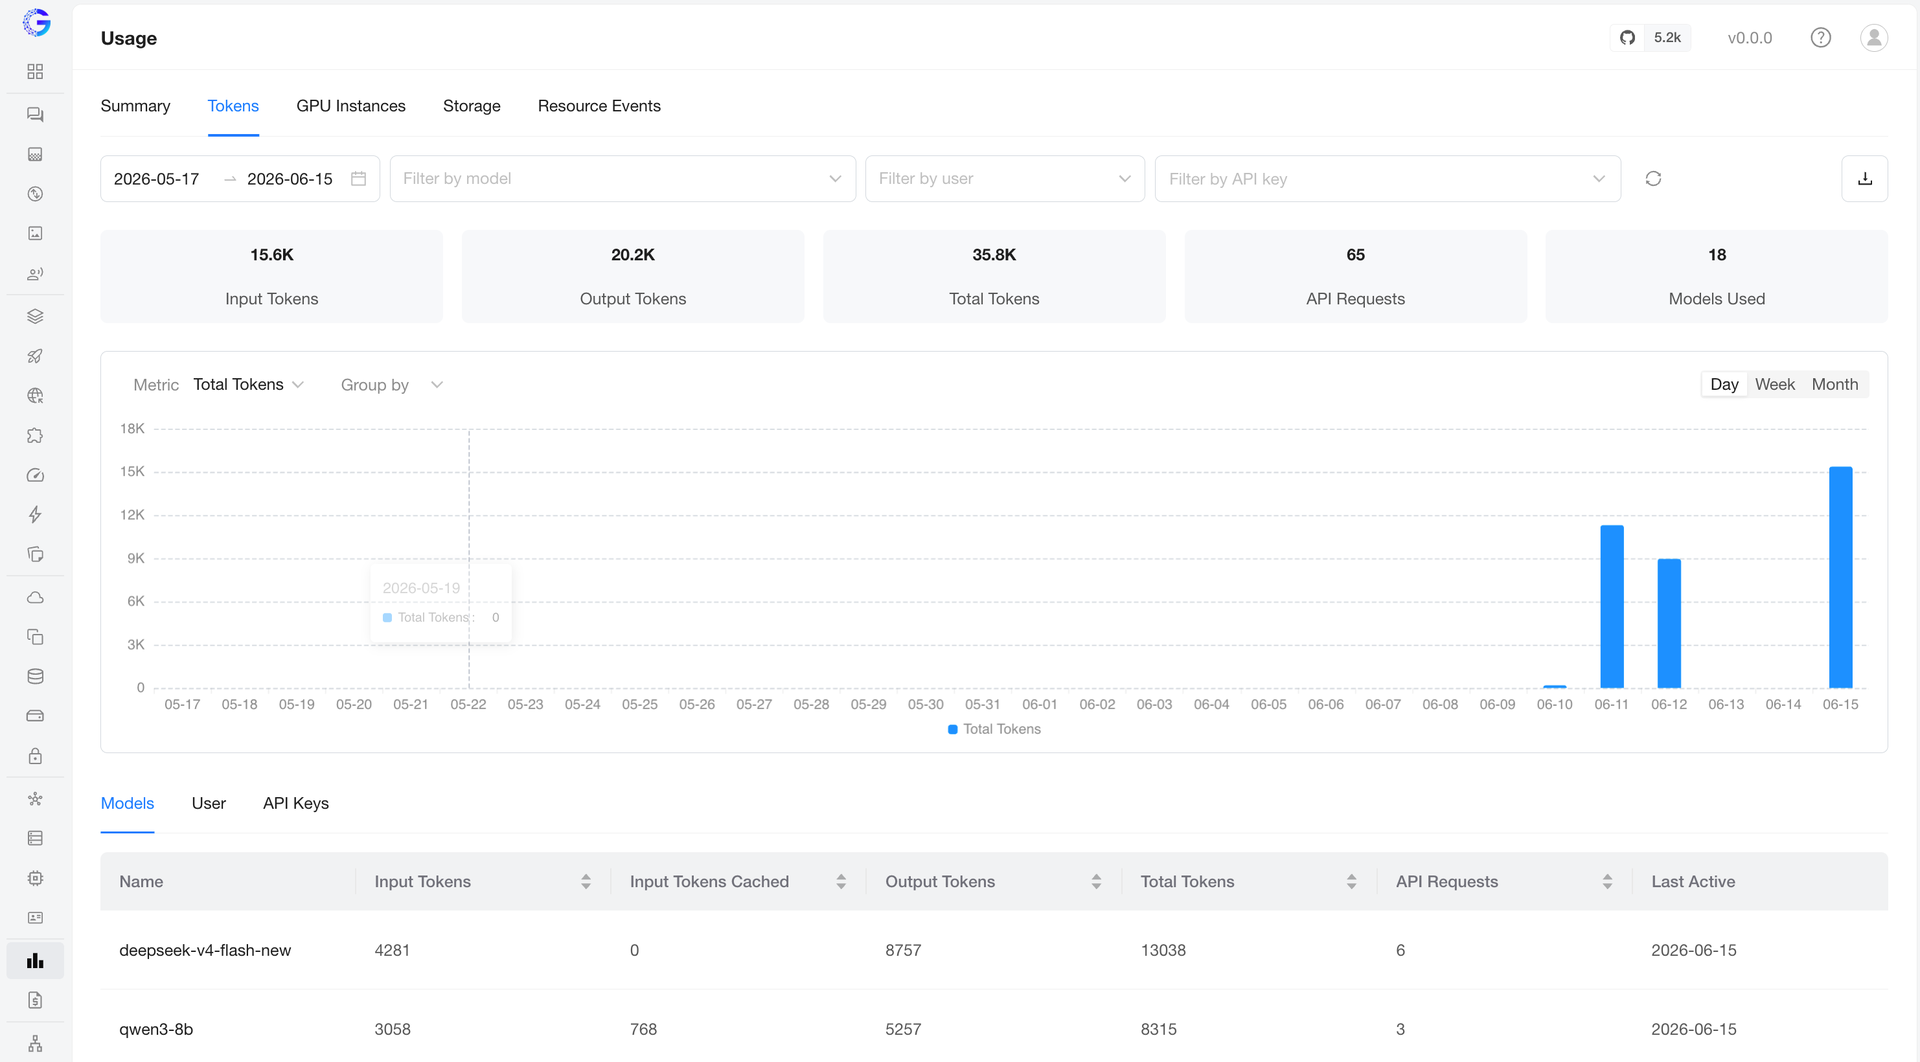
- Tokens, GPU hours, and storage are metered by user, API key, and model with date filters, so several teams can share one cluster and still see where capacity went.
- Test Before You Integrate
- The Playground covers chat, side-by-side comparison, embeddings, reranking, audio, and images against your own deployments, and View Code gives ready-to-paste API calls for the model you tested.
Features
- Model Catalog And Deployments
- Browse a catalog of language, vision, speech, and image models, deploy with a replica count, and follow each instance from download to running.
- Multi-Cluster Worker Management
- Connect workers with a Docker run command, register a Kubernetes cluster, or provision cloud machines, with GPU slicing for partial allocations.
- Pluggable Inference Engines
- Run vLLM, SGLang, TensorRT-LLM, or MindIE, or add a custom backend, with tuned modes for low latency or high throughput.
- Built-In Benchmarking
- Auto Tune explores concurrency or request rates to find peak throughput or the highest load that meets your service-level targets, with charts.
- Usage And Access Control
- Create users and API keys, connect single sign-on over OIDC or SAML, and review token, GPU hour, and storage usage.
- SSH GPU Instances
- Launch SSH-accessible GPU instances from templates for fine-tuning and interactive work, with storage types and public key management.