Imp
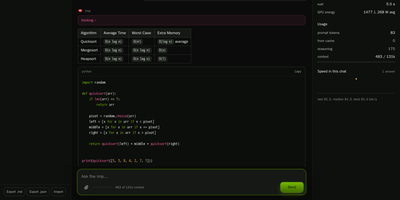
Imp runs large AI chat models privately on one NVIDIA RTX 50 or RTX PRO graphics card, exposing them through OpenAI and Anthropic compatible APIs plus a built-in browser chat. Start it with a single Docker command, point it at a model, and the chat opens in your browser with saved conversations and a live readout of generation speed. Coding agents such as Claude Code and Codex connect by changing one base URL, so your editor talks to the model on your own hardware instead of a rented cloud endpoint. Tool calls, structured JSON output, streaming responses, and reasoning models all work over the wire, and requests can be protected with an API key, per-IP rate limits, and concurrency caps. Load GGUF files you already have or NVFP4 and FP8 SafeTensors checkpoints straight from Hugging Face with no conversion step before the first answer. When a model is bigger than the card, mixture-of-experts weights stay in system RAM while the busiest experts are cached on the GPU, so a 123.6 GiB model still answers from a 32 GB card. Supported models can also read images alongside text, and tokenize, health, and model listing endpoints make the server easy to wire into scripts and monitors. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
FreeLLMAPI
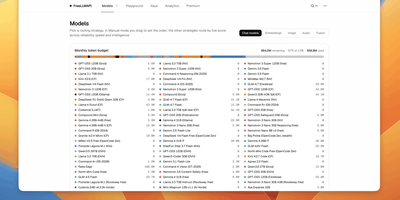
FreeLLMAPI collapses the chaos of 29 free LLM providers — Google AI, Cerebras, Groq, Mistral, OpenRouter, GitHub Models, Cohere, Cloudflare Workers AI, NVIDIA NIM, HuggingFace, SiliconFlow, Reka, Z.ai, and more — into a single /v1 endpoint that speaks both OpenAI and Anthropic protocols. The smart router selects the best available model for each request, automatically fails over to the next provider when rate limits hit, and tracks per-key token consumption so you never exceed a free-tier cap. Keys are stored with AES-256-GCM encryption and clients authenticate using a single unified bearer token, never exposing upstream provider credentials to downstream applications. The catalog tracks 251 model families across 358 provider/model endpoints with approximately 4 billion tokens per month of aggregate free-tier capacity, auto-refreshing from a signed manifest at freellmapi.co twice daily without requiring git pulls. Beyond chat completions, the proxy handles embedding, image generation, and audio/TTS endpoints, plus structured outputs with JSON schema forwarding, JSON healing, and format-ignore failover. An integrated MCP server at /mcp provides gateway introspection for coding agents, while the self-hosted OpenAPI reference at /v1/docs documents every route. Compatible with OpenAI SDKs, LangChain, LlamaIndex, Continue, Claude Code, and Hermes — just change base_url. Deploy via Docker, npm, or build from source. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.