SourceWeft
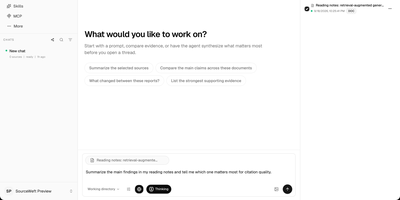
SourceWeft is an AI workstation you host yourself, where agents, your documents, and your model keys work in one place instead of scattering across chat tabs you do not control. Describe a job and a lead agent breaks it down, handing research, exploration, and execution to focused sub-agents that share the same working context and files. Agents draw on a skill library covering presentations, HTML pages, images, meeting summaries, and study guides, and you can add your own skills so good workflows become repeatable. MCP servers, web search, and web extraction connect agents to outside tools, while approved commands run inside a sandboxed environment that cannot touch the rest of your server. Feed it PDFs, web pages, notes, YouTube videos, Notion, Drive, Gmail, or Slack, then follow citations from any answer back to the source material it came from. Bring your own keys for the chat and indexing models you prefer, organize the team into workspaces with roles and access controls, and pick up any conversation from the web app or desktop clients. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Nod
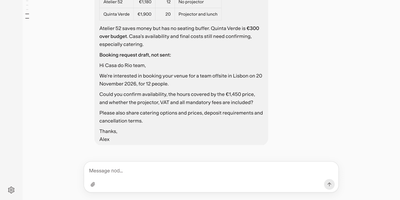
Nod is a personal AI assistant with its own computer, so you can hand it an errand like chasing an unpaid invoice or cancelling a trial and watch it finish the job on real websites. One ongoing conversation follows you from the browser to Telegram and WhatsApp, and long jobs become saved tasks with live status lines on a Scheduled page. Connect Gmail, Calendar, Slack, Notion, Linear, or an n8n instance, and it reads threads, drafts the replies you owe, and prepares a one-page brief before each call. Every action that could change something is checked against your rules, and anything uncovered waits for your yes. Passwords, codes, and cards sit in a Vault that the server types into websites, so the model never sees them. Memory notes are visible, editable, and tied to the message they came from. Schedules run recurring checks like a weekly recap or a price watch that speaks up only on change. Usage lists every action with costs and a monthly spending limit. Pick OpenAI, Anthropic, Gemini, OpenRouter, Bedrock, or a local Ollama server as the model. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
LibreChat
Every major model provider behind one ChatGPT-style interface: LibreChat spans OpenAI, Anthropic, Google, Azure, AWS Bedrock, Vertex AI, Groq, Mistral, OpenRouter, DeepSeek, and any OpenAI-compatible endpoint including local Ollama. You can switch models mid-conversation and compare providers without changing tools. Its Agents framework builds no-code custom assistants with tool access via Model Context Protocol servers, file search over uploaded documents through an optional pgvector-backed RAG service, and a sandboxed Code Interpreter that executes Python, JavaScript, Go, C++, Java, PHP, and Rust. Artifacts render React components, HTML, and Mermaid diagrams directly in chat, and image generation works through DALL-E and other configured providers. Multi-user support is enterprise-grade, with OAuth, SAML, LDAP, and two-factor authentication, per-user conversation history in MongoDB, and Meilisearch-powered search across all messages and files, plus reusable presets, forkable threads, and persistent memory across conversations. The economics favor teams: instead of a ChatGPT Plus seat per person, everyone shares one instance billed per API token, with access to every provider rather than one - and providers see individual API calls, not your accumulated organizational knowledge. Deployment is Docker Compose; API keys and endpoints are configured through .env and librechat.yaml.
llama.cpp
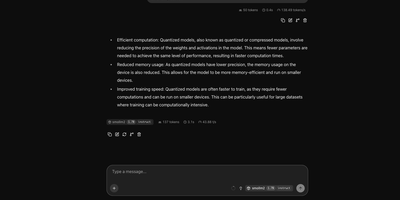
Open-weight language models get a private chat service on your own server, and llama.cpp serves its browser UI the moment the server starts. Conversations appear in a sidebar with search, and each answer shows its token count, generation time, and tokens per second, so you can see how a model really performs. Code replies render in highlighted blocks with a copy button, and messages can be edited, regenerated, forked, or deleted. A Models page lists what the server can run with context sizes and load status, and Settings cover themes, system messages, display options, tools, agentic behavior, import and export, and sampling controls for temperature, top K, top P, and penalties. Remote MCP servers connect by URL, and uploads let multimodal models read files and images. Behind the UI sit OpenAI and Anthropic compatible chat endpoints, embeddings, reranking, function calling, JSON schema constrained output, parallel decoding, and continuous batching for several users at once. Quantized models run on plain CPUs, and official images cover CUDA, ROCm, Vulkan, and other accelerators. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Ollama GUI
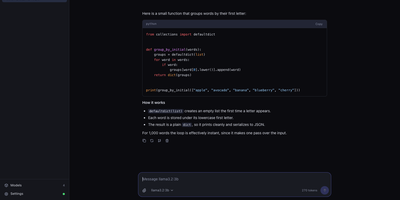
Chat with your own local language models from a clean, fast browser interface. Ollama GUI gives every model on your Ollama server a proper home: streaming replies you can stop, regenerate, or edit, with each edit saved as a version you can flip back to. Reasoning models show their thinking in a collapsible block, and you pick between thinking on, off, or an effort level. Attach images for vision models or drop in text and code files, and answers render with highlighted code, tables, and math. Pull models from a searchable catalog with live progress, check their capabilities and context length, unload them from memory, or delete them in a click. Chats are grouped by date, pinned, archived, renamed, titled automatically, and searched across every message from a command palette. System prompts and generation settings apply globally, per model, or per chat. Light and dark themes, locale-aware dates, and JSON or Markdown export round out the daily routine. Run one shared front end for a whole team or homelab, and every browser keeps its own private history. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Hollama
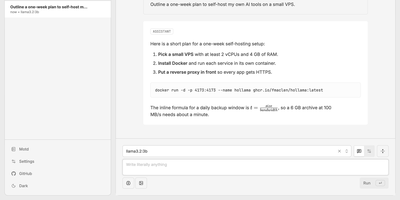
A tidy, account-free chat client for every language model server you run. Ollama, the OpenAI API, and OpenAI-compatible servers like llama.cpp plug in side by side, and each of their models appears in one picker. Prompts accept images for vision models, and answers render Markdown, highlighted code, and KaTeX formulas. Reasoning models keep their thinking in a separate panel from the final answer. Messages can be edited, retried, or copied, and the session panel holds a system prompt plus Ollama options for temperature, Top K, Top P, and seed. Knowledge notes, written in a built-in code editor, attach to a session as reusable context. The Settings page pulls new Ollama models by tag, labels each connection, and filters model names by prefix. Tabs stay in sync, themes switch between light and dark, and the interface is translated into many languages. Servers, preferences, sessions, and knowledge export and import as files. Nothing sits in a cloud database, because history lives in the browser of whoever opens it. A single Docker container on port 4173 serves a whole team. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
AMC WebUI
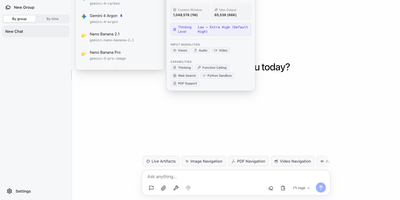
AMC WebUI is one chat window for every Gemini trick, with your conversations kept in your own browser instead of someone else's database. Pick a model from a picker that shows context window, output limit, and capabilities, then watch its reasoning stream with adjustable thinking levels. Voice chat and screen sharing run in realtime, and code blocks can turn into interactive HTML, SVG, Mermaid, or Graphviz previews. A Python sandbox executes snippets with numpy, pandas, and matplotlib inside the page. MCP settings list built-in tool servers beside any stdio, SSE, or HTTP server you add, and tool calls wait for your approval. Upload images, PDFs, audio, video, or whole ZIP folders, search past chats, and read per-request token and pricing logs. Deep search cites sources, text to speech offers thirty voices, and image generation takes aspect ratio and size options. Switch to any OpenAI-compatible endpoint with its own keys and models, choose among four themes and seven interface languages, and install it as a PWA. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Imp
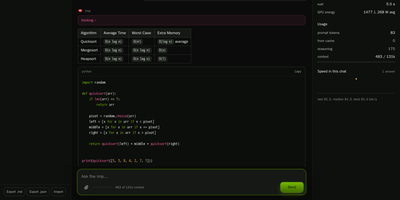
Imp runs large AI chat models privately on one NVIDIA RTX 50 or RTX PRO graphics card, exposing them through OpenAI and Anthropic compatible APIs plus a built-in browser chat. Start it with a single Docker command, point it at a model, and the chat opens in your browser with saved conversations and a live readout of generation speed. Coding agents such as Claude Code and Codex connect by changing one base URL, so your editor talks to the model on your own hardware instead of a rented cloud endpoint. Tool calls, structured JSON output, streaming responses, and reasoning models all work over the wire, and requests can be protected with an API key, per-IP rate limits, and concurrency caps. Load GGUF files you already have or NVFP4 and FP8 SafeTensors checkpoints straight from Hugging Face with no conversion step before the first answer. When a model is bigger than the card, mixture-of-experts weights stay in system RAM while the busiest experts are cached on the GPU, so a 123.6 GiB model still answers from a 32 GB card. Supported models can also read images alongside text, and tokenize, health, and model listing endpoints make the server easy to wire into scripts and monitors. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Neo Chat
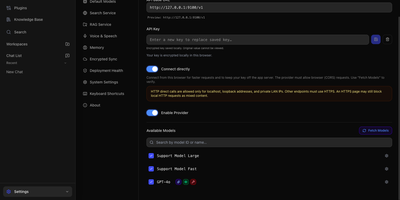
One chat window, every model you already pay for, and a history that stays in your own browser unless you decide otherwise. Neo Chat connects to Google, OpenAI, Anthropic, and any OpenAI-compatible gateway, so switching models mid-project takes one click. Agent mode runs multi-step tool workflows, and Deep Research drafts a plan for approval before producing a cited report that can be resumed if it stops. Attach files, build a knowledge base for retrieval, and let memory carry preferences between conversations. Browse a market of ready-made assistants and text skills, add OpenAPI plugins or remote MCP servers, and search the web through a configurable service. Answers render Markdown, math, diagrams, and charts, plus editable artifacts and interactive checklists, quizzes, flashcards, and calculators. Voice input and read-aloud sit beside the composer, and optional encrypted sync moves settings between devices. An access password can protect a shared deployment, and a health page checks that everything is configured. Switch models mid-conversation, keep one history, and stop juggling a tab for every provider. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.