Categories
Self-Hosted Local AI Chat Interface Model Serving LLM Inference OpenAI Compatible API Open Source LLM QuantizationStars
Forks
Watchers
Developer links
llama.cpp
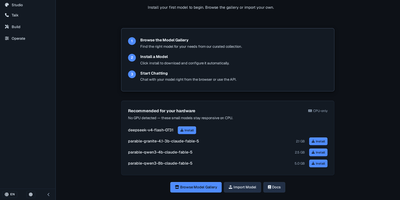
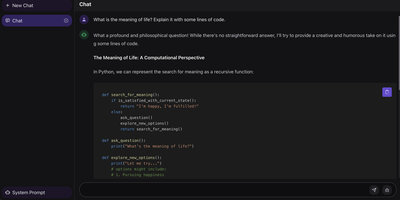
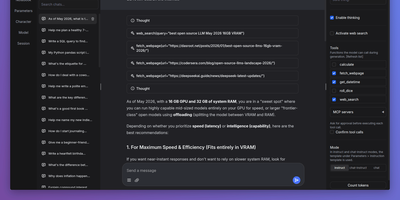
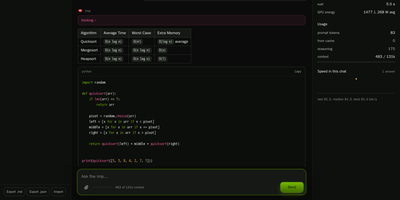
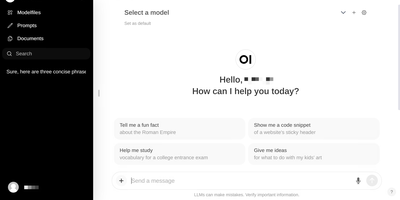
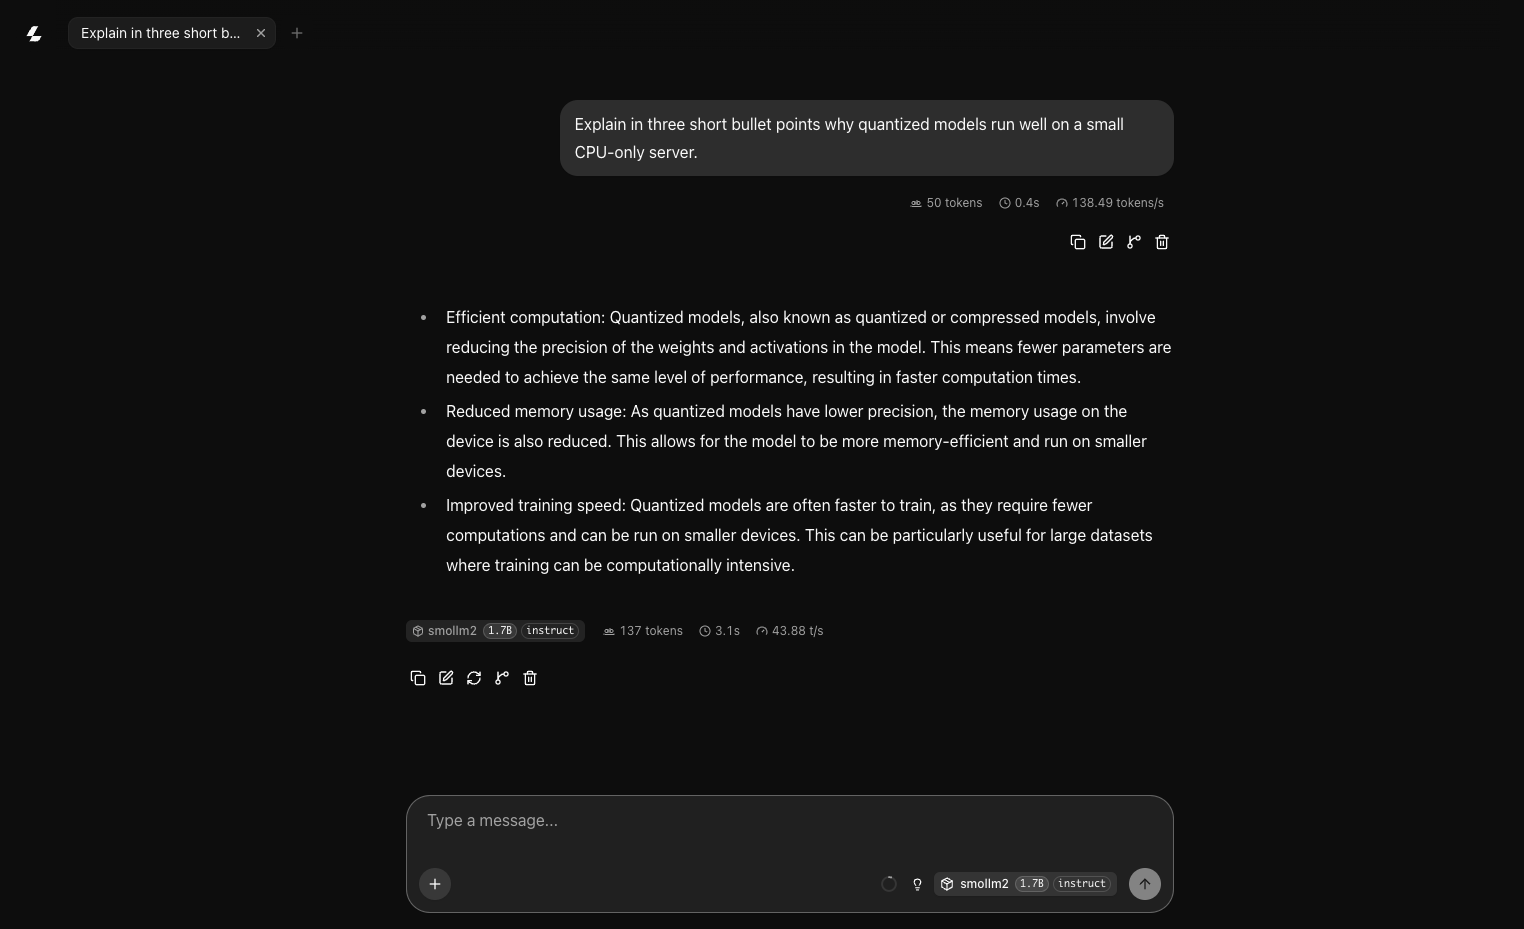
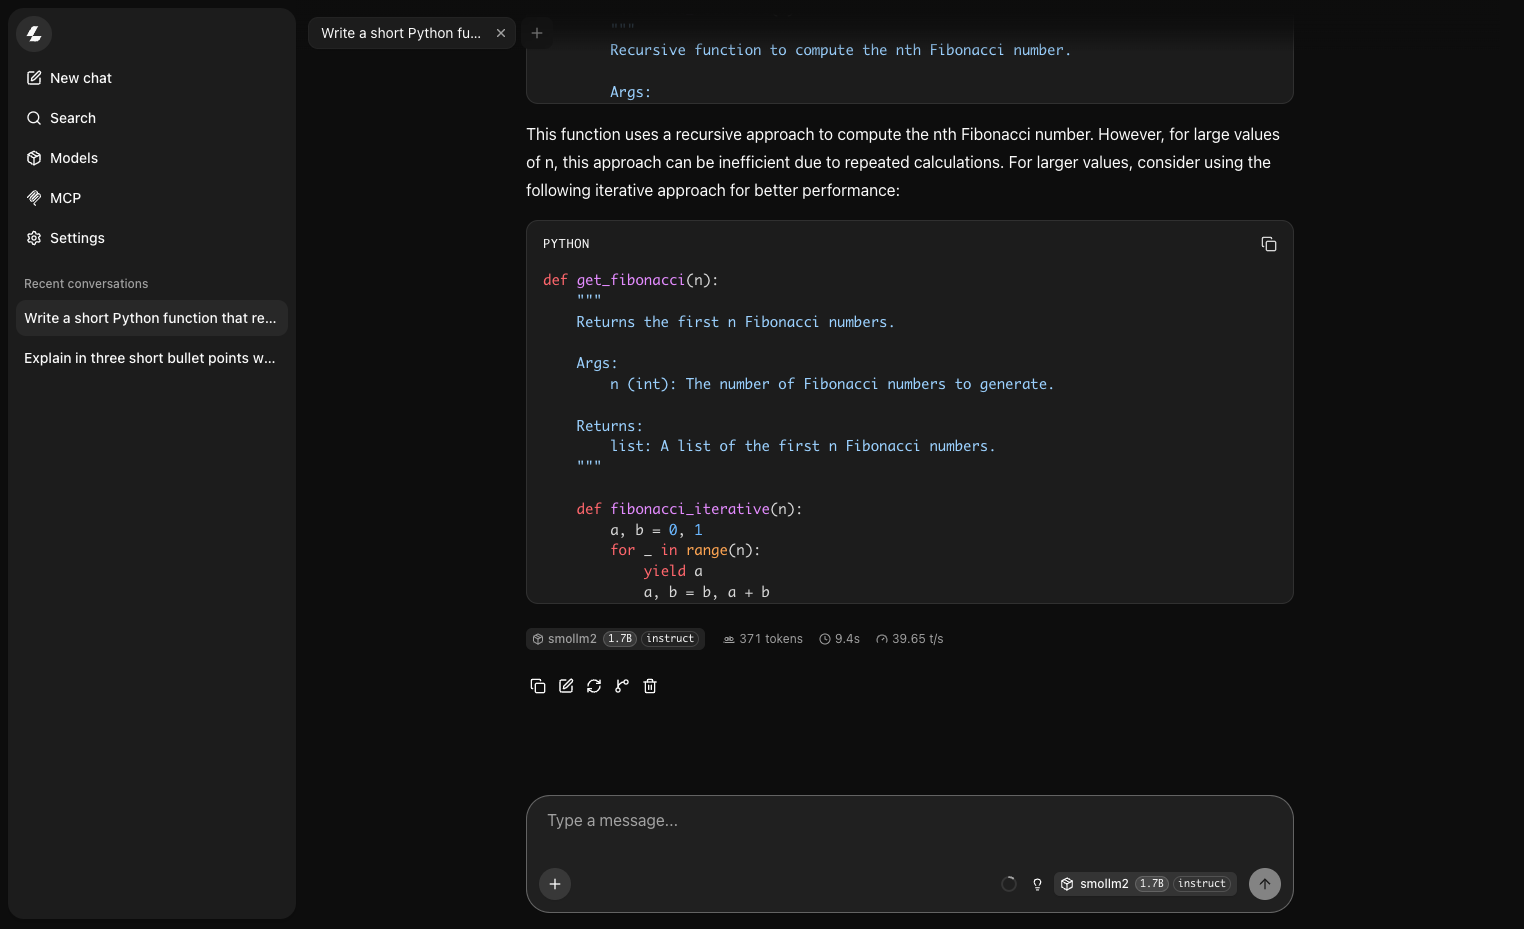
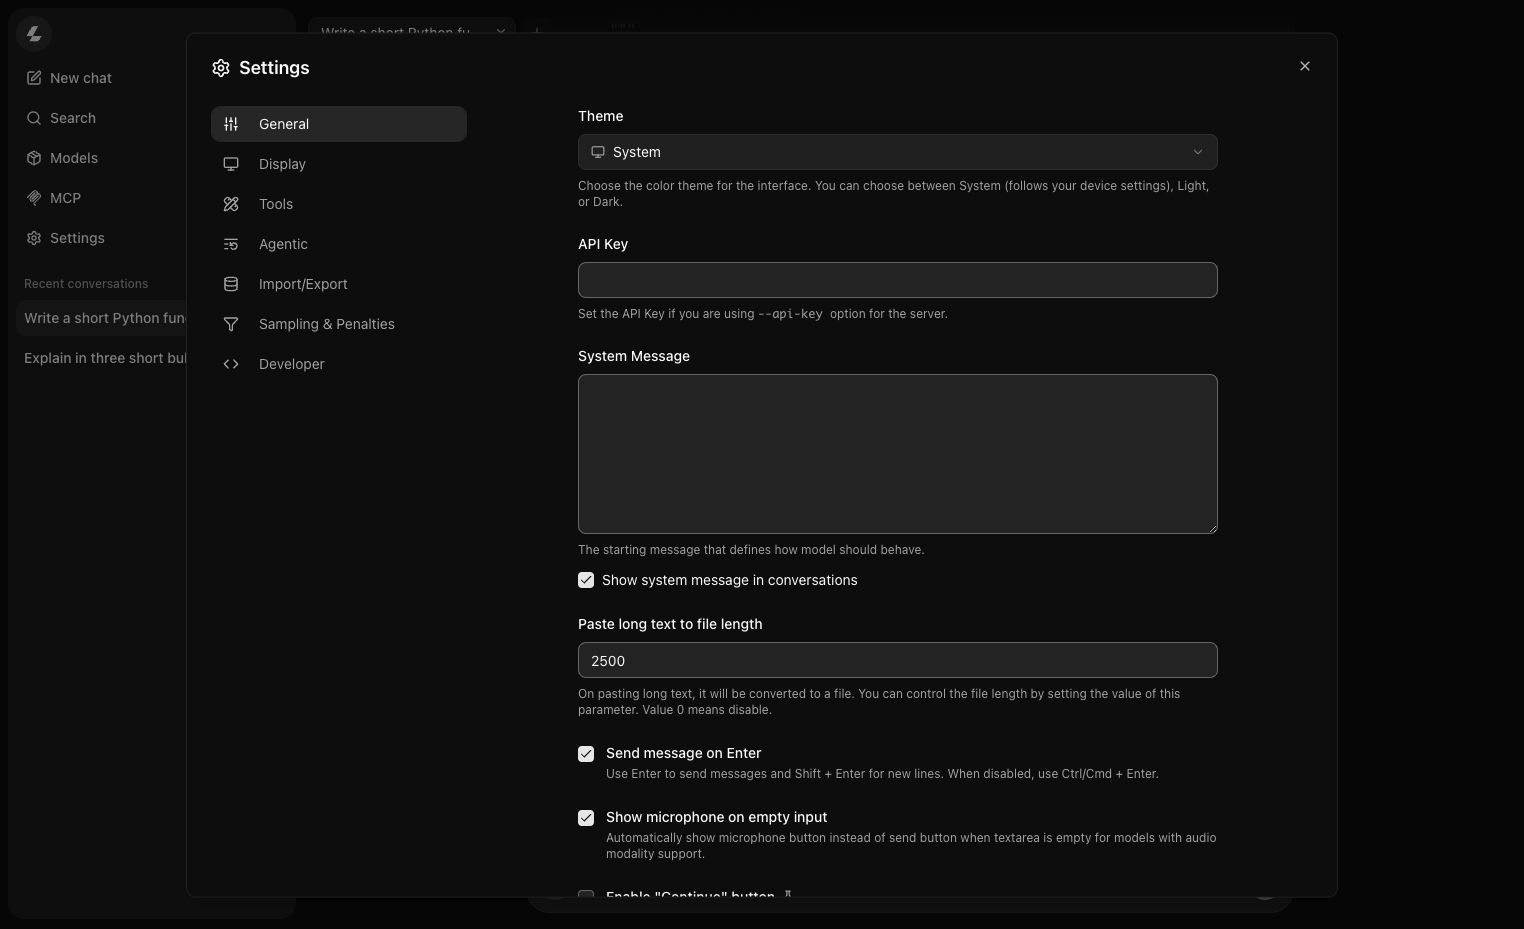
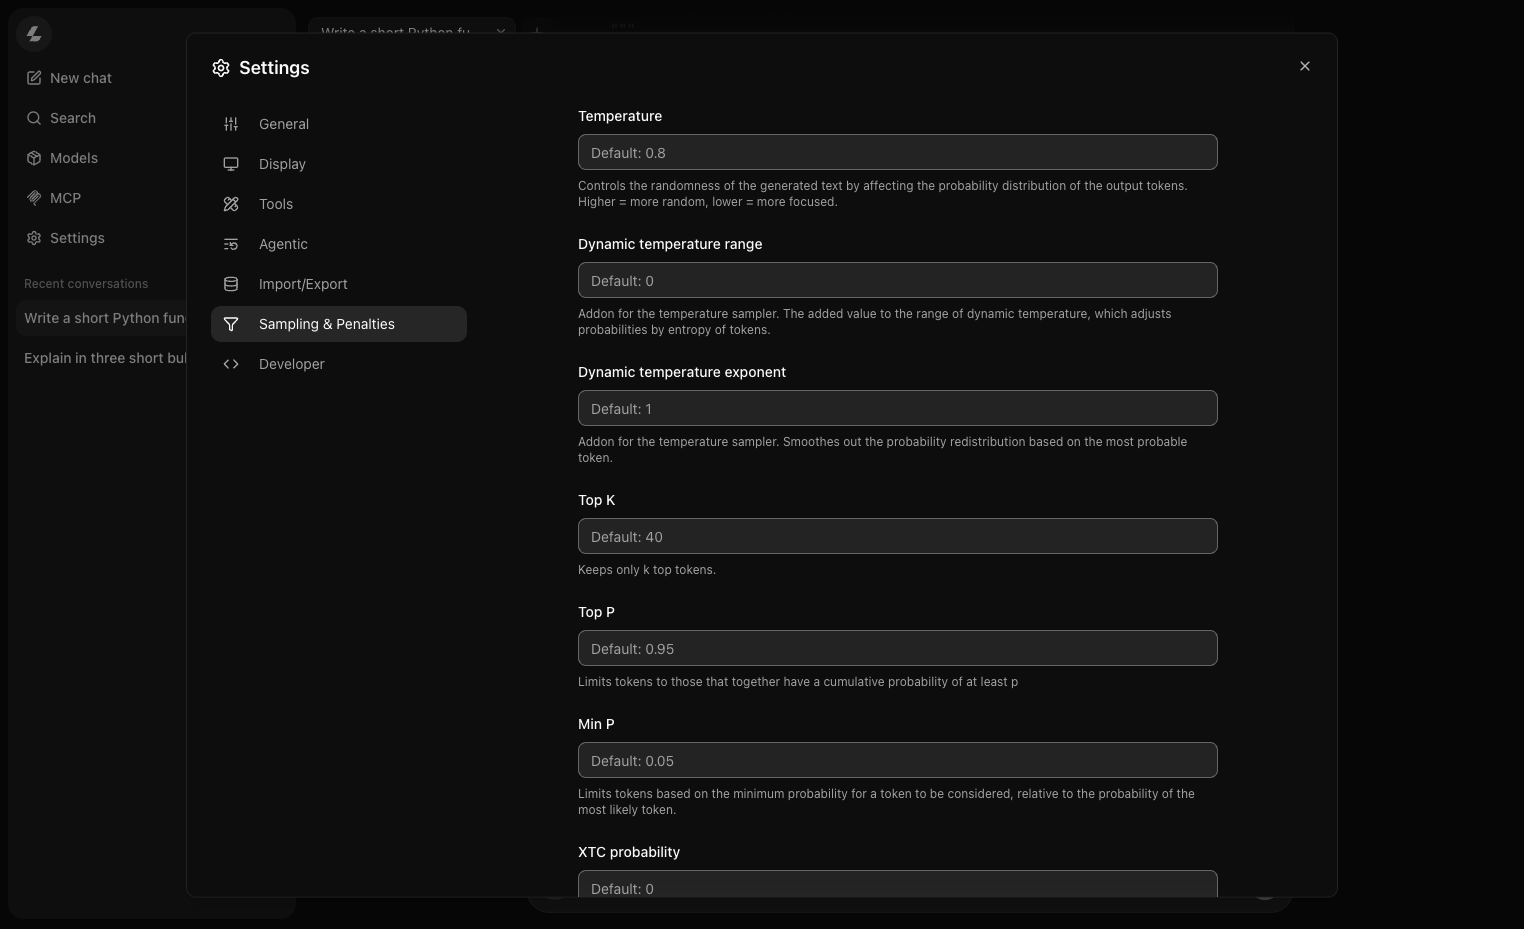
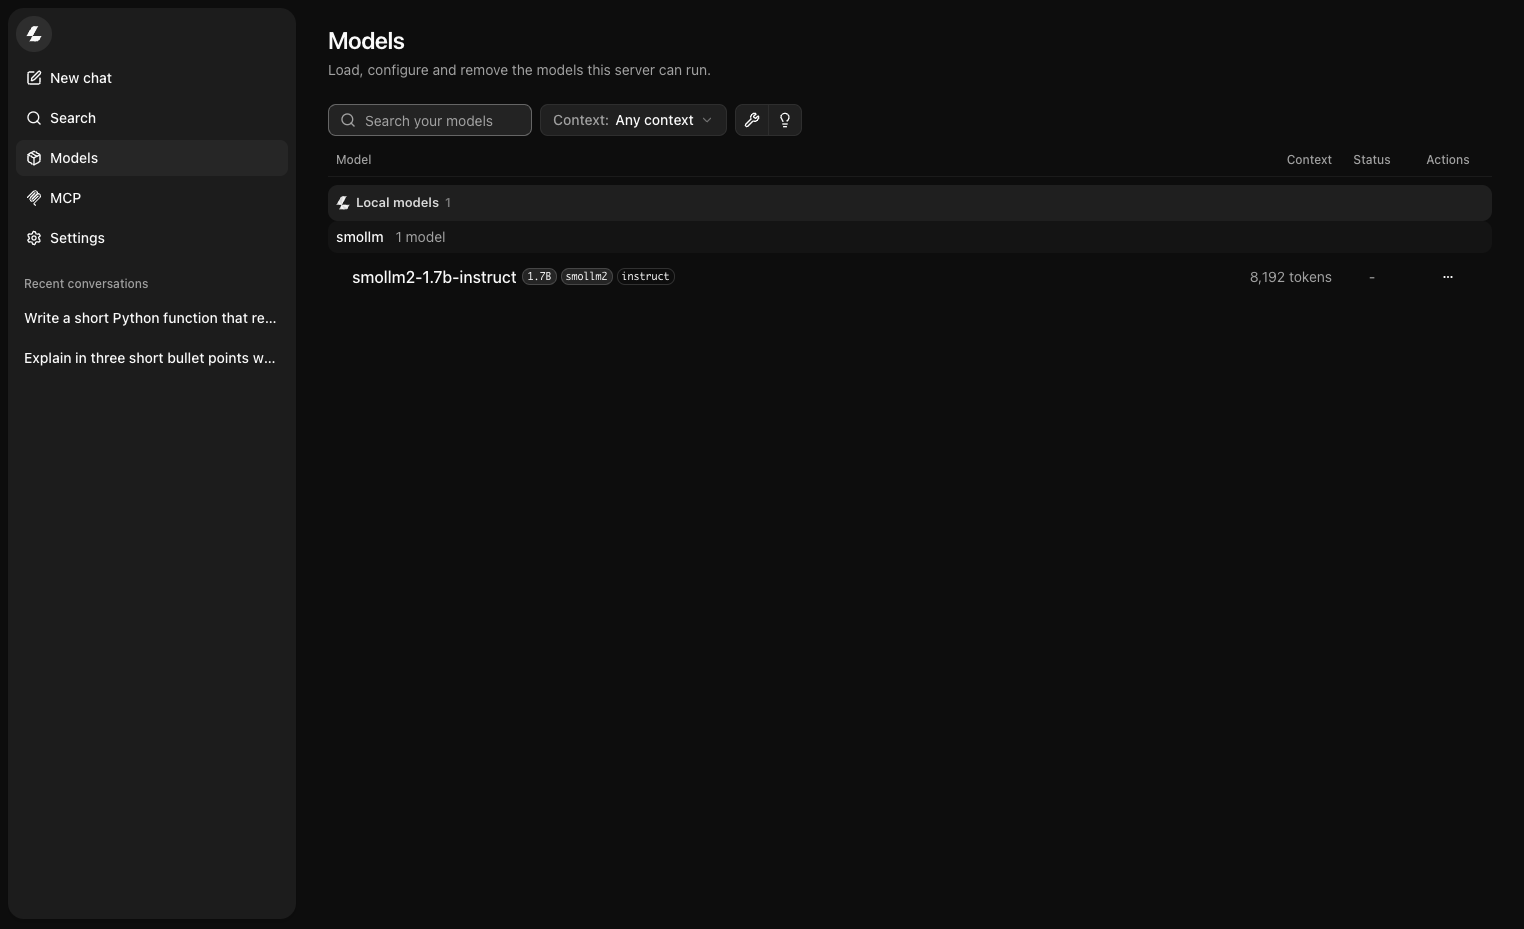
Open-weight language models get a private chat service on your own server, and llama.cpp serves its browser UI the moment the server starts. Conversations appear in a sidebar with search, and each answer shows its token count, generation time, and tokens per second, so you can see how a model really performs. Code replies render in highlighted blocks with a copy button, and messages can be edited, regenerated, forked, or deleted. A Models page lists what the server can run with context sizes and load status, and Settings cover themes, system messages, display options, tools, agentic behavior, import and export, and sampling controls for temperature, top K, top P, and penalties. Remote MCP servers connect by URL, and uploads let multimodal models read files and images. Behind the UI sit OpenAI and Anthropic compatible chat endpoints, embeddings, reranking, function calling, JSON schema constrained output, parallel decoding, and continuous batching for several users at once. Quantized models run on plain CPUs, and official images cover CUDA, ROCm, Vulkan, and other accelerators. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Benefits
- Private Chat On Your Server
- Prompts, files, and conversation history stay on hardware you control, so teams can chat with open models without sending sensitive text to a third-party API.
- Measure Real Model Speed
- Every reply reports tokens, elapsed time, and tokens per second, which makes it easy to compare quantizations and settings on your exact server before committing.
- Drop In For Existing Apps
- OpenAI and Anthropic compatible endpoints let existing SDKs, agents, and chat clients point at your server by changing a base URL, with no code rewrite.
- Run Well On Modest Hardware
- Quantized models fit in small amounts of memory and run on ordinary CPUs, so a standard VPS can serve a capable assistant without a dedicated graphics card.
Features
- Built In Chat Interface
- Start conversations, search history, edit or regenerate replies, branch a thread, and copy highlighted code blocks from a clean browser UI that ships with the server.
- Model Management Page
- See each model with its parameter size, family, context length, and load status, then load, configure, or remove models without restarting the whole service.
- Detailed Sampling Controls
- Tune temperature, dynamic temperature, top K, top P, min P, XTC, and penalties in settings, with sensible defaults shown beside every field.
- Compatible API Endpoints
- Use chat completions, responses, embeddings, and reranking routes in OpenAI format, plus Anthropic style messages, with function calling and schema constrained JSON output.
- Multi User Serving
- Parallel decoding and continuous batching let several people or services share one loaded model, with monitoring endpoints and optional API key protection for the server.
- MCP And File Uploads
- Connect remote MCP servers by URL for tool use, and attach files or images for multimodal models that can read them in the same conversation.