Promptfoo
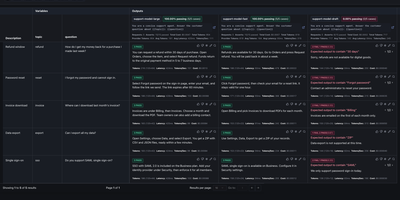
Promptfoo replaces vibes-based prompt tweaking with measurable tests, then attacks your AI app the way a hostile user would. An evaluation matrix lines up every prompt and model side by side, with pass or fail badges, assertion messages, latency, token counts, and cost in each cell. A red team wizard walks through the target, application details, plugins, and strategies, then probes for prompt injection, data exposure, broken access control, and harmful content. Preset bundles map plugins to the OWASP LLM Top 10, NIST AI RMF, MITRE ATLAS, GDPR, ISO 42001, and the EU AI Act. Meta Agent and Hydra Multi-Turn strategies adapt attacks across a whole conversation instead of firing one-shot prompts. Providers span OpenAI, Anthropic, Gemini, Bedrock, Azure, and local Ollama models, and any HTTP endpoint, Python script, or JavaScript function can be tested as a target. The history page lists every run with pass rates and raw scores, and prompt and dataset pages show which templates and test sets each run used. A provider allowlist file narrows the models offered in the web editor for cost control. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
ChainForge
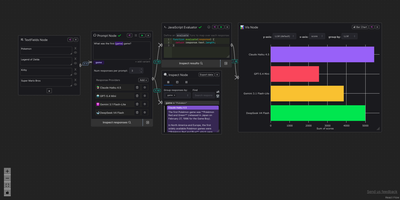
Comparing prompts and models by eye stops working fast, so ChainForge lays every experiment out on one visual canvas. Drop a table of inputs into a Prompt Node, add a handful of models, and the app sends every combination of template variable and model, then collects the answers in an Inspect Node that groups responses by any variable. Evaluator nodes score outputs with a few lines of code, and visualization nodes plot pass rates and numeric scores as histograms or box plots. Chat Turn nodes test follow-up questions, to see if a model caves when a user pushes back. Sparkle buttons draft synthetic table rows, test questions, and starter evaluator code with a model of your choice, and an LLM scorer can judge answers against a rubric you write. Example Flows open ready-made experiments, from a no-key starter with tiny in-browser models to prompt template comparisons, sycophancy checks, gender bias audits, red-teaming runs, and 188 flows converted from OpenAI Evals. Documents, Chunking, Retrieval, and Rerank nodes cover retrieval experiments. Finished flows export as cforge files, and results export to spreadsheets or JSON for the rest of the team. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.