LobeHub
With over 82,000 GitHub stars and 700,000+ downloads, LobeHub has evolved from its origins as LobeChat into a comprehensive multi-agent AI collaboration platform where humans and autonomous agent teams co-evolve. The platform's Agent Harness architecture functions as an operating system between AI models and applications, handling prompt presets, tool orchestration, lifecycle hooks, planning, filesystem access, and sub-agent management across 25+ model providers including OpenAI, Anthropic Claude, Google Gemini, DeepSeek, Mistral, Groq, AWS Bedrock, Azure OpenAI, and local models through Ollama. Agent Groups enable sophisticated collaboration with sequential, parallel, iterative, and debate orchestration modes, allowing multiple specialized agents to tackle complex workflows simultaneously. The Agent Builder creates production-ready agents from natural language descriptions with auto-configuration, drawing from a marketplace of 505+ pre-built agents and 10,000+ MCP-compatible skills and plugins. Pages provide collaborative document editing with multi-agent co-authoring, while Schedules automate agent runs around the clock without human supervision. The knowledge base leverages PostgreSQL with pgvector for RAG-powered retrieval, and Personal Memory gives agents transparent, editable context that evolves through continual learning. The full self-hosted stack deploys via Docker Compose with PostgreSQL, Redis, RustFS for S3-compatible storage, and SearXNG for private web search, all configurable through environment variables. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. LobeHub Community licensed.
Open Lovable
Open Lovable from the Firecrawl team delivers the first truly open-source alternative to Lovable.dev — a chat-driven AI copilot that takes any website URL and regenerates it as a complete, editable React application with TypeScript and Tailwind CSS in seconds. The pipeline combines Firecrawl's intelligent web scraping for JavaScript-rendered pages and single-page applications with your choice of AI provider — Claude, GPT-4, Google Gemini, or Groq — to analyze HTML structure, extract layouts and styling, decompose pages into proper React components, and generate production-ready code following modern best practices. Live preview runs in a secure sandbox environment using Vercel Sandbox with OIDC authentication or E2B Cloud, letting you see results immediately and iterate through natural language chat to request changes like Tailwind migration, componentization, SEO improvements, accessibility fixes, or custom form implementations. The optional Morph LLM fast-apply path accelerates small edits by applying diffs directly without full regeneration. The provider-agnostic architecture means you control costs by routing to different models — use Groq for fast iterations and Claude for complex layouts. Project structure follows Next.js conventions with organized app, components, atoms, styles, utils, and hooks directories. Deploy via pnpm with Node.js 18+ requiring only a Firecrawl API key, one AI provider key, and a sandbox provider configuration. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Supabase
With over 107,000 GitHub stars and adoption by teams at Mozilla, 1Password, Peerlist, and thousands of startups, Supabase has become the most widely deployed open-source Firebase alternative — built entirely on PostgreSQL rather than a proprietary NoSQL store. Every project provisions a dedicated Postgres database with 40+ preinstalled extensions, auto-generating REST APIs via PostgREST, GraphQL via pg_graphql, and real-time change streams via an Elixir-based WebSocket engine that supports database change listeners, user presence tracking, and arbitrary broadcast messaging. Authentication covers email and password, phone OTP, magic links, and 20+ social providers including Google, GitHub, Apple, Azure, and SAML SSO, all enforced through Postgres Row Level Security policies that run inside the database itself. S3-compatible object storage delivers files through a CDN spanning 285+ cities with on-the-fly image transformations powered by imgproxy. Edge Functions run globally distributed TypeScript on the Deno runtime with Node.js compatibility and access to over two million NPM packages. The pgvector extension stores, indexes, and queries vector embeddings for AI-powered semantic search and retrieval-augmented generation workflows. Supabase Studio provides a browser-based dashboard with a table editor, SQL editor, schema visualizer, and log explorer. Official client SDKs ship for JavaScript, Python, Flutter, Swift, Kotlin, C#, Go, and Ruby. The self-hosted Docker Compose stack runs fourteen coordinated services including Kong API gateway, Supavisor connection pooler, and Logflare analytics. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
DeerFlow
DeerFlow 2.0 is ByteDance's ground-up rewrite that transforms what began as a Deep Research framework into a batteries-included super agent harness handling tasks lasting minutes to hours autonomously. Built on LangGraph and LangChain, the runtime orchestrates a lead agent that plans, decomposes, and delegates to sub-agents executing in isolated Docker or Kubernetes sandboxes with persistent filesystem access, while an extensible skills system lets developers add capabilities as Python functions or MCP servers with OAuth token flows. The harness ships with long-term memory using persistent event loops with per-agent isolation, scheduled task execution via cron, context engineering with manual compaction, and a web UI at localhost:2026 for interactive sessions. Model support spans OpenAI GPT-4o/GPT-5, Anthropic Claude via OAuth, Google Gemini, DeepSeek, Qwen via vLLM, and OpenRouter-compatible gateways with per-model pricing configuration. IM channel integration connects Telegram, Slack, Feishu/Lark, Discord, WeChat, WeCom, DingTalk, and Buzz without requiring a public IP — all using long-polling or WebSocket transports. Production deployment uses Docker Compose with nginx reverse proxy, PostgreSQL or SQLite persistence, Redis stream bridges for multi-worker scaling, and lease-based run ownership with automatic orphan recovery. The terminal workbench TUI enables headless operation. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Postiz
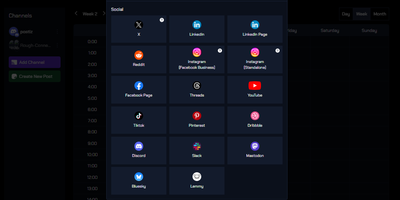
Powering over $145K monthly recurring revenue as a one-person company and holding 34,000+ GitHub stars, Postiz has emerged as the most widely adopted open-source alternative to Buffer, Hootsuite, and Hypefury — combining social media scheduling with AI-driven content creation and agentic automation in a single self-hosted platform. The Next.js 14 frontend with React 18 and Tailwind CSS delivers a visual calendar and Canva-like design editor, while the NestJS backend orchestrates publishing across 30+ social networks including X, LinkedIn, Instagram, TikTok, YouTube, Reddit, Pinterest, Threads, Dribbble, Discord, Bluesky, Mastodon, and Facebook. Temporal handles durable workflow execution for reliable scheduled posting, retry logic, and background job processing. The built-in AI assistant generates post ideas, captions, hashtags, images, and short videos from natural language prompts — all within a single chat interface. An agentic layer exposes a CLI and MCP server that allow AI agents like OpenClaw, Claude, and ChatGPT to autonomously plan, draft, and schedule posts programmatically. Team collaboration includes role-based permissions, approval workflows, multi-workspace management for agencies, and commenting on scheduled content. A full REST API with a NodeJS SDK, N8N custom nodes, and Make.com integration enables automation pipelines. Analytics track engagement, reach, and growth across all connected accounts from a unified dashboard. The self-hosted stack deploys via Docker Compose with PostgreSQL, Redis, and Temporal pre-wired — no feature limitations compared to the cloud version. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
TrueForge
With over 2,100 GitHub stars in its first month and benchmarked at 30-75% lower cost than Claude Managed Agents on enterprise task suites, TrueForge is the open-source agent harness that provides the complete runtime layer for turning any LLM into a working production agent on your own infrastructure. The TypeScript server runs the full execution loop — streaming every step, routing tool calls through MCP servers with centralized header-auth and in-chat OAuth, delegating parallelizable work to isolated subagents, and pausing for human approval on sensitive actions. Context engineering keeps token costs low: deferred tool-schema loading delays MCP schemas until invoked, large-result offloading moves oversized outputs to files, Code Mode processes structured data through sandboxed execution, and automatic compaction summarizes older history at a configurable 50,000-token threshold while preserving the full transcript. The sandbox-as-a-tool architecture provisions isolated Daytona environments only when code execution is required, allowing one server to run many concurrent agents without idle overhead. Agents are configured from shipped YAML catalogs of models, MCP servers, git-backed SKILL.md instruction packs, and sandbox providers, then saved to an Agents Library accessible via the chat UI, TypeScript SDK, or embeddable React UI SDK. Run locally with SQLite via a single npx command, or deploy for teams with Docker Compose or Helm using Postgres and Redis with OIDC authentication. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Onyx
Formerly known as Danswer and now backed by over 31,000 GitHub stars with 253 releases, Onyx delivers a production-ready AI platform that turns any LLM into a context-aware enterprise assistant connected to your organization's actual knowledge. The agentic RAG pipeline combines BM-25 keyword search with prefix-aware embedding models in a hybrid index, then deploys AI agents to retrieve, verify, and synthesize answers with source citations from over 40 connected workplace tools including Google Drive, Confluence, Slack, Notion, Jira, SharePoint, GitHub, and Linear. Custom AI assistants with configurable prompts, backing knowledge sets, and document-level access control enable specialized agents for engineering, sales, support, and research workflows. The platform supports every major LLM provider — Anthropic Claude, OpenAI, Google Gemini, plus self-hosted options via Ollama, LiteLLM, and vLLM for fully air-gapped deployments. Beyond chat, Onyx provides web search with Serper, Google PSE, Brave, and SearXNG integration, an in-house web crawler, code execution, file creation, and multi-step deep research with report generation. Enterprise features include SSO via Google OAuth, OIDC, or SAML with SCIM provisioning, role-based access control, usage analytics by team and agent, query history auditing, PII removal through custom code hooks, and full whitelabeling. Deploy via Docker Compose on any infrastructure. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed (Community Edition).
Archestra
Archestra delivers the enterprise AI infrastructure layer that organizations need when managing multiple LLM providers, MCP servers, and AI agents across teams becomes unmanageable. The LLM gateway routes requests across Anthropic, OpenAI, Azure, Bedrock, and DeepSeek with virtual API keys, per-team cost limits, and dynamic model routing — giving every developer one token for Claude Code, Cursor, or Codex while finance tracks spend per department. The MCP gateway authenticates tool calls with OAuth 2.1 and On-Behalf-Of tokens so each tool executes as the calling user, not a shared service account, eliminating credential sprawl. The private MCP registry lets teams publish custom tool servers with approval flows promoting servers from dev through staging to production, each environment maintaining its own credentials and network egress policies. The Kubernetes operator manages MCP server lifecycle — deploying containers, scaling, health-checking, and routing gateway traffic to local servers automatically. The agent runtime supports scheduled triggers, email and webhook invocations, sub-agent delegation, reusable skills, and sandboxed code execution with a K8s-native filesystem. Deterministic guardrails including Dual-LLM verification and Lethal Trifecta protections prevent dangerous tool calls before execution. Built-in OpenTelemetry traces and Prometheus metrics provide full observability without additional tooling. Docker deployment exposes the Admin UI on port 3000 and API on port 9000 with a single command. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Hermes Studio
The most comprehensive open-source control plane for Hermes Agent — a full workspace combining AI chat, visual workflows, multi-agent orchestration, coding agent management, and platform channel integration in one self-hosted dashboard. Real-time chat streaming over Socket.IO connects to any OpenAI-compatible backend including Ollama, OpenAI, Anthropic, and custom endpoints with multi-session management, tool call expansion, inline file previews for HTML, PDF, DOCX, images, and source code, plus profile-scoped uploads and workspace attachments. The visual workflow builder provides a Vue Flow canvas for constructing DAG-structured pipelines with directed edges, conditional routes, approval gates, loops, and live execution with per-node status updates. Platform channel integration configures Telegram, Discord, Slack, WhatsApp, Matrix, Feishu, DingTalk, QQBot, WeChat, and WeCom bots from one page with credential management and per-platform behavior settings. Multi-agent group chat rooms enable real-time messaging with @mention routing, automatic context compression, and SQLite message persistence. The coding agent panel installs, launches, and monitors Claude Code and Codex with built-in terminal, session history, and file diffs. Usage analytics track token consumption, estimated costs, cache hit rates, and 30-day daily trends with model distribution charts. Kanban boards plan and track agent work alongside cron job scheduling for recurring tasks. Deploy via Docker, npm CLI, or desktop installer for Windows, macOS, and Linux. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Odysseus
Agents with tool use, deep research, a document editor, an IMAP/SMTP email client with AI triage, notes, tasks, and a CalDAV-synced calendar - Odysseus bundles all of it into one open-source, self-hosted AI workspace. It runs local models through Ollama, vLLM, or llama.cpp and cloud APIs like OpenAI and OpenRouter, with a hardware-aware Cookbook that scans your machine and recommends quantized models that fit. Persistent memory uses ChromaDB with hybrid vector-plus-keyword retrieval, web search runs through a bundled SearXNG instance, and agents can use MCP servers, files, and shell access with safety controls, plus custom skills and scheduled agent tasks. A blind Compare mode runs side-by-side model duels with identities hidden and accumulates Elo-style ratings from your votes, so model selection is based on your actual workloads rather than leaderboard claims. Deep research mode - adapted from the Tongyi DeepResearch approach - reads sources through SearXNG and produces cited reports, while the email client tags, summarizes, sets reminders, and drafts replies locally rather than through a third-party mail AI. The writing-first document editor adds AI edits, Markdown and HTML support, and version history. The stack is Python 3.11 with FastAPI, SQLite for state, and a vanilla JS frontend, licensed AGPL-3.0 with zero telemetry. Because agents can read email and execute commands, keep authentication enabled and never expose it as a public unauthenticated service.
SurfSense
Positioned as the open-source NotebookLM alternative for AI agents, SurfSense delivers a live web research platform where your agents access structured data from Reddit, YouTube, Instagram, TikTok, Amazon, Walmart, Google Maps, Google Search, Indeed, and any page on the open web through one REST API or MCP server. Scheduled and event-triggered agents transform findings into briefs, alerts, podcasts, and presentations, while a built-in knowledge base keeps every discovery searchable with Perplexity-style cited answers using hybrid semantic and full-text search powered by PostgreSQL with pgvector. Upload PDFs, Office documents, images, and audio files, or sync Google Drive, OneDrive, and Dropbox — 50+ file formats supported with AI file sorting that auto-organizes documents by source, date, and topic. The MCP server exposes scrapers, knowledge base, and workspaces as native tools for Claude, Cursor, and any MCP-compatible agent. Cross-country proxy rotation handles Reddit, TikTok, and Google Search scraping with geo-aware sticky sessions and captcha-aware anti-bot handling. The platform features collaborative chats, multi-format document export, git-native knowledge base with Open Knowledge Format export, and a desktop quick-ask panel with global shortcut. Docker Compose deployment manages nine services including Caddy proxy, PostgreSQL, Redis, FastAPI backend, Celery workers, zero-cache real-time sync, and Next.js frontend with automatic Watchtower updates. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Open Design
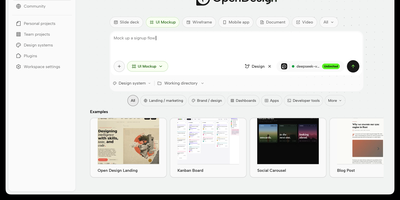
With over 84,000 GitHub stars since its April 2026 launch, Open Design has emerged as the definitive open-source alternative to Anthropic's Claude Design. Rather than shipping its own language model, Open Design acts as an agent-agnostic design orchestration layer that auto-detects 25+ coding CLI executables on your PATH — including Claude Code, Codex, Cursor, Gemini CLI, OpenCode, Qwen, GitHub Copilot CLI, Hermes, and Kimi — or connects to any OpenAI-compatible endpoint via its built-in BYOK proxy at /api/proxy/stream. The platform introduces a file-based protocol where SKILL.md files define composable design workflows and DESIGN.md files establish version-controlled brand systems, currently shipping 31 first-party skills and 72 brand-grade design systems. Output spans web and mobile prototypes, live dashboards, presentation decks, raster images, video, and HyperFrames motion graphics, with export pipelines for HTML, PDF, PPTX, MP4, and ZIP. The daemon architecture uses SQLite for project state and serves a sandboxed iframe preview renderer with vendored React and Babel for JSX artifacts. Deployment options include the native desktop app for macOS, Windows, and Linux, local daemon mode via pnpm tools-dev, a single-container Docker Compose path serving both API and Next.js frontend on port 7456, and Vercel deployment for the web layer. On RepoCloud, deploy Open Design on a dedicated VPS with full root SSH access, persistent storage for your design systems and generated artifacts, and complete control over which AI providers and agent CLIs your instance connects to, all under the Apache-2.0 license.
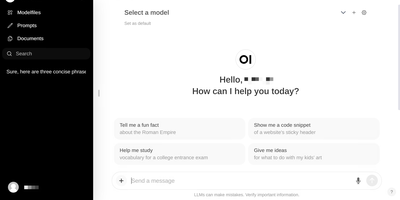
Open WebUI
Large language models get a polished front end that can run fully offline: Open WebUI is the self-hosted front end of choice. It talks to local model runners, primarily Ollama, and to any OpenAI-compatible API, so LM Studio, vLLM, Groq, Mistral, OpenRouter, and cloud providers all plug into the same chat interface and can be mixed per conversation. RAG is built in: upload files to knowledge bases or reference them in chat with the # command, backed by a choice of nine vector databases (ChromaDB and PGVector officially maintained) and multiple extraction engines including Tika and Docling, with hybrid BM25-plus-vector search and cross-encoder reranking. Web search results from providers like SearXNG, Brave, and Tavily inject directly into conversations. Extensibility comes from Python tools and functions that run inside the chat, a Pipelines plugin framework, and native MCP support. Multi-user features include RBAC, SSO, and group permissions, and the instance itself exposes an OpenAI-compatible API your own apps can call.
AnythingLLM
Chat with your own documents: AnythingLLM, from Mintplex Labs, wraps retrieval-augmented generation (RAG) in an open-source application anyone can run. You organize content into workspaces, each an isolated namespace with its own documents, vector embeddings, chat history, and settings, so one instance can hold several separate knowledge bases. Upload PDFs, DOCX, TXT, and other formats, or scrape web pages; the built-in collector parses and chunks them into a vector database (LanceDB by default, with Pinecone, Chroma, Qdrant, and others supported). Answers cite their source documents. It works with both cloud LLMs (OpenAI, Anthropic, Gemini) and local ones via Ollama or LM Studio, and the embedding model is separately configurable. Beyond RAG chat, it includes AI agents that can browse the web and run tools, an embeddable chat widget for your website, a developer API, and multi-user mode with admin, manager, and default roles plus per-workspace access control. Context assembly is smarter than naive RAG: pinned documents, attached files, vector search hits, and recent chat history are combined under a token budget so the model's context window is filled efficiently, and each workspace supports multiple independent conversation threads against the same knowledge base. Because the embedding model, vector store, and chat LLM are all independently swappable, you can move between providers without re-ingesting a single document. The stack is Node.js with a React frontend, MIT-licensed.
DeepSeek Harness
DeepSeek Harness gained over 60,000 GitHub stars within hours of its August 2026 launch, establishing itself as the first fully modular open-source agent runtime where literally every component is a swappable plugin. Built on the Cordis framework—a programming paradigm for spatiotemporal composability—dsh decomposes the entire agent stack into independently replaceable pieces: model adapters for DeepSeek, Anthropic, OpenAI, AWS Bedrock, Azure, and Google Gemini; tool registries covering bash execution, file system operations, web search, subagent delegation, and todo management; plus session stores, sandboxes, approval policies, orchestration loops, and the user interface itself. Four operating modes serve different workflows: Standard provides the full toolset, Code mode uses model-generated code to compose multi-round tool calls, Minimal strips down to a shell and editor for benchmarking, and Creator mode lets developers inspect the running runtime and test Cordis plugins in memory. The kernel handles plugin mounting, unmounting, and dependency resolution while typed events and services coordinate between components. Profiles and bundles allow the same codebase to produce entirely different products—a terminal coding agent, a browser-based workspace, a headless automation service, or an ACP/JSON-RPC endpoint—by swapping YAML configuration layers. Session history is stored as an append-only event stream for full trajectory replay, and project-level hooks on agent lifecycle events enable fine-grained behavioral customization. MCP client integration connects to external tool servers, while Agent Client Protocol enables programmatic orchestration. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Hermes Agent
OpenRouter's most-used application by token volume — over 17 trillion tokens processed — Hermes Agent is an open-source autonomous agent built by Nous Research that lives on your server and gets more capable every day. Define a goal in natural language and Hermes plans sub-tasks, executes them through tool integrations, observes results, handles errors, and refines until the job is done or it genuinely needs your input. Persistent memory with full-text search and LLM summarization lets it recall context across sessions, and an agent-created skills system self-improves after complex tasks. A messaging gateway connects Telegram, Discord, Slack, WhatsApp, Signal, and 16 more platforms with cross-channel conversation continuity. A built-in cron scheduler runs daily reports, nightly backups, and weekly audits unattended. Subagent spawning parallelizes workstreams, and six terminal backends — local, Docker, SSH, Singularity, Modal, and Daytona — fit any infrastructure. Works with any LLM provider: Nous Portal, OpenRouter for 400+ models from 70+ providers, OpenAI, Anthropic, or your own endpoint. The API key you supply powers all LLM calls; billing goes through your own account. Running on a dedicated VPS with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Buzz
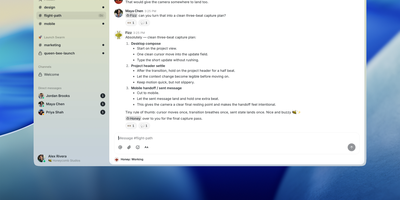
Buzz delivers the first production workspace where humans and AI agents operate as cryptographically equal team members on a self-hosted Nostr relay. The Rust-based backend stores every message, code patch, CI result, review comment, and workflow step as a signed Nostr event in a unified PostgreSQL-backed event log with Redis pub/sub for real-time presence and S3/MinIO for media storage. The integrated Git forge implements NIP-34, turning feature branches into dedicated channels where patches, reviews, and merge decisions live alongside the discussion that produced them — eliminating the split between chat tools and code hosts. Through the open Agent Client Protocol, Buzz natively supports Goose, Anthropic Claude Code, and OpenAI Codex as first-class channel members with scoped permissions, their own audit trails, and the ability to create patches, run workflows, and orchestrate multi-step automations via YAML-defined triggers including message events, reactions, schedules, and webhooks. The Tauri-based desktop client runs on macOS, Windows, and Linux, while buzz-cli provides agent-first JSON I/O for headless automation. Deploy via Docker Compose with the production bundle in deploy/compose/, Railway one-click, or build from source requiring Rust 1.88+, Node 24+, and pnpm. Multi-community mode scopes tenant data by domain with NIP-42 Schnorr authentication, rate limiting, and hash-chain audit logging. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
n8n
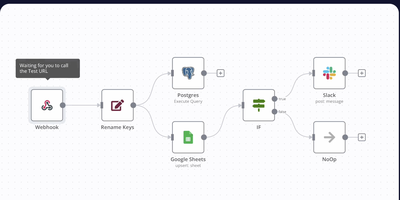
Webhooks, cron schedules, and app events trigger chains of nodes that fetch, transform, and route data: n8n is a workflow automation platform built around a visual, node-based editor. It ships with 400+ built-in integrations covering databases like Postgres, SaaS tools like Slack and HubSpot, and every major AI provider. When a pre-built node does not exist, the HTTP Request node calls any REST API, and the Code node runs JavaScript or Python inline, so you are never blocked by a missing connector. Workflows execute as directed graphs with branching, loops, error handling, and sub-workflows, and every run is logged for inspection and replay during debugging. It also includes LangChain-based nodes for building AI agents with tool calling and memory. Self-hosting on RepoCloud gives you unlimited workflow executions with no per-task pricing, and all data stays on your instance. Runs on Node.js with SQLite by default; add Postgres and Redis queue mode when you need to scale workers horizontally.