Chunky
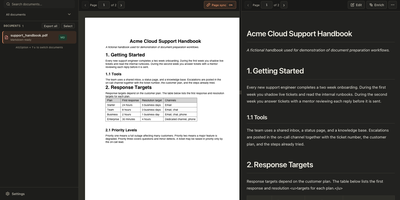
See exactly what your documents look like before a retrieval pipeline swallows them. Chunky puts the original PDF next to the converted Markdown with page-aware scrolling, so broken tables, scrambled columns, and stray artifacts are visible at a glance. Pick a converter, edit the Markdown by hand, then split it into color-coded chunks you can edit, delete, or enrich one at a time. Compare two converters on the same pages in a side-by-side dialog to find which one handles your layouts best. Try token, recursive, sentence, semantic, table, code, and heading-based splitters with adjustable size and overlap, and save the chunk sets that work. Optional model-powered enrichment adds titles, one-sentence context, summaries, keywords, and retrieval questions to each chunk. Process many documents in one batch and export everything as a ZIP. Judge chunk quality by eye, not by guesswork, before any of it reaches an embedding model. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Deploy